# Welcome
Understand Amigo's data foundation, agent workflows, deployment responsibilities, and the evidence used to improve healthcare operations.
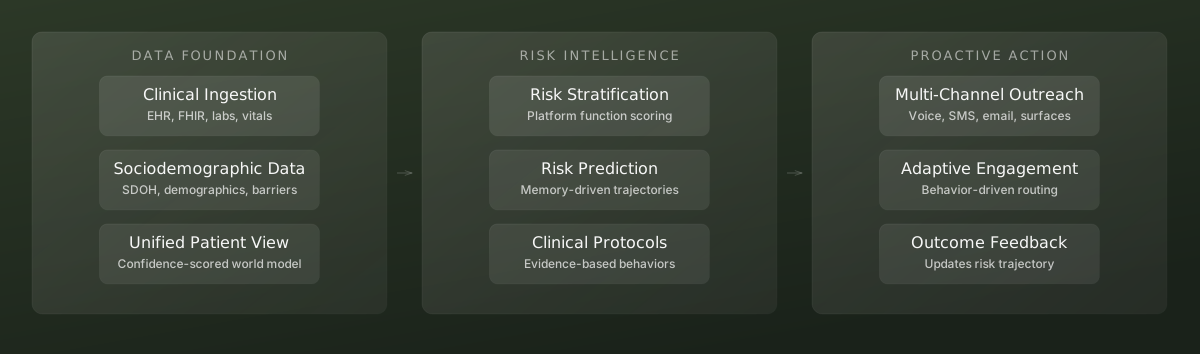
Amigo is a healthcare data and agent platform. It brings supported source data into a shared workspace, runs configured agent workflows, and gives teams tools to supervise interactions and evaluate outcomes.
A useful deployment brings these pieces together. An agent rescheduling an appointment needs the right patient context, current availability, permission to make the change, confirmation from the scheduling system, and a person to handle exceptions. The conversation is one part of the work.
These docs explain the architecture, supported capabilities, and responsibilities involved in a deployment. Start with the evaluation packet for a buying decision or the first conversation guide for an implementation.
## Choose Your Path
| Your goal | Start here | Leave with |
| ---------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| Evaluate Amigo | [Technical Evaluation Packet](/platform-overview/evaluation-packet) | Architecture, availability, effort, and pilot acceptance evidence |
| Build with Amigo | [First Verified Conversation](https://docs.amigo.ai/developer-guide/guides/first-verified-conversation) | A runnable client and verified result, with explicit provisioning prerequisites |
| Operate and improve | [Operating Model](/platform-overview/operating-model), [Testing](/testing/testing), and [Troubleshooting](https://docs.amigo.ai/developer-guide/guides/troubleshooting) | Owners, failure investigation, evaluation, and recovery steps |
| Find an exact contract | [API Reference](https://docs.amigo.ai/api-reference) | Generated operation and model definitions |
| Plan a change | [Upgrade guidance](https://docs.amigo.ai/api-reference/change-logs/upgrade-guide) | Current integration boundaries and relevant historical changes |
## Understand the System
Read these pages in order for a technical introduction:
1. [What Amigo Does](/platform-overview/what-amigo-does) - the product, the problem it addresses, and where it fits in an existing organization.
2. [Core Concepts](/platform-overview/core-concepts) - how workspaces, world-model data, services, agents, Context Graphs, and runs relate.
3. [How It Works](/platform-overview/how-it-works) - follow an appointment change from source data to a confirmed outcome and later evaluation.
4. [Design Principles](/platform-overview/design-principles) - the engineering choices and trade-offs behind that architecture.
5. [Operating Model](/platform-overview/operating-model) - who defines the workflow, operates it, and decides what changes.
## Follow Your Question
| Your question | Continue here |
| ----------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| How does Amigo represent conflicting or incomplete records? | [World Model](/data/world-model), then [Connectors and EHR](/data/connectors-and-ehr) |
| How is an agent configured and constrained? | [Agent Core](/agent/agents), [Context Graphs](/agent/context-graphs), and [Runtime Safety](/operations-and-safety/runtime-safety) |
| How does a workflow reach a patient or operator? | [Channels](/channels/conversations) and [Operators and Escalation](/operations-and-safety/operators) |
| How do we establish that it works and release a change? | [Testing and Evaluation](/testing/testing), [Deployment Model](/platform-overview/deployment-model), and [Continuous Improvement](/agent/pattern-discovery-and-reuse) |
| Where does data go, and what can we inspect? | [Data Residency](/platform-overview/data-residency), [Compliance and Audit](/operations-and-safety/compliance), and [Intelligence and Analytics](/intelligence-and-analytics/intelligence) |
| What evidence supports a deployment decision? | [Evaluating Amigo](/platform-overview/evaluating-amigo) |
The [healthcare use cases](/use-cases/use-cases) apply these concepts to specific workflows. They are design patterns; provisioning, integrations, and operating decisions determine the deployed behavior.
## Concepts, Implementation, and Reference
This space explains behavior, architecture, and operating boundaries. The [Developer Guide](https://docs.amigo.ai/developer-guide) provides authentication, endpoint contracts, SDK guidance, and integration examples. Start its [Getting Started path](https://docs.amigo.ai/developer-guide/getting-started) when you are ready to implement. The [API Reference and Change Logs](https://docs.amigo.ai/api-reference) provide generated operation schemas and historical changes. The [Glossary](/reference/glossary) is a lookup reference; [Core Concepts](/platform-overview/core-concepts) explains the relationships behind the names.
Unless a page says otherwise, these concepts describe the Platform API. The Classic API remains supported for existing integrations and has its own resources and contracts. Use the API named in the implementation guide for your deployment.
## Read Capability Claims in Context
A documented interface can require provisioning, configuration, or a particular runtime. The [capability matrix](/platform-overview/capability-availability) distinguishes those requirements from private previews, demonstrations, proposed designs, and retired workflows. Confirm the capabilities needed for your deployment before committing to scope or timing.
When evaluating a deployment, trace the claim to its prerequisites and observable result. A recorded request, a completed agent turn, a delivered message, and a confirmed external change are different pieces of evidence.
# What Amigo Does
How Amigo combines a shared healthcare data foundation, configured agent workflows, and operational evidence within an existing organization.
Amigo connects healthcare data, agent workflows, and human operations. Teams use the platform to give agents relevant context, define the work they may perform, connect external actions, and inspect the results.
Evaluate a deployment by the work it completes: an appointment changed and confirmed, information collected and available to the responsible team, or an exception resolved by an operator. Conversation quality is one part of that assessment.
## The Problem the Platform Addresses
Consider a patient trying to move an appointment. Their identity may be stored in one system, availability in another, and the reason for the change only in the conversation. A new time can become unavailable between lookup and booking. A request can be recorded successfully even when the scheduling system never accepts it.
The workflow depends on accurate identity, current information, permission to act, and confirmation from the scheduling system. Those dependencies remain even when the conversation itself works well.
Amigo provides configuration, data access, execution, and operational tools for connecting those steps. The implementation team defines the required sources, verification rules, permitted actions, and exception handling.
## A Shared Data Foundation
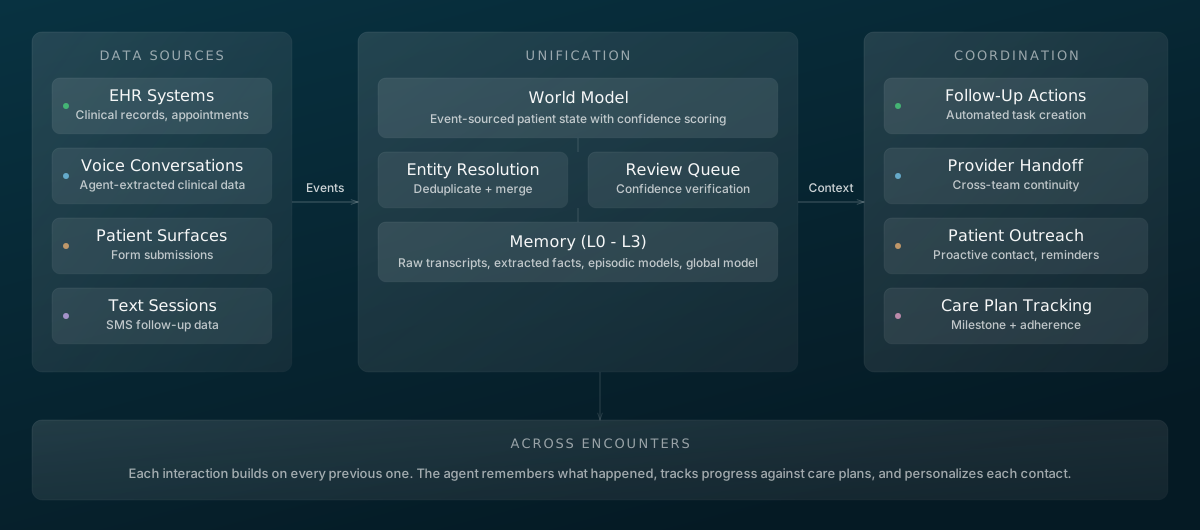
The [world model](/data/world-model) retains supported source observations and derives current views of entities such as patients, practitioners, and appointments. Provenance records where an observation came from. Confidence classes and projection rules help resolve competing observations without treating all inputs as equally authoritative.
Agents, operators, customer applications, and analysts can use this data through their supported interfaces. Each interface has its own permissions, available records, and freshness. Source mappings and business definitions remain part of the integration design.
Source history remains important when records disagree. A patient's report of a new address can be retained even while a stronger source still supplies the projected address. The workflow then determines whether to verify the report or request an external update.
## Configured Agent Workflows
An [agent](/agent/agents) supplies identity and general guidance. A [Context Graph](/agent/context-graphs) organizes the workflow into objectives, states, transitions, and eligible tools. A service brings the selected configuration into an operating context, with channel and runtime settings.
The runtime combines that configuration with the current interaction and selected data. It can retrieve additional facts, call supported tools, respond, or use an authored escalation path. Model-driven decisions remain probabilistic. Permissions and action validation belong in enforced controls as well as in the workflow's instructions.
[Voice, text, messaging, and Surfaces](/channels/conversations) deliver different parts of a workflow. Their capabilities, identity rules, and delivery semantics differ. Reusing agent configuration across channels still requires testing each channel and provisioning the relevant resources.
## Operations and Improvement
A deployment also needs people who can inspect and act on exceptions. [Operators](/operations-and-safety/operators) can monitor and intervene in eligible runs. Supported approval workflows can require a decision on a specific proposed action. External systems report their own delivery or mutation outcomes.
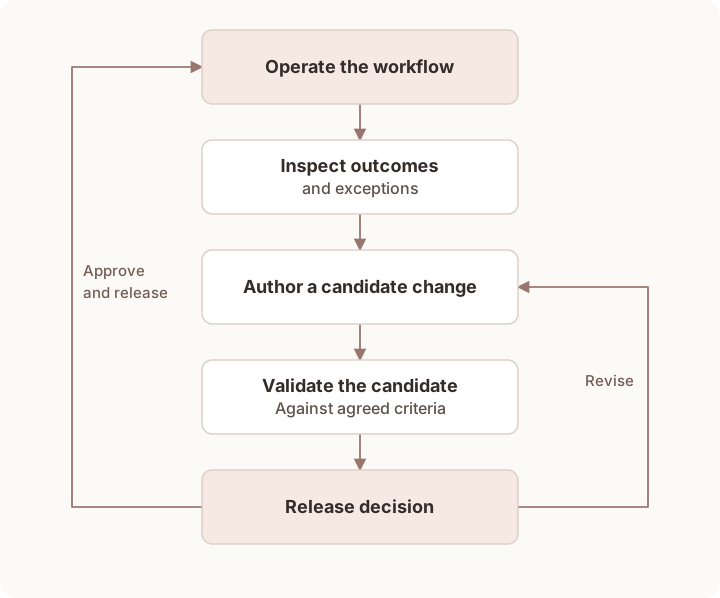
[Testing](/testing/testing), [analytics](/intelligence-and-analytics/intelligence), and [configuration versions](/platform-overview/deployment-model) support a second workflow: improving the deployment. Teams investigate evidence, author a candidate change, validate it, and make an explicit release decision. Production observations do not autonomously rewrite or promote the agent.
## How Amigo Fits into Your Organization
Start with a defined workflow and the systems it needs. Existing systems retain authority over the records and operations they own. Amigo supplies the configured agent, supported data and action interfaces, and operational evidence; the deployment team connects those capabilities to the organization's processes.
The Developer Console supports configuration, testing, and operation. APIs and provisioned data access let customer teams integrate their own applications and reporting. Connector coverage, custom implementation work, and access requirements should be confirmed for each interface.
The [operating model](/platform-overview/operating-model) assigns responsibility for clinical and operational policy, source access, consent, exception handling, and release decisions. The [deployment model](/platform-overview/deployment-model) describes how to move from a baseline to a reviewed release. Hosting, residency, retention, and external data access follow the arrangement agreed for that deployment.
Continue with [Core Concepts](/platform-overview/core-concepts) for the system's vocabulary, then [How It Works](/platform-overview/how-it-works) for the complete interaction lifecycle.
# Core Concepts
The relationships between workspace data, deployed configuration, live interactions, and outcome evidence in the Amigo Platform.
Amigo separates workspace data, workflow configuration, and execution records. Data supplies context, configuration defines the intended work, and execution records show what happened. Each has its own lifecycle.
This page introduces the Platform concepts. The [Glossary](/reference/glossary) provides shorter definitions, and the [Developer Guide](https://docs.amigo.ai/developer-guide) maps them to API resources.
## Workspace: The Shared Boundary
A [workspace](/data/workspaces) scopes data, configuration, and access. A service, a patient entity, and an operator's permissions are evaluated within that boundary. Organizations use separate workspaces when they need separate access, configuration, or operational control.
A workspace is not a workflow or a version of an agent. One workspace can contain several services. Creating a workspace also does not provision every channel or establish a particular hosting, retention, or compliance arrangement.
## Data: Records, Events, and Projections
| Concept | What it represents | Example |
| ----------------------------- | ------------------------------------------------------------------------------ | ------------------------------------------------------------- |
| **Data source** | A configured origin of supported records | A scheduling-system connection or a registered intake source |
| **Entity** | A modeled person or resource within the workspace | A patient, practitioner, or appointment |
| **World-model event** | A source-attributed observation or recorded change | A patient reports a new contact preference |
| **Projection** | A derived read view computed from relevant retained inputs | The current projected patient context |
| **Provenance and confidence** | Where an observation came from and how its source is ranked on supported paths | Distinguishing a patient report from a verified source record |
The [world model](/data/world-model) is the shared event and entity layer. A projection gives consumers a usable read without making them reconstruct the entire history. Projection is asynchronous, and some derived products use their own processing paths. An accepted event can exist before a later read reflects it.
Entity identity also needs an explicit basis. A recognized phone number can help resolve a caller binding; it is not, by itself, the workflow's identity verification. See [Connectors and EHR](/data/connectors-and-ehr#entity-resolution) for the current resolution and binding boundaries.
## Configuration: What a Service Deploys
| Concept | Responsibility |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| **Agent** | Identity, general behavioral guidance, and communication style |
| **Context Graph** | Workflow objectives, states, transitions, state guidance, and tool bindings |
| **Tool** | A specific operation the runtime can invoke under its access and execution rules |
| **Skill** | A prompt-driven companion definition that can use its declared tools; its state binding controls execution and result handling |
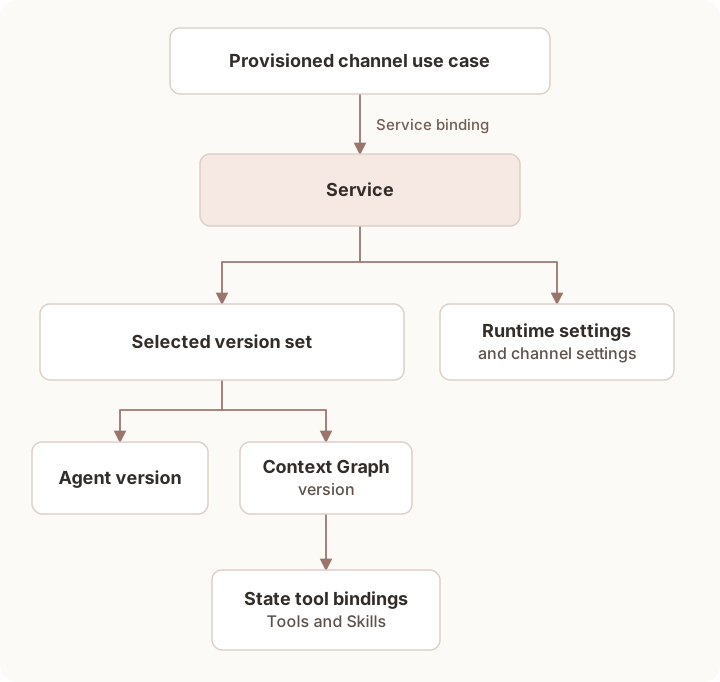
| **Service** | The deployment configuration connecting selected agent and Context Graph versions with runtime and channel settings |
| **Version set** | A named selection of component versions and supported runtime preferences for a service |
| **Channel use case and binding** | Provisioned channel identity and purpose, connected to the service that handles that route |
This is a configuration relationship, not a processing sequence. A deployed interaction combines these pieces. State bindings govern workflow tools, while supported runtime and platform tools can also be exposed through service and channel configuration.
Agent guidance and Context Graph instructions steer model behavior. Server-side authorization and tool validation determine which operations may execute. A tool's presence in a prompt does not grant new permissions.
These definitions separate the agent's perspective from the problem it is solving. The same agent can work through different Context Graphs, and a graph can be evaluated with different agent guidance. The [reasoning engine](/agent/reasoning-engine#what-the-designer-controls) combines them with current context and runtime controls during execution.
Version sets can pin agent and Context Graph versions. An unpinned component can resolve to a newer version when configuration is loaded. Source data, generated memory, integrations, and other settings have their own lifecycles; pinning a graph does not freeze the entire environment. See [Deployment Model](/platform-overview/deployment-model).
## Execution: Conversations, Sessions, and Runs
A **conversation** holds an interaction's history and lifecycle on a supported channel. A **session** is the runtime context processing the interaction. Continuity, termination, and retained configuration depend on the selected path; a new message does not universally create a new session or reload all configuration.
A **run** is the operational record used to inspect supported execution in the unified Runs surface. Run inventory and detail connect the operator or developer to the underlying interaction. They do not imply that every kind of listed historical run can still be started.
The [reasoning engine](/agent/reasoning-engine) consumes the available interaction signals and produces effects such as a reply, a tool invocation, or a transition. Channel-specific runtime behavior turns those effects into speech or messages. A generated reply and a delivered reply are separate outcomes.
Input, reasoning, actions, and delivery can have different lifetimes. A tool result can continue work without another user message, while a new request can arrive during a lookup. Tool bindings and channel controls determine how that overlap is handled; stopping a response does not undo an external action.
## Context: Current Facts and Memory
World-model context supplies selected entity information. [Memory](/agent/memory) derives useful observations and bounded models from earlier interactions, with scoped recall when more detail is needed. Conversation history supplies what has happened in the current thread, subject to that runtime's context handling. Together with state guidance and tool results, these inputs form the agent's working context.
These inputs serve different purposes. A remembered preference can help the agent communicate; a current scheduling lookup is needed when the next action depends on live availability. Generated memory and summaries can be incomplete and do not replace authoritative retrieval.
A Context Graph describes how work proceeds. The world model describes entities, evidence, and relationships. A workflow can consult related records without its states mirroring those relationships. Memory updates the context available for future reasoning; it does not train model weights or automatically rewrite the agent or graph definition.
Proposed extensions to [object memory](/agent/memory#design-direction-object-memory) and [execution coordination](/agent/reasoning-engine#design-direction-universal-reasoning-harness) are documented separately as design direction. Use the current person-memory and channel contracts when scoping a deployment.
## Evidence: What a Result Establishes
The meaning of success depends on the boundary being observed:
* A retained observation shows what was recorded and its source.
* A tool result shows the result exposed by that operation.
* A provider receipt supplies the delivery evidence available for that channel.
* A target acknowledgement or supported read-back can confirm an external change.
* An evaluation scores the evidence available under its definition.
Use those records together to investigate an outcome. A completed run or a favorable evaluation does not establish every downstream result. [How It Works](/platform-overview/how-it-works) follows these boundaries through one workflow.
# How It Works
Follow one appointment change through data retrieval, agent decisions, external action, human exceptions, and outcome evaluation.
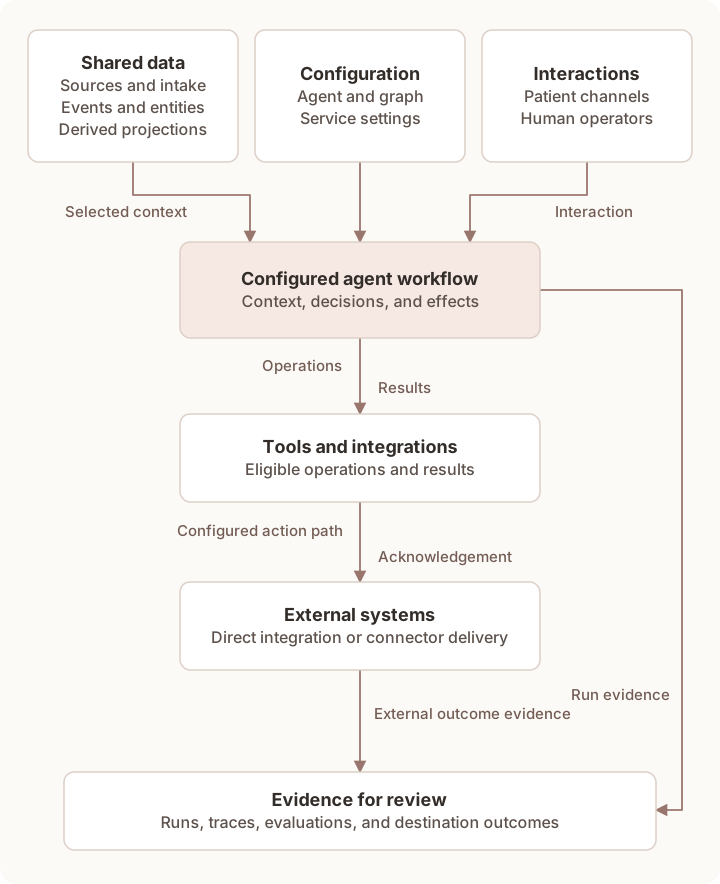
A deployed workflow connects data, decisions, actions, and evidence. This page follows a patient rescheduling an appointment to show where each part of Amigo participates. The example assumes a configured scheduling integration and an approved workflow; it is not a default flow enabled in every workspace.
Read [Core Concepts](/platform-overview/core-concepts) first if services, Context Graphs, or projections are new to you.
## System Architecture
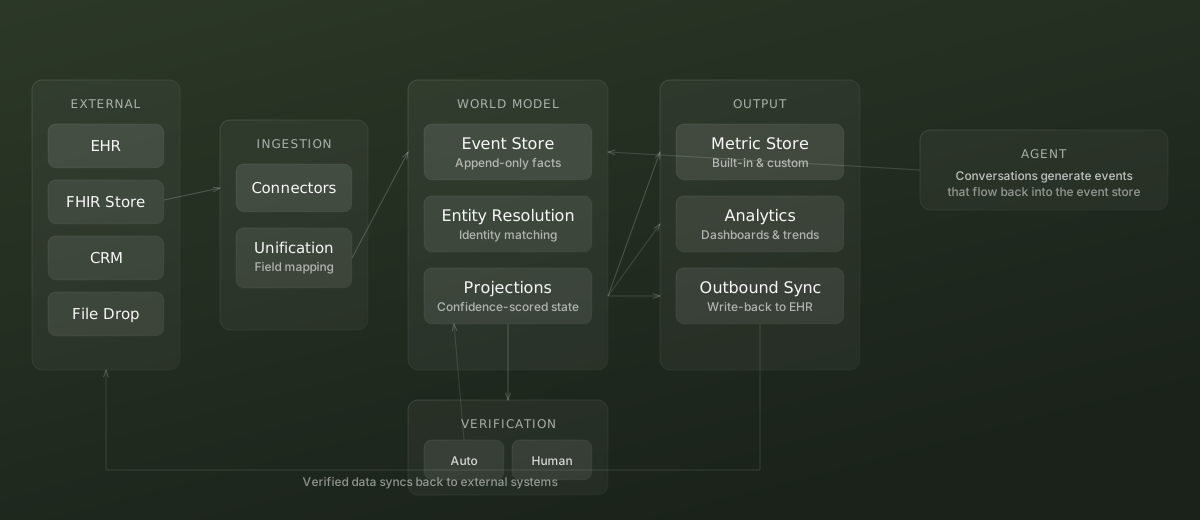
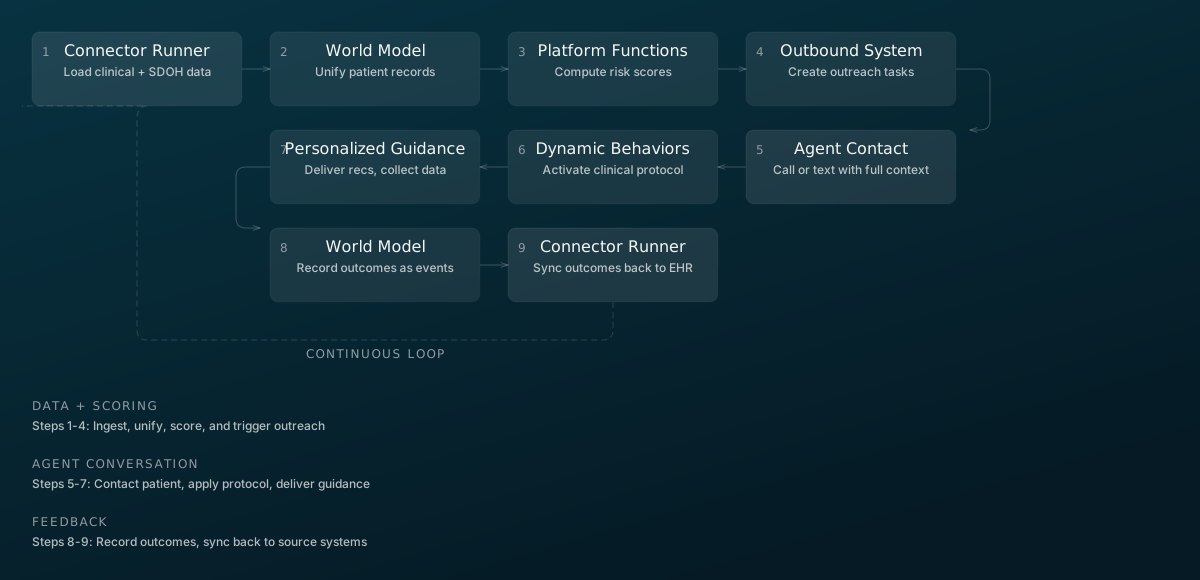
The diagram shows logical responsibilities. The [reference deployment](/platform-overview/reference-deployment) maps the application, Amigo workspace, and external-system boundaries. Direct integration calls and event-driven connector delivery have separate contracts and confirmation steps.
## Call Lifecycle
The patient calls to move Thursday's appointment to Friday. The same operational goal could arrive through another supported channel, but the channel's identity, consent, continuity, and delivery rules still apply.
### 1. Resolve the Route and Caller Context
The provisioned channel route selects a service. The runtime loads the relevant service, agent, and Context Graph configuration. A supported existing caller binding can resolve the associated workspace entity and provide selected projected context.
Recognition helps locate a record. The authored workflow still determines what verification is required before disclosure or action. If the caller cannot be resolved, the agent needs an approved lookup, clarification, or human fallback.
On the supported voice path, preparation can begin while the call rings. Speech recognition and speech synthesis carry the interaction once connected. See [Audio Pipeline](/channels/voice/audio-pipeline) for timing, interruption, and provider behavior.
### 2. Establish What the Next Action Requires
The active [Context Graph](/agent/context-graphs) state defines the objective and relevant guidance. The runtime combines it with the conversation, selected entity context, and available memory. The model can ask for missing information or invoke an eligible tool.
For this example, a projected appointment record establishes useful background. A supported scheduling lookup checks the availability needed for the proposed change. If the patient describes an appointment that conflicts with the available record, the workflow should resolve that conflict before requesting a mutation.
The graph makes the intended sequence and boundaries reviewable. Model-driven navigation remains probabilistic. Required permissions and action validation must be enforced by the corresponding runtime or tool.
### 3. Request the Change Through the Configured Path
After the patient chooses an available time, the agent invokes the permitted scheduling operation. Two common action paths need different treatment:
| Path | What happens | What the workflow must observe |
| ----------------------------------- | --------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| **Direct integration** | A configured tool calls an external endpoint under its authorization and validation rules | The endpoint's actual result, including an ambiguous or failed response |
| **Event-driven connector delivery** | A supported write records an event; outbound policy evaluates it for a configured destination | Eligibility, any required review, and the connector's separate delivery outcome |
Supported text integration calls can pause for conversation-scoped approval. The private-preview external write queue is a separate connector review workflow. Neither is a universal approval gate covering all tools or channels. See [Runtime Safety](/operations-and-safety/runtime-safety#write-safety).
Recording a request preserves intent. It does not confirm a booking. If delivery is asynchronous, the interaction needs an accurate pending response and a defined follow-up owner.
### 4. Confirm the Outcome or Handle the Exception
When the scheduling operation exposes a confirming acknowledgement or supported read-back, the agent can communicate the result it establishes. If the outcome is ambiguous, the workflow should preserve that uncertainty and route it for reconciliation. Blindly repeating a non-idempotent mutation can create a second change.
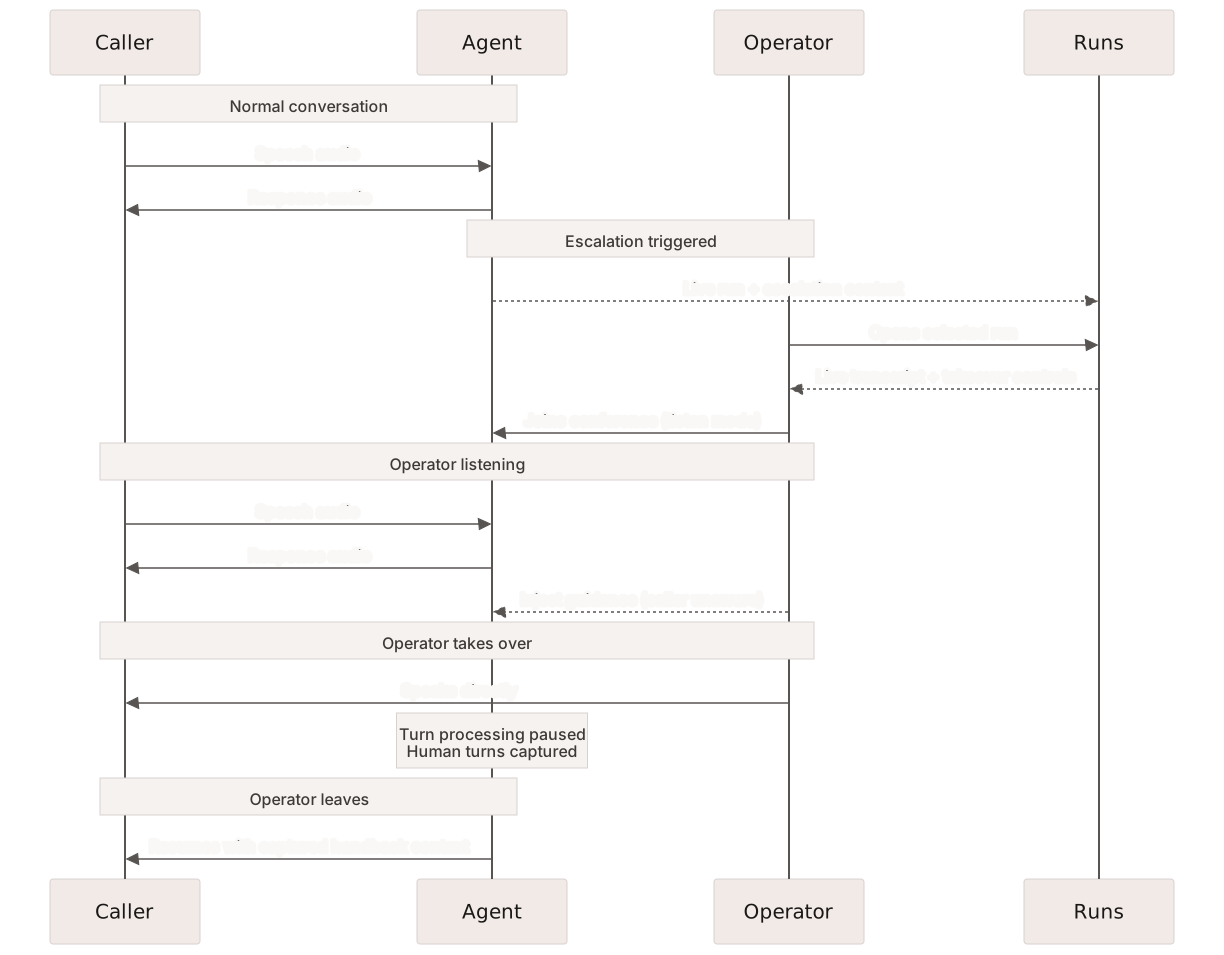
If a person needs to intervene, the [operator workflow](/operations-and-safety/operators) supplies the supported controls for that channel. On eligible voice calls, an operator can join by phone, listen, take over, and hand control back. Transfer to an external destination is a different path with its own answer and failure behavior.
For a messaging follow-up, an accepted send, a final delivery receipt, and a patient response remain different outcomes. The applicable [channel guide](/channels/conversations) defines the available evidence and prerequisites.
### 5. Retain Evidence and Update Read Views
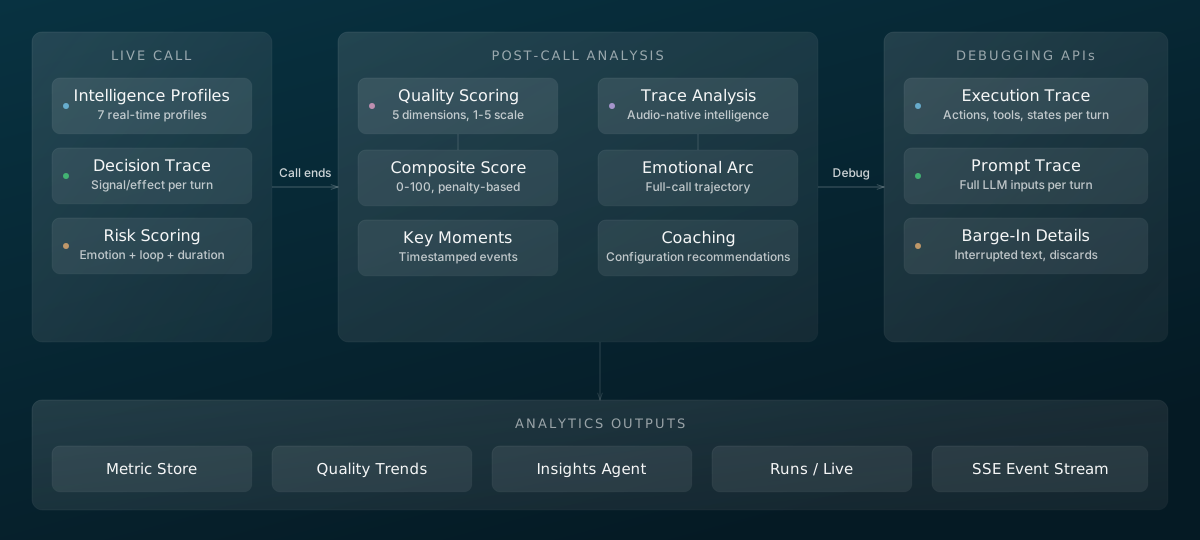
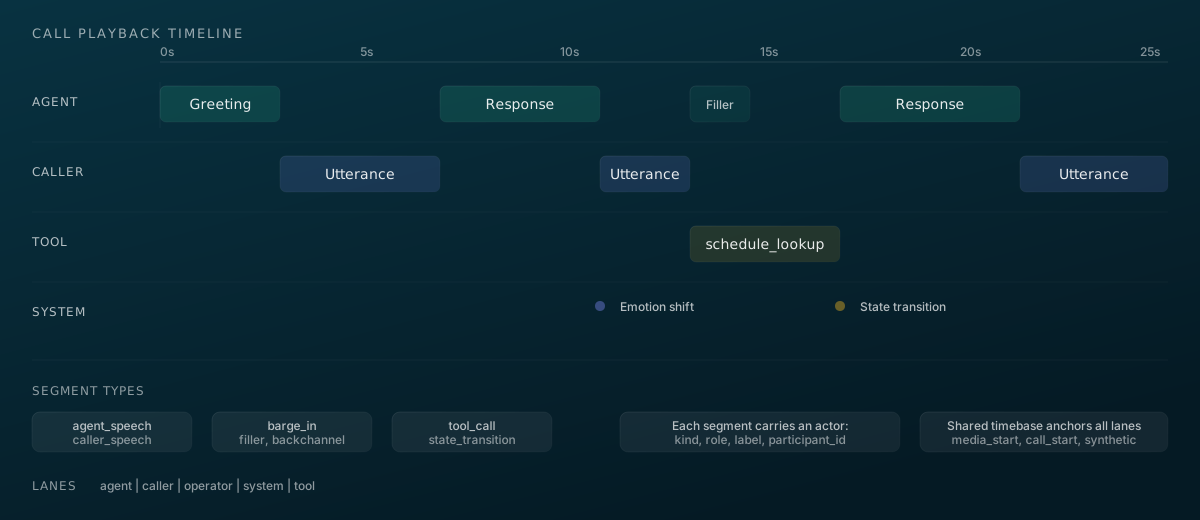
The interaction can produce transcripts, tool activity, run records, source-attributed observations, and post-call artifacts. Each has its own production and retention conditions. Post-call summaries and intelligence are best-effort; the absence of an artifact needs to remain visible during review.
Accepted world-model observations can later appear in projected state. Generated memory may preserve relevant cross-session context through a separate process. A conversation ending does not mean every projection, summary, evaluation, or external write has completed.
## Measure the Whole Workflow
For the rescheduling example, separate these questions:
| Question | Evidence to inspect |
| ----------------------------------------------- | ------------------------------------------------------------------------------------- |
| Did the agent understand the requested change? | Available transcript and evaluated interaction evidence |
| Did it use the intended process? | Selected configuration, observed graph states, and recorded tool activity |
| Did the scheduling system accept the change? | The operation's acknowledgement, supported read-back, or reconciled destination state |
| Did the patient receive the confirmation? | Channel delivery evidence and any subsequent patient response |
| Did unresolved work reach the responsible team? | The applicable handoff or review record and the team's disposition |
The final business outcome may require customer-system data beyond the conversation. Define that join before using a conversation score as a measure of completed work.
## Improve the Next Version
Operational evidence informs a separate engineering process. The team investigates a failure, changes the relevant data mapping, tool, graph, or instruction, and tests the candidate. An authorized release decision selects what runs next.
This [continuous-improvement loop](/agent/pattern-discovery-and-reuse) preserves useful cases and evidence without automatically changing live policy. [Testing and Evaluation](/testing/testing) explains what each test establishes; [Deployment Model](/platform-overview/deployment-model) explains version selection and release.
# Design Principles
The engineering trade-offs behind source-aware data, bounded workflows, explicit action confirmation, and measured improvement.
Amigo's architecture is organized around the conditions a workflow needs to succeed: usable evidence, an allowed action, an observable result, and a way to improve the next attempt. The principles below connect those needs to the platform's design choices and their limits.
## 1. Preserve Evidence and Make Reads Useful
Healthcare records differ in freshness, completeness, and authority. A patient report and an external record can disagree without either becoming disposable. The world model retains supported observations with their source and derives current read views using explicit projection rules.
This separates recording evidence from selecting a value for use. Consumers can use a projection instead of resolving the whole history during each interaction, while retained provenance helps an investigator understand the result.
[Memory](/agent/memory) applies the same principle to understanding that develops across interactions: observe useful information, consolidate a bounded model, and recall detail when the task needs it. Preserve the difference between what a person reported, what a source system recorded, and what a model inferred. Repeatedly summarizing an interpretation does not create independent supporting evidence.
The trade-off is that derived state has a freshness boundary. A write can be accepted before it appears in a projection, and a generated summary can omit detail. Workflows need explicit retrieval when a decision depends on facts that may have changed. See [World Model](/data/world-model).
## 2. Compose Workflows Around Information Requirements
A Context Graph organizes work into objectives, transitions, and eligible operations. It lets an author specify what evidence is needed before moving on without scripting every sentence of the conversation. An agent supplies the broader identity and guidance; the service and runtime supply the operating configuration.
For scheduling, the meaningful transition is having enough verified information to request the permitted change. Counting questions asked is a weak substitute. Existing context can shorten the path, while conflicting information can require another lookup or a person.
Choose the degree of control for each part of the problem. Interpreting a request and explaining options benefit from model judgment. Checking a permission, validating an identifier, or enforcing an enabled approval gate belongs to the operation's control boundary. Declarative definitions make those choices reviewable; the [Reasoning Engine](/agent/reasoning-engine#what-the-designer-controls) explains how they fit together.
Composition makes parts reusable and changes reviewable. It also means behavior depends on several parts at once. Reusing a graph on another channel or with different tools requires validation in that setting. Model-driven navigation remains probabilistic, even when the authored graph is explicit. See [Core Concepts](/platform-overview/core-concepts) and [Context Graphs](/agent/context-graphs).
## 3. Put Controls at the Boundary They Govern
An instruction describes intended behavior. Authorization determines who can perform an operation. Validation checks whether an operation is permitted with the supplied input. An observer records evidence. A human decision supplies the judgment assigned to that person.
Those controls can work together, but they establish different things. A prompt cannot grant an integration permission, and an observed guardrail verdict does not necessarily block a response. The [Runtime Safety](/operations-and-safety/runtime-safety) control map identifies the current enforcement and observation boundaries.
External actions also need their own confirmation. Recording a requested appointment change establishes intent; the scheduling system's acknowledgement establishes the outcome its contract supports. Keeping these distinct makes failed and ambiguous work visible for reconciliation.
The cost is additional integration and operating work: define the result, handle ambiguity, and staff the fallback. That work is part of making a deployment reliable, not something a more confident agent response can replace.
## 4. Improve Through Comparable Evidence and Deliberate Releases
An interaction can reveal a missing source, an ineffective tool, an unclear workflow, or a behavior that needs changing. Retained runs, tests, and analytical evidence make those findings available to the team responsible for the next version.
This separates two loops. Execution uses the current definitions and available knowledge to handle today's work. Improvement evaluates that evidence and proposes better definitions or reusable views for later work. Selecting behavior in the background during one interaction belongs to execution; it is not by itself evidence of learning across interactions. See the [memory design direction](/agent/memory#execution-and-longer-term-improvement).
Separate the question from the configuration being tested. Define the outcome and baseline, identify the required evidence, then compare a candidate on representative cases. Keep missing artifacts and changed populations visible; a better average score can conceal a regression in a consequential segment.
Simulation reduces the cost of exercising behavior before deployment. It does not reproduce every channel or external side effect, so audio, integration, and operational tests supply additional evidence. The team decides whether that evidence is sufficient to release.
The resulting improvement is an engineering process. A metric trend does not automatically rewrite a graph or promote a version. Preserve useful cases and reviewed configuration so later work builds on what was learned. See [Testing and Evaluation](/testing/testing), [Continuous Improvement](/agent/pattern-discovery-and-reuse), and [Deployment Model](/platform-overview/deployment-model).
## Apply the Principles to a Deployment
Use [How It Works](/platform-overview/how-it-works) to trace the boundaries through a concrete interaction. Use [Operating Model](/platform-overview/operating-model) to assign the decisions behind them, and [Evaluating Amigo](/platform-overview/evaluating-amigo) to identify the evidence a technical review should examine.
# Operating Model
How clinical, operational, data, engineering, and Amigo teams divide responsibility for a deployed workflow and its ongoing improvement.
A healthcare agent deployment spans several owners. The team defining the workflow may not control the source records, scheduling system, communication channel, or people handling exceptions. The operating model connects those responsibilities so a successful agent turn can become completed work.
Start with one bounded workflow and name the people who can make its decisions. The responsibilities below are a planning model; the actual implementation and support commitments belong in the deployment agreement.
## Define the Outcome Before the Agent
For an appointment-change workflow, specify the starting condition, eligible population, permitted changes, required verification, and evidence of completion. Decide what happens when the patient cannot be identified, the external system is unavailable, or the result is ambiguous.
The workflow owner defines success in operational terms. Clinical leaders define clinically consequential boundaries and the evaluation criteria for those boundaries. Engineers translate those decisions into data access, tools, authored configuration, and tests.
An outcome definition can be written before every integration is available. It gives the implementation team a concrete target and exposes which missing data or authority prevents the workflow from reaching it.
## Assign Decision Rights
| Area | Organization's decision | Platform and implementation work |
| ----------------------------------- | ---------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- |
| **Workflow scope** | Which work is eligible, what completion means, and what stays with a person | Map that scope into agent guidance, Context Graph states, tools, and handoffs |
| **Clinical and operational policy** | Verification requirements, permitted actions, escalation boundaries, and review criteria | Make the policy inspectable in configuration; implement the applicable enforced controls and tests |
| **Data and integration** | Authorized sources, usable identifiers, freshness needs, and external-system permissions | Configure supported ingestion, mappings, retrieval, write-back, and reconciliation |
| **Messaging** | Sending brand, recipient consent evidence, message purpose, and follow-up ownership | Amigo-managed provisioning and registration where required; configured routing and delivery handling |
| **Live operations** | Staffing, operating hours, who receives exceptions, and how unresolved work is closed | Configure and exercise supported monitoring, operator controls, and transfer paths |
| **Measurement** | Baseline, outcome definitions, relevant segments, and acceptable trade-offs | Configure available evaluations and reporting; connect external outcome evidence where needed |
| **Release** | Who can accept the evidence and authorize a change | Prepare reviewed configuration, targeted validation, rollout, and recovery procedures |
| **Data governance** | Access, residency, retention, and the intended recipients of shared data | Provision the agreed controls and verify actual access and evidence coverage |
The same person can own several areas in a small deployment. Name an accountable owner for each outcome and the teams that contribute to it. Record who can approve scope changes, stop a workflow, and accept unresolved risk. A platform permission grants an operation; the organization's policy determines when its use is appropriate.
## Separate Live Work from Improvement Work
**Live operations** handles the patient interaction and its immediate exceptions. Operators need enough context to act, a supported way to intervene, and a destination for work that cannot finish during the interaction. An escalation instruction is useful only if the relevant person or fallback is reachable.
**Improvement work** changes the system that handles future interactions. The team reviews patterns, forms a hypothesis, authors a candidate, and validates it before release. It can improve a source mapping, a tool, a workflow, or a measure as well as an agent instruction.
The arrows describe team work. Analytics, simulations, and version sets supply supporting capabilities; they do not autonomously approve, promote, or roll back a change.
## Plan the Handoffs That Usually Cross Teams
### Source Data to Workflow
Agree on the identifiers and source records required for an eligible case. Inspect representative joins before launching the interaction: can the intended person, appointment, practitioner, and location be found? Record the expected freshness and the fallback for missing or conflicting data.
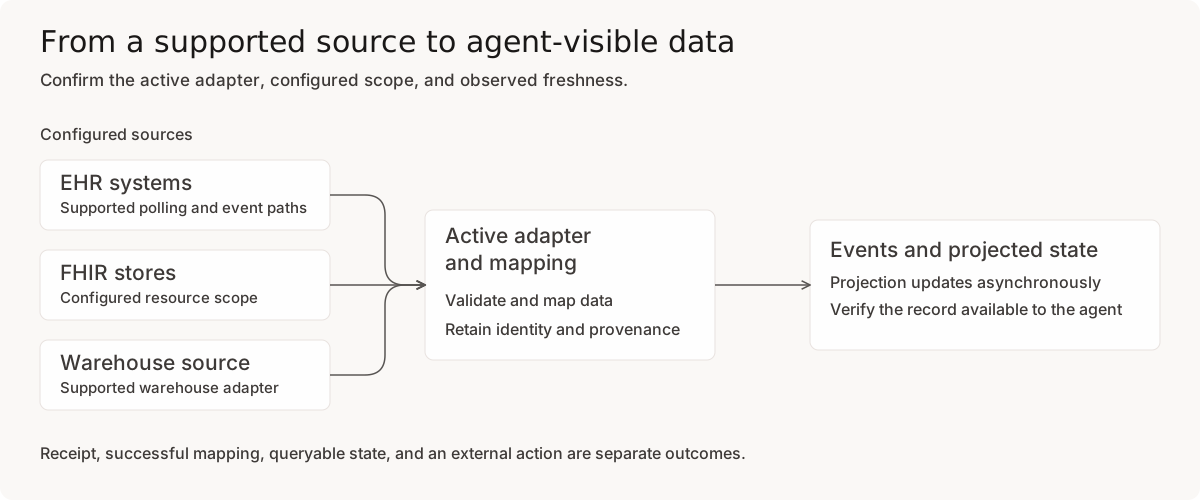
A successful connector sync establishes only what that connector's result reports. It is not proof that every relationship needed by the workflow is available to the agent. See [Connectors and EHR](/data/connectors-and-ehr).
Keep source availability, mapping quality, and consumer readiness distinct in the operating agreement. Assign the team that can investigate each failure and one owner who coordinates resolution across the complete workflow.
### Agent to Operator
Define the reason for handoff, the context the operator needs, and what happens if no operator answers. Test the applicable listen, takeover, handback, or external-transfer path. Those controls have different behavior and availability across channels. See [Operators and Escalation](/operations-and-safety/operators).
### Platform to External System
Agree on what confirms an external action and who reconciles an ambiguous result. Preserve the identifiers needed to find the original request and destination record. Repeating a non-idempotent action is a business decision as well as an integration concern.
Define support hours, severity criteria, notification and escalation routes, and recovery expectations in the deployment agreement. Exercise the handoff with a representative failure before launch so the responsible teams can find the evidence and act on it.
### Evidence to Release Decision
Give the reviewer the candidate configuration, the relevant tests, known gaps, and the intended outcome comparison. Include associated integration or service-setting changes that are outside the pinned agent and Context Graph versions. [Deployment Model](/platform-overview/deployment-model) explains how those selections take effect.
## Establish a Review Rhythm
Use a review cadence appropriate to the workflow's volume and consequences. Start with unresolved work, failed or ambiguous external actions, missing evidence, and representative patient interactions. Compare outcome measures using the same definitions and relevant segments.
Assign each investigation to the team that can change the relevant part of the system. A drop in completion could begin in source data, delivery, staffing, a tool, or agent behavior. Preserve confirmed failure cases in the test set so the next change can be evaluated against them.
For the evidence to request during a technical review, continue with [Evaluating Amigo](/platform-overview/evaluating-amigo). For the recurring engineering workflow, see [Continuous Improvement](/agent/pattern-discovery-and-reuse).
# Deployment Model
Define deployment scope, validate a candidate, select reviewed configuration, and manage release changes across isolated workspaces.
A release selects the configuration that subsequent interactions will resolve. Teams establish a baseline, test a candidate, approve it, and inspect the resulting production evidence. These are deliberate team decisions supported by platform capabilities.
The [Operating Model](/platform-overview/operating-model) assigns responsibility for those decisions. This page covers the release process, version selection, and workspace separation. [Core Concepts](/platform-overview/core-concepts) introduces the configuration relationships.
## Define the Deployment Boundary
Start with a specific operational outcome and the systems needed to achieve it. For appointment outreach, that includes the source of eligibility, current scheduling data, recipient consent, a provisioned channel, confirmed write-back, and a staffed exception path.
Agree on the responsibilities before authoring the agent:
* **Data access** - Which records are available, how fresh they must be, and which system remains authoritative for each external action.
* **Workflow ownership** - Who authors clinical and operational policy, handles exceptions, and approves changes.
* **Channel operations** - Who supplies consent evidence and approved content, and which provisioning Amigo manages.
* **Measurement** - How the team distinguishes an attempted action from a confirmed outcome and compares results with the baseline.
* **Integration** - Which supported APIs, connectors, and data-access paths connect the deployment to existing applications and reporting.
The Developer Console is one interface to these capabilities. Customer applications can use supported APIs and provisioned data access for their own workflows and reporting. A hosted workspace, a customer-owned source system, and a separately agreed deployment arrangement have different data boundaries; confirm the actual arrangement rather than assuming that integration alone moves all processing into the customer's infrastructure.
## Phased Rollout
### Phase 1: Match
Establish the baseline for a defined workflow. Select the eligible cases, escalation paths, evidence, and outcome measures, then compare agent-assisted and existing operations on the same basis.
During this phase:
* Context Graphs encode the approved workflow and operating boundaries.
* Metrics compare eligible agent evidence with the chosen baseline, using the same definitions and filters.
* Operators cover the authored escalation paths and unavailable-agent fallback.
* Retained runs, traces, evaluations, and review evidence inform the next phase when those artifacts are available.
### Phase 2: Discover
With a baseline established, teams analyze observed evidence to form hypotheses about which changes may improve outcomes. Correlation in metrics or traces is not proof that a configuration variable caused the result.
Questions to investigate include:
* Where cases fail or require manual follow-up
* Which missing information delays completion
* Whether escalation reaches the right team with enough context
* Which candidate changes improve outcomes on comparable cases
### Phase 3: Prove
Candidate changes should be exercised through representative simulations, targeted integration tests, and isolated operational validation before production. Teams define the required case count, comparison method, risk checks, and release criteria for the use case.
The prove phase uses:
* Candidate and control version sets with explicit configuration snapshots.
* Simulation suites that exercise common paths, edge cases, and regressions.
* Metric comparisons that preserve filters, sample sizes, missing evidence, and uncertainty.
* Human review for safety-sensitive or clinically consequential behavior.
Simulation evidence supports a release decision; it does not certify safety or reproduce production deterministically.
### Phase 4: Scale
After an authorized reviewer approves a candidate, teams can copy its version-set configuration to `release`. Continue monitoring production evidence and keep a tested rollback configuration; promotion does not prove that future behavior will remain unchanged.
## What a Reviewable Release Includes
Keep the following evidence with the release decision:
* The workflow and intended outcome, including the change from the baseline.
* The selected agent and Context Graph versions, service settings, and related tool or integration changes.
* Relevant simulation, audio, and integration results, with missing evidence and known limitations visible.
* The approving owner, rollout scope, observation plan, and recovery procedure.
A version set captures part of this record. It does not freeze source data, generated memory, every integration setting, or the external systems the workflow depends on. Restoring a previous configuration also does not undo an external mutation that already succeeded.
## Version Sets
Version sets are named service configurations that select agent and Context Graph versions, model preferences, and a supported non-voice turn runtime. They provide reviewable snapshots for testing and release management.
Every Platform service must contain a `release` version set. When service creation omits version sets, the API creates an unpinned `release` set. Other names such as `personal-dev`, `test`, or `preview` are customer conventions, not additional automatic environments.
### Promotion Flow
A recommended path from development to production:
1. **Personal candidate** - Create a named version set, pin the intended agent and Context Graph versions, and inspect the resolved configuration.
2. **Targeted test** - Run the suites and integration checks relevant to the change.
3. **Shared candidate** - Optionally copy the configuration to a team-named set such as `preview` for broader review.
4. **Release** - After approval, copy the reviewed candidate configuration to `release` and verify the stored result.
A version set can pin exact agent and Context Graph versions and carry model preferences. A pinned component changes only when its stored version number changes. An unpinned component resolves to the latest available version when configuration is loaded, so publishing a new version can affect later sessions without a separate pin update. Pin `release` when production behavior should change only through a reviewed configuration update.
## Applying Version-Set Changes
The Platform API upserts individual named version sets on a service. Agent Forge can compare sets, copy a source set to a target, and back up the previous `release` configuration during its promote workflow unless that backup is explicitly disabled.
Treat a version-set update as a change to subsequent configuration resolution, not as an in-place migration of every active interaction. A live session or durable conversation actor can retain configuration loaded earlier. Validate the new `release` value, monitor new runs, and keep a rollback path rather than assuming every next message immediately uses the update.
Use retained configuration versions, Forge diffs, simulation evidence, and applicable audit records together when reviewing a release. No single artifact proves that the candidate produced the intended runtime outcome.
## Multi-Workspace Tenancy
Workspaces are the isolation boundary for data, configuration, and access control. When you need separation between regions, cohorts, or business lines, you create separate workspaces.
Common reasons to use multiple workspaces
* **Data residency**: Use separately provisioned regional deployments and verify their full data flows
* **Cohort isolation**: Separate patient populations (e.g., different clinical programs)
* **Blast radius**: Limit the impact of configuration changes to a single workspace
* **Governance**: Independent roles, audit trails, and promotion controls per workspace
A typical setup for a multi-region deployment:
| Workspace | Region | Purpose |
| ---------------------------- | ---------- | ------------------------------- |
| `acme-cardio-useast` | US East | Cardiology program, US patients |
| `acme-cardio-eucentral` | EU Central | Cardiology program, EU patients |
| `acme-cardio-useast-staging` | US East | Staging environment for US |
Each workspace has its own services, tools, version sets, and access controls. Changes roll out per workspace, so you can deploy to staging, validate, and promote to production without affecting other workspaces.
## Service Channel and Environment
A service's primary channel behavior, supported runtime environment, and organizational tags have different purposes. Treat them as part of the reviewed configuration. Tags help teams organize resources; they do not establish tool permissions, model availability, or a release gate.
Workspace separation and service configuration also serve different purposes. Use the [Workspaces](/data/workspaces) guide for isolation and the [Services Developer Guide](https://docs.amigo.ai/developer-guide/platform-api/workspaces/services) for the current configuration contract.
# Evaluating Amigo
A technical evaluation path through architecture, data, control, delivery, measurement, and deployment, with concrete evidence to examine.
Evaluate Amigo against a defined operational outcome and the requirements your organization must meet to deploy it. Agree on the workflow, baseline, required capabilities, and acceptance criteria before the demonstration. Identify any requirement that would prevent adoption, such as an unavailable integration, insufficient access controls, or an unmet operating commitment.
Follow representative cases from source data through execution to the external outcome. Include incomplete work, failures, and human intervention. Record whether each result came from a fixture, a provisioned test deployment, or production; those settings establish different evidence.
Use the [Technical Evaluation Packet](/platform-overview/evaluation-packet) for a worked evidence example and downloadable worksheets. Its [reference deployment](/platform-overview/reference-deployment) and [capability matrix](/platform-overview/capability-availability) make architecture and provisioning decisions explicit.
## 1. Establish the System Model
Start with [What Amigo Does](/platform-overview/what-amigo-does), [Core Concepts](/platform-overview/core-concepts), and [How It Works](/platform-overview/how-it-works). Be able to locate four things: the retained source evidence, the current read view, the selected workflow configuration, and the outcome record.
**Evidence to examine:** a representative architecture and workflow map with the actual systems, interfaces, and responsible teams identified. Distinguish logical components from where they are hosted. Confirm the deployment's [data residency](/platform-overview/data-residency) and access paths separately.
## 2. Test the Data the Workflow Depends On
Use the [World Model](/data/world-model) and [Connectors and EHR](/data/connectors-and-ehr) to inspect how supported inputs become usable context. Trace one observation from its source into the selected entity view. Check what happens when the source is late, an identifier is missing, or two sources disagree.
**Evidence to examine:** source attribution, effective time where exposed, the relevant projection or mapping rule, and the context actually available to the workflow. A source record and a resolved caller binding are separate steps. Generated memory should also be distinguishable from current source facts.
Confirm that the records needed for the next action can be joined correctly and are current enough for that decision. Identify who owns mapping changes, data-quality exceptions, and source outages.
### Evaluate Memory on Tasks That Need Continuity
Use the [Memory](/agent/memory) workflow to test a remembered preference, a later correction, and a detail omitted from the loaded model. Compare the same task with no historical memory, authorized source retrieval alone, the compact model alone, and the model plus recall. Use a fixture where the supporting evidence is known so retrieval failure can be distinguished from reasoning failure.
Inspect which subject and workspace were searched, whether the answer preserves the source's meaning and time, and how the workflow handles no matches or unavailable recall. Measure the time from new evidence to usable later-session context separately from the latency of a recall request. Better continuity should be visible in the completed task, not inferred from the amount of stored history.
Include evidence attributed to the wrong person, repeated imports of one source, an older detail outside the recall window, and a correction that arrives during reasoning. Score evidence coverage, supported claims, correction handling, and task outcomes separately. A retrieved record must support the answer the agent gives.
## 3. Inspect Intent and Enforcement Separately
Read the [Agent Core](/agent/agents), [Context Graphs](/agent/context-graphs), and [Runtime Safety](/operations-and-safety/runtime-safety) together. Identify what is authored guidance, what is enforced in code, what is observed without blocking, and what requires a human decision.
**Evidence to examine:** selected agent and graph versions, state objectives, eligible tools, authorization, validation, and relevant failure cases. Trace a missing prerequisite through the actual operation. A prompt saying “verify before booking” and a booking tool rejecting an unauthorized request establish different controls.
## 4. Follow the Action to Its Destination
Follow a write through the configured direct-integration or connector path. Where approval is enabled, identify the exact workflow being gated. Then inspect what confirms delivery or an external mutation.
**Evidence to examine:** the recorded request, any required decision, the operation's result, and supported target acknowledgement or read-back. Include a timeout or ambiguous-response case and identify who reconciles it. [How It Works](/platform-overview/how-it-works#measure-the-whole-workflow) gives a running example; [Review Queue](/data/review-queue) explains the separately enabled connector review path.
## 5. Exercise the Real Channel and Human Fallback
Choose the [channel](/channels/conversations) the deployment will use. A text simulation does not exercise speech recognition, live audio interruption, carrier delivery, or operator phone joining. Messaging also requires the applicable identity, consent, and provisioning work.
**Evidence to examine:** a representative interaction on the intended channel, delivery status where available, the supported [operator handoff](/operations-and-safety/operators), and the fallback when a person or destination is unavailable. Include an interrupted or incomplete interaction as well as a successful one.
Test overlapping work explicitly: change the requested appointment date while a lookup is running, let results complete in a different order, and exercise the supported cancellation or takeover path. Inspect both what the tool completed and what the person received. Measure first meaningful output separately from filler, and reconcile uncertain external actions before retrying. [Reasoning Engine](/agent/reasoning-engine#concurrency) explains the relevant execution boundaries.
## 6. Define What the Evaluation Can Establish
Read [Testing and Evaluation](/testing/testing) alongside [Intelligence and Analytics](/intelligence-and-analytics/intelligence). Separate conversation quality, workflow correctness, integration success, and the organization's final outcome. They may require different evidence sources.
**Evidence to examine:** the case set, baseline, scoring definition, required artifacts, missing results, relevant segments, and external outcome data. Ask whether the test used representative data and exercised the channel and integrations that matter. A favorable score supports only the claim its inputs and definition can measure.
Cost and latency comparisons need the same care: use a comparable workflow and account for unresolved work, retries, discarded reasoning, retrieval, and human handling. Separate replay with recorded results from a fresh model run. Agree percentile targets, concurrency and burst assumptions, retrieval budgets, and covered recovery failures before a pilot. See [Cost and Latency Optimization](/platform-overview/cost-and-latency).
## 7. Demonstrate a Reviewed Change
Use [Deployment Model](/platform-overview/deployment-model) to follow a candidate from authoring to validation and release selection. Inspect which components are pinned, which inputs can still change, and when a running interaction loads its configuration.
**Evidence to examine:** a configuration comparison, the affected regression cases, release approval, observations from new runs, and a tested recovery procedure. Restoring a prior agent version does not undo an external action that already occurred.
## 8. Agree on Ownership and Integration Boundaries
The [Operating Model](/platform-overview/operating-model) identifies decisions the organization and implementation team must make. Confirm who handles source failures, patient exceptions, consent changes, external reconciliation, access changes, and release decisions.
**Evidence to examine:** named owners and the interfaces they will use. If a team wants its own application or reporting, review the supported APIs and provisioned data-access path, the datasets available, and their freshness and permissions. If portability matters, identify the actual exportable artifacts and the work required to rebuild integrations and controls elsewhere. Open interfaces do not make an entire deployment automatically portable.
Review security and operating commitments alongside the technical results. Confirm the deployment's access controls, retention and deletion process, assurance evidence, support coverage, incident escalation, recovery expectations, and commercial assumptions. The [evaluation packet](/platform-overview/evaluation-packet#complete-the-enterprise-review) identifies the decision record for each area.
## Evaluate Proposed Extensions Separately
If the evaluation includes [object memory](/agent/memory#design-direction-object-memory) or the [Universal Reasoning Harness](/agent/reasoning-engine#design-direction-universal-reasoning-harness), give that work its own scope, implementation owner, and acceptance criteria. Both are documented as design direction beyond the current paths.
For object memory, test changed identity mappings, incompatible definition revisions, corrections, and revoked access. For the proposed harness, test failed required selections, late advisory guidance, uncertain action submissions, and responsiveness to control requests during long reasoning. Resumed work should use current authority and valid context. Equivalent typed and transcribed inputs, including corrections, should not create duplicate requests.
Record these as requirements for the extension until implementation and deployment evidence establish the behavior. Keep them separate from results obtained on supported production paths.
## Leave with a Deployment Decision
Capture the reviewed workflow, the evidence examined, unresolved dependencies, and the conditions for proceeding. Keep current behavior, deployment-specific configuration, private previews, and proposed work distinct in that record.
The next step should be concrete: resolve a source mapping, test a missing failure path, provision a channel, assign an exception owner, or approve a bounded release. The [Developer Guide](https://docs.amigo.ai/developer-guide) is the next layer when the implementation team needs exact contracts.
# Technical Evaluation Packet
Build a technical decision packet with deployment boundaries, capability confirmations, pilot acceptance criteria, integration effort, and traceable outcome evidence.
Use this packet to record the evidence for a pilot or deployment decision. Engineering, security, operations, and procurement reviewers should be able to identify the proposed scope, verified capabilities, remaining dependencies, and terms of operation from the same record.
Start with [Evaluating Amigo](/platform-overview/evaluating-amigo), the [reference deployment](/platform-overview/reference-deployment), and the [capability matrix](/platform-overview/capability-availability). Complete the worksheets with actual systems, named owners, and observed results. Give unresolved requirements an owner and decision date.
## Assemble the Decision Record
| Artifact | What the reviewer should be able to answer |
| ------------------------------ | ----------------------------------------------------------------------------------------------- |
| Architecture and data-flow map | Which systems process the data, where the boundaries are, and which team owns each interface |
| Capability confirmation | What is enabled in this deployment, what needs provisioning, and what is outside the pilot |
| Integration plan | Which source, identity, action, channel, and operational dependencies remain, with named owners |
| Acceptance plan | Which cases and failure conditions determine whether to proceed |
| Evidence register | What each result proves, where to inspect it, and what remains unknown |
| Decision and operating handoff | Who approved the scope, what conditions remain, and who handles failures after launch |
Download the editable worksheets below. They are planning artifacts, not API payloads or contractual commitments, and do not require GitHub organization access.
{% file src="/files/Q2hVjgcuD2PCB3CJyxTL" %}
Pilot scope, acceptance criteria, evidence, ownership, and decision worksheet.
{% endfile %}
{% file src="/files/sapxI7KHo6p7R2yj8L5Q" %}
Integration dependencies, owners, access lead time, implementation, and validation worksheet.
{% endfile %}
## Define the Pilot Before Running It
Record the workflow, eligible population, intended channel, source and target systems, configuration selection, and excluded actions. Choose a baseline that measures the same work: include unresolved cases, manual handling, and external outcomes. State the observation window and why the cases represent the deployment.
Agree on thresholds before viewing the results. Separate correct workflow execution, target-system success, conversation quality, time, cost, and business outcome. An aggregate score can hide an unacceptable failure in a small but important segment.
### Synthetic Completed Example
The following is a **fictional evaluation record** for a scheduling test system. Identifiers and observations illustrate how to organize evidence. They are not an Amigo API response, a customer case study, or measured product performance.
| Decision field | Example value |
| ----------------- | ----------------------------------------------------------------------------------------------------------------------------- |
| Scope | Move one synthetic appointment to an allowed alternative in a test scheduling system |
| Test channel | Application text only; phone and messaging are outside this test |
| Baseline | A reviewer performs the same fixture cases manually and records the outcome; timing comparison is still unmeasured |
| Configuration | Test service `scheduling-review`; record actual selected agent/graph and integration versions before execution |
| Success criterion | For every approved fixture change, the target read-back matches the requested record and value; no false completion statement |
| Required failures | Unauthorized subject, missing slot, rejected approval, target rejection, and interrupted response after submission |
| Stop condition | Any unintended target change or a claim of success without supporting target evidence |
| Decision owner | Named customer workflow owner, supported by technical and operations reviewers |
| Decision | Hold until the interrupted-response case has a documented reconciliation outcome and owner |
### Follow One Outcome Through Its Evidence
| Stage | Synthetic evidence | Claim it supports |
| -------------------- | ----------------------------------------------------------------------------------------- | --------------------------------------------------------------- |
| Source | Fixture appointment `appt-example-01`, original slot A, read at test start | The case has an identifiable starting record |
| Context | The test run's inspected context includes that appointment and allowed slot B | The workflow had the information needed for this decision |
| Configuration | Saved service selection and graph/action configuration | The reviewer can identify the configured path used in this case |
| Authorization | Test principal permitted to change only this synthetic record; a negative case is refused | The tested access boundary behaves as expected for those cases |
| Approval, if enabled | Reviewer grants the exact A-to-B request; no target change occurred while parked | The human decision was recorded before execution |
| Action | Integration result carries the test target's acknowledgement reference | The target acknowledged that particular request |
| Read-back | Test target reports `appt-example-01` at B | The intended external change is independently observed |
| Agent answer | The recorded answer states that the appointment moved to B | The answer is consistent with the observed target state |
For the interrupted-response case, the action result is unknown until the target is inspected. Record **unresolved**, identify the reconciliation owner, and hold retries. Do not fill the acknowledgement field from an agent's statement or from the approval record.
The [First Verified Conversation](https://docs.amigo.ai/developer-guide/guides/first-verified-conversation) starter produces a smaller executable evidence file. Its `external_action_verified: false` is intentional: it verifies a durable answer and conversation closure. Extend testing with [Verify an Integration Action](https://docs.amigo.ai/developer-guide/guides/verify-an-integration-action) to collect target-system evidence.
## Compare Effort, Cost, and Latency
For hospital integrations, complete the [HL7v2 integration review](/data/healthcare-interoperability) before estimating effort. Record inbound ADT/SIU feeds, outbound scheduling authority, acknowledgments, source-to-agent freshness, and recovery cases. An interface that is not yet verified remains a pilot dependency.
Complete the effort worksheet for access, mapping, implementation, validation, and operations. Track prerequisites and calendar lead time separately from engineering effort. Record assumptions and exclude work that has not been scoped; a universal deployment duration would conceal those dependencies.
Use [Cost and Latency](/platform-overview/cost-and-latency) to define the units and measurement boundary. Include retries, incomplete work, human handling, and external-system delay in the comparison where they affect the workflow. Keep contractual price inputs separate from Amigo's internal cost allocation.
## Make the Decision Reviewable
Choose **proceed within the recorded scope**, **proceed after named conditions**, or **hold**. Link each condition to an owner, evidence required, and review date. Include region/data-flow confirmation, retained/exportable evidence, support boundaries, staffing, and recovery behavior in the handoff.
After a configuration, source, or channel change, rerun the affected cases and update the decision record. A passed text pilot does not authorize a different channel or a broader clinical workflow. The [Operating Model](/platform-overview/operating-model) explains the decisions your organization continues to own.
## Complete the Enterprise Review
Technical acceptance is one part of a deployment decision. Record the following alongside the pilot results, using the proposed agreement and current assurance materials for commitments that product documentation cannot establish.
| Review area | Decision record |
| ---------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| Product fit | Required capabilities, confirmed deployment availability, excluded uses, and any dependency on custom or proposed work |
| Architecture and integration | Systems of record, interfaces, data flows, access requirements, mapping ownership, and tested failure handling |
| Security and data governance | Reviewed access controls, regional processing, subprocessors, retained artifacts, deletion and hold procedures, and applicable agreements |
| Reliability and support | Agreed service levels, capacity assumptions, support hours, incident ownership, escalation, and recovery evidence |
| Delivery and staffing | Scope of implementation work, prerequisites, named owners, acceptance milestones, and ongoing operating effort |
| Commercial terms | Pricing units, expected volume, third-party charges, implementation cost, and cost of exceptions or incomplete work |
| Portability and exit | Exportable data and configuration, permissions and formats, transition assistance, migration work, and termination obligations |
Link [Compliance and Audit](/operations-and-safety/compliance), [Data Residency](/platform-overview/data-residency), and [Cost and Latency](/platform-overview/cost-and-latency) to the corresponding review. Record exceptions explicitly, including who accepts them and when they must be resolved. A pilot approval covers its stated scope; production approval needs the operating arrangements for that scope as well.
# Reference Deployment
Review the logical boundaries, data flows, integration dependencies, and ownership decisions in an Amigo deployment before selecting a pilot architecture.
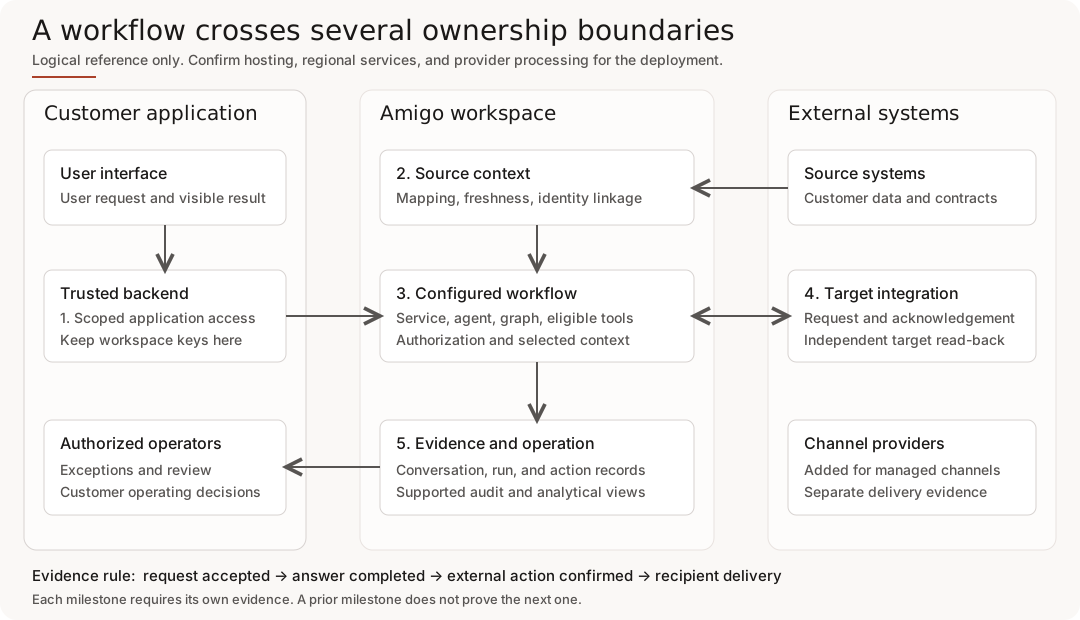
This reference follows an application-hosted scheduling workflow using a managed Amigo workspace and a customer scheduling system. It shows the logical responsibilities that must be connected. Confirm the actual regional services, hosting arrangement, external processors, and network paths for your deployment using [Data Residency](/platform-overview/data-residency).
## Follow the Data and Decisions
| Flow | What crosses the boundary | What to verify |
| ------------------------- | ---------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------- |
| 1. Application access | An authenticated user's request reaches the customer's trusted backend and the supported Amigo access path | Credential scope, user-to-entity resolution where needed, and which service the user may invoke |
| 2. Source context | Supported source records enter the workspace and become usable context after the applicable processing | Source ownership, mapping, freshness, identity linkage, and evidence that the needed record is queryable |
| 3. Workflow execution | The selected service resolves agent/graph configuration, available context, and eligible actions | Which configuration was selected, what is prompt guidance, and what authorization or validation actually enforces |
| 4. External action | A configured integration sends an authorized request to the scheduling system | Target credentials, approval policy where enabled, error behavior, acknowledgement, and independent read-back |
| 5. Evidence and operation | Conversation/run records and supported analytical or audit views inform application and operator decisions | Access, retention, missing evidence, exception routing, and who reconciles ambiguous results |
The diagram does not place every external provider inside Amigo's regional boundary. A phone, SMS, email, or other managed channel adds provider processing and delivery controls; use the [channel availability matrix](/platform-overview/capability-availability). Scribe uses its own provider/session contract and is not the same integration as application text.
## Decide the Integration Boundary
For an application you own, keep long-lived workspace credentials in the trusted backend. Use the supported scoped access flow for browser sessions. See [Serve an Agent From a Web App](https://docs.amigo.ai/developer-guide/platform-api/conversations/serve-agent-from-web-app).
For source data, specify the minimum records and relationships needed by the workflow. Import or connector acceptance is not proof that the serving view or caller binding is ready. Verify the actual read path before asking an agent to act on it.
For external writes, choose the actual integration endpoint and permitted principal. Where approval is enabled, identify the reviewer and the behavior while a decision is pending. The direct-integration approval flow and connector write-back review are separate capabilities. Target acknowledgement remains a separate requirement after either decision.
## Assign Responsibility Before Estimating Effort
| Work item | Customer responsibility | Amigo / implementation responsibility | Evidence that closes the dependency |
| ---------------------- | --------------------------------------------------------------------------------------- | ----------------------------------------------------------- | --------------------------------------------------------- |
| Workflow and outcome | Define eligibility, intended result, exceptions, and baseline | Map the workflow to supported configuration and controls | Agreed workflow and failure cases |
| Identity and access | Own user identities, roles, consent evidence, and source access decisions | Configure supported access and service linkage | Positive and negative access tests |
| Source integration | Supply test records, source contract, access, and mapping decisions | Configure the agreed ingestion/read path | Queryable synthetic case with attributable source |
| External action | Provide target contract, scoped credentials, test environment, and reconciliation owner | Configure and validate the agreed action path | Target acknowledgement and read-back, plus a failure case |
| Channel readiness | Approve intended communications and staff exceptions | Provision supported managed resources and routing as agreed | Test on the intended channel with delivery evidence |
| Evaluation and release | Approve acceptance criteria and operating policy | Supply configuration evidence and execute agreed validation | Reviewed case results and release decision |
| Ongoing operation | Own business exceptions and downstream corrections | Own platform operation and agreed implementation support | Escalation route, access, and recovery exercise |
These are planning responsibilities, not a substitute for the agreed support or commercial terms. Record named owners and any different allocation in the [evaluation packet](/platform-overview/evaluation-packet).
## Estimate Dependencies, Not a Universal Timeline
For each work item, record access lead time, unresolved design decisions, implementation effort, validation effort, owner, and blocking predecessor. Source-system access, identity mapping, managed sender readiness, and customer review can dominate the calendar even when the client code is small.
Separate the initial technical connection from a deployable workflow. A successful [first conversation](https://docs.amigo.ai/developer-guide/guides/first-verified-conversation) verifies a narrow integration milestone; it does not complete channel readiness, target reconciliation, or operational acceptance.
## Review Portability and Recovery
List the configuration, records, traces, and analytical data you need to retrieve, then identify the supported export or access path and permission for each. Confirm format, scope, freshness, retention, and contractual constraints. Retrieve a representative sample and verify that the receiving system can interpret it, including identifiers and provenance. Record any transformation or reconstruction work required.
Test restoring a reviewed configuration and separately test how the team handles external actions that already occurred. Reverting an agent configuration does not reverse an appointment change, message, or other target-system mutation.
# Capability and Availability
Distinguish documented interfaces, managed provisioning, separately authorized services, preview capabilities, and retired paths during deployment planning.
Use this matrix to identify the implementation path and the readiness questions for a proposed deployment. It reflects the documented contract reviewed on September 7, 2026. A documented interface is not proof that your workspace, region, credentials, or channel resources are enabled. Record those deployment-specific confirmations in the [evaluation packet](/platform-overview/evaluation-packet).
**Private preview** means a capability is available to specifically enabled deployments under an agreed scope. Confirm enrollment, supported channels or object types, configuration, and operating limits with the implementation owner. Architecture pages can describe those capabilities alongside broadly available behavior; the access requirements determine which parts your deployment can use. Console visibility is a separate question from runtime availability.
**Design direction** identifies a proposed contract or extension. The [object-memory](/agent/memory#design-direction-object-memory) and [Universal Reasoning Harness](/agent/reasoning-engine#design-direction-universal-reasoning-harness) sections use this label for work beyond the documented current paths. It does not imply private-preview enrollment or general availability.
| Capability | Interface and access boundary | Readiness and limitations |
| --------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Platform configuration and application text | [Platform API](https://docs.amigo.ai/developer-guide/platform-api/platform-api) and [Platform SDK](https://docs.amigo.ai/developer-guide/platform-api/platform-sdk), scoped to a workspace | Requires the correct regional base, credential, and configured service; browser access needs its supported scoped flow |
| Classic integrations | [Classic API](https://docs.amigo.ai/developer-guide/classic-api/core-api) with organization credentials and Classic SDKs | A separate resource and credential model; Platform examples are not drop-in replacements |
| Phone and human operation | [Phone](/channels/voice) and [Operators](/operations-and-safety/operators) | Confirm service configuration, phone provisioning, runtime/provider behavior, and operator phone access; browser operator joining is retired |
| Managed SMS | [SMS](https://docs.amigo.ai/developer-guide/platform-api/conversations/sms) and provisioned service bindings | Registration, consent evidence, setup suppression, content checks, and delivery evidence are distinct; managed provisioning is separately authorized |
| Managed WhatsApp | [WhatsApp](/channels/whatsapp) and managed business setup | Confirm the business/recipient identity, phone readiness, use case, and reply-window behavior; template registration is not template sending |
| Managed iMessage | [iMessage](/channels/imessage) | Provisioned lines and provider/device support; confirm media and delivery behavior for the intended deployment |
| Managed email | [Email](/channels/email) | Sender/domain and use-case readiness; transactional/marketing policy and unsubscribe evidence remain separate from send acceptance |
| Browser forms | [Surfaces](/channels/surfaces) | Form creation, link delivery, submission, and projected data are separate milestones; a submission is not automatically a dataset-intake file |
| Clinical documentation sessions | [Scribe](https://docs.amigo.ai/developer-guide/platform-api/scribe) | Separate deployment base, provider access, supported visit type/template, and session mode; artifact generation can remain asynchronous |
| Source ingestion and querying | [World Model](/data/world-model), [Connectors](/data/connectors-and-ehr), and [Intake](/data/customer-data-intake) | Confirm an active EHR, FHIR-store, or warehouse adapter, mapping, freshness, and queryable projection. Generic SMART FHIR, REST, file-drop, and webhook source types are retired; authenticated dataset intake is separate. |
| Approval-gated integration calls | [Integration approval](https://docs.amigo.ai/developer-guide/platform-api/integrations/approval-gated-integration-writes) | Enabled per integration on supported text/SMS paths; a decision is consumed on the next supported turn and is not external delivery proof |
| Connector write-back review | [Review Queue](/data/review-queue) | Separately enabled private preview; do not infer general availability from direct-integration approvals |
| Standalone ringless voicemail / public upload links | [Voicemail retirement](/channels/voicemail) and [current intake](/data/customer-data-intake) | Retired paths; ordinary outbound-call voicemail handling and authenticated dataset intake are separate retained behaviors |
| HL7v2 inbound and outbound | [HL7v2 ADT/SIU and hospital messages](/data/healthcare-interoperability) | Integration design required; no native receiver or sender verified. Agree on message profiles, direction, acknowledgment, replay, and measured freshness. |
## Console Visibility and Separate Services
Source classifications reviewed 2026-09-07. These distinctions do not certify deployment or enrollment. Confirm access for the intended workspace before relying on a capability.
| Capability | Interface | Console access | Readiness |
| ---------------------------------------- | ------------------------------------------------------------------------------- | -------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| Scribe clinical documentation | Separate provider API and schema | Use the provisioned provider workflow | Confirm Scribe base, provider enrollment, capture mode, visit type/template, and processing region separately from Platform workspace access. |
| Proactive Journeys | Demo presentation | Synthetic sample data in permitted demo workspaces | Use for evaluation of the presentation only; it does not establish live patient journeys or customer enablement. |
| Agent Memory Console surface | Demo presentation; distinct from runtime memory behavior | Synthetic sample data in permitted demo workspaces | Do not use this display as evidence of a workspace's retained memory or queryable records. |
| Outbound Write Approvals Console surface | Related connector write-back review is separately enabled preview functionality | Internal tooling | Arrange the supported review process with the implementation owner. This differs from conversation-scoped direct-integration approvals. |
| Simulation Coverage Console surface | Interface access and Console visibility are separate | Internal tooling | Confirm the supported evaluation and reporting path for your workspace; a coverage API contract does not grant Console access. |
## Record a Deployment Confirmation
For every capability in the pilot, record the intended region, API or managed service, access owner, required configuration, evidence of enablement, remaining limitation, and review date. Use explicit states: **confirmed in this test deployment**, **awaiting provisioning**, **not included**, or **requires separate preview agreement**.
A future proposal should have its own record and decision date. Do not place it in the confirmed column because it appeared in a demonstration or a source commit. Use the implementation links for current contracts and [upgrade guidance](https://docs.amigo.ai/api-reference/change-logs/upgrade-guide) when reconciling older integration assumptions.
# Data Residency
Regional deployment endpoints, data-flow boundaries, and practical planning considerations for regulated deployments.
The region reported by the Platform API identifies the deployment serving the request. It is not an editable workspace placement policy or proof that every system involved in the workflow processes data in that region. Agree on the actual regional data and service boundary when provisioning a deployment.
## Regional Endpoints
| Deployment region | Platform API endpoint |
| ----------------------- | -------------------------------------- |
| **US East** | `api.platform.amigo.ai` |
| **Canada Central** | `api-ca-central-1.platform.amigo.ai` |
| **EU Central** | `api-eu-central-1.platform.amigo.ai` |
| **Australia Southeast** | `api-ap-southeast-2.platform.amigo.ai` |
`api.platform.amigo.ai` is the default US endpoint, not a global router. To create or access a workspace in another supported region, use the endpoint assigned to that regional deployment. The Platform TypeScript SDK defaults to the US endpoint and supports a custom base URL for regional deployments.
{% hint style="info" %}
Regional service availability can differ. Confirm that the channels, connectors, models, and supporting services required by your deployment are available in the target region before provisioning production workloads.
{% endhint %}
## Workspace Placement
Workspace creation does not select a region independently of the deployment endpoint. The workspace update path still accepts a legacy region value for compatibility but ignores it; a successful update does not move data or change the region reported by the serving deployment.
Amigo does not currently expose a self-service cross-region workspace migration. Organizations operating in multiple regions should plan separate workspaces and configuration promotion for each region.
## What the Boundary Covers
Region placement applies to Amigo-managed workspace data and regional services that are provisioned for that workspace. Workspace authorization remains a separate control: region placement does not replace tenant isolation, role-based access, or resource-level permission checks.
Some workflows intentionally communicate with systems outside Amigo's managed regional boundary, including:
* Customer-hosted EHR, CRM, and integration endpoints
* Telephony, messaging, email, and identity providers
* Model, speech, and infrastructure providers used by Amigo or selected by the customer
* Operator browsers and customer applications
Those systems have their own processing locations, retention policies, and transfer mechanisms. Connector traffic also follows the location of the customer endpoint. Review the complete data flow rather than treating the workspace region as an end-to-end residency guarantee.
A configured model can route requests to more than one hosting provider, including a fallback provider. Confirm the permitted providers and processing locations for both normal operation and fallback. A model name or regional API hostname alone does not establish where inference runs.
## Multi-Region Planning
For organizations serving more than one jurisdiction:
1. Choose the regional endpoint before creating each workspace.
2. Keep patient and operational data in the workspace intended for that jurisdiction.
3. Promote agent configuration separately to each workspace.
4. Provision regional channel resources and connector credentials independently.
5. Validate every subprocessor and external integration against the intended data-flow boundary.
Entities and conversations in separate workspaces remain separate unless your own integration deliberately transfers or reconciles them. Do not assume automatic cross-region identity matching or configuration synchronization.
## Compliance Planning
Region choice is one input to a compliance program, not a certification by itself. Applicable requirements depend on the organization, data, purpose, external systems, and contractual terms involved in the deployment.
Before production launch, confirm with Amigo:
* The services available in the requested region
* The managed-data boundary for each channel and connector
* Encryption, retention, deletion, and backup requirements
* Required contractual terms and subprocessors
* Any approved cross-border transfer mechanism
See [Compliance and Audit](/operations-and-safety/compliance) for documented platform controls, and [Deployment Model](/platform-overview/deployment-model) for workspace-isolation patterns.
# Cost and Latency Optimization
Plan deployment cost and latency measurements, distinguish customer billing from internal cost allocation, and understand runtime optimization trade-offs.
## Estimate the Deployment
Start with the workflow and the commercial terms proposed for your deployment. Record expected eligible volume, channel mix, conversation length, source processing, integration work, evaluation, and human exception handling. Ask which items are included, which vary with usage, and which are billed by another system. These are planning inputs, not a published universal price formula.
Use the [integration effort worksheet](/platform-overview/evaluation-packet) to separate access/provisioning lead time, implementation, validation, and ongoing operation. Compare like-for-like outcomes: count incomplete work, retries, and human follow-up in the denominator where they are part of the workflow. Cost per attempted interaction and cost per verified outcome answer different questions.
## Measure the Latency That Matters
| Measurement | Start and end boundary | Report alongside it |
| ------------------------------------- | ---------------------------------------------------------------------------- | ----------------------------------------------------------------------------------- |
| First visible text / audible response | Accepted user input to the first rendered text or audible output | Channel, service configuration, and whether the response is only an acknowledgement |
| Completed answer | User request to the actual final answer, including supported background work | Pending and timed-out cases; exclude neither silently |
| External outcome | User request to target acknowledgement and read-back where required | Target-system delay, approvals, and unresolved cases |
| Human exception | Exception raised to the agreed human response or resolution | Staffing window and workload |
Choose the observation window and percentiles before testing. Report sample size, failures, missing observations, configuration, and the intended channel. A simulation result is not a latency guarantee for a live phone call or an external scheduling system. Any contractual service level must be confirmed separately.
## Runtime Optimization
Amigo's platform-managed conversation runtime uses a stable prompt prefix, per-task model routing, and timing controls for live responses. Provider-owned speech-to-speech sessions have a different execution path. Measure the selected runtime under the expected workload before changing its configuration.
## Stable-Prefix Prompt Caching
The platform-managed conversation runtime builds prompts in two parts:
* **Static prefix** - Session-constant instructions such as the agent identity, service description, capabilities, context-graph topology, and output format.
* **Dynamic suffix** - Per-turn state, objectives, active guidance, current time, and bounded conversation history.
When the selected model provider supports prompt-prefix caching, sending the stable content first lets the provider reuse work across turns with the same prefix. The dynamic suffix still changes as the conversation advances, and conversation history remains part of that per-turn content.
This split reduces repeated processing without changing what the model receives. A provider that does not support compatible prefix caching can process the complete prompt normally; correctness does not depend on a cache hit.
## Per-Task Model Routing
Different parts of the pipeline use different models based on what the task demands:
| Task | Model Selection | Why |
| ------------------------- | -------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Navigation** | Separately configured low-latency model | Produces a small, structured routing decision on each turn |
| **Response generation** | Separately configured engagement model | Produces the caller-facing response, where language quality matters most |
| **Filler speech** | No separate model call | Short time-buying phrases come from prepared templates, while context-aware fillers are produced inline by the same model that generates the response - so no extra model round trip is added |
| **Post-call data review** | Separately configured offline processing | Runs outside the live turn path, so its latency and model choice can differ from conversation generation |
| **Metric evaluation** | Definition- and pipeline-specific model tier | Eligible evaluations can run eagerly or in scheduled processing without blocking the live conversation |
Separate model roles let teams and platform defaults balance latency, quality, and cost by task. Actual usage depends on the resolved service configuration, runtime, fallbacks, and enabled evaluation paths.
## Pipeline Latency Budget
For voice interactions, measure transcription, first audio, and full response latency separately. End-to-end response time varies with the selected models, speech provider, tools, and network path. Three mechanisms reduce the delay callers perceive:
**Filler speech** covers the gap between when the caller finishes speaking and when the agent's full response is ready. The caller hears "Let me check on that" or a similar phrase while the LLM generates the real response.
**Prompt caching** can reduce repeated input processing when the selected provider supports it. The session-constant prefix stays stable while the current state and conversation history remain in the dynamic suffix.
**Two-phase initialization** can prepare the agent during ring time on supported conference-based voice paths. It loads available context and can begin generating the greeting before answer. Provider-side prompt caching and preparation can still miss, so this reduces expected delay rather than guaranteeing instant audio.
## Usage Visibility
The Platform API exposes workspace-scoped billing reads for current-period usage, usage trends, invoice lists, and invoice detail. Values depend on the meters that producers emitted and on asynchronous projection, so an accepted interaction is not proof that every billing rollup has already refreshed.
Teams can use those API responses for their own reporting and reconciliation. Invoice detail includes the line items generated for that billing period, with meter key, quantity, unit price, and amount; the actual catalog depends on configured prices and emitted usage rather than a fixed list of channel examples.
## Cost to Serve Visibility
[Cost to Serve](/intelligence-and-analytics/cost-to-serve) describes staff-only views of Amigo's inference and infrastructure costs. Those internal allocations are separate from customer usage, invoices, and contracted prices. Use the agreed pricing schedule and customer billing records for procurement estimates and invoice reconciliation.
# World Model
Event-sourced data layer that accepts supported healthcare inputs, preserves provenance and confidence, and projects current entity state.
The world model is the platform's shared event and entity layer. Connectors, agent tools, operational workflows, and analytics can contribute or consume workspace-scoped data through supported interfaces. Agents receive a bounded amount of selected context automatically and use tools for facts that are not already present.
This creates a feedback loop between data and agent activity without making every observation automatically available or writable. Session construction selects ambient context, tools perform explicit reads and writes, and accepted observations can become inputs to later projections and analytics.
The world model preserves supported observations with provenance and a source-class confidence value. Current entity state is a computed projection over retained relevant events rather than an in-place record update. Projection rules can therefore resolve conflicting inputs without discarding their retained history.
{% hint style="info" %}
Supported observations are recorded as events. Current entity state is derived from the relevant retained events. Recording an observation preserves what its source reported; it does not independently verify the observation.
{% endhint %}
## Place in the System
The world model supplies shared context to several consumers. It is distinct from the [Context Graph](/agent/context-graphs), which describes how an agent should work, and from [memory](/agent/memory), which can supply generated context from prior interactions. An external system still determines whether it accepted a requested change.
Read this page in three parts: how source evidence is retained, how projections select current values, and how a conversation reads or contributes observations. [Core Concepts](/platform-overview/core-concepts) introduces the relationships; [How It Works](/platform-overview/how-it-works) follows them through an appointment change.
## Data Pipeline
Data enters from external systems through connectors, passes through unification into the event store, and resolves into entity projections. Agent conversations add source-attributed observations to the same model. Metrics and analytics read the resulting state and history. Outbound policies separately decide which events are eligible for delivery. Where connector review is enabled, an eligible mutation is staged as a proposal before an authorized reviewer decides whether to approve it. That decision does not change the source event's confidence.
## Why Event Sourcing for Healthcare
Healthcare data varies widely in structure, freshness, and authority. The world model is designed to make those differences explicit instead of treating every input as equally reliable.
**Source records can be incomplete or stale.** Clinical notes, copied templates, structured records, and operational systems capture different parts of a patient's history. Retaining source and effective time lets consumers distinguish a recent observation from an older record instead of assuming that every field is current.
**Patient observations and verified records serve different purposes.** A caller can report a new symptom or correct an old address while also being uncertain about a medication name or appointment date. Record the observation with its source, then use the workflow's verification rules before acting on it. A lower-ranked observation can remain in the retained history even when it does not become the projected value.
**External systems have uneven reliability and throughput.** EHRs, FHIR stores, practice management systems, and insurance verification services all behave differently. Response times vary, timeouts occur, and some sources can return stale data. Integrations should therefore expose failure and freshness rather than assume constant availability.
**An overwritten value is not enough evidence.** A current-value record alone cannot explain which source contributed the value, what it replaced, or what change was intended when a downstream operation failed. Conflict handling needs an explicit policy. World-model observations instead carry source and confidence, with supersession data where applicable. Current state is projected without rewriting the contributing events. Historical availability remains subject to explicit lifecycle actions, retention, and the bounds of each read surface.
## Four Invariants
The world model follows four core rules, with the lifecycle exceptions called out below.
### 1. World-Model Writes Become Events
Supported world-model write paths add events rather than editing the projected entity row. The serving state is recomputed asynchronously from the retained events relevant to that entity.
Under normal retention, competing observations remain separate events. Projection chooses current values by confidence class and uses recency as the tiebreaker within a class, rather than blindly applying global last-write-wins behavior.
### 2. Events Are Append-Only and Immutable
An accepted event is not updated in place. If new information contradicts an earlier event, a new event can supersede it while both remain available under normal retention. Authorized retention, erasure, and workspace-lifecycle operations remain separate exceptions.
Corrections retain their own provenance. While the contributing events remain available, a reviewer can inspect the earlier observation and the correction selected by the projection. Source validation and correction procedures remain necessary before using that data for an operational decision.
This matters for healthcare operations because it provides:
* **Projection evidence** - Retained source events can explain which observations contributed to modeled state.
* **Temporal analysis** - Historical event reads can support point-in-time reconstruction where the required events and projection logic remain available.
* **Correction without in-place mutation** - A new event can supersede an earlier observation instead of editing it.
### 3. Entity State Is a Pure Function of Events
The entity-state projection is deterministic for the same retained input set and projection version. Projection runs asynchronously from event acceptance, so a successful write can precede the updated serving view. Model-generated memory and narrative products follow separate, non-deterministic derivations.
This determinism makes current entity state explainable and repeatable. Outbound delivery is a separate path: a published event is evaluated against destination policy, and the connector sends that eligible event payload without rebuilding the entity projection at delivery time. A patient's phone number might still project from a higher-confidence EHR observation instead of a lower-confidence conversational observation, but only an event selected by outbound policy is considered for external delivery.
#### Multi-Level Projections
Entity state is one derived view, but not the only one. Different derived products use different methods. The entity-state fold and structured connector projections are deterministic. Episodic memory extraction and semantic user-model consolidation are model-generated, bounded processes that retain lineage to their supporting observations; identical inputs do not guarantee identical narrative text.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart TD
events["Raw Events\n(confidence-scored, append-only)"] --> entity["Entity State\n(patient, provider, appointment)"]
events --> episodic["Episodic Observations\n(model-extracted, source-linked)"]
episodic --> semantic["User Model\n(bounded semantic consolidation)"]
entity --> clinical["Structured Context\n(deterministic connector projection)"]
entity --> analytics["Analytics and Operational Views"]
```
| Level | What It Projects | Derived From |
| ------------------------------------ | -------------------------------------------------------------------------------- | ----------------------------------------- |
| **Entity state** | Current state of each patient, provider, appointment, and other entity | Raw events |
| **Conversation memory** | Episodic observations and a consolidated user model with source lineage | Conversation transcripts and prior memory |
| **Structured context** | Connector-derived context such as current conditions, medications, and allergies | Current entity and connector records |
| **Operational and analytical views** | Scheduling, quality, and workflow-specific summaries | The inputs defined by each view |
A new event can update entity state after asynchronous projection and can become input to other derived products on their own processing schedules. Each product documents its own derivation and freshness rather than inheriting a universal deterministic chain.
### 4. Confidence Resolves Conflicts
When two sources provide conflicting information about the same fact, the projection first compares their source-class confidence. Recency breaks ties within the same class. This prevents a newer low-authority observation from automatically replacing a higher-authority one.
| Confidence | Source | Example |
| ---------- | -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------- |
| **1.0** | Authoritative | Manual entry, explicit relationships, authoritative API writes |
| **0.95** | Human-approved class | Named confidence class retained in the world-model registry; current external-write proposal decisions do not promote source observations into it |
| **0.9** | High | Operator-verified data, high-quality adapter output |
| **0.8** | EHR-trusted | Trusted clinical data from EHR systems |
| **0.7** | Verified | Data assigned the verified source class by a supported producer |
| **0.5** | Self-report | Patient-submitted form data, patient-confirmed information |
| **0.3** | Agent raw | Raw voice agent inference, unverified extraction from conversation |
| **0.0** | Rejected | Observations explicitly assigned the rejected source class |
For fields using this ordering, higher-confidence observations take precedence; recency breaks ties within a class. A recent caller report can therefore remain in history while an older, higher-ranked source supplies the projected value. Source rank alone does not establish that the selected value is current or correct.
Confidence is a source-class ranking, not model-reported certainty. Supported agent-originated clinical writes default to the `agent_raw` class unless a trusted server path supplies a different allowed value. Later observations from a higher-ranked source can supersede the projected value without erasing retained provenance.
Phone projections normalize valid numbers before caller matching. International country codes are preserved, North American numbers are standardized when the country can be inferred safely, and non-phone text is excluded. Ambiguous national formats are retained without inventing a country code. This normalization improves matching across differently formatted source values but does not replace identity verification.
Entity-state fields retain the winning event's source and confidence. Other derived products do not inherit a universal confidence rule: structured connector projections, generated memory, and analytical views each define their own derivation and evidence. Consumers should use the provenance and quality signals exposed by the specific product rather than assuming confidence propagates unchanged through every downstream view.
## Three Data Channels
{% hint style="info" %}
It is useful to think about agent data access through three channels. The exact payload and tools depend on the service, session, runtime, and workspace configuration.
{% endhint %}
### Ambient
Selected data that is pushed into the agent's context without a tool call when the session and service configuration make it available. Examples can include patient identity, upcoming appointments, or recent encounter context. Missing or unavailable source data is not invented.
This channel reduces repetitive lookups for the bounded context selected at session or turn construction. It does not guarantee that every current clinical or operational fact is loaded; the agent still uses queried tools for authoritative details outside the ambient payload.
### Queried
Data that the agent retrieves on demand through tool calls during a conversation. The agent decides it needs specific information and requests it. Examples: searching for available appointment slots, looking up insurance details, checking medication lists.
Queried data covers information that is too large, too dynamic, or too specific to include in ambient context. Tools should remain the authoritative path for details that require a current lookup.
### Extracted
Supported extraction and write tools can capture structured observations from a conversation. Agent-originated clinical writes normally use the `agent_raw` source class unless a trusted server path assigns another allowed value.
During a live voice call, the system can extract configured structured patient fields from recent conversation context, including contact, demographic, language, address, and insurance information. Captured fields are written as source-attributed events and can become available before the call ends.
Extraction is an explicit configured runtime capability. Do not assume that every statement in a conversation becomes a world-model event.
Extracted data enters the world model with source provenance and confidence. Unattended outbound delivery applies source eligibility, confidence thresholds, schema checks, and destination rules. Where private-preview connector review is enabled, an otherwise eligible event can be staged for approval at any confidence; the decision authorizes that specific proposal without promoting the observation's confidence. See [Connectors and EHR Integration](/data/connectors-and-ehr).
## Open Schema
The event model supports additional types of observations while retaining a common structure for identity, source, and time. New types still require agreed business definitions, validation, and consumer support.
Entity-type and event-type fields are text rather than database enums, so trusted producers can introduce a new type without an enum migration. That does not make arbitrary input self-structuring: the producer must still provide a valid event, and consumers need projection or query support for the new shape.
This flexibility is bounded by the caller's write scope, registered enrichment keys, route validation, and the projection support available for a new type.
## Entity Ontology
Entity types use ontological categories rather than domain-specific roles. A `person` entity can be a patient, a practitioner, or both - the projection function detects roles from the underlying event data rather than requiring a type declaration up front.
Person projection is role-aware. It examines the FHIR resource types on an entity's events to detect which roles the person fills and produces output that includes the relevant sections for each role. A person entity with patient events gets demographics and clinical sections. One with practitioner events gets a profile section. A merged entity with both gets all sections plus a roles list. This means a single person entity can represent the same individual across clinical and operational contexts.
### FHIR-Sourced Entity Attributes
When data arrives through EHR connectors that support FHIR, the projection pipeline surfaces a rich set of fields as directly queryable entity attributes. This means agent tools can filter, search, and reason over these fields without parsing raw FHIR resources.
| Entity Type | Projected Fields |
| ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Patient** | Full address (line, city, state, postal code, country), preferred language, marital status, race, ethnicity, emergency contact (name, phone, relationship), facility assignment, primary insurance (payer name, practice payer ID, member ID, policyholder name, policyholder relationship, policyholder DOB) |
| **Appointment** | Participants (provider, patient, location references and display names), appointment type, modality, duration, timezone, cancellation reason |
| **Slot** | Provider, facility, specialty, visit type IDs and names |
| **Practitioner** | Member ID, scheduling eligibility |
| **Location** | Full address, timezone, facility identifier, geographic coordinates |
State and territory values are normalized to standard two-letter abbreviations (e.g., "Virginia" becomes "VA"), so agent queries and licensed-state filters work consistently regardless of how the source system formats addresses.
These attributes participate in the same confidence-scored projection as all other entity data. When the same field arrives from multiple sources, the standard resolution rules apply - higher confidence wins, with recency as the tiebreaker within the same confidence class.
Other built-in entity types - place, organization, outbound task, call, and encounter - have dedicated projection logic. Unknown types can fall back to generic projection; richer custom projections require a supported configuration or implementation path.
## Entity Enrichment
Entity enrichment adds workspace-defined attributes to an entity, such as a preferred communication channel or a program-specific status. Each attribute follows registered validation rules and retains source evidence. Use existing resource fields where they already represent the intended information; define enrichment keys for the additional attributes the workflow needs.
Each enrichment value is a per-key event carrying provenance fields such as source, source system, confidence, and effective time. A patient's preferred language from a human operator, a configured data import, and a call transcript can coexist as separate events; the projection selects the current value by confidence class and then recency within a class.
### Registry-Governed Keys
Each workspace registers its enrichment keys before use. The registry specifies the entity type, allowed values, value type, minimum write confidence, and whether the value is personally identifiable information (PII). Supported types include string, number, boolean, date, enum, and JSON.
API writes against unregistered keys are rejected. Agent-extracted values with unregistered keys are dropped before entering the event stream. Register the required keys and verify the retained values when testing a capture workflow; a conversation mentioning an attribute does not prove it was stored.
The key identifier and value type are immutable after registration. To change them, admins create a new key and migrate. Unregistering a key stops future writes but does not itself rewrite existing `entity.enriched` events; separate retention or source-lifecycle actions can still affect historical availability.
### Why This Matters
The same pattern handles manual admin edits, supported connector backfills, structured intake capture, and agent-extracted values. Each event retains its source and confidence, allowing a higher-confidence system import or human correction to outrank a conversational extraction while preserving the contributing observations.
This makes registered custom attributes source-attributed, confidence-resolved, and queryable with their event provenance.
## Entity Search
The current entity list supports case-insensitive text search across identifiers, display name, entity type, medical-record number, and phone, with additional filters for entity type, source, source system, FHIR resource type, and projection availability. The entity-intelligence search surface provides display-name search with selected filters.
Meaning-based entity retrieval is not currently available. The legacy `search_semantic` compatibility tool returns no results; use the supported text and field filters instead.
## Write Semantics
World-model writes submit events, and entity state is projected asynchronously. A successful API response does not imply that the new value is already visible in the entity projection. Use the response semantics of the specific endpoint and allow for projection delay. Supported patterns include:
* **Single-event submission** followed by asynchronous entity projection
* **Deterministic entity identifiers** when the caller supplies a canonical identifier or explicit entity ID; creation without either is not idempotent
* **FHIR upserts** that link a new event to the prior event for the same source resource through `supersedes`
* **Per-key enrichment history** with current-winner projection by confidence class and recency
### Fresh Enrichment During a Conversation
Where enabled for the workspace, supported interactive enrichment writes can also become available through a temporary read overlay before the asynchronous projection catches up. Conversation reads use the same confidence and recency ordering as the projection; a newer low-confidence observation does not automatically replace a higher-confidence value.
This path is best-effort and requires the applicable write and read capabilities to be enabled. A failed overlay write or read falls back to projection freshness. Connector ingestion, replay, and batch updates still follow their asynchronous projection path. The overlay does not make all world-model writes immediately visible.
## Write Scope Isolation
Supported agent write tools receive a server-constructed write scope that limits the workspace and entity they can target, whether creation is allowed, and the resource types or confidence available to the operation. The exact scope depends on the session and runtime.
Trusted system services use separate service authorization rather than an agent session's write scope. Their access is not evidence that a model-originated tool call can bypass its own scope.
Write scope constrains supported model-originated persistence paths, while source-class projection prevents a lower-ranked retained observation from winning over a higher-ranked value. Customers should validate the specific tools and runtimes they enable rather than infer one universal check across every code path.
{% hint style="info" %}
Write scope isolation is one of the platform's structural safety controls. For how this fits into the broader safety architecture, see [Runtime Safety](/operations-and-safety/runtime-safety).
{% endhint %}
## Direct Agent Access via Platform Functions
Beyond the three data channels, agents can query world model data directly using [platform functions](/agent/platform-functions). These are SQL, AI, Python, and table-valued functions that run on the platform's compute layer and return results mid-conversation. Unlike the ambient channel (pre-loaded context) or the queried channel (built-in tool calls), platform functions can join live entity data with analytical aggregations in a single call.
Built-in platform functions cover common patterns: entity confidence assessment (how trustworthy is the data for this patient?), caller history lookup (what happened in prior calls with this number?), and patient summary briefings. For the long tail of questions no pre-built function anticipated, a workspace registers parameterized data queries (`wsq_`) that run against its own custom tables. Platform functions are read-only; recording new observations as world model events is done through dedicated write tools. Those tools enforce the write scope for their runtime, and accepted events become visible through the asynchronous projection semantics described above.
For the full platform functions reference, see [Platform Functions](/agent/platform-functions).
{% hint style="info" %}
**Developer Guide** - For API endpoints, SDK examples, and integration details, see the [Data & World Model](https://docs.amigo.ai/developer-guide/platform-api/data-world-model) section of the developer guide.
{% endhint %}
# Connectors and EHR
Data pipelines that ingest supported healthcare sources and deliver eligible world-model events to configured external destinations.
## Connector System Overview
The connector system links supported external systems with the workspace's [world model](/data/world-model). It ingests data through supported EHR adapters, FHIR stores, and the supported warehouse connector; preserves source confidence and provenance; and delivers eligible events to configured destinations.
Data sources and sync behavior are configured through the Platform API and the Developer Console. Supported adapters map source records into world-model events. Protocol support, mapping, identity resolution, and outbound operations must be confirmed for the selected connector.
## How Connectors Work
Each external system has its own availability, rate limits, update cadence, and acceptance rules. An integration needs to account for those conditions and expose failures to the team responsible for recovery.
The connector system combines push-based and scheduled ingestion with connector-specific checkpoints and deduplication. Checkpointed polling paths can recover eligible inbound changes on a later poll. Outbound delivery has different semantics: the standard automated path is at-most-once and reports a failed write without automatic reconciliation, while approved proposals for the idempotent FHIR sink types can be retried under their separate delivery policy.
**Inbound** data arrives through two mechanisms depending on the source system's capabilities:
* **Scheduled sync** - The connector checks external systems on the cadence configured for that source. Supported content-hash deduplication paths suppress unchanged records; identifiers and checkpoints determine the selected adapter's recovery behavior.
* **Real-time webhooks** - Supported integrations can receive push notifications as changes happen. Request verification, duplicate handling, and whether the path fetches a full resource before mapping are connector-specific.
Both paths feed into the same entity resolution and enrichment pipeline. Source-specific adapters handle quirks such as business-hour gating, incremental sync, reference data handling, and rate limit management.
**Outbound** write-back first requires an eligible source and destination scope. The unattended path also applies its confidence threshold; a review-configured destination instead stages the source-eligible event at any confidence for an explicit decision. Both paths pass the event payload to connector-specific validation and mapping without rebuilding the entity projection at delivery time. A workspace can target multiple external systems, and a failure at one destination does not block evaluation for another.
The world model records supported observations and requested changes. Connector outcomes provide separate evidence of external delivery. Capacity planning must account for destination limits as well as the rate at which agents generate work.
## Connector Types
The current data-source create contract accepts `ehr`, `fhir_store`, and `snowflake`. A configured source type does not establish that every vendor, resource, sync strategy, or outbound operation is supported.
| Data-source family | Current inbound path | Current outbound boundary |
| ------------------ | -------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------ |
| EHR | Registered polling adapters for CharmHealth, Healthie, and MBP; athenahealth has a separate changed-data/subscription path | Registered handlers for athenahealth, CharmHealth, and MBP; supported operations vary by adapter |
| FHIR store | Registered FHIR-store polling path | Registered FHIR-store handler with operation-specific conflict handling |
| Warehouse | Registered `snowflake` polling path | No corresponding outbound handler in the reviewed registry |
Generic `smart_fhir`, `rest_api`, `file_drop`, and `webhook` data-source types are retired. A `webhook` sync strategy is a separate configuration value; it does not create a general webhook receiver. Authenticated [dataset intake](/data/customer-data-intake) remains a separate file-ingestion path.
For HL7v2 ADT/SIU feeds or outbound hospital messages, use [HL7v2 Integration](/data/healthcare-interoperability) to scope the required integration and its evidence. These capabilities are not implied by a FHIR connector or by a catalog label.
Reliability controls vary by connector and operation. Supported paths can use source checkpoints, content-hash deduplication, bounded retries, circuit breakers, or failure records, but integrations should rely only on the behavior documented for their selected connector.
### Unification Engine
The unification engine is not a connector itself. It is the transformation layer that supported inbound connectors feed into. Raw records can be mapped to world model events using configurable rules with dot-path field extraction for nested source data. Generic sources may need only connector configuration and mapping rules; a new vendor protocol or operation can still require adapter code.
### Data Freshness
How quickly data appears in the world model depends on the connector type and configuration:
* **Webhook and push-based EHR connectors** - Usually lower latency than polling, but timing still depends on the source, queueing, mapping, and asynchronous world-model projection.
* **Scheduled connectors (supported FHIR, EHR, and warehouse sources)** - Determined by the source configuration and active adapter.
* **Authenticated dataset intake** - A separate workflow whose freshness depends on submission and processing.
Supported connector ingestion paths attach source-specific confidence and provenance when data enters the world model. Agents and projections can then distinguish stronger source classes from less certain observations without hiding either source.
## EHR Integration
Clinical data flows in both directions: external records enter the world model so the agent has context, and eligible world-model events can be delivered to configured destinations. Information captured during a conversation remains a source-attributed observation unless an outbound policy selects it for delivery. The agent reads projected entity state, while outbound connectors receive the eligible event payload and report the destination outcome separately.
### FHIR R4 and SMART Authentication
FHIR resource access, backend authentication, and EHR app launch are separate capabilities. The active FHIR-store and EHR adapters determine which connection and authentication settings are usable.
SMART Backend Services signing and token-exchange utilities remain in the platform, but the generic `smart_fhir` data-source type and its connector handler have been removed. Do not create that retired type or infer an active Epic connector from a catalog entry, signing endpoint, or stored configuration. Confirm the supported adapter and enrollment with the implementation owner. Backend authentication does not establish EHR-context launch for a user-facing application.
The FHIR API supports patient search, resource CRUD with entity cross-referencing, resource history with field-level change tracking, bundle import, and scoped sync failure investigation. It serves a broad set of clinical resource types - including Observation, MedicationStatement, FamilyMemberHistory, and QuestionnaireResponse - and supports patient-scoped filtering. Actual read and write availability still depends on the connector type, destination capabilities, credentials, and granted scopes.
### Custom Token Exchange
Some APIs use a non-standard token-exchange flow instead of OAuth or static keys. The API requires a workspace-level secret and one or more dynamic, per-request parameters (such as a user identifier) to mint a short-lived bearer token for each call. This pattern is common in healthcare platforms where each API call must be scoped to a specific end user or tenant, but the token issuance mechanism does not follow the OAuth specification.
The `custom_token_exchange` auth type handles this automatically. At configuration time, the operator provides the exchange endpoint URL, a workspace secret, and a mapping of which request parameters feed which exchange-call headers or body fields. At runtime, the connector mints a fresh bearer token from the workspace secret plus the per-request identifiers for each call.
Exchange URLs are validated at both configuration time and runtime to prevent requests from reaching internal networks, and secret templates are restricted to prevent injection.
### Vendor-Specific Adapters
Vendor-specific adapters handle the authentication, pagination, rate limits, and resource mappings implemented for that system. Confirm those capabilities against the actual source environment and operations required by the workflow. Sharing a FHIR representation does not make two adapters interchangeable.
The public Platform connector contract does not currently expose a general browser or computer-use tier. Systems without a supported API or adapter require a separately designed integration path; do not assume that file deduplication, source identity, or outbound authorization semantics transfer unchanged to portal automation.
### Handling External System Limitations
Checkpointed inbound polling can resume from committed source progress on a later poll. Outbound failures require the recovery procedure for that destination. Supported projections resolve competing observations using their source-ranking rules, but a higher-ranked record can still be stale or incomplete. Validate required fields, relationships, and freshness at the consuming workflow. Browser-only systems require a separately validated integration.
## Outbound Write-Back
When the connector receives an outbound event, source eligibility, test-event exclusion, and entity-type scope apply before unattended delivery or proposal staging. The unattended path also applies its confidence threshold. A review-configured destination stages an otherwise eligible event at any confidence instead of calling the target immediately. The connector uses the event payload rather than rereading the entity projection at delivery time.
Outbound mapping uses connector-specific payload transforms and deterministic matching rules. For example, supported insurance workflows can match a stated carrier against a practice payer list using aliases, substring matching, and bounded fuzzy matching. An unmatched or invalid value is reported according to the operation's failure behavior rather than sent through a model-based fallback.
### Outbound Authorization Paths
Unattended writes and human-reviewed writes use different authorization paths. A review decision is not an extra confidence gate: source and destination eligibility apply before staging, while approval of the specific proposal replaces the unattended confidence check at delivery.
| Check | Applies To | What It Checks |
| -------------------------------- | -------------------------------------- | -------------------------------------------------------------------------------------------------------------- |
| **Source eligibility** | Both paths, before staging or delivery | Is the event from an allowed source? Events originating from external sync are excluded to prevent echo loops. |
| **Confidence threshold** | Unattended writes | Does the event meet the destination's unattended write threshold? |
| **Human approval** | Review-gated writes | Did an authorized reviewer approve this specific payload and target? |
| **Schema and dependency checks** | Both paths | Are required fields, referenced entities, and operation prerequisites valid? |
| **External verification** | Supported operations | Does the target acknowledge the change or show it on read-back? |
On the unattended path, dependency checks can also apply confidence thresholds. For example, a patient dependency below the destination threshold is treated as failed rather than pending.
{% hint style="danger" %}
Conversation-derived data remains subject to the destination's outbound policy. Recording the patient's intent is not the same as confirming that the external system accepted a write.
{% endhint %}
### Delivery Failure Semantics
The standard automated write path reports a failed delivery but does not promise automatic reconciliation after a transient error. Human-approved proposals use a separate delivery policy: the active `fhir_store` sink can retry its idempotent writes, while other sink types receive at most one automatic vendor call. An ambiguous non-idempotent failure is left visible for investigation or manual reconciliation rather than retried automatically.
### Agent-Initiated Record Creation
An agent can invoke the patient-creation tool when the authored workflow has collected the required fields. That tool creates a workspace entity and emits a `patient.created` event. If outbound policy selects the event and the configured destination supports patient creation, the connector validates and submits the mapped payload. The connector does not independently discover a new patient or create a record without an initiating write.
## External Write Review
External write review is a private-preview connector path available only in enabled workspaces and environments. When an eligible event targets a destination configured to require review, the connector does not send the mutation immediately. It creates an [external write proposal](/data/review-queue) with the target, payload, entity, and provenance. An authorized reviewer approves or rejects that proposal, and only an approved proposal enters the separate delivery path. This review step is separate from world-model confidence scoring and does not intercept every integration call or world-model event.
## Entity Resolution
### Automatic External Identity Binding
An opted-in data source can create external-user bindings for eligible patients and guardians after their entities become available in the serving view. The binding lets a supported external identity resolve to the corresponding workspace entity at conversation start.
Binding runs through periodic reconciliation, not during the initial entity-resolution fold. An accepted source record or resolved identifier therefore does not mean that login recognition is ready immediately. Both projection and binding must complete.
**How it works:**
* The source explicitly enables automatic binding and identifies the external integration to use. Its canonical source identifier must yield the same subject key that the external application supplies at login.
* Reconciliation selects eligible, materialized person entities from that source within the workspace.
* It binds the source's external subject key to the resolved entity without substituting a display name or assuming that a medical-record number is the login key.
* Transient binding failures can be retried on a later pass. A key already bound to a different entity is left unchanged and reported for investigation.
This automatic path covers patient and guardian/caregiver records; practitioner records are excluded. It does not assign clinical roles or replace the separately configured external-principal authorization policy.
The feature is available only where the required serving data and identity integration are provisioned. Validate recognition with the actual external subject key before launching a workflow that depends on it.
Current FHIR entity resolution maps supported resource types and references to source-scoped identifiers. This keeps repeated events from the same source attached to the same entity and creates explicit FHIR-derived relationships between related resources.
The current Platform pipeline does not perform fuzzy patient matching or write new cross-source `same_as` merge edges. Existing graph and duplicate APIs can still return historical `same_as` edges created by an earlier resolver. Treat those records as historical evidence, not proof that active connectors currently merge people by phone, email, name, or date of birth.
Caller recognition is a separate path. Customer applications can use verified external-user bindings, and supported channel flows can use scoped identifiers such as a caller phone number. An unmatched caller remains anonymous until the workflow resolves or creates an entity explicitly.
## Outbound Dispatch
The connector system also handles scheduled outbound interactions. When the system needs to contact a patient, each outbound task carries the patient context, interaction purpose, and priority. The platform evaluates which tasks are due and initiates interactions with the relevant patient context pre-loaded.
Outbound tasks are stored as entities in the world model. They are created by scheduling rules, follow-up workflows, or manual triggers, and their projections track status, priority, attempt count, retry timing, and call outcome.
## Gap Scanner
The gap scanner proactively identifies missing data across entities and creates [surfaces](/channels/surfaces) to collect it. It checks entity state against configurable requirements (for example, "patients with upcoming appointments must have insurance information") and generates data collection forms for any gaps found.
Appointment detection reads current event state directly, so appointment updates such as cancellations and rescheduling are reflected without waiting for stale data to age out.
Gap scanning is configured per workspace through the Platform API. See [Surfaces - Automated Gap Detection](/channels/surfaces#automated-gap-detection) for details.
## Console Views
The Developer Console gives operations teams a visual layer over the connector pipeline described above.
### Data Sources Dashboard
The Developer Console Data Sources page provides an operational overview of all external systems feeding data into a workspace. The page opens with a visual pipeline summary showing three stages: source systems (clinical and operational connectors), the normalize-and-map layer (FHIR resources, file uploads, and unification rules), and the world model output that agents and operators consume.
Summary metrics display the number of connected sources, healthy connector count, and recent sync activity. The connected sources table shows individual connector status and recent event throughput.
### Facility Location Mapping
When location, facility, or place entities are synced from clinical systems, the Data Insights dashboard renders their geographic distribution on a live map. Entities with direct coordinates (latitude and longitude) are plotted immediately. Entities that carry street addresses but no coordinates are geocoded on demand. This gives operations teams a visual picture of facility coverage without requiring manual coordinate entry.
## Pipeline Observability
The connector system tracks operational health across data source connections. Operations teams get visibility into pipeline status without waiting for sync failures to surface.
| Metric | What It Tracks |
| -------------------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Overall status** | Whether the pipeline is healthy, degraded, or starting up |
| **Per-source sync health** | Recent sync time, duration, event count, errors, and connection status for each data source |
| **Pipeline states** | Current state of source polling, entity resolution, and outbound processing |
| **Connection health** | Consecutive error tracking per source - a source is marked unhealthy after repeated failures and recovers automatically on success |
### Data Source Freshness
Each data source connection reports a freshness category based on how recently it last ingested data:
| Category | Meaning |
| --------- | --------------------------------------------------------------------------------------------- |
| **Fresh** | Data arrived within the last five minutes. The source is actively producing events. |
| **Stale** | Last ingestion was between five and sixty minutes ago. The source may be experiencing delays. |
| **Quiet** | No data in over an hour. The source may be down, or there may simply be no new records. |
| **Never** | No data has ever been ingested from this source. |
Freshness is computed from the timestamp of the most recent ingested event, not from how recently the connector checked the source. A source with no new data therefore reports freshness based on the last event that actually arrived. This reflects whether data is flowing, not merely whether the connector is running.
Per-source ingestion rates (events per minute, per hour, and over the last 24 hours) give operations teams a quantitative view of throughput alongside the categorical freshness indicator.
### Sensing-to-Action Latency
Pipeline latency metrics describe the timestamps available to the instrumented path. They do not automatically include time between an upstream clinical event and its detection. For an end-to-end freshness claim, preserve the source event timestamp and verify each boundary through agent-visible state and the external outcome, as described in [HL7v2 Integration](/data/healthcare-interoperability#design-for-measured-freshness).
The latency distribution is presented as an hourly sparkline with count and median values. Use changes in that distribution to select periods for investigation, then inspect source health, processing failures, and workload. The shape of a latency chart alone does not identify the cause.
The Platform API exposes pipeline observability through read-only endpoints that power the pipeline dashboard: pipeline status, source listing with live health, source event history, outbound summaries, entity resolution metrics, and throughput time series. If live connector status is temporarily unavailable, stored event and source history remain distinguishable from live health data.
{% hint style="info" %}
Pipeline health data feeds the analytics dashboard. See [Data Quality Analytics](/intelligence-and-analytics/intelligence) for the dashboard metrics. For API endpoints and integration details, see the [Connector Runner](https://docs.amigo.ai/developer-guide/platform-api/data-world-model/connector-runner) and [FHIR](https://docs.amigo.ai/developer-guide/platform-api/data-world-model/fhir) sections of the developer guide.
{% endhint %}
# HL7v2 Integration
Scope HL7v2 ADT and SIU feeds and outbound hospital messages, with explicit direction, freshness, acknowledgment, and deployment evidence.
Hospital workflows can depend on HL7v2 event feeds for admission, discharge, patient updates, and scheduling changes. Scope these feeds alongside the supported FHIR and EHR integrations, with separate evidence for receiving events and sending changes back.
## Scope Each Interface Separately
| Interface | Intended role | Amigo readiness boundary |
| --------------------------- | --------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| HL7v2 inbound ADT | Patient administration events, including admissions, transfers, discharges, and demographic updates | A native HL7v2 receiver and its acknowledgment behavior have not been verified in the current supported connector contract. Requires an explicitly designed and validated integration. |
| HL7v2 inbound SIU | Scheduling notifications such as booking, rescheduling, modification, and cancellation | Requires a hospital-specific feed profile, identity mapping, freshness target, and reconciliation tests. An inbound notification is not permission to change a schedule. |
| HL7v2 outbound | Send a message accepted by the receiving hospital interface | A native HL7v2 sender has not been verified. Agree on the message family, trigger, direction, authorization, and application acknowledgment before committing to delivery. |
| FHIR APIs and notifications | Read or write supported resources; receive events where the server and adapter support them | Use the current [connector inventory](/data/connectors-and-ehr#connector-types). Resource, operation, authentication, subscription, and destination support vary independently. |
These are interface-level findings reviewed September 7, 2026, not deployment commitments. Confirm scope with the implementation owner before accepting an integration requirement.
HL7 defines ADT patient-administration events and SIU scheduling notifications separately. The receiver's supported version, trigger events, required segments, local extensions, and identifiers determine the actual contract. Receiving SIU notifications does not establish scheduling requests in the opposite direction. See [HL7 patient administration](https://www.hl7.eu/HL7v2x/v26/std26/ch03.html) and [HL7 scheduling](https://www.hl7.eu/HL7v2x/v251/std251/ch10.html).
## Design for Measured Freshness
For scheduling, start with the hospital's source of truth and the updates it can emit. Evaluate HL7v2 feeds, supported FHIR subscriptions, vendor notifications, and scheduled reads against the same end-to-end target. FHIR supports [event notifications](https://fhir.hl7.org/fhir/subscription.html); the format alone does not determine latency, and actual subscription support must be confirmed.
Measure source event time, receipt, durable acceptance, mapped record availability, agent-visible state, action submission, and target confirmation separately. Report percentile latency and outage recovery against agreed thresholds. A sync heartbeat or ingestion timestamp cannot prove how old the source event was when the agent acted.
## Qualify Inbound and Outbound Paths
Record these decisions in the [technical evaluation packet](/platform-overview/evaluation-packet):
1. **Feed scope:** originating and receiving systems, directions, HL7 version and profile, ADT/SIU triggers, and separately scoped order or result messages. Use synthetic messages and the hospital's interface specification.
2. **Transport and access:** approved transport, network boundary, authentication, encryption, credentials owner, and environments. MLLP framing alone does not establish a secure transport.
3. **Acceptance and failure:** acknowledgment of durable receipt, application acceptance or rejection, timeouts, replay authority, quarantine, and escalation ownership. The agreed [HL7 acknowledgment mode](https://www.hl7.eu/HL7v2x/v251/std251/ch02.html) determines which acknowledgment means what.
4. **Identity and ordering:** source-scoped patient, encounter, appointment, and message identifiers; duplicates; late and out-of-order events; corrections, cancellations, and identity changes. Preserve provenance through mapping.
5. **Outbound authority:** allowed operations and records, approvals, conflict detection, loop prevention, and receiving-application evidence. An acknowledgment is not automatically proof of a completed appointment change.
6. **Recovery:** retention, replay controls, metrics, downtime behavior, reconciliation procedures, and the evidence required after an interruption.
A hospital interface engine or integration partner can be evaluated as an adapter boundary. Its mapping fidelity, acknowledgment semantics, and Amigo handoff still require testing; selecting a partner is not a verified integration.
## Verify a Scheduling Outcome
Use a synthetic appointment to test create, reschedule, cancellation, and correction events. Repeat messages, deliver them out of order, interrupt the connection, and reject a malformed message. Verify the resulting appointment state and that the agent uses the current state without duplicating an external action.
Test an outbound change separately: obtain authorization, submit through the agreed receiving interface, capture its acknowledgment, and verify the authoritative appointment record. If the result is ambiguous, reconcile before retrying. Keep lab, blood-bank, and other clinical-result workflows outside the scheduling pilot until their message profiles and validation cases are separately agreed.
# Customer Data Intake
Workspace-scoped dataset ingestion, file versioning, source discovery, processing, and publication, with explicit security and rollout boundaries.
Amigo's current file-intake workflow uses registered datasets. It gives each upload a named contract, catalog status, and version history, with separate steps for processing and publication.
| Scenario | Supported workflow |
| --------------------------------------------------------------- | ------------------------------------- |
| An operator uploads a CSV snapshot against a defined schema | Authenticated dataset intake |
| A Google Drive folder should feed a registered dataset | Dataset intake source |
| A source exposes a stable API that Amigo should read repeatedly | [Connector](/data/connectors-and-ehr) |
| A person needs to complete a structured form | [Surfaces](/channels/surfaces) |
The Developer Console exposes dataset intake where the Intake feature is enabled. The former standalone upload-link system and external HMAC upload route have been retired; they are not current alternatives to dataset intake.
## Dataset Intake
Dataset intake is the governed path for files that need a named data contract, catalog status, and version history. Authenticated workspace routes let an operator register a dataset, upload or download files, list file status, and refresh a dataset from mapped sources.
### Dataset Contracts
Every dataset has one of two ingestion modes:
* **Snapshot** - A tabular contract with a primary key and typed fields. CSV is the current processing format. Although the registration contract also accepts `xls` and `xlsx` type tokens, the current snapshot validators and processor read CSV bytes; use CSV for processing workflows.
* **Document** - A set of accepted filename extensions plus a document-processing configuration. The current native text extractor supports PDF, DOCX, and UTF-8 text such as Markdown. `OCR` and `hybrid` are accepted configuration values but are not current processing implementations and result in a failed processing verdict.
Registering a file type does not prove that a downstream processor can interpret every file with that extension. Validate representative files before production use.
### Upload and Version Behavior
An authenticated upload is associated with one registered dataset and is capped at 100 MB. Dataset contracts can record `max_size_mb`, but the current upload runtime does not enforce a lower per-dataset value; clients that rely on it must enforce it before upload. The service computes a content hash and returns an existing row for a byte-identical file already present in the same workspace and dataset.
Snapshot versions are allocated at the dataset level. Document versions belong to a logical document: omit `document_id` to create a document, or provide an existing `document_id` to add a same-type version.
Processing is configuration-dependent:
* Snapshot uploads can be validated synchronously or land as `received` for asynchronous processing.
* Document uploads land as `received` and require the document processor to reach a terminal status.
* A successful upload response confirms storage and cataloging, not successful parsing, publication, or world-model projection.
The current intake path does not perform inline malware scanning. An allowlisted extension, MIME type, or successful schema check is not evidence that a file is safe. Workflows that require a malware verdict must arrange that control before submission.
### Google Drive Sources
A dataset source maps one or more Google Drive folders to registered datasets. Discovery occurs when an operator triggers a source sync or starts a dataset update; registration alone does not schedule continuous synchronization.
A source sync creates a batch per mapped folder, downloads eligible files, and places newly landed files in the dataset catalog. Unchanged content is deduplicated. Processing a batch is a separate step unless the dataset-update workflow orchestrates it.
The dataset-update endpoint combines source discovery, preparation, and publication behind a durable run. It applies only when an active Drive source maps to the requested dataset. Monitor the returned run rather than assuming that `202 Accepted` means the dataset is ready.
## Retired Intake Paths
Standalone shareable upload links and the external HMAC upload route have been removed. Existing integration instructions for those paths need migration to authenticated dataset intake or a separately agreed collection workflow. Patient-facing [Surfaces](/channels/surfaces) remain a distinct form workflow; a form submission does not automatically create a dataset file.
## Security and Compliance Boundaries
* Dataset, source, listing, upload, and download operations require a workspace-scoped Platform credential.
* Content-type checks, schema validation, malware scanning, parsing, and downstream publication are distinct controls. Success at one stage does not imply success at another.
* The intake routes do not, by themselves, establish a HIPAA or HITRUST compliance posture. Deployment controls, contractual coverage, retention, residency, and operating procedures remain separate concerns. See [Compliance and Audit](/operations-and-safety/compliance) and [Data Residency](/platform-overview/data-residency).
For endpoint-level request and response behavior, see the [Platform intake guide](https://docs.amigo.ai/developer-guide/platform-api/data-world-model/intake).
# Workspaces
Tenant isolation boundaries with separate world models, data sources, voice configs, and role-based access control.
A workspace is the tenant boundary in the Amigo platform. Each workspace has its own world model, connected data sources, agent and service configurations, and access settings. Public data access is authenticated and scoped to the selected workspace.
## Tenant Isolation
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart TB
subgraph WA["Workspace A"]
WMA[World Model] --- SA[Services]
SA --- PA[Phone Numbers]
PA --- DA[Data Sources]
end
subgraph WB["Workspace B"]
WMB[World Model] --- SB[Services]
SB --- PB[Phone Numbers]
PB --- DB[Data Sources]
end
WA ~~~ WB
style WA fill:#FDFCFB,stroke:#D7D2D0
style WB fill:#FDFCFB,stroke:#D7D2D0
```
Each workspace is an isolated organizational boundary. This means:
* Workspace-scoped event reads do not expose another workspace's events
* Entity projections are computed per-workspace
* Phone numbers, services, and context graphs are scoped to a workspace
* API keys authenticate to a specific workspace
### Layered Isolation
Public requests authenticate a workspace identity, validate that referenced resources belong to that workspace, and scope supported reads and writes to the same tenant. Data services add storage-level controls where appropriate, while audit records retain workspace and actor attribution.
Some trusted platform workers intentionally process more than one workspace, such as schedulers and connector workers. Those paths use service credentials and preserve explicit workspace scope; they are not public unscoped access. Treat isolation as a layered authorization contract rather than assuming every table uses one identical enforcement mechanism.
For healthcare organizations, this isolation model supports multi-site deployments where each clinic, department, or practice operates as its own workspace with its own data and configuration. A hospital system with five clinics can run five workspaces, each with its own EHR connector, phone numbers, and scheduling logic.
## API Keys and Permissions
API access is scoped to an account within a workspace. Each account has a role that determines what it can do:
| Role | Capabilities |
| ------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Owner** | Admin permissions plus the ability to create owner-role API keys. |
| **Admin** | Can update and delete workspace resources, manage members and API keys, query privileged analytics, view audit data, and delete a workspace. |
| **Member** | Read access plus supported resource creation, clinical data writes, outbound conversation starts, channel sends, and trigger management. |
| **Operator** | View access plus operator actions: monitor and take over eligible runs, send guidance, author supported text turns, and claim or decide external write proposals where the private-preview review flow is enabled. |
| **Viewer** | Read-only access. Can view configurations, data, and call records but cannot modify anything. |
When creating an API key, the caller selects a role and may optionally narrow it to a subset of that role's permissions. The requested role and permissions cannot exceed the creator's own access, and only an owner can create an owner-role key.
## Environment Separation
{% hint style="warning" %}
Never test agent behavior changes directly in a production workspace. Use staging workspaces to validate changes before promoting them to production.
{% endhint %}
Use separate workspaces for different regions and stages of delivery:
| Environment | Purpose |
| --------------- | ------------------------------------------------------------------------------------------------------------------------- |
| **Production** | Live workloads and production integrations. |
| **Staging** | Pre-production testing with production-like configuration. |
| **Development** | Building and testing new context graphs, skills, and integrations, typically with synthetic data or sandbox integrations. |
This separation ensures that changes to agent behavior, safety rules, or data integrations can be tested in staging before they affect real patient interactions in production.
The current Platform API does not expose workspace environment conversion or an editable environment label. Production, staging, and development describe how the team uses and provisions its separate workspaces. Confirm the actual session, data-access, retention, and integration policies for each deployment; naming a workspace staging or production does not change those controls.
## Optional Data Exposure
Workspace administrators can request two separate capabilities: topic modeling and Delta Sharing. Both are disabled by default. Topic modeling enables eligible classification and its provisioned data views. Delta Sharing exposes the selected workspace datasets to a configured recipient; it is not permission to browse other workspaces or a copy of every internal table.
Delta Sharing supports an open-sharing recipient or a Databricks recipient identified by its sharing identifier. Confirm the selected mode and recipient during provisioning. Saving the setting and applying the underlying grants are separate steps, so verify provisioning and recipient access before consuming data.
Disabling exposure or changing an active recipient requests access reconciliation. If that request cannot be queued, the API reports a failure even though the setting was saved. Retry and verify that access was revoked; do not treat the stored flag alone as proof of revocation. Previously downloaded data remains subject to the recipient's own handling policy.
See [Delta Sharing](https://docs.amigo.ai/developer-guide/classic-api/data-access/delta-sharing) for the supported setup and consumption workflow.
## What Lives in a Workspace
A workspace contains all the resources needed to run a deployment:
* **Services** - Define which context graph and agent configuration handle calls
* **Phone numbers** - Routed to services within the workspace
* **Data sources** - Configured EHR, FHIR, database, file, and API integrations plus connector runner settings
* **World model** - The event store and entity projections for this workspace
* **Agent configuration** - Authored behavior, context graphs, models, functions, and channel-specific settings
* **Voice settings** - TTS voice selection, speed, keyterm lists, sensitive topic configuration
* **Operator configuration** - Which operators can join calls and how escalation works
* **Security settings** - Optional workspace-level security controls and access policies
{% hint style="info" %}
**Developer Guide** - For API endpoints, SDK examples, and integration details, see the [Workspaces](https://docs.amigo.ai/developer-guide/platform-api/workspaces) section of the developer guide.
{% endhint %}
# Review Queue
Human approval workflow for proposed writes to external clinical systems, with explicit decisions, delivery status, and audit history.
{% hint style="warning" %}
External write approvals are currently in private preview and available only in enabled workspaces and environments. Contact your Amigo representative before designing a production workflow around this capability.
{% endhint %}
The Review Queue governs eligible connector write-back events for destinations configured to require human approval. Instead of sending the write immediately, the platform stages an external write proposal with the target, proposed change, and origin context. The preview does not intercept every integration tool call or every world-model event.
This workflow is separate from world-model confidence scoring. Source and destination eligibility apply before a proposal is staged, but an eligible event can be staged at any confidence. Reviewers decide whether that specific external mutation may proceed; they do not edit event confidence or rewrite the underlying world-model history.
## How It Works
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
A["Eligible connector\nwrite-back event"] --> P["Proposal staged\nwith provenance"]
P --> R{"Human review"}
R -->|Approve| D["Deliver to\ntarget system"]
R -->|Reject| X["Record decision\nwithout delivery"]
D --> S["Record delivery\noutcome"]
```
1. A source-eligible outbound event targets a connector destination configured to require review.
2. The platform stages a proposal instead of calling the target system.
3. An authorized reviewer inspects the proposal and approves or rejects it.
4. Approved proposals enter the delivery path. Rejected proposals remain closed with the reviewer's reason.
5. The proposal records the final delivery outcome for audit and follow-up.
## What Reviewers See
A proposal gives the reviewer enough context to make a decision:
* The target connector and clinical resource type
* The proposed payload and affected entity
* The originating world event and, when populated, run context
* Confidence and provenance information supplied by the originating workflow
* Current review and delivery status
* Prior decision, delivery attempts, or failure details
Proposed payloads may contain protected health information. Access is workspace-scoped and permission-gated.
## Proposal Lifecycle
| Status | Meaning |
| -------------- | ---------------------------------------------------------------------------------------- |
| **Proposed** | Awaiting a reviewer decision. |
| **Approved** | Approved and waiting for delivery. |
| **Rejected** | Rejected by a reviewer and never delivered. |
| **Pushing** | Delivery is currently in progress. |
| **Pushed** | Delivered successfully to the target system. |
| **Failed** | Delivery did not succeed within the permitted attempt policy. |
| **Superseded** | Retired or replaced before completion and no longer eligible for a decision or delivery. |
Only a proposal in **Proposed** status can be approved or rejected. If two reviewers act at the same time, the first valid decision wins and the other reviewer is asked to reload the current state.
## Review Decisions
Reviewers have two actions:
* **Approve** - Authorize the proposed payload for delivery.
* **Reject** - Block delivery and record a required reason.
The current proposal workflow does not provide a Correct action. If the payload needs to change, reject the current proposal and have the originating workflow create a new one so the audit trail preserves both records.
## Delivery Safety
Approved proposals use a delivery policy matched to the connector type:
* **The active FHIR sink** (`fhir_store`) use idempotent write behavior and can retry up to the proposal's attempt limit.
* **Other sinks** receive at most one automatic vendor call. After an ambiguous failure or a crash during delivery, the proposal fails visibly rather than risking a duplicate booking, cancellation, or creation.
This favors a visible, recoverable under-delivery over a silent duplicate clinical mutation. Failed proposals retain their error state for investigation.
**Pushed** means the destination handler completed without reporting an error and the proposal was marked delivered. A read-back is operation-specific, not universal; verify destination state when the workflow requires end-to-end confirmation.
## Audit and Access Control
Approval and rejection use the authenticated reviewer's identity. Each decision is audit-logged with the proposal, target type, action, and reviewer attribution. The proposed payload is not copied into audit log entries.
Read and decision permissions are separate, allowing organizations to give some users queue visibility without authority to approve clinical writes.
{% hint style="info" %}
For endpoint details and permissions, see [Review Queue](https://docs.amigo.ai/developer-guide/platform-api/integrations/review-queue) in the developer guide. For the surrounding data flow, see [Connectors and EHR](/data/connectors-and-ehr).
{% endhint %}
# Data Access (MCP)
Standalone MCP service for read-only SQL exploration using Classic API organization credentials.
{% hint style="info" %}
**Choose the surface that matches the caller.** Use [platform functions](/agent/platform-functions) when an agent needs data during a conversation. For external clients using Platform API workspace credentials, use the [Platform API MCP server](https://docs.amigo.ai/developer-guide/platform-api/functions/mcp-server). This page describes Data-MCP, a separate service for integrations that use Classic API organization credentials.
{% endhint %}
Data-MCP is an active, standalone Model Context Protocol service for exploring data through read-only SQL tools. It uses MCP Streamable HTTP and can be used by compatible MCP clients.
## Scope and Authentication
Data-MCP uses the Classic API organization model. A connection supplies an organization ID plus either a pre-exchanged bearer token or the complete Classic API key credential set. Queries run through the Classic API under that organization and credential context.
This contract is different from the Platform API MCP server, which uses Platform API credentials and an explicit workspace ID. Do not send a Platform API workspace header to Data-MCP or assume that credentials can be exchanged between the two services.
Data-MCP is not scoped to an individual end user inside an application. When clinicians or other external users require role-specific access, use an [external-principal](/operations-and-safety/compliance#external-principals) agent session or another application authorization layer rather than sharing a broad MCP credential.
## Available Tools
Data-MCP exposes seven tools:
| Tool | What It Does |
| ------------------- | ------------------------------------------------------------------------------------------------------- |
| **sql\_query** | Run a read-only SQL query. Results are limited to 1,000 rows and the query has a 30-second timeout. |
| **describe\_query** | Return the output columns and types a query would produce without running the query itself. |
| **tables** | List accessible tables, optionally filtered by a name pattern. |
| **table\_schema** | Return columns, types, and available descriptions for a table. |
| **sample\_data** | Preview a bounded number of rows from a table. |
| **table\_detail** | Return available table statistics, properties, partitioning, and freshness metadata. |
| **profile\_column** | Summarize a column's cardinality, null rate, value range, and distribution where supported by its type. |
The service also exposes a data-catalog resource that helps clients discover table definitions and query guidance.
## Read-Only Boundary
The SQL execution tool accepts read-only `SELECT` queries. It is intended for exploration and analysis, not for creating tables or changing application data. Use the appropriate Platform API write endpoint, platform function, or configured integration for mutations.
Tool output reflects the tables visible to the supplied Classic API credential and the freshness of the underlying analytical data. A successful query is not evidence that every source system is current or that the result is appropriate for a particular end user.
## Regional Use
Data-MCP has regional deployments. Use the deployment and Classic API backend that correspond to the organization whose data you are querying. The service can accept an allowlisted backend override, so endpoint selection remains part of the client's residency configuration rather than an automatic global-routing guarantee.
For connection headers, endpoint URLs, and examples, see the [Data-MCP developer guide](https://docs.amigo.ai/developer-guide/platform-api/data-world-model/data-mcp).
# Agent Core
Versioned agent identity, background, behavioral guidance, communication patterns, and voice configuration.
An agent version defines the identity and authored guidance that the runtime supplies to the model. It includes an identity object, background text, behavioral guidance, communication patterns, and optional voice configuration. These fields steer model behavior; they are not hard authorization or deterministic policy controls.
For a first read, separate the agent's general guidance from the [Context Graph's](/agent/context-graphs) workflow and the service configuration that deploys both. [Core Concepts](/platform-overview/core-concepts#configuration-what-a-service-deploys) shows that relationship. This page then explains what belongs in the agent version and how to review it.
## Agent as Interpretive Framework
The agent gives the model a domain-specific frame for interpreting the current conversation and available context. Two agents can respond differently to the same evidence because their identity, background, and guidance emphasize different responsibilities and boundaries.
The agent guidance serves three purposes:
1. **Interpretation.** Background and behavioral guidance help the model decide which available facts matter to the current task.
2. **Workflow behavior.** Agent guidance combines with the active Context Graph state, tools, and channel policy when the runtime generates a response or chooses a modeled action.
3. **Communication.** Identity and communication patterns shape language, tone, and professional boundaries across supported channels.
## Core Components
The Platform API stores an agent as a named parent resource and its immutable versions as configuration snapshots.
* **Identity** - Structured persona fields such as name, role, language, and developer attribution.
* **Background** - Bounded text describing relevant domain context, expertise, and operating stance.
* **Behaviors** - Authored rules and priorities for what the agent should or should not do.
* **Communication patterns** - Authored guidance for tone, wording, and response style.
* **Voice configuration** - An optional voice selection for speech output.
The retired standalone Platform persona resource is not part of this model. Identity is embedded in each agent version, and services resolve the selected agent version through their version-set configuration.
### Persona: Two Layers
Authors commonly divide persona content into two conceptual layers:
* **Identity layer** - Structured attributes such as name, role, and default language.
* **Background layer** - Domain context, expertise, biography, and guiding principles stored in the version's background text.
The API bounds the background field by characters, not tokens. Keep it focused enough for reviewers to understand which guidance belongs globally and which belongs in a specific Context Graph state.
### Behavioral vs. Communication Guidance
The current agent-version schema separates two categories:
* **Behavioral guidance** describes intended scope and priorities, such as refusing to create meal plans or routing medical questions to an approved clinical workflow.
* **Communication patterns** describe expression, such as tone, spelling conventions, sentence structure, and prohibited phrases.
The distinction keeps operating boundaries separate from presentation style. Both are model instructions. Enforce permissions, data access, and external mutations with server-side authorization, tool exposure, validation, and approval policy rather than relying on these fields alone.
## How the Agent Core Connects to Other Systems
The selected agent version contributes to the runtime prompt alongside other components:
* [Functional Memory](/agent/memory) and world-model enrichment can supply selected cross-session context.
* The active [Context Graph](/agent/context-graphs) supplies state-specific objectives, boundaries, exits, and tool bindings.
* The service and channel determine runtime capabilities, transport behavior, and additional tool exposure.
* Server-side authorization and tool validation determine which operations can actually execute.
Agent versions and Context Graph versions have separate lifecycles. A version set can pin each independently; memory and world-model state are data inputs rather than artifacts versioned with the agent.
## Designing an Agent Core
Put guidance that applies across workflows in the agent version. Put workflow-specific objectives, boundaries, exits, and tool access in the Context Graph states where reviewers can inspect and test them.
A practical process looks like this:
1. **Interview domain experts.** Capture how they assess severity, personalize guidance, and escalate edge cases.
2. **Translate heuristics into directives.** Express their rules in precise language a model can follow and an auditor can review.
3. **Separate prompt guidance from controls.** Define authored boundaries, then implement enforceable authorization, validation, approval, and escalation paths where required.
4. **Validate with simulations.** Run representative scenarios to confirm the identity behaves as intended before exposing it to users.
## Success Criteria
A well-designed agent version aims for the following traits in representative testing:
* **Appropriate voice and judgment** across the scenarios the team has exercised.
* **Escalation behavior** that matches documented policy in the evaluated cases.
* **Clear boundaries** for permitted work, with a tested handoff when a person must take responsibility.
* **Reviewable configuration** that separates global agent guidance from state, tool, and channel controls.
If observed behavior diverges from the authored agent fields, inspect the Context Graph, state guidance, available tools, memory inputs, runtime, and channel-specific policy.
{% hint style="info" %}
**Related sections** - See [Context Graphs](/agent/context-graphs) for how the agent navigates problem spaces and [Functional Memory](/agent/memory) for bounded cross-session context. Classic API users can also review [Dynamic Behaviors](/agent/context-graphs/dynamic-behaviors), a Classic-only adaptation mechanism.
{% endhint %}
{% hint style="success" %}
**For developers:** See [Agents](https://docs.amigo.ai/developer-guide/platform-api/workspaces/agents) for the current Platform API fields, versioning behavior, and examples.
{% endhint %}
# Reasoning Engine
How agent guidance, Context Graphs, tools, and channel controls coordinate reasoning, ongoing work, and responses across supported interactions.
The reasoning engine combines an agent's guidance, a Context Graph's problem definition, and available evidence to decide what to do next. It can navigate a workflow, invoke tools, use their results, and continue without requiring another user message. Supported voice, text, simulation, and API interactions share these reasoning capabilities; channel adapters handle audio streaming, message delivery, and connection lifecycle.
## Why a Unified Engine Matters
A workflow's objective can stay the same across channels even when its interaction changes. An availability lookup may support a spoken conversation or an asynchronous message. The agent still needs to interpret the request, use the permitted tools, and explain their result, while each channel handles waiting, interruption, and delivery differently.
Amigo separates reusable agent and problem definitions from those channel concerns. Teams can change workflow guidance without rebuilding audio transport, or add a supported channel while retaining the same authored objectives. Each channel still needs its own validation.
## What the Designer Controls
Agent and Context Graph definitions are declarative assets: they describe the intended behavior and can be versioned, reviewed, and evaluated together.
| Part | Designer specifies | Role during execution |
| -------------------------------- | -------------------------------------------------------------------------- | ----------------------------------------------------------------------- |
| **Agent** | Role, communication style, and general guidance | Gives the model a consistent perspective for interpreting the task |
| **Context Graph** | Objectives, states, transitions, and state-specific instructions | Defines the problem and the paths available for addressing it |
| **Tool binding** | Eligible operations, execution timing, result delivery, and retention | Connects a state's work to the tools and result-handling rules it needs |
| **Service and runtime controls** | Channel settings, authorization, validation, and supported safety behavior | Apply the operating boundaries for that deployment |
Use model judgment where interpretation is useful, such as understanding a request or explaining available options. Put requirements that must block an operation into the corresponding authorization, validation, or supported approval boundary. A state instruction to obtain confirmation guides the agent; an enforced confirmation requirement also needs a tool or approval check that rejects execution without it.
This lets a workflow vary how much judgment each step allows. It does not make model-backed navigation or responses deterministic. See [Context Graphs](/agent/context-graphs) and [Runtime Safety](/operations-and-safety/runtime-safety) for the specific controls.
## Cut, Navigate, Engage
Amigo uses three operations to coordinate the voice timeline and signal-driven text flow:
1. **Cut** - Decide whether an incoming signal creates a boundary in the current interaction phase.
2. **Navigate** - Select the next context-graph state or channel-level unit of work from the current session state.
3. **Engage** - Carry out that selection by generating a response, executing tools, scheduling a deadline, or delivering channel output.
The operations appear at more than one layer:
| Scale | Cut | Navigate | Engage |
| ------------------ | -------------------------------------------------- | ------------------------------------------------------------ | -------------------------------------------- |
| **Conversation** | A user turn or qualifying event prompts evaluation | Select a path through the context graph | Generate a response and execute tools |
| **Voice timeline** | A timing or session signal creates a boundary | Select breath, filler, hold, response, or listening behavior | Schedule or play the selected audio behavior |
| **Text flow** | A queued message or event becomes the next item | Run the shared reasoning path | Deliver or persist the resulting effects |
This coordination keeps fillers, silence handling, empathy pauses, tool progress narration, and barge-in recovery on one voice timeline. The [voice timeline](/channels/voice/audio-pipeline#voice-timeline) describes how it operates within each turn.
The [Universal Reasoning Harness design direction](#design-direction-universal-reasoning-harness) extends this coordination to longer-running and non-conversational work. Its broader context and scheduling contract is distinct from the current channel-specific operations described here.
## Signals and Effects
The engine communicates through two primitives.
**Signals** represent something that happened. Supported adapters normalize relevant input into typed signals before it enters the shared flow:
| Signal | What It Represents |
| ------------------ | ----------------------------------------------------------------------------- |
| **Utterance** | The caller or user said something (text, from any source) |
| **Emotion** | An emotional state update from acoustic or transcript analysis when enabled |
| **Tool result** | A tool execution completed with a result |
| **Silence** | The caller has been silent beyond the configured threshold |
| **Barge-in** | The caller interrupted the agent mid-speech |
| **External event** | An injected event from an operator, surface submission, or external system |
| **System** | A system-level event such as a timeout, connection change, or error condition |
**Effects** represent something the engine wants to happen. The modality adapter decides how to execute each one:
| Effect | Voice | SMS | Simulation |
| -------------- | -------------------------------------------------------- | ----------------------- | -------------------------------------------------- |
| **Respond** | Stream the generated response through the voice pipeline | Send as an SMS message | Capture as simulation output |
| **Filler** | Play filler audio ("Let me check on that...") | No-op | No-op |
| **Pause** | Hold deliberate silence | No caller-facing output | Capture the effect when applicable |
| **Tool call** | Execute tool, feed result back as signal | Same | Same real tool path, with simulation-tagged writes |
| **Terminate** | Hang up after final speech | End session | Return final state |
| **Transition** | Records a state change; no caller-facing output | Same | Capture in trace log |
| **Observe** | Emits an analytics event; no caller-facing output | Same | Capture in trace log |
## The Pipeline
The interaction can be understood through three stages. A signal can update context or control the channel without requiring a new model response; for example, an emotion update can inform later speech, while barge-in can interrupt playback.
**Perceive.** The modality adapter converts raw input into typed signals. A voice adapter produces utterance signals from speech-to-text and emotion signals from prosody analysis. An SMS adapter produces utterance signals from message text. A simulation adapter injects both from test parameters.
**Reason.** The engine's core loop implements cut/navigate/engage at the conversation level:
1. **Navigate** - The context graph engine determines the current state, evaluates transition conditions, and selects the appropriate action.
2. **Engage** - The response generation model produces a reply, drawing on the agent's persona, current state guidance, selected memory, patient data from the world model, and the emotional context described below.
3. **Execute** - If the model calls tools, the engine executes them, feeds results back as tool result signals, and re-engages. This loop continues until a final text response is produced.
**Act.** The engine emits effects. The modality adapter executes each one according to channel capabilities. For voice, the [voice timeline](/channels/voice/audio-pipeline#voice-timeline) applies cut/navigate/engage within each turn to coordinate fillers, empathy pauses, and tool progress narration - the same three operations at a smaller scale.
The engine supports two processing styles. **Streaming mode** lets the voice adapter begin response generation and speech delivery without waiting for a complete text response. **Completed-effect mode** lets text, simulation, and API consumers receive materialized effects. Both use the shared navigation and tool-execution contract, while voice-specific timing and acoustic adaptation remain in the voice path.
Filler handling is channel-aware. Voice can play a short acknowledgement while work continues. Asynchronous messaging channels suppress voice-style filler and deliver results through their channel-specific completion flow. See [Email](/channels/email#long-running-tools-and-reply-delivery) for a non-live example.
Navigation can also be re-evaluated after a successful tool result rather than waiting for another user message. This occurs only for tool bindings configured for completion-gated navigation; the navigator may remain in the current state or select another valid state. See [Action State Extensions](/agent/context-graphs#action-state-extensions).
## Emotional Adaptation
When a voice session has usable emotion data, the engine can add that context through two paths. Simulations may also supply emotion signals for testing, but ordinary text messages do not produce acoustic evidence.
**Per-message annotations.** When acoustic evidence is available, the user message can retain the current detected emotion and valence alongside its transcript. These annotations are model-derived signals, not verified statements about the caller's internal state.
**Session-level steering.** Once the voice runtime has enough evidence, it can add a rolling summary to response prompts:
* **Dominant emotion and trend** - Is the caller improving, stable, or deteriorating?
* **Adaptation instructions** - Targeted guidance based on the caller's emotional quadrant (high-arousal negative callers need de-escalation; low-arousal negative callers need patience)
* **Behavioral signals** - Patterns like repeated interruptions, short response streaks, or extended silences that indicate disengagement or frustration independent of vocal emotion
* **Call-phase urgency** - After extended calls with deteriorating mood, the engine instructs the model to become more direct and resolution-focused
* **Coherence warnings** - When what the caller says and how they sound disagree, the engine flags the ambiguity so the model does not over-commit to a single interpretation
The combination gives the response model recent evidence and adaptation guidance. It does not make emotion classification definitive, and safety or clinical decisions should not rely on emotion inference alone.
## Per-State Configuration (TurnPolicy)
Each context graph state can configure the pipeline independently. A medication verification state behaves differently than a general scheduling state - not because the reasoning logic changes, but because the state's turn policy tunes the pipeline for that context.
Five areas are configurable per state:
* **Barge-in** - Enable or disable caller interruptions for the active state. The service's minimum speech duration applies during the greeting as well as later responses; there is no separate greeting-shield duration. A quick-answer state can keep barge-in enabled for faster turn-taking.
* **Safety response** - What happens when a safety rule fires. Options: stay in the conversation and respond with empathy, suspend the agent and route to an operator, or log an alert without interrupting.
* **Context strategy** - Choose full history or compact past state groups. A per-state threshold can activate compaction, and the engine can also ratchet to compact mode when prompt usage approaches the configured context limit.
* **Tool controls** - The state defines its actions. Turn policy can additionally block call forwarding entirely or after a configured number of turns.
* **STT sensitivity** (voice only) - End-of-turn thresholds and silence timeouts. Data collection states use higher thresholds and longer timeouts because callers pause between pieces of information. Quick-answer states use lower thresholds for faster responses.
## Model Configuration
The platform supports separate model preferences for navigation and engagement. Navigation selects a path through the context graph; engagement handles tool calling and response generation. Configuring them independently lets teams tune cost, latency, and response quality, but model-backed navigation is not inherently deterministic.
## Graceful Degradation
Selected failure paths have bounded fallbacks so an optional subsystem or a single model timeout does not automatically end a session.
| Component | Failure | Fallback |
| --------------------- | ------------------------------------------------------ | ------------------------------------------------------------------------------ |
| **Emotion detection** | Connection failure or repeated receive errors | Continues without new emotion-derived steering |
| **Navigation model** | Timeout or unavailable configured model | Tries a configured fallback; otherwise remains in the current engageable state |
| **Context pressure** | Estimated prompt usage approaches the configured limit | Compacts past state groups and caps retained history |
These paths reduce failure propagation, but they are not a zero-failure guarantee. Transport loss, exhausted fallbacks, session limits, or failures in required dependencies can still interrupt or end an interaction.
## Voice Control Plane
Voice calls combine service, agent, workspace, and environment settings that control vocal identity and delivery. They do not use one universal override hierarchy. Each field family has its own resolution rule.
| Setting Family | Resolution |
| ---------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Service pipeline tuning** | A service value applies when set; otherwise the field uses its documented runtime default or supported fallback |
| **Session provider** | Service, then agent, then environment |
| **TTS provider** | Service, then agent, then workspace, then environment. Per-language maps check the exact language, base language, and `multilingual` key, with service, agent, and workspace precedence within each key |
| **TTS provider configuration and model** | Workspace provider configuration forms the base, then agent and service configuration override it. A service model is the final model override; unresolved values use the environment configuration. A selected per-language entry can replace the merged base provider configuration |
| **Workspace voice settings** | Provide voice identity, tone, speed, volume, language, domain vocabulary, sensitive topics, and other workspace baselines for the fields that consult them |
| **Per-state `TurnPolicy`** | Controls separate state behavior such as STT sensitivity, barge-in, safety response, and context strategy; it is not another provider-inheritance tier |
When the emotion system has usable evidence, it can derive a turn-level delivery tone and prompt guidance. Navigation can select a turn-specific tone, an explicit workspace tone can take precedence over computed voice context, and provider defaults apply when no turn tone is available. This tone choice is separate from provider and TTS configuration resolution. See [Emotion Detection](/channels/voice/emotion-detection) and the [Audio Pipeline](/channels/voice/audio-pipeline).
## Concurrency
User input, reasoning, tool execution, and delivery can overlap. A caller can correct a request while a lookup is running, and a tool can finish after the agent has stopped speaking. Receiving information, continuing reasoning, and delivering a response are separate decisions.
Supported runtimes coordinate accepted interaction work while tools and background tasks can run independently. A tool binding separately controls whether work blocks or runs in the background, how success and failure return to the interaction, and how results are retained. Lifecycle support differs by modality; see [Tool Dispatch Configuration](/agent/context-graphs#tool-dispatch-configuration).
For example, with a voice lookup configured for background execution and interrupt delivery:
1. The caller asks for Friday's availability and the agent starts the lookup.
2. The voice runtime manages waiting and any configured progress speech while the lookup runs.
3. When the result is ready and continuation is permitted, the agent can present the options without another user message.
4. If the caller changes the request, the new input can interrupt speech and start another reasoning step. The completed lookup and whether to speak about it remain separate; continuation checks account for newer input and pending transcription, but do not establish universal rejection of every stale result.
With several outstanding voice tools, the current continuation path waits for the last completion before considering an automatic response. Earlier results can be recorded without generating separate responses.
Interrupting speech does not undo a tool's completed action. Requesting cancellation is also different from confirming that work stopped. For an external write with an uncertain outcome, use the operation's acknowledgement or supported read-back before deciding whether to retry.
Voice coordinates fillers, responses, empathy pauses, and progress narration on one timeline. Text uses its supported conversation and background-result lifecycle. These controls do not promise identical delivery timing, recovery of every in-flight task, or bit-exact replay across channels. See [Text Sessions](/channels/text-sessions) and the [Voice Timeline](/channels/voice/audio-pipeline#voice-timeline).
## Design Direction: Universal Reasoning Harness
The proposed harness extends the shared reasoning contract to work whose input, reasoning, actions, and delivery have independent lifetimes. An external record update could lead to background work and an observed outcome without a conversational reply. The design retains declarative agent and problem definitions while making dependencies, context validity, and ownership of ongoing work explicit.
Current implementations provide the channel behavior described above. Full execution ownership, background behavior selection, and general evidence-preload support are proposed extensions; their presence in this design does not establish support in every runtime or deployment.
### Capture Context, Decide, and Accept Work
| Step | Purpose in the proposed harness |
| ----------- | ------------------------------------------------------------------------------------------------------------- |
| **Cut** | Capture a bounded selection of relevant context while new signals can continue to arrive |
| **Reason** | Interpret that context using the agent and problem definition, through deterministic rules or model reasoning |
| **Enqueue** | Accept intended work with priority, dependencies, and conditions under which it remains valid |
A signal supplies information; the harness decides whether that information requires work. A cut creates a context boundary and need not interrupt current activity. Interruption or invalidation becomes necessary when changed assumptions affect unfinished work. Priority orders work that is eligible to proceed; it cannot satisfy a missing prerequisite or grant permission.
The design calls the bounded context used for interpretation a *quantum*. Its scope follows the task. Smaller units allow earlier reconsideration but can add overhead and discarded reasoning; larger units preserve more continuity but can leave more work to reconsider after a correction.
One execution owner would accept changes to state and scheduling. Concurrent workers would return proposed guidance, results, or outcomes for that owner to check. The owner would check relevance when accepting a result and again before releasing dependent work, while remaining responsive to control signals during long model requests.
For example, a Friday behavior selection that finishes after the request has changed to Monday must not restore Friday's instructions merely because it completed last. The proposed acceptance checks generalize the narrower voice continuation checks above. Replacement of an execution owner must also prevent the previous owner from continuing to accept changes.
### Background Guidance and Required Evidence
The proposed background selector would compute behavior guidance against captured context while other eligible work continues. Advisory guidance could be adopted at a later reasoning boundary. If an action or response requires a selection, that dependency would hold the affected work until selection succeeds or the defined fallback resolves it. Mandatory constraints remain enforced while selection is pending or fails.
The same distinction applies to [memory and required evidence](/agent/memory#context-required-by-a-task). Loading information early can reduce waiting, while required evidence gates the decision that uses it. New contradictions or missing facts can trigger additional authorized retrieval even when they were absent from the initial context declaration.
A model request already in flight has received its context. Accepting new guidance means using it in a later request or cancelling and regenerating unfinished output; changing shared instructions does not rewrite the active request. A correction can require a new decision, while an ordinary update may wait until the next boundary.
Voice filler can acknowledge that work is continuing. Its usefulness depends on measured timing: initial silence, any gap after the filler, and time to meaningful output. Filler does not satisfy a prerequisite or restart the latency measurement.
### Recovery and Human Control
The target contract distinguishes an intended action, its submission attempts, and its confirmed outcome. Recovery would retain pending obligations or explicitly mark them unresolved. An uncertain external submission requires the provider's supported idempotency or reconciliation path before retrying; execution ownership alone cannot guarantee exactly-once effects.
Operator guidance, takeover, and handback need separate authority and scope. The proposed harness would reconsider affected pending work after handback and retain already submitted actions for reconciliation. Current controls and channel limits remain documented in [Operators](/operations-and-safety/operators); this design does not promise restoration of every dropped call or recovery of every running tool.
Evaluate recorded-result replay separately from rerunning models. The former inspects execution handling for supplied outcomes; the latter also measures model variability. Agree on covered failures, recovery deadlines, meaningful-output latency, and total cost under a stated workload before assigning production targets. See [Evaluating Amigo](/platform-overview/evaluating-amigo).
## Modality Adapters
Each adapter handles the channel-specific concerns that the reasoning engine does not touch:
| Adapter | Signal Production | Effect Execution |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Voice** | STT produces utterance signals; prosody analysis produces emotion signals; silence and barge-in detectors produce their respective signals | Respond effects stream through TTS with emotion-adaptive delivery; fillers play audio; pauses hold silence; terminate effects hang up after final speech |
| **Text (SMS)** | Incoming messages produce utterance signals | Respond effects send SMS messages; terminate effects end the session |
| **Simulation** | Test parameters inject utterance and emotion signals | Effects are captured as simulation evidence; tool writes use simulation source tagging rather than a separate database branch |
New modalities can reuse the signal-and-effect contract through an adapter. Channel-specific delivery, lifecycle, authorization, and failure handling still require integration and testing.
{% hint style="info" %}
**Related sections** - See [Context Graphs](/agent/context-graphs) for how the engine navigates problem spaces, [Functional Memory](/agent/memory) for bounded cross-session context, and [Voice Agent](/channels/voice) for voice-specific pipeline details. [Dynamic Behaviors](/agent/context-graphs/dynamic-behaviors) documents a separate Classic API capability.
{% endhint %}
# Context Graphs
Structured state machines that define conversation flow, decision points, and safety boundaries for agent workflows.
Context graphs define the authored workflow available to an agent: states, transitions, objectives, guidance, boundaries, and state-bound tool specifications. Model-driven navigation still has probabilistic failure modes, so use simulations and runtime safety controls rather than treating graph text as a formal guarantee.
A Context Graph describes the work; the [world model](/data/world-model) supplies selected facts about the people and resources involved. The [agent](/agent/agents) supplies broader identity and guidance. Read the architecture and authoring sections first, then use the state and tool sections for the execution details.
## The State-Based Architecture
Context graphs differ from scripted dialog trees and unconstrained prompt-only agents in three ways:
1. **States, not scripts**: The graph defines states and transitions, not a fixed sequence of utterances. Model-driven states select among authored actions and exits from the available conversation context.
2. **Variable authoring detail**: Different regions can carry different amounts of objective, guidance, boundaries, guardrails, and tool configuration. These instructions steer behavior; they do not by themselves make model output deterministic.
3. **Incomplete by design**: Context graphs define workflow shape but not the full performance. The complete picture combines the graph's structure, the agent's identity and directives, state-level guidance, available tools, selected memory context, and channel policy.
The agent navigates the graph by evaluating which state to enter next based on the conversation so far, the patient's data, and the constraints defined on each transition.
Context graphs allow agents to:
* **Make safety intent reviewable** - place escalation guidance, boundary constraints, and state-specific guardrails next to the workflow step they govern.
* **Carry workflow state across turns** - track the current state and, for data-collection states, collected and remaining fields.
* **Vary guidance by task risk** - author more explicit constraints for sensitive steps and broader objectives for exploratory ones.
* **Reuse structure across supported channels** - apply channel overrides where voice and text behavior should differ.
* **Inspect observed paths** - use traces and simulation evidence to find untested or poorly performing states.
## From Protocol to Practice
Context graphs can encode clinical protocols and service workflows as state machines that an author reviews against the source protocol. Explicit states and exits make authored intent and observed navigation paths inspectable. They do not expose hidden model reasoning or replace clinical, compliance, and release review.
## Varying Constraint by State
"Context density" is an authoring heuristic, not a persisted state property. Authors vary constraint using the fields the runtime actually reads: objectives, actions, navigation guidance, boundary constraints, typed guardrails, exit conditions, tool bindings, and turn policy.
Use more explicit guidance and narrower exits for sensitive steps, and broader objectives for conversational steps. Validate the resulting behavior in simulations; added prompt detail is not equivalent to deterministic phrasing or a hard policy control.
## Bounded Multi-State Traversal
Within a turn, navigation can leave an action state, pass through decision and annotation states, and land on an engageable action or data-collection state. Decision states select an authored exit; annotation states inject authored internal guidance without a user-facing turn. The navigator detects loops and enforces an iteration cap instead of allowing an arbitrary number of internal transitions.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
A1["Action state"] --> D["Decision state"]
D --> N["Annotation state"]
N --> A2["Action state"]
D --> C["Data-collection state"]
```
Initial and terminal states are configured as action states. A turn can nevertheless engage through a data-collection state, so do not infer that every user-visible turn begins and ends on an action state. Traces record observed states, transitions, and actions; they do not expose hidden chain-of-thought reasoning.
## Integration with Memory and State Guidance
Context graphs do not run in isolation. At each state, the agent can receive selected [Functional Memory](/agent/memory) context and applies the state's authored guidance, turn policy, and tool specifications. Conditional behavior should be visible in states and transitions so teams can review and simulate it directly.
{% content-ref url="/pages/Kii5Ga5iQp6e9fEKbQ0t" %}
[Dynamic Behaviors](/agent/context-graphs/dynamic-behaviors)
{% endcontent-ref %}
## State Types Reference
Each state type serves a specific purpose in managing conversation flow and agent behavior.
| State Type | Purpose | Typical Use |
| ------------------- | ------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------- |
| **Action** | Deliver user-facing responses within guardrails | Conversational turns, report delivery |
| **Decision** | Select among authored exits using current inputs | Routing between workflows, escalation decisions |
| **Annotation** | Inject preset guidance into the agent's reasoning, then advance to a fixed next state | Steer reasoning between states without an extra model turn (for example, inject a reminder before a sensitive step) |
| **Data Collection** | Collect structured fields from the caller with surface fallback | Insurance intake, demographic verification, medication lists |
Data-collection states define fields to gather, a completion transition, turn limits, and an optional [surface](/channels/surfaces) fallback. The fallback can build a form from remaining fields after the configured number of turns; creation and delivery still depend on entity context and a supported Surface channel.
The same graph can support voice and text runtimes, but channel capabilities and delivery semantics differ. Use channel overrides and test each enabled channel separately.
### Designing a State
Each state definition should answer five questions before it ships to production:
1. **Objective** - What outcome must be true before the state can exit?
2. **Guidance** - Which ordered actions or prompts keep the model on the intended path?
3. **Boundaries** - Which behaviors are forbidden, especially for safety or compliance?
4. **Exit criteria** - What explicit signals trigger each transition, and which state follows?
5. **Tooling and memory configuration** - Which tool calls are exposed in this state, and should active memory retrieval be skipped?
State tool-call specs gate workflow tools bound to that state. Runtime-provided system tools and shared platform tools can also be exposed when the service and channel enable them, so state bindings are not a universal inventory of every callable tool. Turn policy can further block supported system tools such as forwarding.
### Action State Extensions
Action states support several optional workflow controls. The asynchronous and channel-specific controls include:
* **Wait conditions** - A state can declare a `wait_for` condition that pauses the context graph. The agent stays in the current state, constrained to empathetic small-talk, until the condition clears (e.g., a surface submission or human approval).
* **Surface templates** - A state can include a surface spec that requests [surface](/channels/surfaces) creation on state entry. Creation requires valid entity context and a successful platform request.
* **Channel overrides** - Per-channel overrides for objective and action guidelines. When the same context graph runs across voice and SMS, overrides let each channel tailor behavior without duplicating the entire state definition.
* **Completion-gated navigation** - A tool call spec can set `navigate_on_completion`. After a successful result, the engine re-evaluates navigation without waiting for another user message. The navigator can remain in the state or select another valid state; this option does not guarantee that every completion advances.
### Tool Dispatch Configuration
Each tool a state binds carries three independent dispatch axes that control *when* the tool runs, *how* its result re-enters the conversation, and *whether* the work is tied to the turn that asked for it. All three default to the historical behavior, so existing services are unaffected.
* **Execution** - `blocking` (default) awaits the tool inline within the turn, so its result is in hand before the agent continues; `background` dispatches it off-turn so the agent keeps the floor and the result arrives later. Use `background` for work that can take longer than the caller should wait in silence.
* **Delivery** - `interrupt` (default) surfaces the result as soon as it is ready, as a fresh continuation turn; `queue` folds the result silently into the next user turn instead. Two combinations are rejected when you save the context-graph version: a `background` tool may not use `queue` (a fire-and-forget result that never surfaces is a silent dead-end), and a tool in the terminal state may not be `background` (there is no later turn to deliver into).
* **Lifecycle** - `independent` (default) lets a `background` task continue after the launching turn; later delivery still depends on the channel and conversation remaining deliverable. `coupled` ties the task to the turn that launched it: if the user sends another message or the conversation closes first, the task is cooperatively superseded and its result is dropped. This axis is currently meaningful for background work on text and chat paths; voice uses its own teardown behavior.
The lifecycle axis decides what happens to a `background` result once the conversation has moved on:
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart TD
D["Turn N dispatches a\nbackground tool"] --> R["Tool runs off-turn\n(agent keeps the floor)"]
R --> C{"Tool completes"}
C -->|"independent (default)"| DEL["Deliver the result\n(whenever ready)"]
C -->|"coupled, conversation moved on\n(new turn or ended)"| DROP["Drop the result\n(task superseded)"]
C -->|"coupled, still the same turn"| DEL
style DEL fill:#FDFCFB,stroke:#D7D2D0
style DROP fill:#FDFCFB,stroke:#D7D2D0,stroke-dasharray: 5 5
```
### Tool Result Persistence
A state-tool binding also controls which arguments and results remain in conversation history and later prompts:
| Mode | Conversation journal | Later prompts |
| -------------- | --------------------------------------------------------------------- | ------------------------------------------------------------------ |
| **Accumulate** | Retains each call's arguments and result | Renders the retained results, subject to normal context management |
| **Override** | Still retains every call | Renders only the latest result per tool name |
| **Ephemeral** | Retains redacted execution metadata, without raw arguments or results | Excludes those entries from reconstruction |
Accumulate is the default. Override reduces repeated prompt context; it does not delete earlier results from storage.
Ephemeral persistence requires workspace authoring enablement and is supported only on the inline text and simulation path. When its runtime rendering capability is enabled, raw arguments and results can inform the current reasoning transaction. With rendering disabled, the transaction still runs and journals redacted metadata, but the raw payload is not supplied to the model. Voice, background, and external realtime sessions reject an ephemeral graph during initialization. Ephemeral bindings must use interrupt delivery; queue delivery is rejected.
This setting governs the tool payload in the conversation journal and prompt reconstruction. It is not a deployment-wide zero-retention policy: a tool's destination, an external write, or information repeated in the agent's response has its own handling rules.
## Automated Optimization Through Agent Forge
[Agent Forge](/reference/agent-forge) lets coding agents inspect, author, validate, and apply Context Graph configuration. Use simulation and production evidence to propose changes, then review the diff and rerun relevant suites before promotion. Forge does not make graph optimization automatic or guarantee that a configuration change improves outcomes.
{% hint style="info" %}
**API naming:** The Classic API represents Context Graphs as `service_hierarchical_state_machine` resources; see [Agents and Context Graphs](https://docs.amigo.ai/developer-guide/classic-api/core-api/agents-and-context-graphs). Platform services bind separate agent and Context Graph versions through version sets; see [Services](https://docs.amigo.ai/developer-guide/platform-api/workspaces/services).
{% endhint %}
# Dynamic Behaviors
Classic API dynamic behavior sets, including semantic triggers, instruction injection, tool changes, versioning, and Platform API alternatives.
Dynamic behavior sets are a Classic API capability. They adapt how a Classic agent operates for one turn without changing its underlying Context Graph. When a caller's message semantically matches a configured trigger, the Classic runtime can inject an instruction, change the available tool candidates, or do both.
{% hint style="warning" %}
The Platform API does not expose or execute dynamic behavior sets. On Platform services, author conditional behavior in Context Graph states, transitions, entry guidance, exit conditions, turn policies, and eligible tools. Do not migrate a Classic behavior set by assuming a like-for-like Platform resource exists.
{% endhint %}
{% hint style="info" %}
**Classic API name:** `dynamic_behavior_set`. See [Dynamic Behaviors](https://docs.amigo.ai/developer-guide/classic-api/core-api/dynamic-behaviors) in the developer guide for the current Classic contract.
{% endhint %}
## Classic Behavior Model
A Classic Context Graph defines the workflow structure. A dynamic behavior set adds reusable turn-level adaptation outside that graph. This can be useful when one semantic condition should affect several states without duplicating the same instruction or tool change in each state.
This separation is specific to the Classic runtime. Platform safety and scope boundaries belong in the authored agent and Context Graph rather than in a separate dynamic-behavior layer.
## Anatomy of a Behavior
Each Classic dynamic behavior defines:
* **Triggers** - Natural-language descriptions of the conversation patterns that activate the behavior. At each turn, the platform matches the caller's message against these triggers by semantic similarity, so a trigger describes an intent ("the caller mentions chest pain") rather than an exact phrase.
* **Actions** - What the behavior does when it fires. At least one action is required, and two types are supported:
* **Instruction injection** - Adds an instruction to the agent's guidelines for the turn. The behavior can either append to the state's existing guidelines or override them entirely.
* **Tool candidate changes** - Changes the tools available to the agent for the turn. The behavior can either add tools to the current state's set or replace that set.
Behaviors are grouped into named, versioned sets. A Classic service version set can reference the desired behavior-set versions alongside its other Classic configuration.
## Classic Version Sets
Classic dynamic behavior sets are applied to services through version sets. A conversation created against a given Classic version set evaluates the behavior sets bound to it. Test the exact version-set combination before updating a release alias.
See [Version Sets and Promotion](https://docs.amigo.ai/developer-guide/operations/devops/version-sets-best-practices) for the broader release workflow.
## Relationship to Context Graphs
In Classic, a matching behavior changes the current turn without changing graph topology. The state and transition structure stays intact while the behavior adjusts guidance or tool candidates.
In Platform, place the equivalent logic explicitly in the Context Graph or agent configuration. Safety-sensitive rules should be visible in the authored state and transition model so they can be reviewed and simulated directly.
## Migrating to Platform
When moving a Classic service to Platform:
* Move safety and scope rules into explicit states, entry guidance, exit conditions, and escalation instructions.
* Move reusable factual guidance into the agent's authored instructions or supported knowledge sources.
* Add conditional tool availability to the relevant state's tool specifications.
* Rebuild simulations around the resulting Platform graph instead of expecting Classic behavior-set versions to migrate.
## Related Pages
{% content-ref url="/pages/b9dT9LVnevpo6xLqrEfo" %}
[Context Graphs](/agent/context-graphs)
{% endcontent-ref %}
For Platform per-state configuration, see [Context Graphs](/agent/context-graphs) and [Reasoning Engine](/agent/reasoning-engine#per-state-configuration-turnpolicy).
# Memory
How source-linked observations and bounded models preserve useful context, with scoped recall when an agent needs detail from earlier interactions.
{% hint style="success" %}
**For developers:** See [Memory Architecture](https://docs.amigo.ai/developer-guide/operations/reference/memory-architecture) for API resources and [Data & World Model](https://docs.amigo.ai/developer-guide/platform-api/data-world-model) for entity enrichment.
{% endhint %}
Functional memory develops useful, source-linked understanding over time. It helps an agent carry context into later interactions and retrieve supporting detail when the loaded model is insufficient. The world model anchors that understanding to an entity and workspace; the active session uses it alongside current records and conversation history.
Three operations explain the person-memory workflow:
* **Observe** - Interpret a completed conversation against the current understanding and extract useful new information.
* **Consolidate** - Integrate observations into a bounded user model with references to supporting evidence.
* **Recall** - Search earlier observations and conversations when the current task needs more detail.
The compact model gives the agent a starting point. Exact operational facts, such as appointment availability, still come from the appropriate data tools. A generated interpretation does not acquire the authority of a clinical record merely because it is remembered.
## Memory, World Data, and Working Context
| Layer | Purpose | Example |
| ------------------------- | ------------------------------------------------------------------- | ------------------------------------------------------------------- |
| **Source evidence** | Retain what was recorded and where it came from | A conversation turn or connected system record |
| **Derived memory** | Summarize useful context, changes, and interaction patterns | A person's preferences and reported barriers |
| **Structured world data** | Preserve typed facts and relationships for retrieval and operations | An appointment's time, status, and associated person |
| **Working context** | Supply the information used in the current interaction | Recent turns, selected enrichment, state guidance, and tool results |
The subject of a memory must be distinguished from the person speaking. An operator discussing a patient does not make that observation a memory about the operator. The person-recall path below uses the session's resolved subject, within its workspace.
The world model owns reusable object facts, relationships, and factual resolution. Memory derives useful understanding from eligible evidence. Applications own their task notes and operational state; the reasoning runtime owns the context used during execution. These responsibilities do not require separate stores, and generating a summary does not create a second authority for the underlying record.
The implemented extraction, consolidation, and recall path described below is person-scoped. The [object-memory design direction](#design-direction-object-memory) extends these ideas to other objects; it is separate from this current contract. Confirm any private-preview object types, sources, and views for the intended deployment.
## Implemented Memory Model
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
transcript["Completed conversation\ntranscript"] --> episodic["Episodic observations\nnet-new, source-linked"]
episodic --> semantic["Semantic user model\nbounded consolidation"]
connector["Connector and EHR records"] --> clinical["Structured clinical state\ndeterministic projection"]
semantic --> current["Current entity enrichment"]
clinical --> current
current --> session["Later agent session"]
```
| Layer | What It Contains | How It Is Produced |
| ----------------------------- | --------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------- |
| **Conversation record** | The source transcript and turn history | Stored as conversation evidence |
| **Episodic observations** | Net-new or surprising information from a completed conversation | Extracted from the transcript in the context of the current user model |
| **Semantic user model** | An integrated narrative of patterns, changes, and interaction preferences | Consolidated from the current model and a bounded set of recent observations |
| **Structured clinical state** | Current conditions, active medications with doses, and allergies from connected records | Deterministically projected from world-model events |
The semantic user model and structured clinical state reach the agent through the same current-enrichment surface, but they have different provenance and confidence. Structured connector-derived context outranks model-generated memory when both compete for the same key.
## Post-Conversation Processing
After a conversation ends:
1. The platform associates the completed transcript with the resolved workspace entity.
2. The episodic extractor compares the conversation with the current user model and records net-new observations with source references.
3. The semantic consolidator updates the integrated user model from the current model plus a bounded window of recent observations.
4. The enrichment fold selects the current values, retaining confidence, source, effective time, and supporting lineage.
5. A later session loads the current enrichment alongside the rest of its world-model context.
Processing is asynchronous. Information said in the current conversation remains available in that conversation's turn history, but it may not appear as cross-session memory until post-conversation processing succeeds.
## Episodic Observations
Episodic observations capture information that may matter later, such as:
* Communication preferences and engagement patterns
* Goals, motivations, and barriers
* Emotional or behavioral changes over time
* Patient-reported context not already represented in the current user model
These observations are model-generated. They retain references to supporting conversation evidence and remain bounded by the configured memory dimensions, but they are not guaranteed to capture every detail or to be clinically authoritative.
## Semantic User Model
The semantic layer integrates episodic observations into a concise narrative rather than appending an unbounded history. Consolidation uses:
* The current user model
* Recent observations since the previous consolidation
* A bounded lookback of observations relevant to the model's pattern themes
The result can describe trajectories such as rising, falling, stable, or changed behavior. Consolidation requires a non-empty set of supporting observation references and instructs the model to preserve safety-relevant signals. Those references help trace a generated model; their presence alone does not verify that every sentence is supported or that every important detail survived consolidation. The user model should not replace authoritative clinical records or runtime safety rules.
## Structured Clinical State
The platform also derives a deterministic `clinical_state` enrichment from connected clinical data:
* Active conditions
* Active medications and available dose information
* Allergies
Conditions and medications use bounded summaries with visible overflow markers. Allergies are not truncated. This projection is connector-derived rather than extracted from conversation text, so it carries a higher confidence tier than model-generated memory.
## Custom Memory Dimensions
Workspaces can add conversation-memory targets through enrichment keys tagged for memory extraction. A custom memory key must:
* Apply to person entities
* Use a valid `snake_case` identifier
* Include a non-empty description that defines what to extract
* Use the string value type
* Avoid shadowing a platform-provided key
Custom dimensions join the same extraction and validation path as platform defaults. A workspace with no custom dimensions continues to use the default memory targets. Custom dimensions are bounded to the behavioral precision tier; they do not become authoritative clinical state.
Define a dimension around information that will change how a later interaction is handled. For example, describe scheduling constraints and the reasons the person gives, including changes over time, rather than asking for a generic conversation summary. Test the definition with a new preference, a correction, and an interaction that contains nothing relevant. These are authoring and evaluation practices; adding a dimension does not guarantee complete extraction or retrospective processing of all earlier conversations.
## Retrieval and Session Context
The agent receives the current user model and other selected enrichment at session start. It can still query the world model or connected tools for detailed operational and clinical data when needed. Functional memory does not eliminate retrieval, guarantee complete recall, or load every historical transcript into the prompt.
Use memory for durable interaction context and patterns. Use authoritative data tools for current appointments, medications, clinical records, and other facts where freshness or source authority matters.
### Recall Beyond the Loaded Model
When the memory-expansion tool is exposed in a supported session, the agent can search the resolved person's observation history, prior conversation turns, or both. This is useful when the summary says that scheduling is difficult but the agent needs to recover the reason given in an earlier interaction.
Recall is read-only and scoped by the server to the session's resolved person and workspace. The model supplies a topical query, an optional observation dimension, a search scope, and a bounded result limit. It cannot select another person's history by supplying an identifier.
The search uses keyword or phrase matching and returns recent matches first. It caps the history searched, the number of results, and returned text length. It can therefore miss an older detail, a different phrasing, or context outside a returned excerpt. It is not a semantic relevance ranking or an exhaustive history review.
| Result | Meaning | Recommended workflow response |
| ---------------------------------- | ------------------------------------------------------- | --------------------------------------------------------------------------------- |
| **Matching observations or turns** | Detail was found within the searched history | Check source, speaker, and time before using it |
| **No matches** | The bounded query found no matching records | Refine the query, use an authorized data tool, or ask for the missing information |
| **No resolved person** | The session has no subject whose memory can be searched | Resolve the subject through the supported identity workflow |
| **Temporarily unavailable** | The recall path could not serve the request | Continue with sufficient existing evidence or use the workflow's fallback |
An empty or unavailable result is not evidence that an event never happened. Retrieved agent speech is also not an independent confirmation of what a person reported or what an external system did.
The task itself can reveal a need for retrieval: a required field, newly mentioned object, or correction may matter even when the loaded summary contains no cue to search. Do not use the summary as the only checklist of what evidence could be missing.
### A Changed Preference Across Interactions
Suppose the loaded model describes a morning appointment preference, but the person now says, "I work nights now, so afternoons are better."
1. Use the correction as current conversation context and clarify any ambiguity relevant to the task.
2. If earlier detail matters, recall supporting observations or conversation turns instead of inferring them from the summary.
3. Check live availability through the scheduling tool; the remembered preference supplies context for that lookup.
4. After the interaction, asynchronous extraction and consolidation can incorporate the change into later-session memory.
Verify the later enrichment before assuming the update is available to another session. Separate the time the conversation ended, the time memory processing completed, and the time the served context reflected the change. A processing schedule alone is not an end-to-end freshness guarantee.
## Design Direction: Object Memory
The proposed extension organizes memory around an object, its evidence, and task-specific views. A study, specimen, aliquot, and experiment run retain distinct identities and histories. A view may be a narrative, exact fields, a relationship map, or a few orientation cues. Several views can use the same evidence for different tasks.
General object-memory derivation, project subscriptions, state-entry preload, and the full correction contract below are extensions to the person-memory path. They are design requirements, not guarantees supplied by the current recall tool.
### Evidence and Corrections
Observe, consolidate, and recall remain the main operations, with a broader evidence contract:
| Concern | Required behavior in the proposed design |
| ----------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Attribution** | Keep the subject, speaker, and observer distinct; retain original source identity when an object mapping changes |
| **Meaning and time** | Preserve source revisions, effective time, units, and conditions; distinguish measurements, reports, and inferences |
| **Supporting evidence** | Check that material claims are supported by eligible records with the correct subject, revision, and meaning; the previous summary is context, not new support |
| **Corrections** | Invalidate affected views and pending use after a correction, withdrawal, identity change, or incompatible definition change; rebuild before dependent work proceeds |
| **Publication** | Accept a rebuilt view only while its dependencies still match, so an older computation cannot restore invalidated understanding |
| **Coverage** | Make incomplete, stale, unavailable, and no-match results distinguishable; retain evidence outside a processing limit as pending or explicitly excluded |
A repeated measurement can be meaningful even when its value is unchanged. Importing that same measurement repeatedly does not create independent confirmation. Later arrival also does not automatically make a record supersede an earlier observation: the time and conditions of the claim still matter.
Access and retention apply to derived views and retrieved context as well as source records. Related objects and shared projects do not grant access. The proposed correction and erasure process must account for indexes, caches, traces, and serving views; a historical or pinned view remains subject to withdrawal and access rules.
### Context Required by a Task
A project would identify relevant objects, relationships, and views. A Context Graph state would declare which view it needs, which decision depends on it, what makes it valid, and the fallback when it is unavailable. These declarations describe proposed execution support, not additional fields in today's public Context Graph contract.
Required context and preloaded context are independent. A required view can load while unrelated work continues; the dependent decision waits until its prerequisites are satisfied. Existing valid context can be reused. Reasoning may discover another information gap and request scoped evidence within the task's budget. Model confidence cannot waive a prerequisite.
For example, a proposed read-only study comparison would begin with the study and run identities, then retrieve each run's inputs, values, units, recorded conditions, and applicable method and analysis revisions. Individually recent records may still be incompatible. An unexplained normalization difference would trigger additional retrieval. If a handling record were corrected before the comparison completed, affected pending conclusions would need reconsideration before release. The answer would separate supported differences from inferred causes and unresolved questions.
### Execution and Longer-Term Improvement
The execution loop uses accepted knowledge for the current task and retains new evidence and outcomes. A slower improvement loop would examine repeated work and propose reusable views, dimensions, or resolution rules. A useful comparison that repeatedly requires the same reconstruction is a candidate for this review.
The slower loop remains a design direction. Proposed definitions need an owner, evaluation, explicit acceptance, and a rollback path before later work uses them. Background behavior selection within an interaction is still execution; it does not establish learning across interactions. Automatic production-definition changes are outside this design phase.
Evaluate a compact view against source retrieval and their combination on a stated task. Compression, repeated agreement, and successful replay do not prove completeness or causality. Reprocessing history cannot recover a measurement that was never recorded. See [Evaluating Amigo](/platform-overview/evaluating-amigo#evaluate-memory-on-tasks-that-need-continuity) for the evidence to collect.
## Safety and Auditability
* **Source preservation** - Conversation records remain the evidence behind extracted observations.
* **Lineage** - Semantic claims point back to supporting episodic observations.
* **Confidence separation** - Generated memory does not silently outrank structured connector-derived context.
* **Workspace isolation** - Memory is scoped to the entity and workspace that produced it.
* **Bounded context** - Consolidation and prompt loading stay bounded rather than growing with the full conversation history.
Memory can improve continuity, but it is not a guarantee of perfect recall or a substitute for clinical verification. Safety decisions must continue to use the platform's runtime controls and authoritative data sources.
{% hint style="info" %}
For text-thread persistence within a conversation, including frozen plans and recent turns, see [Text Sessions](/channels/text-sessions#durable-conversation-model). Conversation persistence and cross-session functional memory are separate mechanisms.
{% endhint %}
# Clinical Tools
Current built-in world tools for patient lookup, scheduling, clinical reads, and source-attributed writes.
The Platform runtime has a built-in catalog of world tools for patient, scheduling, clinical, and operational workflows. A catalog entry is a supported tool definition, not a promise that every agent can call it. Actual exposure depends on the runtime, service, Context Graph state, channel, authorization, and resolved patient scope.
{% hint style="info" %}
Earlier note-authoring and semantic patient or event search tools are retired. Current capabilities are grouped by workflow below. Use explicit patient identifiers and typed lookups rather than natural-language entity search.
{% endhint %}
World write tools record structured, source-attributed events. Event acceptance, entity projection, review, connector eligibility, and external delivery are separate milestones. A successful tool result does not by itself prove that an external system changed.
## Patient Data
| Capability | Type | What It Does |
| ------------------ | ----- | ----------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Patient lookup** | Read | Searches by a known entity ID or supported demographic and source identifiers, including date of birth, name, phone, email, or medical record number. |
| **Patient create** | Write | Creates a person event after the tool's supported duplicate check. |
| **Patient update** | Write | Records supported demographic and contact changes for a resolved patient. |
| **Save patient** | Write | Updates a supplied entity or performs the supported lookup-and-create path when no entity is supplied. |
## Scheduling
| Capability | Type | What It Does |
| -------------------------- | ----- | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Slot search** | Read | Finds supported available slots by date and optional location, appointment type, provider, specialty, or time constraints. |
| **Appointment lookup** | Read | Searches appointments using the supported patient, status, and date filters. |
| **Schedule appointment** | Write | Records a booking from a supported slot reference and resolved patient. |
| **Cancel appointment** | Write | Records cancellation of a resolved appointment. |
| **Confirm appointment** | Write | Records confirmation of a resolved appointment. |
| **Reschedule appointment** | Write | Records cancellation of the prior appointment and creation of its replacement. These are related writes, not one universal external transaction. |
## Clinical Context
| Capability | Type | What It Does |
| ----------------------------------- | ----- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Medication lookup** | Read | Retrieves supported prescription records for a resolved patient. |
| **Prescription refill** | Write | Records a refill-request event for a selected prescription. |
| **Encounter lookup** | Read | Retrieves supported visit and encounter history. |
| **Insurance create** | Write | Records a coverage event for a resolved patient. |
| **Payer and reference-data lookup** | Read | Searches configured payer information or other supported workspace reference data. |
| **Typed clinical lookups** | Read | Query supported conditions, allergies, observations, medication statements, notes, family history, questionnaires, uploads, care plans, goals, tasks, service requests, consents, and diagnostic reports. Coverage depends on projected source data. |
## Operations
| Capability | Type | What It Does |
| ----------------- | ----- | ---------------------------------------------------------------------------------------------------------------------- |
| **Queue lookup** | Read | Reads projected outbound-task state using supported status, phone, ordering, and limit filters. |
| **Ticket create** | Write | Records a support or operations ticket event. |
| **Log call** | Write | Records a supported call-outcome event for a resolved patient. |
| **Log triage** | Write | Records the structured outcome supplied for a triage conversation. It is not an independent clinical decision service. |
Scheduled outbound voice work is created through explicit outbound-task actions or workflows, not a semantic search tool or a general built-in agent tool. See [Outbound](/channels/outbound).
## Tool Exposure
Context Graph state bindings can expose eligible built-in tools for that state. Supported runtimes can also add narrowly scoped system tools or other configured tool families. State membership alone is not authorization, and presence in the global catalog does not mean a tool is active for a particular service.
For the live catalog and service-specific resolution endpoints, see [Tool Testing](https://docs.amigo.ai/developer-guide/platform-api/functions/tool-testing).
## Verification
Clinical write capabilities do not push raw conversation output directly into external systems. They validate structured tool input, enforce the applicable workspace and patient scope, and attempt a source-attributed world-model event write. Some runtimes suppress only identical writes that overlap in flight; that is not general request idempotency.
Connector policy determines whether an eligible event becomes an external mutation. Where the private-preview review flow is enabled, a configured path can create an [external write proposal](/data/review-queue). Approval authorizes the proposal but does not prove downstream delivery.
Workspaces can add other eligible capabilities through [Platform Functions](/agent/platform-functions), workspace queries, integrations, and Skills.
# Platform Functions
Workspace-registered SQL, AI, Python, and table-valued functions for governed data retrieval and computation.
{% hint style="info" %}
**API Name**: Platform functions are managed through the Agent Forge CLI, the platform SDK, and the Developer Console's Warehouse tab (Tools > Warehouse), which provides a read-only directory, inspector, and test runner, in addition to the workspace-scoped `functions` endpoints. See the [Developer Guide](https://docs.amigo.ai/developer-guide/platform-api/functions) for endpoint details.
{% endhint %}
Platform functions are workspace-registered computation tools. You define a supported SQL, AI, Python, or table-valued function and deploy it to the workspace function registry. Supported agent runtimes can then expose that function as a tool and return its result to the agent.
The key capability is cross-domain querying. Platform functions can read both live entity data (the world model's operational store) and analytical aggregations (historical trends, billing data, population statistics) in a single call when the registered SQL has access to those sources. A function might combine an entity's current projected confidence fields with a separately defined utilization aggregate.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
agent["Agent mid-conversation"] --> fn{Function Type}
fn --> sql["SQL\n(query live + analytical data)"]
fn --> ai["AI\n(classify, extract, summarize)"]
fn --> py["Python\n(custom logic)"]
fn --> tvf["Table-valued\n(multi-row results)"]
sql --> result["Structured result\nback to agent"]
ai --> result
py --> result
tvf --> result
```
## Tool Categories
Each successfully loaded platform function registers as a tool with a name, description, input schema, and result. Two related families can load at session start:
* **Named platform functions** - addressed as `fn_`, these are pre-built queries or computations registered for the workspace. Each runs on the platform's compute layer.
* **Workspace data queries** - addressed as `wsq_`, these are parameterized SQL templates that run directly against a workspace's own custom tables. Parameters are typed with optional defaults, write-time validation rejects multi-statement and session-state SQL, and execution runs under the workspace's tenant-scoped role.
### Named Functions
Named functions are pre-built queries or computations registered for the workspace. Each function has a name, description, input schema, and return type. The agent calls them by name with structured parameters.
Function types:
| Type | What It Does | Example |
| ---------------- | ------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------- |
| **SQL** | Parameterized query that returns rows or a single computed value across live and analytical data | Patient summary, caller history, entity confidence assessment, risk score |
| **AI** | A query that wraps an AI operation such as classify, summarize, extract, or assess | Intent classification, clinical extraction, transcript cleanup, care plan generation, handoff summaries, urgency assessment |
| **Python** | A sandboxed scalar function for custom logic | Address parsing, custom scoring algorithms, phone formatting |
| **Table-valued** | A sandboxed function that returns multiple rows | Expanding a record into per-line-item rows, derived tabular results |
Deployments can expose common world-data functions, and a workspace can register additional named functions. The session runtime loads functions that are registered for that workspace; do not assume a warehouse function is automatically present as an agent tool.
{% hint style="info" %}
**Common Function Names**
Depending on deployment and workspace registration, common examples include:
* **Entity confidence** - Current projected source, event count, confidence value, and last-event time for an entity (SQL)
* **Caller history** - Recent call dates, outcomes, quality scores, and conversation summaries for a phone number (SQL)
* **Patient summary** - Current display name, entity type, event count, source, and last-event time (SQL)
{% endhint %}
Workspaces can register additional SQL, AI, Python, and table-valued functions. The callable set for a session depends on workspace registration, successful loading, the selected runtime, and any applicable Context Graph bindings.
### Workspace Data Queries
Workspace data queries (`wsq_`) cover the long tail of questions that no pre-built function anticipated, such as "how many appointments did this patient cancel in the last 6 months?" or "which providers at this location accept this insurance?" A team registers these as parameterized SQL templates that run against custom tables provisioned for the workspace. Parameters are typed (string, integer, number, boolean) with optional defaults, and write-time validation rejects multi-statement SQL and session-state commands. Query access remains constrained to the workspace's provisioned tables.
Platform functions are read-only. Recording new observations as world model events is done through the dedicated write tools described in [Clinical Tools](/agent/clinical-tools) and the [World Model](/data/world-model) page, not through this surface.
## Loading Functions at Session Start
Registered functions and workspace data queries are loaded at session start from the workspace stores. A load failure can leave a function unavailable for that session. In the state-machine runtime, `tool_call_specs` normally determines state-level visibility. Other supported runtimes can expose shared platform tools through their own session configuration. Validate the runtime used by the service rather than assuming one universal gating rule.
## Using Functions in Context Graphs
For the state-machine runtime, bind a function through `tool_call_specs` on each Context Graph state that needs it:
```yaml
tool_call_specs:
- tool_id: fn_entity_confidence
- tool_id: wsq_appointment_history
additional_instruction: "Look up the patient's appointment history when relevant"
```
Named platform functions use the `fn_` prefix, becoming `fn_{name}` (e.g., `fn_caller_history`, `fn_risk_score`). Workspace data queries use the `wsq_` prefix, becoming `wsq_{name}`.
This keeps function access contextual on that runtime - a triage state might expose `fn_entity_confidence` and `fn_caller_history`, while a data-capture state exposes relevant workspace data queries. Other supported agent runtimes can use a shared-tool contract; consult their runtime documentation before relying on state-level hiding as an authorization boundary.
## Management
Platform functions are managed through workspace-scoped REST endpoints, the platform SDK, and [Agent Forge](/reference/agent-forge) - see the [developer guide](https://docs.amigo.ai/developer-guide/platform-api/functions) for endpoint details. Deploying a function name that already exists replaces the definition in place (no versioning or aliases), and functions registered in one workspace are independent of other workspaces.
### Agent Forge CLI
[Agent Forge](/reference/agent-forge) provides function management commands:
```bash
forge platform function list
forge platform function catalog
forge platform function register --file function.json
forge platform function test --input '{"argument": "value"}'
forge platform function query --sql 'SELECT ...'
forge platform function sync
forge platform function delete
```
## How Tool Types Relate
The platform has three complementary tool types. Each serves a different purpose:
| | Platform Functions | Actions | Skills |
| -------------------- | --------------------------------------------------------- | ---------------------------------------------------------------------- | ------------------------------------------------------------- |
| **Definition** | Declarative (SQL, AI, Python, table-valued) | Imperative (custom code packages) | LLM-backed micro-agents with prompt-based configuration |
| **Deployment** | Register and run - no container or build step | Package with dependencies, deploy to execution environment | Configure prompt, schemas, model, and declared tools |
| **Data access** | Read access granted to the registered function runtime | Defined by the packaged Action and its credentials | Through declared integration and static tools |
| **Write capability** | None - read-only; writes go through dedicated write tools | Defined by the package and its authorized integrations | Delegated through declared tool calls |
| **Latency** | Warehouse or compute startup can add delay | Depends on the deployed Action and execution environment | Bounded by configured timeout and agent-turn limits |
| **Best for** | Data retrieval, scoring, classification, summarization | Multi-step workflows, external system integration, document generation | Prompt-driven reasoning and orchestration over declared tools |
Use platform functions when the agent needs data or computation. Use Actions on the Classic API when the agent needs a versioned code package. Use Platform Skills when the task requires model-driven reasoning or multi-step orchestration over explicitly declared tools.
### Skill Execution
Platform Skills are orchestrated companion definitions, not a five-tier execution surface. A skill declares its prompt, input and result schemas, model settings, turn and timeout bounds, and the integration or static tools it may call. The Platform API does not currently expose `direct`, `autonomous`, `browser`, or `computer_use` execution-tier fields.
When a declared tool produces a world-model observation, outbound policy evaluates that event separately. Where the private-preview connector review flow is enabled, a configured destination can stage a specific external write proposal rather than changing the observation's confidence.
{% hint style="info" %}
**See also**
* [World Model](/data/world-model) for how events and entities work
* [Clinical Tools](/agent/clinical-tools) for built-in patient lookup, scheduling, and insurance tools
* [Context Graphs](/agent/context-graphs) for how states bind workflow tools
{% endhint %}
# Continuous Improvement
Use production evidence, simulations, and versioned releases to improve agent behavior through an explicit, governed team workflow.
Every interaction can produce evidence about agent behavior: outcomes, metric scores, context graph paths, executed tools, latency, escalations, and operator involvement. Teams use that evidence to decide what to change, verify the change, and release it deliberately.
The platform supports this loop with analytics, evaluations, simulation, configuration versions, and deployment tools. It does not autonomously rewrite agent configuration, promote a candidate, or change world-model confidence policy from an observed correlation.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
measure["Measure\nproduction and tests"] --> investigate["Investigate\nsegments and examples"]
investigate --> change["Author\na versioned change"]
change --> validate["Validate\nin simulation and targeted tests"]
validate --> decide{"Authorized\nrelease decision"}
decide -->|Release| observe["Observe\nproduction results"]
decide -->|Revise| change
observe --> measure
```
## The Improvement Loop
### 1. Measure
Start with evidence that the platform already records:
* Conversation and run outcomes
* Configured evaluation results and metric trends
* Context graph states and executed tool calls when trace evidence is available
* Latency, escalation, and operator-participation signals
* Surface completion and outbound delivery outcomes
Production evaluations can run on demand or after completed conversations when eager evaluation is enabled. Dashboards and APIs expose results over configurable time ranges so teams can establish a baseline before making a change.
### 2. Investigate
Aggregate trends identify where to look; individual interactions explain what happened. Compare periods and relevant segments, then inspect transcripts, executed actions, and trace evidence for representative successes and failures.
Treat a correlation as a candidate explanation, not an automatic configuration instruction. A lower completion rate for one service might reflect a changed caller population, unavailable source data, a tool failure, or agent behavior. Confirm the cause before changing the agent.
### 3. Author a Versioned Change
Make the smallest change that tests the hypothesis. Depending on the finding, that may be a context graph transition, agent instruction, tool binding, service setting, evaluation definition, or test case.
Agents and context graphs use explicit versions, and version sets can pin the versions a service releases. Record related changes to non-versioned settings or evaluation definitions with the same release decision. The Developer Console, Platform API, SDK, and [Agent Forge](/reference/agent-forge) provide interfaces for these resources; none of them releases a change merely because a metric moved.
### 4. Validate Before Release
Use [simulations](/testing/testing/simulations) to exercise the affected paths and compare the candidate against the baseline criteria. Add cases for newly discovered failure modes so the regression remains visible. Use real-audio tests when the change affects speech, timing, or media behavior, and use an isolated integration environment for connector or approval workflows.
Validation should cover both the target improvement and important guardrails. A faster scheduling flow is not an improvement if it lowers information accuracy or increases unsafe escalation behavior.
### 5. Release and Observe
An authorized user decides which tested versions and settings to release. After release, compare the same measures used for the baseline and watch for changes outside the target metric. Retained agent and context graph versions give the team a known configuration to restore deliberately if the release performs worse.
## Multi-Objective Review
Healthcare workflows rarely have one success measure. Define an acceptance set that reflects the actual operating constraints, for example:
* Task completion meets its target
* Safety-critical evaluations remain within policy
* Information accuracy does not regress
* Caller experience remains acceptable
* Duration and cost stay within operating limits
The platform can compute and present these measures, but the team defines the trade-offs and release criteria. There is no autonomous optimizer choosing a configuration on the workspace's behalf.
## What Does Not Feed Back Automatically
Analytics can show that one source, path, or tool correlates with stronger outcomes. That observation does not automatically:
* Change event confidence or source precedence in the world model
* Rewrite context graph transitions or tool order
* Adjust escalation thresholds
* Promote a version set
* Roll back a production release
Those controls remain explicit because an operational correlation is not enough evidence to change a clinical or safety policy.
## Governance
The improvement workflow uses the platform's normal governance boundaries:
* **Permissioned** - Authorized roles control configuration and release actions.
* **Auditable** - Configuration changes and deployment actions retain actor attribution.
* **Versioned** - Candidate and released configurations remain distinguishable.
* **Bounded** - Safety requirements are release constraints, not variables to trade away for a higher average score.
## Building Reusable Evidence
Improvement compounds when teams preserve what they learn:
* Convert production failure modes into permanent simulation cases.
* Keep baseline periods and release criteria with the change record.
* Reuse proven patterns across services only after validating them in the new context.
* Review metrics after each release using the same definitions and segments.
This creates an evidence base that improves future decisions without claiming that the system learns or deploys configuration changes on its own.
{% hint style="info" %}
See [Testing Overview](/testing/testing) for the validation workflow, [Metrics and Quality](/testing/testing/metrics) for evaluation concepts, and [Agent Forge](/reference/agent-forge) for versioned configuration commands.
{% endhint %}
# Overview
How voice, text, messaging, email, and Surfaces deliver a shared workflow while preserving distinct identity, consent, and completion rules.
Channels determine how a workflow reaches a patient and how its responses become speech, messages, or forms. Supported agent paths can reuse agent guidance, Context Graphs, tools, and selected world-model context. Identity, consent, timing, session continuity, and operator controls still belong to the specific path.
A patient might answer a call, complete a browser form, and receive a later reminder. Coordinating that work requires an explicit workflow and shared context; it does not imply one uninterrupted conversation state across every transport.
## How It Works
The [reasoning engine](/agent/reasoning-engine) processes available interaction signals and produces effects such as responses and tool calls. The selected runtime handles the channel's input, delivery, and control behavior. Surfaces provide a separate form-collection lifecycle that can contribute observations to the world model.
When adapting a workflow to another channel, review the information it needs, available tools, consent requirements, identity rules, and evidence of completion. Test those boundaries on the intended path. [How It Works](/platform-overview/how-it-works) follows one operational outcome through the wider system.
## Channel Types
### Phone
[Phone](/channels/voice) provides real-time conversations with speech recognition and generated speech. Supported paths include inbound and outbound calling, interruption handling, optional emotion analysis, and human escalation. Use the voice chapters for the audio pipeline and recordings, and [Operators](/operations-and-safety/operators) for phone-based listen and takeover.
### Text Sessions
[Text Sessions](/channels/text-sessions) explains application-hosted text and durable messaging conversation behavior. Applications and managed channels expose different response and completion contracts. Use this guide to understand continuity, request completion, and background work before implementing the channel-specific integration.
### SMS
[SMS](/channels/sms) uses provisioned sender resources and managed inbound routing. Review registration, consent evidence, content checks, suppression, and delivery receipts before planning outreach. A supplied phone number and a successfully created conversation do not establish permission to send or recipient delivery.
### WhatsApp
[WhatsApp](/channels/whatsapp) uses a business-scoped recipient identity for managed text conversations and applies a free-form reply window. Its separate phone-keyed voice-note operation has its own session and audio-delivery contract. Do not treat the two paths as one shared thread.
### iMessage
[iMessage](/channels/imessage) provides managed messaging through provisioned lines on compatible devices. It uses the durable conversation model with its own provider, media, and delivery boundaries. SMS and iMessage support an explicit switch within a compatible conversation; other channel transitions need their own workflow.
### Email
[Email](/channels/email) has managed sender domains, transactional or marketing use cases, reply threading, and separate delivery and unsubscribe evidence. Its send path is distinct from the Conversations API's outbound-start and channel-switch capabilities. Use the email guide for domain setup and sending behavior.
### Surfaces
[Surfaces](/channels/surfaces) collect structured input in a browser form. A configured workflow can create a form and share its supported email or web link, then use the submitted information. Form creation, link delivery, submission, and world-model projection are separate milestones. A Surface submission is not automatically a dataset-intake file.
### Voicemail
The standalone ringless voicemail channel has been retired. Answering-machine and configured voicemail behavior during a regular phone call remain part of the voice workflow.
## Background Tool Delivery on Non-Live Channels
Live voice, application text, and asynchronous messaging expose different completion contracts. An application turn can complete within its request or require the client to inspect pending work. Managed messaging can attempt a later reply when supported background work completes.
Provider delivery remains separate. Suppression, rejection, retries, or an outage can prevent that reply from reaching the recipient. See [Text Sessions](/channels/text-sessions) and the relevant channel guide for the supported lifecycle.
## Multi-Channel Orchestration
Choose channels through provisioned use cases, authored workflows, triggers, and supported outbound operations. Patient preferences, consent, contact history, and the information being exchanged should inform that configuration.
For each transition, decide which entity and history the next step can access, what starts it, what confirms completion, and who handles a failure. Shared world-model context can support continuity even when the transports retain separate session state. Automatic cross-channel optimization or fallback should not be inferred from that shared context.
### Outbound
[Outbound](/channels/outbound) explains platform-initiated contact and scheduled work. A campaign also needs explicit eligibility, pacing, consent, retry, and exception policy. A channel's availability does not supply those policies automatically.
### Channel Availability
Availability depends on the deployment, geography, provider capacity, and completed provisioning. Managed SMS, iMessage, WhatsApp, and email resources can require Amigo-assisted onboarding. Confirm the intended resources and routing before exercising the workflow.
## Continue the Deep Dive
Read the relevant channel guide for transport behavior, [Runtime Safety](/operations-and-safety/runtime-safety) for enforced and observed controls, and [Testing and Evaluation](/testing/testing) for evidence that covers the actual channel. The [Operating Model](/platform-overview/operating-model) assigns consent, staffing, and exception responsibilities.
# Phone
Real-time phone-based conversations with conference-first architecture, emotion detection, and adaptive voice delivery.
Phone has real-time constraints that asynchronous text does not: callers expect a prompt response, silence can feel like a failure, and vocal delivery affects the interaction. Voice shares the platform's reasoning and Context Graph concepts, while transport, tool exposure, safety controls, and lifecycle behavior still depend on the selected runtime and channel configuration. See [Agent Architecture](/agent/reasoning-engine).
## Conference-First Architecture
Platform-managed phone calls use a multi-party conference for the caller and agent legs. This design lets an authorized human [operator](/operations-and-safety/operators) join a supported call as another participant without replacing the caller's connection.
For outbound calls, session preparation can begin while the destination is ringing. For inbound calls, the conference can hold the caller while the session and greeting become ready, then add the agent leg. These readiness paths reduce first-audio delay, but telephony and dependency latency can still affect when the greeting begins.
When an operator joins, they enter the same conference in a supported listen or takeover mode. Operator access is permission-gated, and the exact join method depends on the configured operator channel.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
C[Caller] <-->|Audio| Conf[Conference]
A[AI Agent] <-->|Audio| Conf
O[Operator] -.->|Joins on\nescalation| Conf
```
## The Voice Pipeline
On the Amigo-managed speech pipeline, a supported call turn flows through five layers that convert caller audio into a spoken response. Layers 1-2 and 5 are voice-specific. Layers 3-4 use the shared [reasoning engine](/agent/reasoning-engine). A service configured for a separate realtime speech provider can follow that provider's audio and turn-processing path instead.
| Layer | What It Does | Scope |
| ------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------ |
| **1. Audio Capture** | Captures the caller's audio stream from the telephony layer. Sends it to two parallel processors: speech-to-text and emotion detection. Neither blocks the other. | Voice |
| **2. Speech-to-Text** | Converts audio to text using streaming transcription with domain-specific vocabulary boosting. Determines when the caller has finished speaking and emits final utterance signals. | Voice |
| **3. Intelligence** | Maintains a short rolling emotional state from acoustic valence, arousal, categorical scores, transcript sentiment, and toxicity. A separate per-call acoustic profile is exposed for observability after warmup. | Engine |
| **4. Navigation and Response** | The context graph engine selects the right action, chooses the appropriate vocal emotion for the response, generates text, and produces filler speech to cover processing time. A unified voice timeline orchestrator coordinates all filler emission, empathy pauses, and tool progress updates through a signal-driven model rather than independent timers. | Engine |
| **5. Text-to-Speech** | Converts the generated text into spoken audio using the emotion selected during navigation, along with pace and emphasis. Each utterance carries its own TTS parameters (emotion and speed), so fillers and responses can use different vocal qualities without interference. Streams audio back to the caller through the conference. | Voice |
If the navigation model times out or its configured identifier is unavailable, the engine can try a configured fallback model. Voice filler may cover part of that delay. If no fallback succeeds, navigation remains in the current engageable state rather than claiming that the turn advanced.
After the call ends, optional background jobs can verify the caller transcript and score the interaction across quality dimensions when recording and analysis are enabled. Accuracy evidence and suggested keyterms are review inputs; they do not update transcription configuration automatically.
The separate realtime-provider runtime builds workflow instructions from a Context Graph with exactly one action state. That state's objective, action descriptions, and guidelines become instructions for the provider's model. If instruction preparation fails, the call can continue with fallback instructions, so a connected call does not prove the intended workflow loaded. Multi-state navigation, operator takeover, and session event injection from the platform-managed pipeline do not carry over to this runtime. Validate the intended workflow and escalation path on the selected runtime before launch.
## Patient Context Injection
When a call connects, the agent can use the caller's phone number to look up an existing workspace entity. If a matching entity and authorized data are available, selected demographics and clinical or operational context can be included in the session. Unknown callers and incomplete source data are valid outcomes and must not be treated as identity verification.
The runtime can refresh session context after supported writes, but connector projections and external systems may be eventually consistent. Agents should verify time-sensitive facts through the appropriate source rather than assume every write is immediately visible everywhere.
## Session Event Injection
External systems can inject events into supported platform-managed voice sessions in real time. When delivery and response generation succeed, the agent can speak a response. The separate realtime-provider runtime does not process these injections.
| Type | Behavior | Use Case |
| ------------------ | ---------------------------- | ------------------------------------------------------------------- |
| **External event** | Queues behind current speech | EHR notifications, appointment confirmations, system status updates |
| **Guidance** | Interrupts current speech | Operator steering, real-time instructions to the agent |
Events can be injected through multiple paths: an HTTP endpoint, a WebSocket control channel, or through the platform API. The platform API also provides a dedicated [operator guidance](/operations-and-safety/operators) endpoint so operators can send guidance scoped to their identity and permissions.
The injection path supports multi-instance deployments by relaying commands to the session owner. Delivery and reconnection are still subject to session state, authorization, network conditions, and the lifecycle of the active call.
## Operational Impact
For healthcare organizations, voice agents can augment front-desk workflows such as scheduling, benefits intake, refill-request collection, and general inquiries. The actions available in a specific deployment depend on the configured context graph, tools, integrations, permissions, and safety controls. Supported workflows can route or escalate to a human operator.
Calls emit lifecycle and conversation data to the [world model](/data/world-model). Conversation-derived observations remain source-attributed and are evaluated by outbound source, confidence, schema, and destination policies before any eligible external write. Automated delivery outcomes are reported separately and are not treated as confirmed when a destination call fails. Review-gated external write proposals are a separate private-preview path for configured mutations.
## Phone Numbers
Phone numbers are the entry point for inbound calls. Each number is provisioned through the platform and routed to a specific service.
### Provisioning and Lifecycle
Numbers follow a four-step lifecycle: **search** provider inventory, **purchase** an eligible number, **assign** it to a use case or service, and **release** it when no longer needed. Multiple numbers can route to the same service - for example, different clinic locations sharing one scheduling agent.
Four number types are represented by the provisioning API. Inventory varies by country and provider:
| Type | Use Case |
| ------------- | --------------------------------------------------------- |
| **Local** | Geographic numbers tied to a specific area code or region |
| **Mobile** | Mobile numbers, common in markets outside North America |
| **Toll-free** | Free-to-caller numbers for national reach |
| **National** | Non-geographic national numbers in supported countries |
Search can filter by country, type, required capabilities, and - for local numbers - area code. An empty result means no matching inventory was returned; it does not guarantee that a type is permanently unavailable in that country.
### Channel Management
Phone-number provisioning is gated by an approved business profile and any compliance bundle required for the requested country, number type, and business use. Requirements are conditional; not every number is eligible for the same voice-branding or messaging programs.
For US voice numbers, caller-authentication enrollment applies to supported local and toll-free numbers. Display-name registration applies to eligible US standard long-code numbers, not US toll-free or Canadian numbers. Other countries can require provider-defined regulatory bundles and supporting documents. The platform resolves the applicable bundle before purchase and blocks provisioning until required approvals are present.
Messaging compliance is separate from voice provisioning. US long-code application-to-person messaging uses a brand-and-campaign flow, while US and Canadian toll-free messaging uses toll-free verification. A number having SMS capability does not mean it is approved for every messaging use case.
Some inventory requires a local, foreign, or other approved address. Search excludes numbers the setup cannot satisfy where possible, and purchase validates the stored business address against the selected number's requirement.
The number-purchase operation compensates for provider-side changes when a later step in that purchase fails. Compliance submissions have their own asynchronous review states and may require corrected information or resubmission. Approval or registration does not guarantee a particular carrier display, attestation treatment, answer rate, or spam-classification outcome.
### Routing
When a call arrives on a provisioned number, the platform routes it to the service associated with that number. The service association determines:
* Which context graph governs the conversation flow
* Which voice settings (tone, speed, key terms) apply
* Which world model workspace provides patient context
* Which escalation rules and authored safety instructions or guardrails apply
Each phone number routes to exactly one service. This keeps the mapping simple - if you need to know what a number does, look at its service assignment.
{% hint style="info" %}
**Developer Guide** - For phone number API endpoints and voice agent integration details, see the [Developer Guide](https://docs.amigo.ai/developer-guide/platform-api/conversations/voice-agent).
{% endhint %}
## Learn More
{% content-ref url="/pages/diNa7vR8bPyfaSkKqKHe" %}
[Audio Pipeline](/channels/voice/audio-pipeline)
{% endcontent-ref %}
{% content-ref url="/pages/aYU0aijmZffitKIRNaTq" %}
[Emotion Detection](/channels/voice/emotion-detection)
{% endcontent-ref %}
{% content-ref url="/pages/IeSDYAEqjzKUcXkDFduG" %}
[Compound Emotions](/channels/voice/compound-emotions)
{% endcontent-ref %}
{% content-ref url="/pages/nRAlEc8vAwxClF3hhQFs" %}
[Call Recordings](/channels/voice/recordings)
{% endcontent-ref %}
# Audio Pipeline
How speech recognition, emotion detection, filler speech, barge-in detection, and TTS work together in real time.
## Browser Recording Sessions
Clinical recording sessions support a browser-based capture path where the provider's microphone audio streams to the platform over a resumable WebSocket connection. The protocol supports pause, resume, and reconnect so that transient network interruptions do not lose accumulated transcript state.
Key characteristics:
* **Resumable.** If the connection drops, the browser SDK can reconnect to the same session. The worker rehydrates prior transcript segments and resumes from the last acknowledged audio position.
* **Pause and resume.** A provider can pause recording, which flushes a transcript snapshot and releases the upstream transcription resource. Resuming opens a fresh transcription connection while preserving segment ordering.
* **Structured lifecycle.** Each connection validates session ownership and state before accepting audio. Typed close codes distinguish clean completion, recoverable disconnects, and fatal errors so the client can respond appropriately.
* **Fenced state transitions.** Concurrent or stale connections cannot overwrite state owned by a newer attach, preventing split-brain scenarios during reconnect sequences.
The audio pipeline converts a caller's voice into text, processes the transcript through the agent's reasoning, and converts the response back to speech. Speech recognition, optional emotion analysis, tool execution, and speech output have separate responsibilities, but required model, tool, or transport work can still delay or fail a turn.
Each voice session manages four user-visible concerns:
* **Listen** - Capture caller speech and detect when the caller has finished a turn.
* **Understand** - Produce transcripts and emotional context for the agent.
* **Decide** - Use the current context graph, patient context, and tool results to choose the next response.
* **Speak** - Deliver the response with the right timing, voice, and interruption behavior.
This design lets Amigo update recognition, emotion detection, and response generation independently while preserving a consistent call experience for the patient.
## Signal Capture
Audio arrives from the telephony layer as a standard telephony audio stream. The system splits it into two parallel paths the moment it arrives:
1. **Speech-to-text** - Converts audio to transcript text in real time
2. **Emotion detection** - Analyzes vocal qualities for emotional signals (covered in [Emotion Detection](/channels/voice/emotion-detection))
The optional emotion path is isolated from speech recognition, so its failure does not stop transcription. Emotion analysis may still receive audio when transcription fails, but a live agent turn generally cannot proceed without usable caller text.
### Progressive Initialization
The runtime prepares configuration, tools, integrations, and greeting audio before the agent begins the live exchange. Speech recognition and the optional emotion stream initialize alongside the rest of the session.
For outbound calls, preparation can run while the destination is dialing or ringing. For inbound conference calls, the caller can remain on hold while preparation completes and the agent leg is created. These paths reduce startup delay but do not guarantee zero wait under all network or dependency conditions.
The runtime connects speech recognition before it begins forwarding caller audio. Emotion analysis connects after STT and is non-fatal: if that optional stream is unavailable, the call continues without emotion-derived steering.
### Greeting
The agent can prepare and play the greeting while the speech recognition setup task is running. Caller audio waits for the STT-ready signal before it is forwarded, preventing a partially initialized recognition stream from receiving audio.
For conference-mode calls where the agent leg is created during ring time, the platform waits for the caller to actually join the conference before releasing the greeting. This prevents the greeting from playing into an empty conference.
### Speech Handling
Caller speech can be recognized during the greeting once speech recognition is ready. The opening uses the same service-level minimum speech duration and applicable state barge-in policy as later speech. There is no separate greeting shield that discards all caller input until the greeting finishes. Test simultaneous greetings and short interruptions with the deployed voice configuration.
## Speech-to-Text
The speech-to-text stage converts caller audio into text transcripts in real time. On the multilingual recognition path that supports language consolidation, detected language observations can narrow recognition hints and update the speech-output language after enough consistent evidence is available. Other speech-recognition providers do not expose the same mid-call controls.
Amigo uses streaming speech recognition for real-time transcription. Latency varies with provider, language, network conditions, audio quality, and end-of-turn detection; the platform does not promise a fixed per-segment transcription latency.
The default recognition path can accept mid-call updates to keyterms, end-of-turn sensitivity, and language hints. Support is provider-dependent: a routed provider may accept only a subset of these controls or ignore a control it cannot apply.
### Provider Routing
The platform supports multiple speech-to-text engines and selects one at session setup using resolved language, deployment availability, audio encoding, and an optional workspace preference. A workspace preference is honored only when that provider is enabled and compatible; otherwise routing falls through to the deployment's normal selection chain. This is setup-time selection, not a guarantee of live provider failover after a recognition session has started. Operator audio follows a fixed policy rather than the caller's workspace override.
### Language Selection
The platform supports English-optimized and multilingual STT models, selected per-service:
| Setting | Model | Best For |
| ---------------- | ------------------------------------- | ------------------------------------------------------------ |
| **English** | English-optimized (lowest error rate) | Monolingual English-speaking populations |
| **Multilingual** | Multi-language with code-switching | Populations that switch between languages mid-conversation |
| **Auto** | Multi-language with auto-detection | Unknown caller language; narrows automatically once detected |
In auto mode on the compatible multilingual recognition path, the platform tracks reported languages across turns. Once one language has enough consistent support, it narrows language hints and notifies the speech-output path. This can improve recognition focus, but it is not a formal language-identification guarantee.
When an already-resolved entity has a language value in the [world model](/data/world-model), session setup can use it before speech begins. The priority order is entity language, then workspace voice language, then the deployment default. A stored language is a routing hint and should not be treated as proof of the caller's preference for the current interaction.
### Keyterm Boosting
Medical terminology, provider names, medication names, and organization-specific vocabulary are difficult for general-purpose speech recognition. Three layers of keyterm boosting improve recognition accuracy:
| Level | Managed By | Scope |
| ------------------- | ------------------------ | ---------------------------------------------------------- |
| **Service-level** | Workspace administrators | Applied to all calls for a given service |
| **Workspace-level** | API configuration | Per-workspace vocabulary (clinic names, local terminology) |
| **System defaults** | Amigo engineering | Baseline medical and scheduling vocabulary |
The configured layers are merged and deduplicated during session setup. When an existing caller entity resolves, selected medication, allergy, and condition terms can be added to the active recognition session. Whether those keyterms affect transcription depends on the selected provider's capabilities.
### End-of-Turn Detection
The system must determine when the caller has finished speaking so the agent can respond. This uses configurable confidence thresholds that balance two concerns:
* **Responding too early** cuts the caller off mid-sentence
* **Responding too late** creates awkward silence
Base end-of-turn controls come from the deployment and optional per-service voice settings. Context graph states can add compatible turn-policy overrides:
* **Data collection states** (collecting a date of birth, spelling a name) use higher thresholds and longer silence timeouts, because the caller is thinking and pausing between pieces of information
* **Action states** (confirming an appointment, answering a yes/no question) use default thresholds for snappy turn-taking
These overrides take effect on state transitions - when the agent moves to a data collection state, the STT engine reconfigures mid-call to be more patient with pauses.
#### Final Turn Boundary
Navigation starts only after the speech recognizer emits its final end-of-turn event. Earlier eager-end and resumed-turn signals are retained for observability, but they do not launch or cancel speculative navigation. This avoids spending a model call on an incomplete utterance while keeping turn-detection behavior measurable.
## Text-to-Speech
The TTS engine converts generated text into spoken audio. Response and filler utterances can carry their own emotion and speed values, while voice identity, volume, language, and other settings come from the resolved provider configuration. Speech synthesis is streamed, so audio can begin before the complete response text is available.
### Provider Selection
The platform supports multiple TTS providers through layered workspace, agent, service, and per-language configuration. Provider capabilities differ in latency, voice selection, expressive controls, pronunciation support, language coverage, and timing metadata. The Developer Console can expose available voices and previews for configured providers, while the API and agent configuration carry the provider-specific settings.
Provider-specific settings are resolved only for the selected provider, which prevents configuration fields from one provider leaking into another. Selecting an unknown provider name falls back to the deployment default during setup, but an outage in the selected live provider can still delay or fail speech. The current agent voice path uses 8 kHz mu-law audio across supported STT, TTS, and transports. Provider choice can still change voice quality, language behavior, expressive controls, and timing evidence.
### Per-Language Provider Routing
The platform supports routing text-to-speech to different providers based on the caller's detected language. This is configured through a language-provider map that associates language codes with specific TTS providers and voice configurations.
When a caller's language is detected, the platform resolves the TTS provider through a priority matrix:
1. **Exact language match** - e.g., `ar-SA` matches an Arabic (Saudi Arabia) entry
2. **Base language match** - e.g., `ar-SA` falls back to an `ar` entry
3. **Multilingual fallback** - a catch-all entry for any language not explicitly mapped
At each level, service configuration takes priority over agent configuration, which takes priority over workspace configuration. The first match wins.
If no language-specific entry matches, the platform uses the standard TTS provider selection (service > agent > workspace > default). Per-language configuration is isolated - when a language-specific provider is selected, only that entry's voice settings are used, preventing configuration for one provider from affecting another.
### TTS Tone Resolution
The response utterance first uses the emotion selected by navigation, when navigation returns one. Otherwise, the runtime uses the computed voice context:
1. After at least two acoustic segments, a sufficiently strong rolling emotion maps to an empathetic provider tone. Anger and Disgust map to calm delivery, Fear and Sadness map to sympathetic delivery, and Joy maps to enthusiastic delivery.
2. If the current rolling signal is weak or unmapped, tone momentum retains the previous successfully mapped emotion-derived tone.
3. If no emotion-derived tone exists, a current context-graph action that matches a configured sensitive topic can select sympathetic delivery.
4. A configured workspace tone overrides the computed voice-context tone.
5. If no turn-specific tone is set, the TTS provider keeps its configured baseline or default.
There is no separate vocal-burst model or burst-first tone rule in the live pipeline. Tone momentum also does not carry arbitrary navigation choices forward; it stores only the last tone derived by the rolling emotional state.
## Conversation Dynamics
Recognizing speech and synthesizing it are only part of the job. The pipeline also manages the moment-to-moment dynamics of the conversation: which models handle each turn, how the agent adapts to the caller's state, what the caller hears while tools run, when the agent yields the floor, and how the call ends.
### Split Model Architecture
Navigation and response generation can use different model preferences:
* **Navigation** returns a constrained state-routing decision and is commonly tuned for latency and consistency.
* **Response generation** produces caller-facing text and tool calls and is commonly tuned for response quality.
The configured models, observed latency, and output quality depend on the active version set. Model-backed routing and response generation remain probabilistic.
### Situation-Response Adaptation
The voice pipeline adapts across four independent dimensions simultaneously. Each dimension operates on different output channels, so the agent can change *what* it says, *how* it says it, and *whether* it fills silence - all independently and in real time.
#### Emotion → Voice Tone
The agent mirrors empathy, not the caller's emotion. An angry caller hears a calm voice (de-escalation), not an angry one. An anxious caller hears a sympathetic voice (reassurance). A happy caller hears enthusiasm (matching energy).
#### Emotion → Filler Behavior
Filler speech adapts to the caller's emotional state. Anxious callers hear reassuring fillers ("Of course," "I'm here to help"). Frustrated callers with high arousal hear no fillers at all - the system suppresses them because frustrated callers want answers, not acknowledgments. Happy callers hear warm, matching fillers.
#### Emotion → Response Content
Once at least two acoustic segments are available, non-neutral rolling state or tracked behavioral signals can add emotional trend and adaptation guidance to the response prompt. Deteriorating negative state prioritizes empathy and resolution speed. Neutral, stable state without behavioral signals adds no emotion guidance.
#### Behavioral Signals → Response Content
Three behavioral signals - interruption count, short response streaks, and silence gaps - are tracked in real time and injected into prompts when thresholds are crossed, augmenting the emotion detection system with patterns that never appear in vocal tone. See [Behavioral Signals](/channels/voice/emotion-detection#behavioral-signals) for the signals, thresholds, and how the agent responds.
### Response Micro-Behaviors
The voice channel prompt instructs the response model to use communication patterns such as:
* **Speech rhythm mirroring** - Short bursts from the caller produce concise responses; conversational callers get warmer, flowing replies
* **Emotional name usage** - The caller's name is used at moments of emotional significance, not mechanically
* **Pause injection** - When delivering difficult information, the agent pauses naturally before the key detail
* **Pace inversion** - When the caller is rushing, the agent slows down with longer sentences and gentle transitions
* **Completion inference** - When a caller trails off mid-sentence, the agent acknowledges what they were trying to say
The prompt instructs the agent not to mention emotion detection. Because response generation is model-backed, teams should validate this behavior in simulations and production review rather than treat a prompt instruction as an absolute control.
### Voice Timeline
The voice pipeline applies the same [cut/navigate/engage](/agent/reasoning-engine#cut-navigate-engage) pattern that drives conversation-level reasoning - but within each turn, managing what the caller hears and when.
Fillers, responses, empathy pauses, and tool progress narration are treated as states in one timeline. "Let me check on that" followed by "Her appointment is Thursday" is one conversation trajectory in two parts, not two unrelated audio events.
#### Three Operations
1. **Cut** - A supported timing or session signal creates a new voice-timeline boundary. Signals that do not require a transition leave the current timeline state unchanged.
2. **Navigate** - Given the compressed state and the trajectory of previous states, select the next voice state. Navigation does not directly produce audio; engagement turns the selected state into an utterance.
3. **Engage** - Prepare an utterance with its own emotion, pace, and timing policy. If the main response is still pending, the voice timeline can move through filler, progress, or hold states without losing the caller's place.
#### Signal-to-State Mapping
Each signal produces a specific voice state:
| Signal | Voice State | What Happens |
| ---------------------------- | ----------- | ----------------------------------------------------------------------- |
| **Caller finished speaking** | Breath | Brief pause before the agent responds |
| **Navigation complete** | Transition | Filler window opens if the response is not ready |
| **Tool started** | Progress | Tool wait narration on a repeating interval ("Let me check on that...") |
| **Tool finished** | Response | Agent delivers the tool result |
| **All audio finished** | Listen | Silence deadline starts - check-ins escalate if the caller stays quiet |
| **Empathy tier shifted** | Hold | Intentional silence - the agent pauses to give the caller space |
| **Caller started speaking** | Listen | Pending fillers drain - the caller has the floor |
| **Deadline expired** | Next state | Self-signal - the actor re-enters cut/navigate/engage |
Timing policies are what make this self-driving. A transition state can wait briefly for the real response, play a filler when the response is not ready, or hold silence when empathy calls for it. If the response arrives first, the pending filler is skipped.
#### Per-Utterance Voice Parameters
Each utterance carries its own emotion and speed, set when the utterance is prepared. This keeps filler speech, progress narration, and final responses from overwriting one another when they are close together in time.
#### Voice Timing Configuration
The voice timeline exposes two categories of configuration per service:
**When** - timing policies for pauses, filler windows, progress narration, empathy holds, and cooldowns.
**What** - vocabulary and style:
| Parameter | What It Controls |
| ----------------------- | ------------------------------------------------------------- |
| **Filler style** | Phrase, backchannel, or silent (see below) |
| **Filler vocabulary** | Custom backchannel words ("Mm," "Yeah," "Mhm") |
| **Progress vocabulary** | Custom tool-wait phrases ("One moment...," "Let me check...") |
These settings shape the timeline, while the runtime still applies bounded queues, cooldowns, lifecycle checks, and error handling.
#### Filler Styles
The service schema accepts three filler-style values, but their current runtime behavior is not fully symmetric:
| Style | Behavior | Best For |
| --------------- | ------------------------------------------------------------------------------------- | ------------------------------------------ |
| **Phrase** | Currently advisory; it follows the normal autonomous filler path | Reserved for phrase-oriented configuration |
| **Backchannel** | Currently follows the same normal autonomous filler path | Default non-silent behavior |
| **Silent** | Suppresses autonomous navigation backchannels and ordinary tool-wait acknowledgements | Services that prefer no autonomous filler |
`silent` removes autonomous filler prompt pressure and audio in the normal path. Explicit deterministic progress phrases authored on a context-graph tool binding remain intentional script and can still play. Receipt and working fillers inherit the resolved utterance tone and speed when those values are present. Service filler vocabulary affects navigation backchannels; tool-wait vocabulary is configured separately.
When navigation is skipped - typically in single-action context graphs where the agent always stays in the same state - the orchestrator starts a short timer (configurable per service). If the response has not produced audio by the time the timer fires, a backchannel sound plays to hold the conversational rhythm. If the response arrives first, the timer is cancelled. Services using the "silent" filler style suppress this timer entirely.
#### Empathy-Gated Filler Behavior
Filler behavior is controlled by the caller's [empathy tier](/channels/voice/emotion-detection#empathy-tier-classification). Higher tiers can add an intentional hold or suppress fillers:
* **T0-T1** - Normal filler emission. At T1, the filler type is set to "empathy" (warmer, acknowledging) rather than "receipt" or "working."
* **T2 Full Empathy** - The voice timeline applies an empathy hold and the response prompt must lead with empathy. An empathy filler may still be used.
* **T3 Hold Space** - Fillers are suppressed entirely. The agent pauses, then delivers a pure empathy response.
The tier is assigned at the caller's final turn boundary and sent to the voice timeline before navigation completes for that turn.
Empathy fillers are marked separately from receipt and working fillers so the speaker can use slower delivery when no per-utterance speed is already present. Per-utterance tone and speed from the voice timeline take precedence over the speaker's fallback filler adjustments.
#### Principle-Based Filler Generation
Navigation can return a contextual filler using the current action and available emotional guidance. When navigation is skipped or retried, the runtime uses bounded backchannel or retry vocabularies instead. Tool-wait progress uses authored phrases or deterministic templates rather than making another model call on the voice latency path.
Autonomous navigation acknowledgements use cooldowns and a bounded retry count to prevent a burst of overlapping fillers. Tool-progress narration follows its own trigger and interval policy and can continue while a long-running tool remains active; later attempts reuse the final configured or templated pattern.
#### Tool-Wait Progress Hints
Fillers emitted while a tool is running can be shaped per state and per tool, not just per service. A progress hint describes *the shape of the wait* rather than supplying a phrase list: what kind of work the tool is doing (record lookup, write, external call, computation, multi-step workflow), roughly how long it is expected to take, and how the agent should cover the wait (`auto`, `verbal`, `backchannel`, or `silent`).
The orchestrator turns the hint into utterances using authored phrases, progress class, attempt count, and the active voice style. Later attempts use attempt-aware templates such as an acknowledgement followed by a continuing-status update. A tool-level hint field-merges with the state's channel-level hint, so individual tools need to override only the fields that differ.
For tools with expected latency of four seconds or more, a custom phrase can override the generated progress text. This gives agent engineers precise control over what callers hear during long waits - for example, a tool that queries multiple external systems. The custom phrase is bounded to 30 words and requires a progress class as fallback.
Tool-start signals hand progress narration to the voice timeline, which avoids a second independent tool-wait filler loop. Authored deterministic phrases remain part of that same timeline.
#### Result Persistence Modes
Tool call specs support a `result_persistence` setting that controls how tool results accumulate in the agent's prompt context:
| Mode | Behavior | Best For |
| ------------------------ | ------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------- |
| **accumulate** (default) | Every tool result is retained in the prompt history | Tools called once or a few times per conversation |
| **override** | Only the latest result per tool name is retained; previous results for the same tool are replaced | Polling tools called repeatedly (availability checks, status lookups) where only the most recent result matters |
Both modes retain every call in the conversation journal; override changes prompt rendering. The [ephemeral mode](/agent/context-graphs#tool-result-persistence) is limited to inline text and simulation. A voice session rejects a graph containing an ephemeral binding during initialization.
Override mode prevents context bloat from tools that the agent calls multiple times during a conversation. A scheduling agent that checks availability five times during a complex multi-provider booking only carries the most recent availability snapshot in its context, not all five results stacked up. This keeps the prompt focused and reduces token usage without losing the information the agent actually needs.
### Context Window Management
The engine compares the most recent model request's input-token count with the configured context-window size. This measures the prompt that must fit now rather than cumulative usage across earlier calls.
When the current prompt reaches the compaction threshold (80% by default), the engine ratchets the session into compact history mode and caps retained prompt-history entries. Recent context stays detailed while older state groups are summarized. The policy does not create a separate warning tier or automatically escalate the call to an operator.
### Barge-In Detection
If the caller starts speaking while the agent is talking, the system needs to decide whether to stop the agent's audio. Barge-in uses semantic confirmation - it requires actual recognized words rather than just acoustic energy. This reduces noise-triggered interruptions, though background speech and recognition errors can still produce false triggers.
The main detection path evaluates these conditions together:
1. Whether the caller's speech contains actual recognized words from the speech-to-text engine (not breathing, echo, or background noise). Voice activity detection alone is not sufficient - the system requires at least one recognized word before triggering a barge-in.
2. Whether the speech has lasted long enough with recognized words (minimum duration is configurable per service). The default minimum is 500ms. Shorter acknowledgments do not meet that duration gate unless the service configures a lower threshold.
3. Whether the cooldown period has elapsed since the last barge-in (configurable per service, prevents rapid false triggers)
4. Whether the agent is currently speaking
5. Whether the active turn policy allows barge-in
When all conditions are met, the agent's audio stops and the system returns to listening mode. This prevents the agent from talking over a caller who is trying to ask a question or correct a misunderstanding.
There is also a fast path for end-of-turn interrupts. When the speech engine produces a complete transcript with an end-of-turn signal while the agent is speaking, the recognition listener can interrupt playback without waiting for the transcript to pass through the processing queue. This fast path still checks the minimum speech duration and active barge-in policy.
### Response Length Enforcement
Supported TTS paths enforce per-service sentence and word caps while consuming the streamed model response. Once a cap is detected, the runtime stops accepting further response text for speech. Counting occurs on streamed text fragments, so the boundary is a practical output guard rather than a linguistic parser with perfect sentence segmentation.
### Call Completion
When the agent reaches a terminal state in the context graph and decides to end the call, it signals its intent to hang up but does not disconnect immediately. The system waits for signal convergence: the agent's closing utterance must finish playing and any in-flight tool results must resolve before the call disconnects. If the caller speaks during this window (barge-in) or a transfer is initiated, the hangup intent is retracted and the conversation continues.
This is designed to let the closing message and pending tool work settle before disconnect. Transport failure or caller hangup can still end the call earlier.
## Per-Service Voice Configuration
Voice behavior is configurable at the service level, allowing different services within the same workspace to have different voice characteristics. Unset fields do not all fall through one three-level hierarchy: provider and TTS fields use their field-specific service, agent, workspace, and environment rules; service tuning fields use documented runtime defaults or supported fallbacks; and Context Graph `TurnPolicy` controls separate per-state behavior. See [Voice Control Plane](/agent/reasoning-engine#voice-control-plane). Per-service settings cover:
* **Filler behavior** - Silent versus normal autonomous filler behavior, navigation vocabulary, tool-progress vocabulary, and backchannel timing
* **Barge-in sensitivity** - Minimum speech duration and cooldown period
* **Response limits** - Maximum sentences and words per response
* **End-of-turn detection** - Eagerness threshold and timeout
* **TTS settings** - Model selection and buffer delay
* **Voice timing** - The "when" and "what" knobs described in [Voice Timing Configuration](#voice-timing-configuration) above
* **Call forwarding** - A service forwarding configuration enables transfers and explicitly selects warm or cold transfer. A fixed destination uses the configured number; a dynamic destination requires the agent to supply an E.164 number. Forwarding destinations do not cascade from workspace settings. See [Warm Hand-Off](/operations-and-safety/operators#warm-hand-off).
These settings are managed through the Platform API and the Agent Forge CLI.
## After the Call
{% hint style="info" %}
The real-time STT stream prioritizes speed over accuracy. Post-call re-transcription catches words the live stream may have missed.
{% endhint %}
**Transcript verification.** When enabled and a recording is available, a background pass creates another caller transcript with word timing and compares it with the live transcript. The platform stores the result and comparison measurements when processing succeeds. The second transcript is review evidence, not guaranteed ground truth, and it does not automatically change configured keyterms.
**Quality analysis.** When enabled, recording-based analysis scores five dimensions - task completion, information accuracy, conversation flow, error recovery, and caller experience - and can return an outcome, observed issues, and suggested recognition keyterms. Processing is asynchronous and best-effort; suggestions do not automatically update voice configuration.
**Terminal intelligence.** At call end, the primary voice runtime can derive a summary from observed session state: available emotion evidence, latency, conversation shape, tool performance, and operator involvement. A rule-based 0-100 quality score summarizes operational friction from the evidence available on that runtime path; it is not a clinical score or a complete measure of outcome quality.
The scoring dimensions, intelligence summaries, and the APIs that expose them are covered in the Call Intelligence section:
{% content-ref url="/pages/mdQhKn4ilaVQsyr2OUGh" %}
[Intelligence Overview](/intelligence-and-analytics/intelligence)
{% endcontent-ref %}
# Emotion Detection
How acoustic emotion scores, transcript analysis, rolling state, empathy tiers, and voice steering work in the live voice runtime.
When emotion detection is enabled, the primary voice runtime analyzes caller audio and transcript text without putting either path on the critical path for speech recognition. The resulting signals can shape response guidance, filler behavior, and text-to-speech delivery. They are probabilistic conversation signals, not clinical assessments.
## Live Signal Flow
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
audio["Caller Audio"] --> segment["Voiced 2-Second Segments"]
segment --> categorical["Categorical Acoustic Model\n9-Class Scores"]
segment --> dimensional["Dimensional Acoustic Model\nValence + Arousal"]
segment --> profile["Per-Call Acoustic Profile"]
transcript["Final Transcript"] --> language["Sentiment + Toxicity"]
categorical --> state["Rolling Emotional State\n4 Segments, About 8 Seconds"]
dimensional --> state
language --> state
state --> empathy["Empathy Tier"]
state --> tone["Prompt + TTS Steering"]
state --> compounds["5-Turn Compound Resolver"]
profile --> observer["Live Observer Payload"]
state --> observer
```
There is no separate live vocal-burst classifier. Sighs, laughs, gasps, cries, and similar sounds are not routed through a dedicated burst model or a burst-first TTS priority path.
## Acoustic Analysis
The emotion path processes short voiced segments and skips audio below its silence threshold. Segmentation and analysis run independently from live transcription.
The service combines two acoustic outputs:
* **Categorical classification** - Nine scores: angry, disgusted, fearful, happy, neutral, other, sad, surprised, and unknown.
* **Dimensional inference** - Continuous acoustic attributes. The voice agent maintains valence and arousal in its rolling state and uses them for downstream guidance.
The rolling runtime label is derived from the combined dimensional region rather than assuming that the largest categorical score is authoritative, especially when the categorical distribution is nearly flat.
The agent maps the nine categorical labels into its runtime vocabulary. For example, `angry` becomes `Anger`, `happy` becomes `Joy`, and `neutral` becomes `Calmness`. The `other` and `unknown` classes are mapped to a non-emotional placeholder and excluded from the displayed score distribution.
{% hint style="info" %}
Dominance is not maintained as a live rolling-state or empathy-control dimension. Do not rely on it for agent behavior in the current runtime.
{% endhint %}
## Transcript Analysis
Final caller transcripts are also sent to the emotion service. A separate text path returns:
* **Sentiment** - one score from negative to positive
* **Toxicity** - category scores such as toxicity, threat, insult, and identity attack
Transcript analysis is asynchronous and best-effort. If it fails, the call continues with acoustic and transcript content still available to the rest of the voice pipeline.
The text path does not return a second set of named emotions. Labels such as Masked Distress, Cold Hostility, and Sarcasm are derived later by the compound resolver from relationships among sentiment, toxicity, valence, and arousal.
## Speaker Profile
The emotion service builds a per-call acoustic profile from each analyzed segment. It tracks:
* Relative energy
* A pitch-related acoustic proxy
* A speech-rate-related acoustic proxy
After five analyzed segments, approximately 10 seconds of voiced audio, the service emits normalized deltas relative to that caller's running baseline. It can also report whether recent energy is rising, falling, or stable.
These speaker-profile values are currently observability data. They appear in the live emotion payload after warmup, but they are not fed back into acoustic inference, the rolling emotional state, empathy classification, or the compound resolver.
## Rolling Emotional State
The voice agent keeps at most four recent acoustic segments, approximately eight seconds of voiced audio. Valence and arousal are averaged with linear recency weights, so newer segments influence the state more than older ones.
The rolling state derives a dominant runtime label from the aggregated valence-arousal region. It also applies two cross-channel checks:
* Mildly negative acoustic valence requires negative transcript sentiment before the state commits to Sadness.
* High toxicity with negative sentiment can replace an otherwise calm or positive label with Hostility or Contempt.
Trend classification starts once four segments are available. It compares the first and second halves of the four-segment window and reports improving, stable, or deteriorating.
### Signal Boundaries
| Signal | Current Use |
| ------------------------------- | -------------------------------------------------------------------------------------- |
| **Categorical scores** | Per-segment observer data and current-turn compound dyads |
| **Rolling valence and arousal** | Empathy classification, prompt guidance, TTS tone selection, and compound trajectories |
| **Dominant runtime label** | Prompt annotations, empathy checks, TTS tone mapping, and call summary |
| **Trend** | Prompt guidance and call summary |
| **Sentiment and toxicity** | Cross-channel label checks, compound signals, observer data, and call summary |
| **Coherence** | Diagnostic agreement score in observer data and the terminal emotion summary |
| **Speaker profile** | Live observer data after warmup |
The terminal emotion summary stores aggregate evidence, including the final dominant label, average valence and arousal, peak negative valence, shift count, final trend, segment count, behavioral counters, coherence, sentiment, and toxicity. It is not a guaranteed per-segment timeline.
## Empathy Tier Classification
Before navigation for each caller turn, a rule-based classifier assigns one of four empathy tiers. It uses the current transcript plus the rolling valence, arousal, dominant label, and recent acoustic valence history. It does not make an additional model call.
| Tier | Name | Runtime Behavior |
| ---- | ---------------- | ---------------------------------------------------------------------------- |
| T0 | **Functional** | Normal task-oriented response and filler behavior |
| T1 | **Light Touch** | Empathy-oriented filler content before normal task content |
| T2 | **Full Empathy** | A configured empathy hold and an empathy-first response prompt |
| T3 | **Hold Space** | A longer hold, filler suppression, and no task advancement for that response |
The classifier checks higher tiers first:
* **T3** - Explicit crisis or loss language and implicit grief markers such as funeral, bereavement, hospice, or palliative-care context
* **T2** - Strong negative valence; Fear or Sadness with agreeing negative valence; three recent negative acoustic valence readings; distress, helplessness, or financial-distress language
* **T1** - Mild negative valence, mild concern language, concern for a dependent, vulnerability cues, or negative high arousal
Negation, figurative crisis phrases, and resolved past-tense statements are filtered before keyword rules are applied. For example, "I'm not worried," "dying to know," and "I was worried but I'm fine now" do not take the same path as current distress.
The empathy tier is classified before the current turn's compound snapshot is created. Compound scores do not raise or lower the empathy tier in the current runtime.
### Empathy Baseline
The controller keeps a separate empathy baseline so delivery does not snap back immediately after a difficult turn. Each tier contributes a bounded signal, and the baseline decays across later caller turns. When elevated, it can reduce configured TTS speed, subject to the service's minimum-speed floor.
## Behavioral Signals
The rolling state also tracks caller behavior:
| Signal | Rolling-State Threshold | Prompt Effect |
| ------------------------- | ----------------------------------------------- | ------------------------------- |
| **Barge-ins** | 2 or more during the call | Notes repeated interruptions |
| **Short response streak** | 3 or more consecutive turns of 4 words or fewer | Notes sustained terse responses |
| **Long silence count** | 2 or more gaps of at least 5 seconds | Notes repeated extended pauses |
These counters can appear in emotional prompt guidance once at least two acoustic segments are available. The compound resolver uses related per-turn observations over its own five-turn window, with stricter cross-signal conditions described in [Compound Emotions](/channels/voice/compound-emotions).
## TTS and Prompt Steering
After enough acoustic evidence is available, the rolling state can add concise adaptation guidance to the response prompt and map caller state to an empathetic TTS tone. The mapping responds to the caller without imitating negative emotion: an angry or disgusted signal maps to calm delivery, Fear or Sadness maps to sympathetic delivery, and Joy maps to enthusiastic delivery.
Weak or unmapped acoustic turns retain the previous successfully derived emotion tone instead of resetting immediately. This tone momentum applies to the emotion-derived TTS tone; navigation can still select a response emotion, and a configured workspace tone can override the computed voice-context tone. See [TTS Tone Resolution](/channels/voice/audio-pipeline#tts-tone-resolution) for the complete order.
If no emotion-derived tone is available, the current context-graph action can trigger a sympathetic fallback when it matches a configured sensitive topic. This is a delivery fallback, not a prediction that the caller is distressed.
Call-duration guidance is prompt-only. During an extended call with deteriorating or negative evidence, the prompt can ask for shorter, resolution-focused responses and suggest considering escalation. These checks do not automatically transfer or escalate the call.
## Compound Emotions
At each caller turn, the runtime resolves zero or more scored compounds from acoustic, linguistic, and behavioral evidence over the most recent five caller turns.
{% content-ref url="/pages/IeSDYAEqjzKUcXkDFduG" %}
[Compound Emotions](/channels/voice/compound-emotions)
{% endcontent-ref %}
## Fault Tolerance
Emotion analysis is optional to the live conversation path:
* A connection failure is non-fatal and the call continues without emotion-derived steering.
* Backpressure can skip best-effort emotion segments rather than delaying speech processing.
* Repeated receive or parsing failures can disable the emotion stream for the rest of that session.
* Transcript-analysis errors do not interrupt acoustic analysis or the call.
When emotion data is unavailable, the voice runtime uses navigation, configured voice settings, and provider defaults. It does not synthesize missing emotion evidence.
# Compound Emotions
How the five-turn resolver produces scored compound-emotion signals from acoustic, transcript, and behavioral evidence.
Compound emotions are turn-level analytical signals. The resolver combines several weak indicators so consumers do not have to interpret a categorical acoustic score, sentiment value, or behavior in isolation.
{% hint style="info" %}
The resolver can return multiple `{name, score}` items for one caller turn. A score is the result of a deterministic rule, not a calibrated probability or clinical confidence measure.
{% endhint %}
## Turn-Gated Architecture
The resolver runs after each final caller transcript. It keeps the five most recent caller-turn snapshots and evaluates the newest snapshot in the context of that window.
Each snapshot currently carries:
* The most recent segment's mapped categorical acoustic score distribution
* Rolling valence, arousal, and dominant runtime label
* The latest available transcript sentiment and toxicity values
* Whether the turn interrupted agent speech
* Word count and the silence before the turn
* The empathy tier already assigned to the turn
Dominance does not participate in the current live resolver.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
acoustic["Latest Acoustic Scores\n+ Rolling Valence/Arousal"] --> snapshot["Caller-Turn Snapshot"]
language["Sentiment + Toxicity"] --> snapshot
behavior["Barge-In + Words + Silence\n+ Empathy Tier"] --> snapshot
snapshot --> window["Five-Turn Window"]
window --> dyads["Dyads"]
window --> trajectory["Trajectory"]
window --> behavioral["Behavioral Rules"]
window --> linguistic["Linguistic Rules"]
dyads --> output["Up to Six Scored Compounds"]
trajectory --> output
behavioral --> output
linguistic --> output
```
Rules add signals to a shared result set rather than forming an override chain. If more than one rule produces the same name, the resolver keeps the strongest score, normalizes the returned range, removes weak results, and returns a bounded list in descending order.
## Acoustic Dyads
Dyad rules use co-activation in the newest caller turn's mapped categorical score distribution. Both component scores must contribute; a single strong category is not enough to produce the pair.
| Co-Activation | Compound |
| ----------------- | ----------- |
| Joy + Calmness | Contentment |
| Sadness + Anger | Bitterness |
| Sadness + Fear | Despair |
| Sadness + Disgust | Remorse |
| Anger + Disgust | Contempt |
| Fear + Surprise | Awe |
| Joy + Surprise | Delight |
| Anger + Fear | Conflict |
The non-emotional placeholder mapped from `other` and `unknown` is excluded from dyad scoring.
## Temporal Trajectory
Trajectory rules compare rolling valence and arousal across the current five-turn window. Directional changes can appear with less history than sustained-state signals.
| Signal | Evidence Pattern |
| ----------------- | ---------------------------------------------------------------------------------------- |
| **Deteriorating** | Meaningful negative movement in valence across the window |
| **Recovering** | Meaningful positive movement in valence |
| **Escalating** | Meaningful increase in arousal |
| **Resignation** | Sustained negative valence, mostly low arousal, and recent negative transcript sentiment |
| **Frustration** | Sustained negative valence with mostly high arousal |
| **Serenity** | Repeated positive valence with low arousal |
| **Elation** | Repeated positive valence with high arousal |
| **Ambivalence** | Multiple changes in valence direction |
Resignation's sentiment check is intentional cross-channel corroboration. Negative low-energy telephony audio alone does not produce the signal.
## Behavioral Rules
Behavioral rules inspect recent caller turns and require corroborating evidence rather than a behavior alone:
| Signal | Evidence Pattern |
| ----------------- | ------------------------------------------------------- |
| **Impatience** | Repeated recent interruptions plus negative valence |
| **Withdrawal** | Repeated terse turns plus negative transcript sentiment |
| **Disengagement** | Repeated long pauses plus low arousal |
| **Distress** | Repeated recent turns assigned a higher empathy tier |
These rules return their own scored items. They do not rewrite another compound into labels such as "Bitter Impatience" or "Resigned Withdrawal."
## Linguistic Rules
The newest available transcript analysis is compared with the rolling acoustic state:
| Signal | Evidence Pattern |
| ------------------- | -------------------------------------------------------------------------------- |
| **Cold Hostility** | Elevated toxicity with low arousal |
| **Aggression** | Elevated toxicity with higher arousal |
| **Masked Distress** | Strongly negative transcript sentiment with neutral or positive acoustic valence |
| **Sarcasm** | Negative transcript sentiment paired with positive acoustic valence |
These are score relationships, not transcript phrase matching. For example, the Sarcasm rule does not search for phrases such as "oh great"; it detects positive acoustic valence paired with sufficiently negative transcript sentiment.
## Current Context Boundary
The resolver can represent context-related evidence, but the current live turn path does not supply the completed tool-failure and outcome signals needed for its contextual rules. Do not treat Process Frustration, Helplessness, or Relief as current live outputs.
## Where Results Appear
Compound results are attached to the caller turn when the result list is non-empty. They are also published as a separate `compound_emotion` observer event with:
* `compounds` - the scored result array
* `turn_index` - the caller-turn index that produced it
At call end, call intelligence retains the strongest observed score for each compound name and stores a bounded, sorted aggregate. The terminal summary does not preserve a full compound timeline or choose one authoritative compound for the call.
Empathy classification happens before the snapshot and does not consume compound output. Compounds are therefore observability and terminal-intelligence evidence, not a second empathy control loop.
# Call Recordings
Workspace-scoped caller, agent, and merged stereo recordings with time-limited download links and best-effort availability.
When call recording is enabled, the voice runtime can retain caller and agent audio as separate WAV files and create a merged stereo WAV during finalization. Playback uses those stored artifacts.
Recording finalization is best-effort. A call can complete successfully even when a recording is missing or incomplete. A successful request for download links does not prove that the files exist; the client must handle the result of fetching each link.
## Channels and Timing
| Channel | Contents | Playback behavior |
| ---------- | -------------------------------------- | --------------------------------------------------- |
| **Caller** | Inbound caller audio | Stored as a mono WAV |
| **Agent** | Spoken agent audio | Stored as a mono WAV |
| **Stereo** | Caller on the left, agent on the right | Created during finalization and stored for playback |
Current voice recordings store the mono channels as 8 kHz mu-law WAV and the merged stereo file as decoded PCM WAV. Each file carries its codec and sample rate in the WAV header. Clients should read that header, including when handling older recordings, rather than assuming that every WAV contains PCM audio.
The runtime aligns outbound audio with the inbound timeline during capture. This shared timing origin lets playback views align transcripts, agent speech, tool activity, and other call events without treating each channel as an independent recording.
## Playback and Review
The Platform API authenticates the requester, verifies workspace access, and returns time-limited links for the caller, agent, and stereo files in that workspace. It does not check file existence before issuing those links. A missing artifact fails when the link is fetched.
Treat download links as temporary access to sensitive audio: share them only with authorized recipients and request fresh links after expiry. The current recording interface does not provide the former separate metadata, waveform, or on-demand stereo-transcoding endpoints. A playback client derives file metadata and waveforms from the downloaded audio.
## Availability and Retention
Recording availability depends on deployment configuration and successful finalization. Older calls may lack the merged stereo artifact even when individual channels exist. Retention requirements should be configured and validated as part of the workspace's data-handling policy; stored retention settings are advisory and do not by themselves enforce deletion. See [Retention Policies](/operations-and-safety/compliance#retention-policies).
{% hint style="info" %}
For optional post-call transcript verification and quality analysis, see [After the Call](/channels/voice/audio-pipeline#after-the-call). For timeline review that aligns speech with agent actions, tool calls, and system events, see [Call Playback Timeline](/intelligence-and-analytics/intelligence/call-intelligence#call-playback-timeline).
{% endhint %}
# Text Sessions
Durable text conversations over the web API, SMS, iMessage, WhatsApp, and email, with channel-specific delivery behavior.
Text sessions run the agent's core reasoning and Context Graph behavior without the live audio pipeline. The bound service determines the agent configuration and eligible tools; each channel adds its own identity, delivery, timing, and operator controls.
The public web integration uses the Conversations REST API. A turn can return one JSON response or stream typed Server-Sent Events (SSE). The platform does not currently expose a public text-session WebSocket.
## Durable Conversation Model
The platform persists text turns against a conversation ID. Conversation detail exposes the durable history, current status, and channel attribution needed to resume or inspect a thread. Channel runtimes can keep short-lived actor state for active work, but an idle actor does not erase the durable conversation.
The public conversation resource separates two concepts:
* **Status** records the stored processing state, such as active, completed, closed, paused, or failed where applicable.
* **Lifecycle** is a read-time view of recency: `active`, `dormant`, or `closed`. A dormant conversation is idle, not deleted.
Do not treat lifecycle as a guarantee that an actor is resident in memory. Resume behavior depends on the channel, conversation status, provider thread key, and current service configuration.
### Phone-Keyed Threads
SMS and iMessage resolve inbound messages through phone-based provider thread keys. Managed WhatsApp uses a business-scoped recipient identifier and use case instead of assuming a phone number. While a non-terminal conversation remains available for that key, later messages resume it and retain its durable turn history.
A new thread starts after terminal Context Graph completion or an explicit lifecycle change. For SMS and iMessage, outbound creation also accepts `force_new: true`; the platform closes the active conversation for the same recipient and use case before dispatching a new opener. Outbound WhatsApp creation is not supported by this conversation-start path.
There is no patient-facing reset keyword. If an application needs a deterministic reset, retain the conversation ID and close it through the lifecycle API before the next inbound message.
{% hint style="info" %}
Endpoint details and examples are in the [Conversations API guide](https://docs.amigo.ai/developer-guide/platform-api/conversations).
{% endhint %}
### Configuration Changes
Published service configuration and version-set bindings determine what a conversation loads. An already active channel actor can retain configuration it loaded earlier, so a newly published version is not guaranteed to affect the very next inbound message.
For a controlled rollout, pin the intended versions in the service's `release` [version set](/platform-overview/deployment-model#version-sets). When a structural change is incompatible with an in-progress thread, close the conversation and start a new one rather than relying on a mid-thread reload.
## Supported Text Paths
| Path | Continuity | Response behavior |
| ----------------- | --------------------------------------------------------------------------------- | ----------------------------------------------------------------- |
| **Web API** | A caller creates a web conversation and sends turns by conversation ID | Synchronous JSON or request-scoped SSE |
| **SMS** | Provider thread resolves to a durable conversation | Asynchronous provider delivery |
| **iMessage** | Provider thread resolves to a durable conversation | Asynchronous provider delivery with supported media |
| **WhatsApp text** | Business-scoped recipient identity and use case resolve to a durable conversation | Asynchronous managed text reply within the permitted reply window |
| **Email** | Message headers and stored references preserve email threading | Asynchronous email reply delivery |
WhatsApp voice notes use a separate audio-turn path and separate session state. They do not merge with managed WhatsApp conversation history.
## Web Conversations: REST and SSE
A web client first creates a conversation for a service, then sends one turn at a time to that conversation.
### Synchronous JSON
The standard turn request returns the user's input, agent output, conversation snapshot, and optional tool-call details in one response. Serialize turns per conversation: do not submit another user turn while the current one is still in flight.
### Server-Sent Events
For incremental output, use the dedicated streaming turn endpoint or request `Accept: text/event-stream` on the standard turn endpoint. The stream can emit:
* `token`
* `tool_call_started`
* `tool_call_completed`
* `thinking`
* `message`
* `done`
* `error`
These are request-scoped events, not a persistent bidirectional session. A client should handle an `error` event and an interrupted HTTP connection explicitly.
### Background Tool Completion
A synchronous response can return `background_pending: true` when a tool outlives the blocking window. In that case, the returned output is an acknowledgement, not the final answer.
Clients have two supported controls:
1. Set `wait_for_final: true` on the message turn to wait for the final answer for a bounded period.
2. If the response still reports pending work, send a no-message request with `poll=true` until the completion is returned. Do not combine polling with SSE or a user message, and avoid polling more often than the documented interval.
Sending the next user turn can also drain completed background work, but applications that need the result before accepting more input should poll explicitly. An open WebSocket is not part of this completion protocol.
## Asynchronous Channel Delivery
SMS, iMessage, WhatsApp, and email use non-live channel policies. When supported background work is handed off, the channel runtime suppresses an intermediate filler response and attempts to re-drive the conversation when the result completes.
That behavior does not make external delivery infallible. Provider rejection, opt-out policy, invalid addressing, or exhausted retries can still prevent the final message from reaching the recipient. Use the channel's delivery status and recovery controls rather than treating agent completion as proof of delivery.
### Message Coalescing
SMS, iMessage, and WhatsApp can coalesce messages that accumulate while a turn is already processing. Up to ten queued message signals can become the next agent turn. This prevents several rapid fragments from producing several overlapping replies.
Web API and email turns are not coalesced. Non-message signals remain separate.
## Channel Notes
### SMS
SMS supports inbound durable threads and outbound openers through provisioned use cases. Sender selection, opt-out enforcement, media support, and delivery status belong to the SMS channel contract.
{% content-ref url="/pages/06YznjcZmK794tiVzM7q" %}
[SMS](/channels/sms)
{% endcontent-ref %}
### iMessage
iMessage uses a managed channel setup and durable phone-keyed conversations. The public lifecycle API supports outbound openers and explicit switching between SMS and iMessage.
{% content-ref url="/pages/c1iRKBkz9pUpCgeAnQTO" %}
[iMessage](/channels/imessage)
{% endcontent-ref %}
### WhatsApp
Managed WhatsApp routes inbound messages into a durable conversation and sends text replies asynchronously. The separate service voice-note API returns synthesized audio to its caller and has independent continuity. The former synchronous text-turn API has been removed.
{% content-ref url="/pages/SS3ZnjwCmfLJCyDs8hcQ" %}
[WhatsApp](/channels/whatsapp)
{% endcontent-ref %}
### Email
Email uses message headers and stored references to preserve reply threading. Its delivery, suppression, attachment, and recovery behavior is documented separately.
{% content-ref url="/pages/uirHtW6W7wkJL0eKBdYK" %}
[Email](/channels/email)
{% endcontent-ref %}
## Differences from Voice
| Text behavior | Operational consequence |
| ------------------------------------------------- | -------------------------------------------------------------- |
| No real-time audio pipeline | No barge-in, filler speech, or acoustic emotion evidence |
| Request- or message-driven turns | Delivery and response timing depend on the channel |
| Durable asynchronous threads | A later message can resume a non-terminal conversation |
| Authored-turn takeover on eligible non-voice runs | Operators stage a reply instead of joining an audio conference |
Text channels can use language-level safety and sentiment signals where configured, but they do not have the vocal evidence available to a live phone call.
## Playground Testing
Open **Prove > Playground** in the Developer Console. The playground has two modes:
* **Voice** for eligible voice services
* **Text** for eligible voice or text services
Text mode creates a durable web conversation and streams each turn over SSE. It can show optional Context Graph and Timeline panels; it is not a separate REST, realtime, or WebSocket mode. See [Playground and Interactive Testing](/testing/testing/playground).
# SMS
SMS channel for outbound and inbound text messaging through provisioned phone numbers.
The SMS channel lets agents send and receive text messages through provisioned phone numbers. Each SMS use case has a managed sender pool, registration, consent checks, and delivery tracking. Managed infrastructure also supports MMS when the sender pool has the required capability; this does not mean every agent conversation can generate or interpret every attachment type.
## Provisioning
SMS provisioning is a regulated, operator-managed process rather than a self-service Platform API or Developer Console flow. It includes the applicable carrier registration, messaging use case, and phone-number configuration. Timing depends on carrier review and number readiness.
After provisioning, Amigo supplies the use-case identifier. The Platform API binds that SMS use case to a service in the workspace. It does not create the upstream SMS setup, campaign, messaging service, or number assignment for the workspace.
To request SMS provisioning for your workspace, contact your Amigo account team.
### How Use Cases Are Backed
Each provisioned SMS use case is backed by managed messaging infrastructure and an assigned phone-number pool. Sender selection occurs within that use case; callers starting an outbound conversation supply the use case and recipient, not a `From` number.
## Inbound SMS
Customers can text a configured phone number to start a conversation with the agent. The platform routes the message to the bound service, resolves authorized context when available, and runs the agent's reasoning engine. Messages from the same caller on the same use case are serialized onto the current non-terminal durable conversation. Terminal Context Graph completion, closing a known conversation ID, a use-case rebind, or outbound creation with `force_new: true` starts a fresh thread; see [Phone-Keyed Threads](/channels/text-sessions#phone-keyed-threads).
Once operator provisioning is complete, the workspace application does not configure a provider webhook for each conversation. The managed channel validates inbound delivery, deduplicates provider retries, resolves the destination use case, and records message metadata for processing and analytics.
When a reply depends on supported background work, the asynchronous channel policy suppresses the intermediate acknowledgement and attempts to re-drive the final reply. Provider acceptance and delivery remain separate; inspect delivery status and recovery evidence rather than assuming the recipient received it. See [Long-Running Tools and Reply Delivery](/channels/email#long-running-tools-and-reply-delivery).
Signature validation ensures that only authentic message deliveries are accepted. Duplicate deliveries (from network retries) are silently acknowledged without creating duplicate records.
## Outbound SMS
The platform supports agent-initiated outbound SMS without waiting for an inbound text. The bound service generates the opening turn using its published configuration and the authorized context available at execution time. A recipient reply can continue the resulting durable conversation.
Outbound SMS conversations are started through the conversation lifecycle API by specifying SMS as the channel, a recipient phone number in E.164 format, and a use case that determines the sender. The sender (FROM number) is resolved from the use case configuration - it is never supplied by the caller. See [Outbound](/channels/outbound) for details on the channel-generic lifecycle.
Outbound SMS can support reminders and follow-up workflows when the workspace has a provisioned use case and the application supplies the required routing inputs. Contact the Amigo team to confirm availability and onboarding for your workspace.
{% hint style="info" %}
Outbound text conversations support entity-based resolution. When an entity ID is supplied, the runtime can load authorized context available for that entity before the first message rather than relying only on phone-number matching. Missing data, source permissions, and projection lag still apply.
{% endhint %}
## Channel Switching
An active conversation on another channel (such as iMessage) can be switched to SMS, preserving the full conversation history. Each turn records which channel it occurred on, so the history is self-describing across channel changes. See [Outbound](/channels/outbound#switching-between-sms-and-imessage) for the switch lifecycle.
## Consent and Registration
Carrier registration, recipient consent, and message content are separate launch requirements. The customer supplies the consent process and evidence for the intended audience and purpose; Amigo manages the channel registration and configured send controls. A phone number in the world model is contact information, not permission to send outreach.
### Preparing a Campaign
Amigo reviews the sending business, message purpose, consent flow, sample messages, and support details before submitting the registration. The deployed workflow must match that submission, including whether messages recur and whether they contain links or phone numbers. A successful text in a demo does not establish that a production campaign is ready.
The launch review establishes:
* **Who is sending and why.** Identify the brand the recipient consented to hear from and the full scope of messages. Adding health coaching to a scheduling program, for example, requires reviewing whether the existing consent and registration cover the new purpose.
* **Where consent is given.** Use a clearly documented SMS consent step. A recorded verbal flow can be used when its script and evidence are included in the approved campaign. A written flow should use an explicit, optional SMS choice, separate from consent to other channels.
* **What the recipient is told.** Align the consent language, first message, sample messages, terms, privacy policy, sender identity, expected frequency, charges disclosure, and STOP/HELP instructions.
* **How evidence is retained.** Assign responsibility for retaining the consent record and the wording presented to that recipient. For verbal consent, verify that the recording or other approved evidence actually exists and remains available.
* **How customer systems stay consistent.** Agree how opt-outs reach the customer's own contact and campaign records. Amigo's channel suppression does not automatically update every external system.
Existing patient relationships, a supplied contact list, or permission collected by another organization do not by themselves establish campaign permission. A program sending on behalf of another organization needs review of that brand's consent evidence, authorization, and registration structure. Do not send an unsolicited first SMS merely to ask for consent or rely on STOP as the consent mechanism.
### The Managed Send Gate
For US long-code and US/Canada toll-free sender pools, the managed channel requires a recorded opt-in message for each recipient and use case before ordinary messages can be sent. That message uses the approved registration's confirmation copy. Its record is created after the provider accepts the send; it is not proof that the recipient received it or that the customer collected valid consent. Repeating the opt-in operation does not remove an existing suppression.
The same in-platform opt-in gate does not cover Canadian long-code or other international sender pools. Confirm the applicable consent and provider requirements during provisioning. The absence of this particular gate does not authorize messaging.
### Registered Content
For registered US long-code and US/Canada toll-free pools, a model-based check compares an ordinary outbound text body against every registration governing the pool. Off-purpose content is blocked. If the check fails or cannot produce a usable decision, the send is blocked rather than bypassing the check.
This check evaluates the text body, including the registered purpose and applicable content restrictions. It does not inspect media-only MMS content and does not establish legal compliance or clinical accuracy. Consent, suppression, and sender-capability checks still apply to those sends.
## Opt-Out and Re-Subscription
An opt-out suppresses ordinary outbound SMS across the recipient's **managed business setup**, which can contain multiple use cases and sending numbers. It is broader than one conversation or campaign, but is not a universal opt-out across unrelated businesses or other channels. Agents and campaigns cannot bypass it by starting another conversation or choosing another number within that setup.
| Sender path | Recognized handling |
| ----------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **US long-code with a verified campaign** | Registered opt-out keywords include `STOP`, `STOPALL`, `UNSUBSCRIBE`, `CANCEL`, `END`, and `QUIT`. Registered help keywords include `HELP`. Matching trims surrounding whitespace and ignores case. These requests are handled by the channel instead of the agent. |
| **US/Canada toll-free keyword path** | `STOP` records both a line-specific opt-out and business-setup suppression. `START` or `UNSTOP` clears the line-specific record only. These keywords do not become agent turns. |
The campaign keyword path attempts the registered confirmation on each recognized opt-out request and the registered help reply on a help request. Confirmation delivery can fail independently; a confirmation is not a guarantee that future messages are permitted. Do not assume the toll-free path sends the same confirmation or supports every campaign keyword.
**Texting `START` does not automatically restore Amigo delivery.** An authorized Amigo operator must separately clear the business-setup suppression after reviewing renewed consent and recording a reason. For a live toll-free opt-out, the recipient must first text `START` or `UNSTOP` to the affected line; the operator cannot override that prerequisite.
Opt-out history is retained after reversal. Amigo can inspect the setup's suppression records and the related inbound, outbound, and opt-in evidence through managed operations. Contact the Amigo team for consent review or re-subscription; these provider-management operations are not public workspace API capabilities.
## Phone Number Assignment
SMS use cases require phone numbers with SMS capability, and the registration requirement depends on the number type and country. US/Canada toll-free numbers require approved toll-free verification. US local and national long-code numbers require an approved messaging campaign. Registration makes a sender eligible for assignment; recipient consent, suppression, content checks, and provider delivery rules still apply to each message.
Unlike voice channels - where a single phone number can serve different voice use cases on different channels (one for inbound voice, one for outbound voice, one for voicemail) - SMS assignment is exclusive. A phone number can only be assigned to one SMS use case at a time. This mirrors the underlying telephony constraint that a phone number belongs to exactly one messaging service.
## Channel Separation
SMS and voice operate on separate channel bindings. A phone number can be assigned to both a voice use case and an SMS use case simultaneously - the two channels do not conflict. The platform tracks voice and SMS assignments independently, so assigning a number to an SMS use case does not affect any existing voice assignments on that number, and vice versa.
## Lifecycle
The managed SMS lifecycle is:
1. **Provision** - An Amigo operator creates the required channel resources and completes carrier registration.
2. **Assign numbers** - Eligible SMS-capable numbers join the use case after the applicable verification or campaign approval.
3. **Bind service** - The workspace binds the provisioned use case to an eligible service through the Platform API.
4. **Send and receive** - Messages route through the managed number pool and durable conversation path.
5. **Retire** - An operator unassigns numbers and tears down upstream resources when the use case is no longer needed.
{% content-ref url="/pages/F9G0lrxZA31mW1pawkgs" %}
[Text Sessions](/channels/text-sessions)
{% endcontent-ref %}
# WhatsApp
Managed WhatsApp conversations with business-scoped identity, asynchronous replies, and a bounded customer-service window.
A provisioned WhatsApp use case can route inbound messages to a bound Amigo service and deliver the agent's text reply through the managed channel. Amigo handles provider authentication, message records, routing, and delivery-status updates. Confirm business-account provisioning and service binding with the Amigo team before launch.
The managed channel and the separate service voice-note API have different delivery and continuity models:
| Path | Input | Output | Continuity |
| -------------------------- | ---------------------------------------------------------------------- | ------------------------------------------------------------ | ----------------------------------------------------------------------------- |
| **Managed messaging** | Provider-authenticated inbound content | Asynchronous text reply through the business use case | Durable conversation keyed by business-scoped recipient identity and use case |
| **Service voice-note API** | Customer phone and supported recorded audio supplied by an integration | Synthesized audio or no-content response to that integration | Separate audio-turn session |
The former synchronous WhatsApp-style text-turn API has been removed. Use the managed channel for WhatsApp messaging and the [Conversations API](https://docs.amigo.ai/developer-guide/platform-api/conversations) for application-hosted text interactions.
## Managed Text Conversations
The channel uses a business-scoped user identifier for recipient addressing. A phone number may be available as metadata, but it is not required for every inbound identity and is not interchangeable with the messaging identifier.
For the same recipient and use case, later messages can resume the current non-terminal durable conversation. Processing is serialized, and queued message fragments can be coalesced into a later turn. The service supplies the published agent configuration, Context Graph, and eligible tools.
Inbound processing can retain supported media and reactions as channel records. A reaction without message or media content does not drive an agent turn. Retaining an attachment is not proof that the agent transcribed or interpreted it; the managed agent reply path currently sends text. Validate any media workflow separately.
After an inbound message is committed, the channel attempts to mark it as read. This receipt does not prove that the agent has processed the message, completed the task, or delivered a reply.
## Reply Window and Delivery
Managed free-form sends require an inbound message from the recipient to that use case within the preceding **23 hours**. This is Amigo's send boundary. A long-running task can finish after the reply window has closed, in which case the agent turn can remain recorded even though the reply cannot be sent.
Template registration and status tracking exist in managed operations, but the current send path does not send templates. An approved template therefore does not enable this path to initiate an out-of-window conversation.
When supported background work is running, the channel suppresses an intermediate filler and attempts to deliver the final reply when the work completes. Window checks, provider rejection, and channel failures still apply. Check delivery evidence separately from tool or agent completion.
The public conversation-start and channel-switch operations do not currently create outbound WhatsApp threads or switch another channel into WhatsApp. Contact Amigo to confirm the supported outreach design for your deployment.
## Voice-Note Turns
The service voice-note API accepts recorded audio, transcribes it, runs the reasoning path, and returns synthesized audio when the agent responds. The integration calling that API is responsible for delivering the returned audio to its destination.
Audio-turn sessions use workspace, service, and customer phone for continuity and serialize turns for the same speaker. Their state is separate from managed WhatsApp conversations. They do not provide the continuous media stream, barge-in, live takeover, or acoustic timeline of a phone call.
There is no public per-number response-modality switch that automatically joins these paths. Use a live [phone call](/channels/voice) when the workflow needs real-time audio controls.
## Operational Boundaries
* Complete business-account provisioning and bind the use case to an eligible service.
* Preserve business-scoped recipient identifiers instead of assuming phone-based identity.
* Distinguish inbound receipt, agent processing, provider acceptance, and recipient delivery.
* Account for the reply window when scheduling background work.
* Confirm channel-specific consent and data-handling requirements for the intended content.
* Treat managed messaging and the service voice-note API as separate sessions and integrations.
{% content-ref url="/pages/F9G0lrxZA31mW1pawkgs" %}
[Text Sessions](/channels/text-sessions)
{% endcontent-ref %}
# iMessage
iMessage channel for patient communication through Apple's messaging platform.
The platform supports iMessage as a managed messaging channel for patient communication through Apple's native messaging experience. The channel records delivery status and supports text plus bounded media payloads on compatible devices.
## Provisioning
Like SMS, iMessage provisioning is operator managed rather than self-service through the Platform API or Developer Console. It includes business identity, provider, and phone-line configuration. Timing depends on provider and carrier readiness. Contact your Amigo account team to request access.
After provisioning, the Platform API can list workspace-owned use cases and bind an eligible iMessage use case to a service. It does not create or delete the upstream provider setup or phone line for the workspace.
### What Happens During Provisioning
iMessage is provisioned with a managed business identity and phone line. During setup, the Amigo team:
1. **Registers the managed setup** - Associates the workspace's business identity with the channel provider.
2. **Assigns a phone line** - Uses an available number or waits for asynchronous line placement.
3. **Binds the use case** - Makes the provisioned channel available to the selected Platform service.
### Phone Line Lifecycle
Each setup includes one or more phone lines. A phone line is in one of two states:
* **Pending** - The line has been requested but a phone number has not yet been placed. The setup tracks the outstanding request.
* **Assigned** - The line has a phone number in E.164 format and is ready for messaging.
The transition from pending to assigned is asynchronous. Do not send until the managed setup reports an assigned line.
## Inbound iMessage
Inbound iMessage conversations follow the same durable processing model as SMS: messages from the same caller on the same use case are serialized onto the current non-terminal conversation. Replies can include supported text or bounded media payloads.
When a reply depends on supported background work, the asynchronous channel policy suppresses the intermediate acknowledgement and attempts to re-drive the final reply. Provider acceptance and delivery remain separate; inspect status rather than assuming the recipient received it. See [Long-Running Tools and Reply Delivery](/channels/email#long-running-tools-and-reply-delivery).
## Starting a Fresh Conversation
Because iMessage conversations are durable, a caller who messages the same number later can resume the current non-terminal thread - there is no reset keyword. If your application has the conversation ID, it can close that conversation through the lifecycle API. For a new outbound opener, create the iMessage conversation with `force_new: true`; the platform closes the active thread for the same recipient and use case before creating the new one. See [Phone-Keyed Threads](/channels/text-sessions#phone-keyed-threads).
## Outbound and Channel Switching
iMessage conversations can be started proactively (outbound) through the conversation lifecycle API by specifying iMessage as the channel, a recipient phone number in E.164 format, and a use case that determines the sender pool. The sender is resolved from the use case configuration - it is never supplied by the caller. See [Outbound](/channels/outbound) for details on the channel-generic lifecycle.
An active conversation on another channel (such as SMS) can be switched to iMessage, preserving the full conversation history. Each turn records which channel it occurred on, so the history is self-describing across channel changes.
## Security and Management Boundary
Channel selection must account for the intended content and contractual coverage. Do not infer that iMessage is covered for PHI because the Amigo workspace is configured for healthcare or because the device displays an encrypted conversation. Confirm the permitted use with the Amigo team before launch.
For sensitive collection, a workflow can send a minimal notification with a link to a [Surface](/channels/surfaces), where the patient supplies the required information in a browser. The message body, link, form, access policy, and destination still need to match the deployment's data-handling requirements. A form link does not make PHI already included in the message safe to send.
Provider credentials, line placement, and inbound provider authentication remain inside managed channel infrastructure. Workspace applications use Platform credentials and the public conversation lifecycle; they do not receive provider secrets. After provisioning, bind the provisioned use case to a service through the Platform API for workspace routing, and contact Amigo for upstream setup changes.
{% content-ref url="/pages/F9G0lrxZA31mW1pawkgs" %}
[Text Sessions](/channels/text-sessions)
{% endcontent-ref %}
# Email
Email channel with domain verification, inbound reply handling, thread continuity, and transactional and marketing use cases.
The platform supports email as a communication channel alongside voice and text. With a verified sending domain in place, workspaces create email use cases, send messages through the platform API, and receive inbound replies that thread back into the original conversation.
## Sending Domain Setup
Before an email use case can send or receive messages, the workspace must have a verified sending domain. Each setup binds a logical tenant name to a domain identity, creating an isolation boundary for reputation and suppression management. Each email domain setup is isolated to its workspace, and a workspace can have more than one.
Sending-domain setup is provisioned by the Amigo team - it is not self-serve. The team registers the domain identity, provides the DNS records to publish at your DNS provider, and confirms verification against live DNS. A single domain identity serves both outbound sending and inbound receiving, and a domain must complete DNS verification before it can back an email use case. To enable email for a workspace, contact the Amigo team.
Each email setup includes:
* **Domain identity** - The domain used for sending (e.g., `notifications.example.com`)
* **DNS records** - Records that must be added to the domain's DNS configuration for verification: DKIM signing keys, SPF records, DMARC policies, and inbound MX routing
* **Verification status** - Whether the DNS records have been confirmed
## Use Cases and Sender Identities
Email on the platform is organized around use cases. A use case names one email sender identity - a sender address backed by a verified sending domain - owned by a workspace. Each use case specifies:
* **Sender email address** - The `From` address for messages sent through this use case
* **Email type** - Either `transactional` (triggered by user actions, like appointment confirmations) or `marketing` (bulk or promotional messages). The type determines sending rules and compliance handling.
* **Entity name and use case name** - Labels that identify the purpose of the use case for reporting and management
Each use case also records an explicit decision on two inbox posture settings:
* **Unsubscribable** - whether sends carry one-click unsubscribe headers and honor per-use-case opt-out lists. Marketing email must be unsubscribable. Transactional use cases may opt out for must-send flows such as password resets.
* **Accepts cold inbound** - whether the sender address acts as an open inbox (cold first-contact email reaches the agent after authentication and spam gates) or a strict thread-only inbox (only replies to outbound messages are accepted).
Binding a use case to a service is the act that enables the email channel for the workspace. Once bound, inbound traffic for the use case resolves to the bound service, and outbound dispatch from the service routes through the use case. Rebinding replaces the current binding immediately. Unbinding turns the channel off.
Use cases are managed through the platform API (create, bind, unbind, and delete use cases).
{% hint style="info" %}
Email sending, delivery tracking, and engagement analytics are available through the Platform API. See the [Developer Guide](https://docs.amigo.ai/developer-guide) for endpoint details.
{% endhint %}
## Inbound Email
When a domain's MX records are configured, the platform receives and processes inbound email. Inbound messages are resolved back to the original outbound email that prompted the reply, linking the patient's response to the correct conversation context.
Reply resolution uses the standard `In-Reply-To` and `References` headers from the inbound message to find the parent outbound. When a match is found, the inbound email is associated with the same use case and workspace, giving downstream systems full thread context.
### Long-Running Tools and Reply Delivery
Some agent replies depend on a tool that takes longer than the synchronous turn window. Voice can provide a live acknowledgement. A web API client instead follows the REST contract: bounded `wait_for_final`, `background_pending`, and explicit polling when work remains.
Email is asynchronous, so its channel policy suppresses an intermediate acknowledgement and waits for supported background work before attempting the final reply. The recipient does not maintain a live text connection. Tool completion, message creation, provider acceptance, and recipient delivery are separate milestones.
The intended result is one useful reply rather than a filler followed by a correction. Tool failure, exhausted processing retries, suppression, bounce, or provider rejection can still prevent that outcome. Use channel status and the recovery queue to distinguish those cases.
SMS, iMessage, and WhatsApp use related non-live policies. Web conversations use request-scoped REST or SSE rather than a persistent text WebSocket.
### Attachment Handling
The inbound parser handles standard MIME attachments and the deeply nested layouts produced by some mail clients. Supported behavior includes:
* **Attachment parts are preserved.** Recognized attachment parts are extracted with their content and metadata rather than flattened into the message body.
* **Forwarded emails stay intact.** An email forwarded as an attachment is kept as a single `.eml` file, preventing attachments inside it from being attributed to the outer message.
* **Inline images retain CID identity.** Content-ID parts are stored under their CID identifiers so renderers can resolve references from the message body. Consumers should not assume every client hides those parts from attachment views.
## Reply Threading
Outbound emails can be sent as replies to inbound messages, maintaining thread continuity in the patient's email client. When sending a reply, the platform sets the `In-Reply-To` and `References` headers according to RFC 5322, so the patient sees a single threaded conversation rather than disconnected messages.
The platform maintains the full reference chain across multiple reply rounds. If a patient replies to an outbound, and the platform replies back, and the patient replies again, each message carries the complete thread history. Even when a patient's email client strips the `References` header (some lightweight mailers do this), the platform reconstructs the chain from its stored records so the next outbound reply still threads correctly.
Reply threading is scoped to the same use case and email setup. Cross-use-case replies are rejected to prevent confused-deputy scenarios where a reply intended for one context could be misattributed to another.
## Delivery Tracking
The platform records available provider lifecycle events for outbound email:
* **Delivery confirmation** - When the receiving mail server accepts the message
* **Bounce handling** - Hard bounces (invalid address) and soft bounces (temporary failure) are recorded and influence future sending decisions
* **Complaint tracking** - When a recipient marks a message as spam, the platform records the complaint and can suppress future sends to that address
## Unsubscribe Handling
Outbound emails include RFC 8058 one-click unsubscribe headers. When a patient clicks the unsubscribe button in their email client, the platform processes the opt-out automatically. Unsubscribe scope can be per-use-case (the patient stops receiving emails from one campaign but continues receiving others) or per-setup (the patient opts out of all email from that domain).
## Reliability and Operational Recovery
The email channel is built for reliable message processing. Inbound email turns are processed with automatic retry logic - if processing fails after multiple attempts, the turn is set aside in a durable record that captures the full routing context (service, use case, session, and message references), with safeguards against duplicate processing.
Operators can recover these failed turns after the underlying fault is resolved using a dedicated recovery tool. The recovery reconstructs a fresh processing item with a clean retry budget and re-submits the turn for processing. The tool defaults to a dry-run mode that displays the reconstructed item without writing anything, requiring an explicit flag to apply changes.
The platform monitors email processing load so teams can detect when inbound volume outpaces processing capacity. A rising backlog indicates that inbound turns are arriving faster than they can be processed - a condition that per-turn liveness signals alone cannot detect.
During maintenance or a worker restart, bounded retries can re-process unstarted work. Items that exhaust their retry budget move to durable recovery records; operators should monitor backlog and use the recovery workflow rather than assume lossless processing.
# Surfaces
Agent-generated data collection interfaces delivered by email or web, with templates, progress tracking, and pending appointment requests.
A patient calls to schedule an appointment. During the call, the agent realizes it needs insurance information and a photo of the insurance card. It cannot collect a photo over the phone. Instead of asking the patient to call back or visit a portal, the agent generates a surface - a short data collection form - and shares a secure link. The patient fills it out on their phone. The submission is stored against the surface, and the platform attempts to publish a provenance-bearing world-model event for later projection. Where the private-preview connector review flow is enabled, a configured downstream mutation can become a separate write proposal.
Surfaces close the gap between "we need this data" and "we have a way to collect it." They can be generated dynamically or from workspace templates, delivered by email or handed off as a web link, and contribute patient-reported data to the world model asynchronously.
## How Surfaces Work
The agent decides what to ask. The platform handles rendering, delivery, and collection. Agents generate surface specs from their understanding of what data is missing, or select from workspace-level form templates that pre-define field layouts and prefill rules for common workflows.
## Mid-Call Surface Tools
Agents can access a family of ten surface tools when those tools are exposed by the service and current Context Graph state. This lets an agent create a form, inspect its progress, and hand off a supported link during an interaction without making surface capabilities universal to every state.
| Capability | What It Does |
| ------------------------ | ------------------------------------------------------------------------------------------ |
| **Create surface** | Creates a dynamic form and returns its patient-facing URL when link signing is configured. |
| **Deliver surface** | Sends an email or records an external web handoff. Phone-shaped destinations are rejected. |
| **Check status** | Reads the current lifecycle state and submitted data when available. |
| **Extract file text** | Extracts text from supported PDF fields on a completed surface. |
| **List entity surfaces** | Lists existing surfaces for an entity, optionally filtered by status. |
| **Get surface insights** | Returns observed completion history, pending count, and channel statistics. |
| **Get form templates** | Lists reusable workspace templates. |
| **Create from template** | Resolves a template, prefills supported fields, and creates a surface. |
| **Get progress** | Reports saved and missing fields for a surface. |
| **Reshape surface** | Creates a shorter surface containing remaining fields. |
A typical mid-call flow: the agent notices the patient's insurance card is missing, creates a two-field surface (front photo + back photo), sends the link to the patient, and checks back moments later to see if the patient has opened it. If completed before the call ends, the agent confirms receipt. If not, the surface stays active and the patient can complete it later.
### Real-Time Surface Observation
Supported active sessions can observe a submission for a surface they are tracking and acknowledge it in the conversation. Event delivery is best-effort, so status reads remain the authoritative fallback when the workflow must confirm completion.
The runtime filters available workspace events to the tracked surface IDs and can inject a matching submission as guidance. A missed observer event does not change the stored submission or its lifecycle status.
Surface tools must be present in the service's eligible tool set and bound where the workflow needs them. Workspace authorization and entity scope still apply.
### Surface Templates and Wait Conditions
Context graph states can also declare surfaces and waiting behavior directly in their definition, without the agent needing to call tools:
* **Surface templates** - A state can include a surface spec template. When the agent enters that state, the platform automatically creates the surface using the template's fields and entity context. This is useful for deterministic workflows where the form is always the same (e.g., "collect insurance card" always needs front and back photo fields).
* **Wait conditions** - A state can declare that the agent should pause and wait for the surface to be submitted before continuing. While waiting, the agent stays in the current state and makes empathetic small-talk rather than advancing through the conversation. The wait clears automatically when the patient submits the form or when a reviewer approves the submission.
These extensions work across both voice and text channels. For more details, see [Action State Extensions](/agent/context-graphs).
### Form Templates
Workspace administrators can define form templates that standardize common data collection workflows. A template pre-defines the field layout, section structure, and prefill rules - mapping entity state fields to form fields so patients see their known information pre-populated. Templates also support patient-type routing, delivering different field sets based on the entity's characteristics.
Agents access templates through two tools: one to list available templates for the workspace, and one to create a surface from a template with a specific entity. The template system handles field prefill from the entity's world model state, reducing the number of fields the patient needs to fill manually.
Templates are useful when the same form is used repeatedly (intake forms, insurance collection, consent workflows). For one-off or dynamic data collection, agents still generate surface specs directly.
### Calendar Booking
Surfaces can include an appointment-request step where patients select from projected free slots. Submission validates that the slot still appears free, stores the request on the surface, and emits a `booking.requested` event. The response is `pending`; it is not confirmation that an external scheduling system created an appointment.
This is particularly useful for post-call follow-up surfaces where the agent identified that the patient needs to schedule a visit. The surface can collect missing data and capture an appointment request in one flow, while confirmation remains a separate scheduling outcome.
## Intake Upload Links
The separate shareable intake upload-link system has been retired. It is not a current alternative to a Surface. Use Surfaces for supported patient-facing forms and [dataset intake](/data/customer-data-intake) for authenticated file ingestion. Surface collection and dataset processing have separate lifecycles; submitting a form does not automatically register or publish a dataset file.
## Automated Gap Detection
Beyond mid-call surfaces, the platform can proactively identify missing data and create surfaces automatically. A background scanner periodically examines entity state across the workspace, compares it against configurable requirements, and creates surfaces for any gaps it finds.
For example: a workspace can define that every patient with an upcoming appointment must have insurance information, a pharmacy on file, and an emergency contact. The scanner checks eligible entities and can create a surface for missing data. Creation does not itself prove that an email or web handoff was delivered.
| Setting | What It Controls |
| ---------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| **Requirements** | Named rules defining which fields must be present for an entity type (e.g., "insurance card required for patients with upcoming appointments") |
| **Trigger** | When to check - before upcoming appointments or after recent interactions |
| **Channel** | The surface's supported email or web delivery mode |
| **Cooldown** | How long to wait before re-scanning the same entity, to prevent notification fatigue |
| **Priority** | Low, normal, or high - controls processing order |
The scanner is rule-based with no LLM involvement. It is disabled by default and configured per workspace.
### Auto-Delivery via Outbound Call
The scanner does not directly auto-deliver a surface through SMS, iMessage, or WhatsApp. The implemented auto-outreach action is an outbound voice task, where the eligible path and an outbound service are configured. Email delivery and web handoff remain separate surface-delivery operations.
## Surfaces Optimization
Surface analytics feed back into surface creation to prevent fatigue and improve completion rates.
**Agent-side intelligence** - Before creating a new surface during an interaction, the agent can query observed surface history: pending count, completion rate, and channel statistics. That evidence can inform whether to collect data verbally or use an eligible delivery channel, but it does not force a deterministic model decision.
**Gap scanner fatigue gating** - The automated gap scanner respects per-workspace limits:
| Setting | Default | What It Controls |
| ------------------------ | ------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Max pending surfaces** | 3 | Skip entities that already have this many unfinished surfaces |
| **Min completion rate** | 0% | Skip entities whose historical completion rate is below this threshold |
| **Channel optimization** | Off | Supplies the observed preferred channel as an override candidate; current delivery support still limits the result to email or web |
These settings help limit repeated outreach to people with pending forms or low observed completion.
## Delivery Channels
Surfaces are delivered through two channels - email and web link. SMS, WhatsApp, and iMessage are not supported as surface delivery channels.
| Channel | How It Works | Best For |
| --------- | ----------------------------------------------------------------------- | ----------------------------------------- |
| **Email** | Email with a branded link via the workspace's configured email provider | Longer forms, document collection |
| **Web** | Shareable link for embedding in portals or handing off directly | Integration with existing patient portals |
The workflow or agent selects between email and a web handoff according to its configured policy and the available address. During a live voice call, simple data can be collected verbally, while a photo or document requires a browser surface.
## What Surfaces Can Collect
Fourteen field types cover data collection and display:
| Type | Example Use |
| ----------------- | ------------------------------------------------- |
| **Text** | Name, address, pharmacy name |
| **Textarea** | Symptom description, special instructions |
| **Date** | Date of birth, preferred appointment date |
| **Phone** | Contact number, emergency contact |
| **Email** | Patient email for follow-up |
| **Number** | Age, weight, dosage amount |
| **Single select** | Preferred provider, insurance type |
| **Multi select** | Symptoms from a checklist, available days |
| **Checkbox** | Consent confirmation, HIPAA acknowledgment |
| **Photo** | Insurance card front/back, wound photo, ID |
| **Signature** | Digital consent signature, authorization |
| **File** | Referral letter, prior records, lab results |
| **Heading** | Display-only section title or instruction divider |
| **Info** | Display-only explanatory or warning text |
Fields support prefilling from known data (so patients do not re-enter information the system already has), conditional display (show a field only when another field has a specific value), and PHI flagging for sensitive data handling.
## Form Intelligence
Surfaces include six layers of intelligence that reduce patient effort and improve data quality:
| Capability | What It Does |
| ------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Smart formatting** | Auto-formats SSNs, ZIP codes, and phone numbers as the patient types. Corrects common email domain typos (gmailcom to gmail.com). |
| **Contextual warnings** | Cross-references fields against each other and the patient's record. If a patient enters a medication that conflicts with an allergy listed elsewhere on the form, a warning appears immediately. Age detection from date of birth triggers minor consent flagging when relevant. |
| **Input correction** | A model can review eligible values on blur. High-confidence corrections may apply automatically and can show an informational toast; lower-confidence suggestions require the patient to accept or dismiss them. Sensitive fields receive formatting-only handling. |
| **Healthcare lookups** | Medication and allergy fields search a standardized drug database in real time. Pharmacy fields search the national provider registry. Insurance carrier fields search a curated list. Results appear as the patient types, reducing free-text entry errors. |
| **OCR prefill** | For insurance card collection, patients can take a photo with their camera. The platform extracts structured fields (member ID, group number, plan name, dates) from the image and pre-fills the form. The patient reviews and confirms before submission. |
| **Abandonment recovery** | If a patient starts a form but does not finish, the agent can check which fields remain unfilled and generate a shortened follow-up surface containing only the missing fields. The patient picks up where they left off without re-entering completed data. |
## Lifecycle
Each surface progresses through a tracked lifecycle:
| Status | What It Means |
| ------------------ | --------------------------------------------------------------------------------- |
| **Created** | Surface row and specification stored; lifecycle event publication is asynchronous |
| **Pending Review** | Awaiting review before delivery (when review workflows are configured) |
| **Delivered** | Email accepted for sending or an external web handoff recorded |
| **Opened** | Patient opened the link |
| **Partial** | Some fields submitted (auto-saved as patient progresses) |
| **Completed** | All required fields submitted |
| **Expired** | TTL exceeded without completion (default 7 days, configurable 1 hour to 1 year) |
| **Archived** | Removed from active use by an authorized operator |
## Data Flow
Surface submissions can enter the world model as provenance-bearing events:
* **Source**: `surface` - distinguishable from EHR, voice, or manual imports in analytics and audit trails
* **Confidence**: Initial confidence appropriate for patient-reported data - not automatically trusted at the same level as authoritative EHR data
* **Entity association**: Creation and submission events carry the target entity when publication succeeds. Event type and projection rules determine whether and how derived entity state changes.
When a patient submits a surface, the platform stores the submission and starts a fire-and-forget `surface.submitted` event write. Entity projection is asynchronous, so successful submission does not guarantee that event publication succeeded or that a derived demographic or clinical view has refreshed. Workflows that need a submitted value immediately should use the submission record or another response documented for that path.
This means surface data participates in the same [confidence and entity-resolution rules](/data/connectors-and-ehr) as other sources. A submission keeps its surface provenance. Where the private-preview connector review flow is enabled, a configured downstream mutation can become a separate [external write proposal](/data/review-queue).
## Healthcare Examples
| Scenario | What the Agent Generates |
| -------------------------- | ----------------------------------------------------------------------------------------------------------------- |
| **Pre-visit intake** | After scheduling, send a surface with insurance card photo, pharmacy name, medication list, and consent signature |
| **Post-call follow-up** | After a triage call, send a surface with symptom tracker fields and a photo upload for the affected area |
| **Insurance verification** | During a call where insurance details are unclear, send a surface for front/back photos of the card |
| **Consent collection** | Before a referral, email a surface with a consent form, digital signature, and HIPAA acknowledgment |
| **Appointment prep** | Day before appointment, send a surface with transportation needs, interpreter request, and current medications |
## Delivery
When a surface is ready, the delivery endpoint can send it through a configured email use case or record an external web handoff. A phone-shaped destination is rejected. Lifecycle event publication and observer notifications are asynchronous and should not replace the delivery response or provider status.
### Sharing the Link
The web link is portable: the agent can read the URL aloud during a voice call for immediate access, or hand it off within an active conversation thread. The surface itself is still delivered via email or web link - SMS, WhatsApp, and iMessage are not delivery channels.
Observer events such as `surface.delivered`, `surface.opened`, and `surface.submitted` can update dashboards and active agents when publication and subscription succeed. Consumers must tolerate missing or delayed events and reconcile against stored surface state.
### Developer Console
Open **Operate > Outreach** to manage this capability. The current page groups **Surfaces**, **Pending Review**, and **Analytics** in separate tabs.
## Branding
Patient-facing surfaces adopt the workspace's visual identity automatically. Workspace administrators configure default branding - logo, primary color, background color, and font - through the workspace settings. When a surface renders, the platform applies these defaults so every form is consistent with the organization's brand.
Surface-level branding can override workspace defaults for specific use cases. For example, a workspace might use the standard brand for intake forms but apply partner-specific branding for co-branded outreach. The merge is field-level: surface-level values take precedence, and any unset fields fall back to the workspace default.
Branding changes are audit-logged and take effect on the next surface render - already-opened surfaces are not retroactively updated.
## Multi-Page Forms
Longer data collection needs can be split into sections, creating a step-by-step form experience. Each section groups related fields under its own title and description, so patients work through one page at a time rather than scrolling through a single long form.
The form renders sections as stepped pages with Next and Back navigation buttons. A progress bar at the top shows the current step and overall completion. Each step validates its fields before allowing the patient to advance - required fields, format checks, and conditional logic are enforced per step, so patients catch errors immediately rather than at the end.
Sections are useful for complex intake workflows - for example, separating demographics, insurance information, and consent into distinct steps. Auto-save works across steps, so patients can complete part of the form, leave, and return to where they left off. Forms with a single section or no sections render as a single page, maintaining backward compatibility.
## Patient Experience
Patients access surfaces through a secure link - no login, no app download, no account creation. The link contains a cryptographically signed token that grants access to that specific surface only.
The surface renders as a mobile-first browser page. All fourteen field types have patient-facing renderers; photo, signature, and date controls use supported browser capabilities. Eligible input fields auto-save as the patient progresses, allowing a later visit to resume the last successfully saved values.
File and document uploads use a dedicated upload page with drag-and-drop support, per-file progress indicators, and streaming upload for large files. The upload page validates files client-side before uploading (file type, size limits) and server-side after upload (content validation, duplicate detection).
### Inline Validation and Accessibility
Forms validate fields inline as the patient fills them out - errors appear immediately when a field loses focus, not after the patient submits the entire form. When submission or step advancement fails validation, the page scrolls to and focuses the first error field automatically.
Long text fields display a live character count that changes color as the limit approaches. The browser prompts before closing a tab with unsaved form progress. All validation messages are linked to their fields via `aria-describedby` for screen reader compatibility.
Rate limiting protects patient-facing endpoints against abuse. Clients should handle a rate-limit response and retry only after the documented interval.
## Security
* **Token-based access** - Patients access surfaces via HMAC-signed URL tokens. No login required. Each token grants access to one specific surface only.
* **Scoped access** - Dedicated `surfaces:read` and `surfaces:write` permissions control who can generate and view surfaces
* **Sensitive fields** - Fields flagged as sensitive receive additional PHI handling throughout the pipeline
* **File content validation** - File and photo uploads are validated by inspecting the file's actual content type (magic bytes), not just the declared MIME type. Files whose content does not match the allowed types are rejected before storage. This prevents disguised file uploads regardless of what the client declares.
* **Duplicate detection** - After a file uploads successfully, the platform checks for existing files with the same content hash in the workspace. Duplicates are flagged in the response but never blocked - healthcare workflows legitimately re-upload the same document, so the platform informs rather than prevents.
* **Expiration** - Surfaces automatically expire after their configured TTL, limiting the exposure window
* **Entity-scoped** - Each surface is associated with a specific entity, maintaining workspace-level data isolation
* **Rate limiting** - Patient-facing endpoints are rate-limited per IP to prevent abuse
* **Audit trail** - Authorized API actions and successfully published lifecycle events provide separate audit evidence; a surface response does not guarantee every asynchronous event is already present in the [audit trail](/operations-and-safety/compliance#audit)
{% hint style="info" %}
**Developer Guide** - For model schemas, field definitions, and API details, see [Surfaces](https://docs.amigo.ai/developer-guide/platform-api/conversations/surfaces) in the developer guide.
{% endhint %}
# Outbound
Source-backed outbound paths for SMS and iMessage conversations, direct voice calls, scheduled voice tasks, and managed voicemail delivery.
Amigo has several outbound paths with different channel support and lifecycle semantics. They share workspace authorization and use-case configuration, but they are not one automatic channel-selection system.
| Path | Supported channel | Primary contract |
| --------------------------------- | ----------------- | ------------------------------------------------- |
| **Conversation start and switch** | SMS and iMessage | Durable Conversations API |
| **Direct outbound call** | Voice | Outbound Calls API |
| **Scheduled outbound task** | Voice | `outbound_task` world-model events and dispatcher |
Email sending uses the email channel API. The conversation-start endpoint does not currently start outbound email, WhatsApp, or voice conversations.
## Outbound SMS and iMessage
The Conversations API starts a durable outbound SMS or iMessage thread. The request identifies:
* the bound service
* `channel` as SMS or iMessage
* the recipient in E.164 format
* a workspace-owned use case that resolves the sender
* an optional instruction for the opening agent turn
The caller does not supply a sender address. The platform validates the use case, dispatches the first turn, and returns the durable conversation record. A recipient reply resolves through the same provider thread key and resumes that conversation while it remains non-terminal.
Set `force_new: true` when a new outbound SMS or iMessage opener must not reuse the active thread for the same recipient and use case. The platform closes the prior active conversation before dispatching the new opener.
{% hint style="info" %}
Request models, permissions, and failure responses are in the [Conversations API guide](https://docs.amigo.ai/developer-guide/platform-api/conversations).
{% endhint %}
### Switching Between SMS and iMessage
An active durable conversation can switch from SMS to iMessage or from iMessage to SMS. A switch request supplies the target channel, recipient, target use case, and a reason. It can also request an immediate opener on the new channel.
The conversation ID and existing history remain the same. Each new turn records its own channel attribution, so consumers should render the per-turn channel rather than applying the conversation's current channel to all history.
The channel change is persisted before the optional opener is dispatched. If opener delivery fails, the conversation remains switched and the caller can retry delivery without switching again. Voice, email, and WhatsApp are not supported switch targets.
## Direct Outbound Voice Calls
Use the Outbound Calls API for an immediate voice call. This path is separate from conversation creation and does not require an `outbound_task`.
A valid request requires:
* `phone_to` in E.164 format
* an outbound-voice `use_case_id`, which resolves caller ID
* either `patient_entity_id` or `patient_canonical_id`, but not both
* a reason for the call
Optional fields include the service, goal, system-prompt override, tags, metadata, callback lineage, an idempotency key, and an outbound-task entity ID. The workspace must already have valid outbound voice configuration; an API key alone is not sufficient.
The response returns the call identifier and initial telephony status. It can also return the resolved sender information and an `event_id`. The `outbound.initiated` world-model event is emitted best-effort, so `event_id` is nullable and must not be treated as proof that the call itself was or was not queued.
### Context and Lineage
The optional goal and system prompt steer the call. If a patient identifier is supplied, the runtime can load the authorized context available for that entity. Do not assume every clinical field is present or current; projection lag, source permissions, and missing upstream data still apply.
Use `derived_from_call_sid` to associate a callback with an earlier call. Tags and metadata support external correlation and analysis, subject to their request limits.
### Idempotent Retries
Provide a stable idempotency key when a client may retry after a timeout or transient failure. This reduces duplicate call creation, but downstream telephony and world-model event delivery remain separate lifecycles. Reconcile against the returned call ID and call status.
The Developer Console does not currently provide a general-purpose **Call now** action for this API. External applications and operator workflows invoke it programmatically.
{% hint style="info" %}
See the [Outbound Calls guide](https://docs.amigo.ai/developer-guide/platform-api/conversations/calls) for the endpoint contract and examples.
{% endhint %}
## Scheduled Outbound Voice Tasks
Scheduled outreach uses an `outbound_task` entity. A deterministic trigger action can write an `outbound.scheduled` event, and the dispatcher later selects due tasks from the projected serving state.
Supported task data includes:
* destination phone number
* reason and goal
* scheduled and next-attempt timestamps
* numeric priority from 1 through 10
* maximum attempts and retry backoff
* a business-hours window and timezone
* optional patient, service, source, and context references
Higher numeric priority is dispatched first. Tasks at the same priority are ordered by their scheduled time. A task still needs a service that resolves to an outbound-voice use case before a call can be placed.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
A["outbound.scheduled event"] --> B["Asynchronous projection"]
B --> C{"Due and in window?"}
C -->|Yes| D["Resolve outbound voice use case"]
D --> E["Place call"]
E -->|Accepted| F["outbound.dispatched"]
E -->|Retriable failure| G["outbound.failed with next attempt"]
G --> C
E -->|Attempts exhausted| H["outbound.failed"]
```
The projection is asynchronous. Writing `outbound.scheduled` does not mean the task is immediately visible to the dispatcher. Dispatch claims and deterministic event identifiers reduce duplicate attempts and duplicate lifecycle events, but integrations should not describe this path as exactly once.
### Task Lifecycle
| State | Meaning |
| -------------- | --------------------------------------------------------------------------------------------------------------------------------------- |
| **Scheduled** | Waiting for its due time and business-hours window |
| **Dispatched** | A call request was accepted for the current attempt |
| **Completed** | Call completion feedback recorded a successful outcome |
| **Failed** | Attempts are exhausted; a retriable failure records its outcome and projects the task back to scheduled with a future next-attempt time |
The world-model projection can also represent cancelled and snoozed events when a supported workflow emits them. Approval, dispatch, call completion, and external delivery remain distinct states.
## Triggering Scheduled Work
Cron, supported event, and authenticated external-trigger flows can invoke an action that creates an outbound voice task. Use a deterministic outbound-task action when the phone, timing, and routing inputs are already known. Use stable external identifiers and retry logic at the integration boundary when webhook delivery can repeat.
The platform does not automatically convert every promise spoken during a call into a task. Nor does it automatically choose voice versus text or fall back from an unanswered call to another channel. Those behaviors require an explicitly configured Context Graph, trigger, or external workflow.
General population campaigns also require an explicit source of eligibility, pacing, consent, and retry policy. Customer-specific automation should not be presented as a universal campaign engine.
## Ringless Voicemail
The separate ringless voicemail channel has been retired. This does not remove answering-machine detection or configured voicemail behavior during a regular outbound call. Review those behaviors with the voice workflow; there is no standalone ringless drop operation.
## Operational Guidance
* Configure and validate the channel use case before dispatch.
* Treat agent completion, provider acceptance, and recipient delivery as separate milestones.
* Use stable idempotency keys for retried direct calls and deterministic identifiers for scheduled work.
* Respect consent, opt-out, business-hours, and contact-preference policy in the workflow that selects recipients.
* Reconcile world-model projections asynchronously rather than assuming immediate timeline visibility.
* Monitor terminal failures and exhausted retries instead of relying on automatic cross-channel fallback.
# Voicemail
Migration guidance for the retired standalone ringless voicemail channel and the separate voicemail behavior of regular outbound phone calls.
The standalone ringless voicemail channel has been retired. Its former provisioning, send, and delivery-status workflow is no longer available.
Voicemail handling during a regular outbound phone call is a separate voice behavior. Use the configured [outbound call workflow](/channels/outbound) and validate its answering-machine and voicemail behavior before outreach.
# Operators and Escalation
Human operators monitor live interactions from Runs, take over when needed, and hand control back to the agent.
Human operators handle work that needs their judgment or authority. The platform supplies controls for inspecting and intervening in eligible interactions; the organization defines staffing, handoff criteria, and the destination for unresolved work. [Operating Model](/platform-overview/operating-model#agent-to-operator) explains that division.
The Developer Console's unified **Runs** surface is the operator entry point. Its **Live** tab is the urgency-ranked queue, and an eligible row or run detail page opens takeover controls for that exact run in place.
Distinguish live takeover, transfer to an external phone destination, and approval of a proposed write. Each addresses a different problem and has its own lifecycle. The sections below cover live operation and transfer; [Review Queue](/data/review-queue) covers the separately enabled connector approval workflow.
When an operator joins a voice call, they enter the same conference as the caller and the agent. Listen mode does not transfer or reconnect the call. If the operator chooses to speak, the console requires an explicit confirmation before unmuting them and suppressing the agent's voice.
For eligible text, SMS, email, and web runs, takeover pauses the agent while the operator authors replies, then resumes it when the operator hands control back.
Example voice escalation and operator takeover sequence.
## How Escalation Policy Works
Escalation behavior is authored in the agent's context graph and instructions. Teams define which user requests, safety boundaries, unavailable tools, or uncertain situations require a transfer, callback, refusal, or operator involvement. The current runtime does not provide a separate monitor-concept system that can replace those instructions.
Runs Live shows eligible active work and uses available call signals to help order voice rows. An operator can choose a run, join in listen mode, and explicitly take over. Supported join paths emit escalation and operator-attribution events.
Define a fallback for times when no operator is available. Depending on the workflow, that can mean a configured external transfer target, a callback task, emergency instructions, or a bounded response that does not continue beyond the agent's authority.
## Runs Live and Takeover
Takeover is part of the unified Runs experience rather than a separate operator screen.
### Live Queue
The **Live** tab requests running and paused runs across supported kinds. Active conversations can appear while they are in progress; framework list and history data is best-effort and normally becomes available at terminal completion rather than serving as authoritative real-time dispatch state. Voice calls are ranked with the shared urgency rule: matched escalation data contributes risk and immediacy when available, while elapsed wait time provides a fallback for a live call without matching escalation data. Non-call runs remain visible without being treated as urgent calls.
Rows show the run type, entity, service, caller, status, outcome, turn count, direction, start time, and duration. A critical spotlight calls attention to the highest-priority eligible call. Selecting **Take over** from a row or run detail page opens a run-scoped drawer without navigating to another queue or resolving the call a second time.
### Operator Modes
Voice operators work in one of two modes:
* **Listen mode** - The operator hears the conversation but is muted at the telephony level, and the agent continues handling the call. The platform does not add operator speech or an audible join announcement; organizations remain responsible for any monitoring disclosures required by policy or law.
* **Takeover mode** - After explicit confirmation, the operator is unmuted and speaks directly with the caller. Agent speech and turn processing are suspended; caller and operator speech is captured for handback context. When the operator switches back to listen mode or leaves, the agent resumes in the existing session.
During takeover, the operator's speech is transcribed separately and recorded as operator turns when transcription succeeds. The retained call record can therefore include the human segment alongside agent and caller turns.
### Text-Channel Takeover
For an eligible live text, SMS, email, or web run, the takeover drawer shows the conversation turns. The operator explicitly pauses the agent, authors the next reply, and can continue sending replies while driving the conversation. **Hand back** returns control to the agent.
### Phone Connection
Voice operators connect over the phone network. The platform dials the phone number on the operator's profile and adds them to the conference when they answer. The Developer Console provides the controls and transcript; the operator's phone carries the audio. Carrier conditions affect the additional media leg.
Browser microphone and headset joining through WebRTC is no longer supported. Configure a reachable operator phone number before testing listen mode or takeover.
Only one operator can be active on a call at a time. If a second operator attempts to join the same call, they receive a conflict error. The same operator joining the same call again receives the cached response (the join is idempotent).
### Run Context
The takeover drawer identifies the caller and service and shows the live transcript for voice. The run detail page provides the channel-specific record behind the selected row, keeping the operator anchored to the run they chose.
### Guidance Injection
Operators in listen mode can send text guidance to the agent without taking over the call. When delivery reaches the active session, the current voice runtime interrupts agent speech and frames the guidance for the agent's next response. The API can also report queued or failed delivery, so clients should inspect the returned status rather than assume the instruction was applied.
This is useful when an operator sees the conversation going in the wrong direction and wants to steer the agent without adding operator audio to the call. For example, an operator monitoring a scheduling call could send "Ask for their insurance ID before confirming the appointment" for the agent to incorporate into its next response.
Guidance messages are distinct from external events. External events carry factual information ("The appointment has been confirmed") and queue behind the agent's current speech. Guidance carries instructions ("Ask about their insurance") and interrupts because instructions are time-sensitive.
Both event types use the active voice-session delivery path, which routes the event to the session handling the call.
## Silence Management
Silence handling is a dedicated voice-runtime behavior. It does not depend on a composite risk score or a separate conversation-monitoring service.
If the caller stops speaking, the silence monitor manages this with exponential backoff:
1. After **10 seconds** of silence, the agent generates a short check-in.
2. If there is still no response, the next threshold is **20 seconds**.
3. At the third unanswered threshold, capped at **40 seconds**, the agent generates a brief goodbye and ends the call.
Check-in utterances have a 5-second staleness window. If the caller speaks during the check-in filler, the filler is discarded and the conversation continues normally. This prevents awkward overlaps where the agent says "Are you still there?" just as the caller starts talking.
Caller speech resets the silence sequence. Safety and escalation behavior remains governed by the authored agent policy and explicit operator or forwarding workflows.
## Speaker Resolution
With three participants in a conference (caller, agent, operator), the system resolves who is speaking at any given moment using a priority chain:
1. **Operator in takeover mode** - Highest priority. Agent audio is suppressed.
2. **Caller** - Barge-in detection applies. If the caller speaks during agent output, the agent stops.
3. **Agent** - Speaks when neither the operator nor the caller is active.
Operator takeover suppresses the agent. Caller interruptions depend on the active barge-in policy and recognized speech, so background noise or speech below the configured threshold does not necessarily stop playback.
## Warm Hand-Off
Warm forwarding is a service-level call-forwarding mode, separate from an operator joining through Runs. When the agent invokes `forward_call` and the resolved forwarding configuration uses `warm_transfer: true`, the runtime keeps the caller in the conference, dials the configured destination, and gives the agent a brief hand-off turn before connecting the caller to the person who answered. Cold forwarding remains available when a briefing is inappropriate, such as an IVR, voicemail, or emergency destination.
### Phase 1: Normal
The agent and caller are in conversation as usual. Authored instructions decide when the agent should invoke `forward_call`; the runtime then resolves the destination from the supported forwarding inputs and service configuration.
### Phase 2: Briefing
After the agent's current speech drains, the runtime holds the caller and dials the forwarding target. The caller remains on hold during the briefing and cannot hear or be heard by the agent and destination. The runtime waits for a human-answer classification before beginning the briefing; an answered call alone is insufficient. The hand-off is intentionally brief and does not guarantee transfer of the full transcript, patient record, risk assessment, or recommended actions.
Barge-in is disabled during the briefing phase so speech from the caller or forwarding target does not interrupt the agent's introduction.
### Phase 3: Connected
After the briefing speech drains, the runtime takes the caller off hold before removing the agent. If unholding fails, it retains the agent rather than deliberately leaving the caller stranded. Voicemail, fax, a failed dial, or an answer timeout returns the caller to the agent. Answer classification is provider-dependent and is not a guarantee that a destination is a suitable human operator.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
sequenceDiagram
participant Patient
participant Agent
participant Destination
Note over Patient,Agent: Phase 1: Normal
Patient->>Agent: "Can I speak to someone?"
Note over Patient,Destination: Phase 2: Briefing
Agent->>Destination: Dials configured target
Note over Patient: Remains on hold during briefing
Agent->>Destination: AI briefing (destination hears)
Note over Patient,Destination: Phase 3: Connected
Note over Agent: Removed from call
Patient->>Destination: Direct conversation
```
A service forwarding configuration explicitly selects warm or cold transfer and either a fixed destination or a dynamic number supplied by the agent. Without that configuration, the forwarding tool is unavailable. State policy can further restrict forwarding. Destination selection does not inherit a fallback number from workspace settings.
## Deferred Transfer
When the agent initiates a call transfer (for example, forwarding to a clinic's front desk), the transfer is deferred until the agent's goodbye message finishes playing. This prevents the caller from being redirected mid-sentence. If the caller speaks during the goodbye (barge-in), the transfer is cancelled and the conversation continues. If an operator joins the call during this window, the transfer is also cancelled.
## Operations Views
Operators register with a profile that includes their name, skills, phone number, and role. Their status is tracked as online, busy, or offline.
The Developer Console separates live intervention from historical review:
* **Runs > Live** - Urgency-ranked live work and in-place takeover.
* **Runs > All runs** - Filterable conversation and framework history.
* **Runs > Overview** - Workspace totals and status distributions.
* **Operator analytics and audit** - Escalation, response-time, handle-time, and attributed operator-action records exposed through the operator and analytics APIs.
## Escalation as Collaboration
The agent handles the routine part, and the operator handles the part that needs human judgment. Both contribute to the same run record. After a voice takeover, the agent can resume with the captured caller and operator turns as handback context.
Use escalation rates, response times, handle times, and fallback outcomes to inform staffing. Do not assume automation removes the need to staff authored escalation paths or maintain an unavailable-operator fallback.
{% hint style="info" %}
**Developer Guide** - For API endpoints and integration details, see the [Operators](https://docs.amigo.ai/developer-guide/platform-api/conversations/operators) reference in the developer guide.
{% endhint %}
# Runtime Safety
Current runtime safety controls, their enforcement boundaries, operator intervention, and evidence-based release practices.
Runtime safety is a layered system. Authored conversation policy guides the agent, structural controls constrain supported execution paths, server-side authorization limits writes, and operators can intervene through the unified Runs surface.
The current architecture does not depend on a separate semantic monitoring or regulatory-triage service. Safety-critical behavior must be expressed in the agent's context graph, tool permissions, escalation instructions, and operating procedures, then verified against representative scenarios.
## Control Map
| Control | Scope | Current Behavior |
| --------------------------------------- | -------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Context graph policy** | Voice and text | States define objectives, available tools, exit conditions, guardrails, and boundary constraints that shape agent behavior. |
| **Graph navigation invariants** | Platform-managed context graph runtime | Navigation resolves to an engageable state, detects loops, and caps per-turn transitions in code. |
| **Cross-runtime invariant observation** | Voice | The platform records shadow verdicts for engageable-state, loop, and iteration checks. These verdicts do not change the live call. |
| **Response guardrail observation** | Voice | Candidate responses are compared with the active state's guardrails and boundary constraints in shadow mode. Verdicts are diagnostic only. |
| **Integration approval policy** | Text conversations | A top-level integration tool call can pause for an authorized approve or reject decision when its integration policy gates the operation. |
| **Write scope** | Supported agent write tools | A server-side write scope binds model-originated writes to an allowed workspace and entity; each registered tool constrains its resource shape and source-appropriate confidence. |
| **In-flight write deduplication** | Supported voice runtimes | An identical write-tool call is short-circuited while the first invocation is still running. A later invocation can proceed after the first finishes. |
| **Outbound policy** | Connector delivery | Source, confidence, schema, dependency, and destination rules determine whether an event is eligible for unattended delivery. |
| **Operator control** | Eligible live runs | Authorized operators can listen, take over, send guidance, author a text turn, and hand control back, depending on channel. |
This map distinguishes controls that actively enforce behavior from controls that only produce evidence. That distinction matters when setting clinical and operational expectations.
## Safety in the Agent Policy
The agent evaluates the conversation within its normal reasoning loop. There is no independent subsystem that can compensate for missing escalation instructions or incomplete boundaries.
For each safety-sensitive state, define:
* **Objective** - What the agent is trying to accomplish in that state.
* **Allowed tools** - The smallest tool set needed for the task.
* **Boundary constraints** - What the agent must not claim, recommend, or attempt.
* **Escalation conditions** - Observable situations that require a human or a configured transfer target.
* **Safe fallback** - What the agent should say and do if the required person, tool, or destination is unavailable.
* **Exit conditions** - The evidence needed before the graph advances.
On the Platform API, reusable policy that spans states should be expressed through shared context graph structure, state guidance, transitions, eligible tools, and tested authoring conventions. Classic dynamic behavior sets are a separate Classic API capability and are not a Platform runtime control.
{% hint style="warning" %}
Safety instructions are model-facing policy. They are not a substitute for server-side authorization, clinical governance, or a staffed escalation process.
{% endhint %}
## Structural Navigation Controls
The platform-managed context graph navigator enforces three structural properties during a turn:
1. **Engageable landing** - Routing states are resolved until the conversation reaches a state that can handle the next user interaction.
2. **Loop handling** - Repeated navigation is detected so the engine does not traverse the graph indefinitely.
3. **Transition cap** - A bounded number of state changes can occur within one turn.
If navigation cannot resolve safely, this runtime stays on the last engageable state rather than presenting a routing-only state to the caller.
The voice layer also observes these properties across supported runtimes. That observer is shadow-only: it records diagnostic verdicts but does not interrupt, reroute, or end a call. Runtimes that navigate independently therefore do not inherit the platform-managed navigator's enforcement merely because they produce the same telemetry.
## Guardrail Evaluation Status
State guardrails and boundary constraints are included in the agent's active instructions. Separately, the platform runs a lightweight response-text evaluator on voice calls and records whether a candidate response appears to overlap a configured rule.
{% hint style="warning" %}
The response evaluator is shadow-only. A recorded `block` verdict does not block or rewrite the response, and evaluator failure does not affect the call. Treat these verdicts as calibration and regression evidence, not as an enforced clinical safety boundary.
{% endhint %}
Because shadow evaluation observes text rather than clinical truth, teams should review false positives and false negatives before using its output in an operational process.
## Write Safety
### Integration Tool Approval
Workspace integrations can set an approval policy of `none`, `writes`, or `all`. On supported text conversation paths, a gated top-level integration call is parked before execution until an authorized reviewer approves or rejects it. The default is `none`.
This mechanism is conversation-scoped and fail-closed. It does not currently gate integration tools called from companion skills, and it does not apply to voice execution. It is also separate from external write proposals: integration approval pauses a conversation tool call, while an external proposal stages a connector payload for later review and delivery.
### Agent Write Scope
Supported agent write tools receive a server-constructed write scope that restricts which workspace and entity the operation can target. The registered tool contract separately constrains the resource shape and assigns or caps the confidence available to model-originated data.
These checks protect the persistence boundary even if the model supplies an unexpected identifier. System-originated connector and projection work follows separate trusted-service authorization and is not evidence that an agent can bypass its own scope.
### Duplicate Calls
Supported voice runtimes track identical write-tool calls that are already in progress. If the model repeats the same write before the first completes, the duplicate is rejected as already running. This prevents concurrent duplicates; it is not a permanent idempotency guarantee for later calls.
Operations that need durable idempotency should still use the operation's documented idempotency key or destination-specific protection.
### External Delivery
Recording an observation in the world model does not confirm an external mutation. Unattended connector delivery evaluates the event against its source, confidence, schema, dependencies, and configured destination.
The standard automated outbound path is at-most-once and has no reconciliation loop. A transient failure can remain a permanent failed delivery unless the customer verifies and retries it through an appropriate workflow.
Review-gated external write proposals are a separate private-preview capability. Where enabled, a source-eligible connector event for a review-configured destination is staged at any confidence, and an authorized reviewer can approve or reject that specific payload and target. Approved FHIR-sink proposals can be retried under their idempotent delivery policy; other sink types receive at most one automatic vendor call and then require investigation or manual reconciliation after an ambiguous failure. This flow does not restore the retired general review queue and does not make every world-model observation human-reviewed.
## Human Intervention
The unified Runs surface gives operators one place to monitor eligible live work:
* **Voice** - Join in listen mode, explicitly take over, send guidance, switch mode, and hand the call back.
* **Text channels** - Pause an eligible run, author the next turn, and hand control back.
* **History** - Inspect the transcript, run metadata, available analysis, and recorded operator actions.
Operator actions require the Operator update permission, available to operator, admin, and owner roles. Supported action routes bind the requested operator identity to the authenticated caller and emit operator-attributed events for takeover-related actions.
An authored escalation policy must also define what happens when no operator is available. Appropriate fallbacks can include a configured transfer target, callback workflow, emergency instruction, or a bounded refusal. Do not assume the platform automatically pages a clinician or creates a post-call review item.
## Validation Before Release
Simulations exercise the current workspace configuration through the real reasoning and tool path. Simulation-originated world-model writes are tagged so production EHR delivery and production analytics can exclude them, but simulations do not create an isolated configuration branch and do not replace every external dependency with a stub.
Use dedicated test workspaces, test entities, or safe integration environments when a scenario could reach a real external system. Separate broad text-tier validation from real-audio tests that measure transcription, speech rendering, turn timing, and media attachment.
A practical release review includes:
1. Run targeted cases for each safety boundary and escalation path.
2. Run regression suites against the configuration intended for release.
3. Inspect normalized checks, transcripts, tool calls, and failure reasons.
4. Review shadow guardrail and control-invariant evidence where available.
5. Confirm operator staffing and fallback procedures.
6. Deliberately update the pinned `release` version set when the evidence is acceptable.
Simulation results and drift analysis do not automatically block version-set promotion or roll back a release. Promotion and rollback are deliberate operator actions.
## Production Review
After release, use conversation evaluations, run history, connector outcomes, and operational metrics to find changes in behavior. Compare defined cohorts and stable time windows rather than treating a single aggregate score as proof of safety.
When a regression appears:
1. Identify affected channels, services, versions, and cohorts.
2. Add or update a reproducible simulation case.
3. Verify whether the issue is agent behavior, tool behavior, media quality, or destination failure.
4. Correct the smallest responsible configuration or integration boundary.
5. Re-run the affected suite before moving the release pin.
## What Runtime Safety Does Not Guarantee
* **Perfect outcomes** - Model behavior and external systems remain fallible.
* **Automatic clinical triage** - Organizations must author, test, and staff their own clinical escalation protocols.
* **Enforced shadow verdicts** - Guardrail and cross-runtime invariant observers currently record evidence only.
* **Universal human review** - Only supported top-level text integration calls and enabled private-preview external write proposals use their respective approval paths.
* **Automatic deployment rollback** - Teams decide when to move a version-set pin.
* **Automatic outbound reconciliation** - Standard unattended connector delivery is at-most-once.
{% hint style="info" %}
Triage and safety evaluation support operational decisions; they do not replace clinical assessment. Organizations remain responsible for clinical protocols, escalation staffing, destination verification, and regulatory review.
{% endhint %}
## Related Documentation
* [Context Graphs](/agent/context-graphs)
* [Operators](/operations-and-safety/operators)
* [Testing and Evaluation](/testing/testing)
* [Connectors and EHR](/data/connectors-and-ehr)
* [Compliance](/operations-and-safety/compliance)
* [Safety and monitoring APIs](https://docs.amigo.ai/developer-guide/platform-api/safety)
# Compliance and Audit
Authentication, access control, audit evidence, workspace isolation, outbound authorization, and assurance boundaries for regulated healthcare environments.
The Amigo platform is built for regulated healthcare environments. Its technical controls and evidence surfaces can support a customer's compliance program, but product behavior alone does not establish legal compliance. Applicable agreements, deployment configuration, operating procedures, and customer responsibilities remain part of the control environment.
## Authentication and Access Control
The platform applies authentication, authorization, and workspace scoping at defined service and route boundaries. The exact controls depend on the surface and credential type, so customers should validate the routes they use rather than infer universal coverage from this overview.
### Role-Based Access Control
Permissions follow five default workspace roles. Viewer is the read baseline. Member and operator branch from that baseline for different jobs; admin combines member capabilities with configuration administration and supported operator actions. Owner currently carries the admin permission set but is required by owner-only workflows. The API-key permission catalog is the authoritative source for the current defaults.
| Role | Permissions |
| ------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Viewer** | Read the workspace resources and data included in the default viewer grant set. |
| **Member** | Viewer access plus supported create, send, trigger, conversation, and data-write operations. Configuration update and delete operations remain admin-level. |
| **Operator** | Viewer access plus review actions and supported live-run guidance or takeover operations. Operator is not a data-ingestion role. |
| **Admin** | Member access plus configuration CRUD, member administration, audit access, supported operator actions, and workspace administration. The default catalog includes `Workspace:Delete`, although individual routes can add conditions. |
| **Owner** | The admin permission set plus eligibility for owner-only workflows, including workspace archive and issuing owner-role API keys. |
Permissions are workspace-scoped. A user can be an admin in one workspace and a viewer in another. This matters for multi-site healthcare organizations where clinical staff at one location should not have configuration access to another.
### API Keys
API keys provide bearer-token authentication for programmatic access. A key selects one default role and can optionally carry a subset of that role's permissions. The requested role and permissions cannot exceed the creator's own access, and only an owner can issue an owner-role key.
### SSO with Identity Federation
Users authenticate through their organization's identity provider. The platform supports both OIDC and SAML federation. Auto-provisioning creates platform credentials on first login based on domain policies, so IT teams do not need to manually create accounts for every user.
### Multi-Factor Authentication
TOTP-based second factor for accounts that do not use SSO. Recovery codes are generated at enrollment for account recovery if a device is lost. MFA is enforceable per SSO connection with admin visibility into enrollment coverage across the workspace.
### Session Enforcement
Supported interactive sessions apply configured idle timeouts. If a session is inactive beyond the configured threshold, it is terminated automatically. Concurrent-session limits can expire the oldest session when a new login exceeds the configured limit.
Token rotation includes theft detection. When a refresh token is used, a new one is issued and the old one is invalidated. If the old token is presented again (indicating it was copied before rotation), all sessions in that token family are revoked immediately. Sender-constrained tokens remove the need for rotation entirely - see [Token Security](#token-security) below.
### IP Allowlists
Workspaces can configure CIDR-based IP restrictions for supported identity token flows. When an active allowlist is resolved successfully, an address outside the configured ranges is rejected. If the policy cannot be evaluated, the request is allowed, so combine this control with network and credential safeguards rather than treating it as a universal request firewall.
### Progressive Account Lockout
Supported identity flows record failed attempts and apply progressive lockout thresholds. If lockout state cannot be evaluated, the request is treated as unlocked. Rate limits and upstream identity-provider controls remain separate safeguards.
### Agent Session Tokens
Supported agent sessions use short-lived delegated tokens bound to a workspace and a call or job. Administrative, credential-management, and further-delegation scopes are stripped, and the effective role is capped below the admin tier. Tool availability and reads still depend on the runtime policy and any external-principal binding; the token alone should not be interpreted as entity-scoping every read. Supported agent world-write tools use an additional server-constructed entity write scope.
### External Caller Identity
A customer-hosted application can bind its verified external user identity to a patient entity in the workspace. At conversation start, the platform resolves that binding so a recognized caller receives the correct world-model context and returning-user memory. An unbound caller starts anonymously rather than being matched by guesswork.
Patient identity bindings are separate from [external principals](#external-principals), which represent clinicians and other role-scoped users. A patient binding cannot target an entity with active principal roles, preventing patient recognition from becoming an authorization path. This binding surface is not part of the current public Platform API contract.
### Machine-to-Machine Authentication
The platform supports OAuth 2.0 client credentials grants for machine-to-machine integrations. Services authenticate by exchanging a client ID and secret for an access token, without user interaction. This is the standard pattern for backend integrations, scheduled jobs, and CI/CD pipelines that need to call the platform API programmatically.
## Credential Security
Client secrets used for machine-to-machine authentication are hashed with an industry-standard key derivation function, following OWASP recommendations, before storage. Plaintext secrets are returned once at creation time and are never stored or retrievable afterward.
## Token Security
The platform supports sender-constrained tokens using the DPoP standard (RFC 9449, Demonstration of Proof-of-Possession). When enabled, access and refresh tokens are cryptographically bound to a key held by the client application. Even if a token is intercepted in transit or extracted from logs, it cannot be used by a different client because the receiving service verifies that the caller holds the corresponding private key.
Sender-constrained tokens also eliminate a class of race conditions in token refresh flows. Because the token is bound to a specific client key, the platform does not need to rotate refresh tokens on each use - removing the window where concurrent refresh attempts from multiple tabs or network retries could invalidate a session, and eliminating the grace window where two valid tokens coexist.
## Identity Linking and Provider Trust
When an operator accepts an invitation through one authentication method (such as a magic link or email code) and later signs in through a different provider (such as Google), the platform can automatically link the two identities to the same operator entity. This cross-provider linking is gated by a trust rule: the second provider must be authoritative for the operator's email mailbox at the time of sign-in. For corporate domains, this means the provider must manage the domain's accounts through its own administration. For consumer email addresses hosted natively by the provider, controlling the account is equivalent to controlling the inbox. A consumer account registered under a third-party corporate email address does not qualify, because the provider's historical email verification does not prove current inbox control.
If an operator entity already has a linked identity for the incoming provider under a different subject, the platform refuses the new link and logs an identity conflict for administrator resolution. Every automated identity link is audit-logged with the providers involved, email address, and external subject identifier.
## Federated Identity and Invitation Recovery
Workspace operators are sometimes invited via one authentication method (such as magic link or email one-time password) and later expected to sign in through the workspace's federated identity provider (OIDC or SAML). Because the invitation was accepted under a different provider, the operator's identity record does not match the federation source, and the federated login would otherwise fail.
The platform handles this by checking whether the email asserted by the identity provider matches an active member of the federation source's own workspace. If it does, the login succeeds with the token scoped strictly to that workspace - a workspace-scoped identity provider can never issue tokens for workspaces outside its own boundary. No durable federation identity is created during this recovery, so each subsequent login re-verifies active workspace membership. Pending invitations are not auto-accepted from an identity provider assertion - operators accept invitations through the standard console flow, which independently verifies the invited email.
This recovery path is audit-logged with a dedicated event that records the federation source, the matched provider, and the asserted email.
## Operator Identity Enforcement
Supported operator action routes, including join, mode switch, leave, guidance, wrap-up, and run-scoped takeover routes, enforce server-side identity binding. The platform verifies that the authenticated caller matches the operator profile being acted as before allowing the action to proceed. Mismatched identity attempts are logged and rejected. This prevents a client-supplied operator identifier from becoming an impersonation path on those routes.
## Audit
### Note-Generation Raw Output Archive
When the platform generates a structured clinical note, it best-effort archives the verbatim model completion - the text the model returned before parsing and template validation - alongside the parsed note. Each generation produces its own addressable archive entry stored in the same protected location as transcript and note artifacts, under the same access controls.
Archiving runs asynchronously on a best-effort basis. An archive-write failure does not block the committed note or session progress, so a completed note does not prove that a raw-output archive exists. Raw completions can contain sensitive information and need the same access and retention review as other clinical artifacts.
### Cross-Workspace Audit Reads
Two additional read paths complement the per-workspace audit log:
* **Personal trail.** An authenticated caller whose credential is bound to an actor entity can retrieve audit events matching that actor across workspaces. The actor identity is set server-side; credentials without an actor entity are rejected. No workspace-level audit permission is required.
* **Platform-wide trail.** Platform administrators can query audit events across all workspaces, including events that carry no workspace - such as login events that occur before workspace activation. This path requires the `platform:admin` scope.
Workspace-scoped audit reads are unchanged. The per-workspace endpoint continues to return only events belonging to the specified workspace.
Some audit events, including login and credential-theft detection, carry no workspace association. Workspace-scoped queries exclude them. The platform-wide path can retrieve them; a personal query remains limited to events matching the credential's actor entity.
The platform provides a workspace-scoped audit surface for supported platform events, including sensitive data access and selected configuration or operator actions. Available fields depend on the event producer; the audit schema supports actor identity, timestamp, credential, network context, action, resource, and PHI classification.
On the MCP data access surface, covered reads that return patient-identifying data - including entity listings that project display names and medical record numbers - schedule an audit record with the action, resource type, tool name, and result status. Audit-write failures surface operational warnings but do not make the read fail, so customers should monitor audit delivery rather than infer transactional coupling. Schema-discovery operations that return only tool metadata and no PHI are excluded.
Audit API responses conform to the published response schema. Fields that are not available for a particular producer are returned as nullable values rather than inferred.
Workspace-scoped audit queries return entries for the requested workspace and require the applicable audit permission. Personal and platform-wide queries use the separate authorization rules above. Available actor, resource, and workspace fields depend on the event producer; inspect their coverage when assembling an access review.
### PHI Access Logging
Supported PHI-sensitive routes classify their audit events for compliance reporting, including selected entity reads, patient-data access, call recordings, and intelligence views. Customers should validate route coverage against their own audit requirements rather than infer universal coverage from the PHI report alone.
### Principal Session Audit
When a workspace credential starts a conversation anchored to an entity that has an active external role assignment, the platform treats this as principal impersonation - the session acts as that external principal with the principal's role-scoped tool access. This action requires admin or owner credentials and is recorded as a dedicated audit event (`principal.session.opened`) capturing the conversation ID, the acting credential, and the target entity. This ensures that every principal impersonation through the API-start path is traceable to a specific credential and entity.
### Session Token Delegation
When a short-lived session token is minted from a parent credential, the platform records a structured audit trail of the role derivation decision. This includes the parent's claimed role, the role inferred from the parent's actual permissions, the effective role assigned to the child token, whether the role was capped due to privilege restrictions, and the parent token's provenance chain. If a parent's role claim is rejected as inconsistent with its permissions, a dedicated audit event is emitted so security teams can identify forged or drifted credentials without searching through general session logs.
### Workspace Access Auditing
Supported Identity workspace-access routes are wired to append structured audit events for member additions and reactivations, role changes, ownership transfers, removals, invitation sends and resends, acceptance, decline, revocation, and membership bootstrap or auto-provisioning. Successful audit records include the acting identity, workspace, target resource, and operation-specific details. Membership mutation and audit append are separate operations, so monitor audit delivery and reconcile access state rather than treating the log as transactionally complete proof of every transition. These records can support SOC 2 access reviews and HIPAA workforce-clearance evidence.
### Audit Queries
The compliance dashboard provides four views into the audit trail:
| View | What It Shows |
| --------------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| **Audit events** | Retained audit entries with filters for service, action, actor, resource type, resource ID, PHI classification, and date range |
| **PHI access report** | Covered entries classified as PHI access, for use in customer investigation and reporting workflows |
| **Entity access log** | Retained audit entries that match a specific resource identifier |
| **Audit summary** | Counts of matching events, PHI-classified entries, actors, and services within the requested scope |
### Audit Log Export
Audit exports run asynchronously for a selected date range. Once ready, the export provides CSV chunks through short-lived download links. Treat export identifiers and URLs as sensitive; the [Developer Guide](https://docs.amigo.ai/developer-guide/platform-api/safety#audit-log-export) describes submission, polling, and link refresh.
Creating an export records a PHI-sensitive audit event. Downloading a chunk through its presigned link is a separate operation and does not establish a new Platform download audit event. The former synchronous NDJSON export and its 50,000-event cap no longer describe the current workflow.
### Compliance Reporting
Two compliance evidence exports are available:
| Report | What It Provides |
| ------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **HIPAA evidence report** | Produces a partial evidence summary for a configurable period (default 90 days), including audit statistics, configured retention values, declared encryption flags, and an API-key summary. The current response returns `compliance_status: partial`; MFA coverage, SSO enforcement, allowlist status, session timeout, and locked-account fields are not currently populated. |
| **Access review export** | Lists API key credentials with role, status, and activity dates. Interactive user and session credentials are not included in the current export. |
### Service Authentication
Internal platform services can authenticate using verified client certificates instead of shared secrets when requesting machine-to-machine tokens. Each service credential uses exactly one authentication method - certificate-based or secret-based - and the two are never combined. Certificate-based authentication is restricted to internal service-account credentials; external and provider integrations continue to use client secrets.
Failed certificate authentication attempts are logged but do not trigger account lockout, because the certificate identity is verified at the transport layer and cannot be brute-forced. This prevents a misconfigured service from locking out the legitimate credential holder.
## Audit Trails Through Event Sourcing
The [world model](/data/world-model) stores observations as append-only events. When a modeled fact changes, a new event can supersede the prior observation without rewriting it. This event history is distinct from configuration records, audit events, and external destination logs, which follow their own storage models.
This architecture provides event-level evidence for modeled data:
* **What was known, and when.** For modeled facts with retained event history, replay up to a timestamp can reconstruct the observations available at that point.
* **Where data came from.** Every event records its source (EHR sync, voice call, manual import, agent inference) and its confidence level.
* **What changed, and why.** When an entity's state changes, the event that caused the change is traceable. Superseded events are linked to the events that replaced them.
* **Who accessed supported resources.** API access is scoped to authenticated accounts, and covered access paths emit separate audit events.
Event history and access audit serve different purposes. Event history explains changes to modeled state; the audit surface records covered actions by authenticated actors. Neither should be treated as a substitute for destination-system evidence.
## HIPAA Considerations
Amigo workflows can process protected health information (PHI). Review the following controls against the data, access paths, and operating responsibilities in the proposed deployment:
### Isolation
Customer-facing PHI access is scoped to the workspace at defined storage, query, and route boundaries. Each workspace has its own logical world model, data-source configuration, and access controls. A multi-site healthcare organization can use separate workspaces per clinic so each site's patient data is available only through credentials authorized for that workspace. Customers should still validate the exact storage and access paths in their deployment rather than infer a universal isolation mechanism from this overview.
### Access Control
The platform provides RBAC and supports MFA, SSO, IP restrictions, session controls, and progressive lockout on their documented identity and application paths. These controls do not all apply at every access point, and allowlist or lockout backing-service failures can fail open. See [Authentication and Access Control](#authentication-and-access-control) for the boundaries of each control.
#### External Principals
For sessions driven by external users (such as partner clinicians or care coordinators), the platform supports entity-anchored, role-scoped access control. An external user is bound to a workspace entity with assigned roles, and role grants determine which integration endpoints, skills, and knowledge base scopes the session can access. Grant changes insert a new record and supersede the prior one, preserving authorization history. Identity injection through token-exchange bindings prevents the agent from supplying or overriding a bound identity parameter. Sessions without an external-principal binding use the ordinary workspace and session authorization path; they do not inherit a principal role grant.
### Data Minimization
The three data channels in the world model (ambient, queried, extracted) control what information is available to the agent at a given moment. Ambient context is configured per service, queried data requires an explicit tool call, and extracted observations retain source and confidence. External delivery is a separate policy decision; configured private-preview proposal flows add human approval only for the specific writes they gate.
#### Call Analysis Pipeline
The structured execution-trace input to post-call quality analysis includes tool names, input key names, output lengths, success/failure flags, state names, confidence scores, emotion labels, and latency values. It excludes raw tool arguments and results. This limit applies to that trace input; transcripts, recordings, and other analysis inputs have their own data-handling requirements.
### Encryption
Data is encrypted in transit and at rest. Voice call audio, transcripts, and world model events are stored with encryption. Specific encryption standards and certifications are available on request.
### Field-Level Encryption
User variables that contain credentials or API keys for tool execution are encrypted at rest and are write-only through the API. They are decrypted for authorized runtime use. This field-level control applies to those secret variables; review encryption coverage and key management for other data classes in the assurance package.
## Confidence and External Write Authorization
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
V[Patient interaction] --> E[Observation with provenance]
E --> W[World model confidence and conflict resolution]
W --> G{Outbound policy selects this event?}
G -->|Private-preview review policy| P[External write proposal]
P -->|Approved| X[External system]
P -->|Rejected| R[No delivery]
G -->|No approval required| X
```
[Confidence and provenance](/data/world-model) preserve where a modeled value came from and help prevent a less reliable observation from silently replacing stronger evidence. External-write approval is a separate private-preview authorization path for configured mutations; it is not a universal review stage.
Consider the flow:
1. A patient mentions a new pharmacy address during a phone call.
2. The agent records the observation with transcript provenance and source-appropriate confidence.
3. Higher-confidence evidence can supersede the value without erasing the original observation.
4. Outbound policy determines whether the event is eligible for unattended delivery or requires a configured proposal flow.
5. Where private-preview review is enabled, an approved proposal enters its separate delivery path, with destination-specific retry and failure semantics.
Recording an observation therefore does not confirm an external mutation. Event provenance, proposal decisions where enabled, connector outcomes, and destination records provide evidence at separate boundaries. Customers that need an end-to-end chain should correlate those records with stable identifiers and verify the destination state.
## PHI in Voice Calls
Voice calls present specific PHI handling considerations:
* **Transcripts** contain PHI by nature (patient names, conditions, medication details). They are stored in the workspace's world model with the same isolation and access controls as all other data.
* **Audio recordings** are stored encrypted and scoped to the workspace. Retention policies are configurable.
* **Emotion detection data** is processed in real time and stored as aggregate signals (valence, arousal, trend), not raw audio. The emotion pipeline does not retain audio segments after processing.
## Certifications and Agreements
{% hint style="success" %}
Amigo maintains a SOC 2 Type II report and supports HIPAA-regulated workloads. BAAs are available for covered customers. Current assurance materials are available through the Trust Center.
{% endhint %}
| Assurance | Status | Scope |
| ----------------- | ------------------------ | ---------------------------------------------------------------------------- |
| **SOC 2 Type II** | Current report available | Security trust services criteria within the report's stated scope and period |
| **HIPAA** | Supported with BAA | PHI safeguards and contractual coverage defined by the applicable agreement |
| **GDPR** | DPA available | EU data-processing terms defined by the applicable agreement |
Downstream vendor coverage, subprocessor terms, and any applicable BAAs are controlled assurance materials rather than guarantees inferred from this product overview.
BAAs are available for HIPAA-covered customers. Contact or visit the [Trust Center](https://trust.amigo.ai) for certification details and audit reports.
## Webhook Security
Classic SMS, email, and iMessage use cases can POST inbound-turn payloads to their configured receiver. Classic channel delivery signs those payloads with HMAC-SHA256 using a per-use-case secret. Explicit secret rotation returns the new secret once and dual-signs with the old and new versions for a 30-minute grace window. Changing the webhook URL remints the secret without that grace period. This Classic channel webhook path is separate from Platform triggers.
Platform triggers use authenticated trigger-fire calls rather than Platform-hosted vendor webhook destinations. Customers verify a vendor webhook in their own integration layer, normalize its input, and then call the trigger endpoint with a permitted Platform credential. Classic webhook signing and secret-rotation behavior does not describe this Platform trigger path.
## Infrastructure Security
* **Encryption** - The Platform compliance response declares encryption at rest and in transit. Detailed scope, protocols, and control evidence belong in the current assurance package.
* **Identity controls** - SSO, MFA, session controls, IP restrictions, and progressive lockout apply on their documented paths and have the availability boundaries described above.
* **Deployment boundaries** - The assigned regional hostname determines the serving deployment. Workspace metadata is not a placement or migration control. Confirm residency and isolation against the agreed deployment and its actual data paths.
* **Operational assurance** - Current vulnerability-management practices, incident commitments, penetration-test coverage, transport controls, and change-review evidence are available through the Trust Center or applicable contract. This page does not promise a universal mTLS design or fixed operational cadence.
## Data Lineage Boundaries
World-model events carry event-level source, confidence, and supersession information. The current per-entity provenance view exposes entity identity and historical merge information, but it should not be treated as a complete chain of custody. In particular, the unified lineage response does not currently populate outbound-sink or review-history records.
Use connector delivery outcomes and destination-system records to prove an external mutation. Use the audit API for covered actor actions and PHI access. Use external write proposal records only where that private-preview flow is enabled. These records can be correlated, but they are not presented as one universally complete per-entity timeline.
## Retention Policies
Per-workspace retention policies record intended retention periods. The default shown by the platform is 2,190 days; organizations should confirm that value against their record type, contracts, jurisdictions, and legal-hold requirements.
| Data Type | Default Retention | Configurable Range |
| ------------------ | ------------------- | ------------------ |
| Call recordings | 2190 days (6 years) | 1-100 years |
| Call transcripts | 2190 days | 1-100 years |
| Audit logs | 2190 days | 1-100 years |
| World model events | 2190 days | 1-100 years |
| PHI data | 2190 days | 1-100 years |
**Legal hold** records an override to the configured retention policy and includes a reason for documentation. Because automated retention deletion is not yet enforced, organizations must implement and verify the corresponding operational hold process.
{% hint style="info" %}
Retention policies are currently advisory - the policy is stored, displayed, and available for compliance reporting, but automated deletion is not yet enforced.
{% endhint %}
## Ongoing Compliance
Compliance is not a one-time certification. The platform supports ongoing compliance through:
* **Audit queries** - Covered platform events can be filtered by actor, service, action, resource, PHI classification, and date
* **PHI access logging** - Covered PHI-sensitive paths classify audit events for dedicated reporting and investigation
* **Event provenance** - World-model observations retain source, confidence, and supersession evidence
* **Retention policies** - Documented defaults with per-workspace configurability and legal hold; automated deletion is not currently enforced
* **Compliance reports** - A partial HIPAA evidence summary and an API-key access-review export
* **External write decisions** - Private-preview proposal records preserve reviewer decisions for the specific mutations routed through that flow
* **Authored safety policy** - Context graphs, tool permissions, escalation instructions, and operator procedures define the active runtime boundary (see [Runtime Safety](/operations-and-safety/runtime-safety))
* **Assurance evidence** - Current control evidence and operating commitments are maintained in the Trust Center and applicable agreements
Event history, confidence-aware outbound policy, covered audit events, access controls, and documented operating procedures provide evidence for compliance programs. Organizations remain responsible for validating coverage against their legal, contractual, and governance requirements.
For API details on workspace permissions, audit reporting, runtime controls, and operator workflows, see the [Developer Guide](https://docs.amigo.ai/developer-guide/platform-api/safety).
# Testing Overview
Simulations, interactive testing, voice-path checks, metrics, and trend review support deliberate verification before and after deployment.
The platform provides a testing and evaluation framework for verifying agent behavior before deployment and measuring quality in production. This section covers simulations for repeatable behavior checks, the playground for interactive testing, tiered voice testing, metrics for scoring conversation quality, and a practical process for finding degradation in those results over time.
## Choose Evidence for the Question
| Question | Start with | Additional evidence needed |
| ------------------------------------------- | --------------------------------------------------------------------------------- | ----------------------------------------------------------------------------- |
| Does the authored workflow handle the case? | [Simulations](/testing/testing/simulations) and observed graph/tool activity | Representative context and failure cases |
| Does the experience work over audio? | [Voice Simulation](/testing/testing/voice-simulation) and the intended voice path | Speech, timing, interruption, and transport behavior |
| Does an external action complete correctly? | Isolated tool and integration tests | Destination acknowledgement or reconciliation under that operation's contract |
| Is the released workflow improving? | [Metrics](/testing/testing/metrics), comparable cohorts, and production examples | Missing-result accounting and the actual operational outcome |
Testing produces evidence for a release decision. The [operating model](/platform-overview/operating-model) assigns that decision, and the [deployment model](/platform-overview/deployment-model) describes how to select the reviewed configuration. The detailed sections below explain the available test paths.
## Testing Philosophy
Healthcare workflows can span data retrieval, identity verification, external writes, and human follow-up. Each step needs evidence appropriate to its failure modes.
Testing every branch through live calls is slow and makes reasoning failures difficult to separate from audio or integration failures. The platform uses three principles:
1. **Use controlled workspace context.** Simulations read current workspace state. Dedicated test workspaces or entities provide stable fixtures when comparison across runs matters.
2. **Exercise the real reasoning and tool path.** Text simulations run context graphs and tools rather than replacing external calls with generic stubs. Simulation-aware platform workflows exclude tagged writes from their production processing, while unsupported effects such as surface delivery remain disabled. External tools still require isolated test credentials and data; provenance is not a universal side-effect sandbox.
3. **Validate audio and integrations at their own boundaries.** Real-audio tests cover speech and transport behavior. Connector and approval workflows need an appropriately isolated integration environment when their live behavior is under test.
This structure keeps broad reasoning regression tests fast while preserving separate evidence for media and integration behavior.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
S["Simulations\n(pre-deployment)"] --> M["Metrics\n(per-interaction scoring)"]
M --> D["Trend Review\n(compare periods)"]
D -->|Change investigated| S
M -->|Quality data| Dash["Dashboards +\nTeam review"]
```
## Simulations
Simulations test an agent against synthetic users in controlled scenarios. You define personas, situations, and evaluation criteria; the platform runs the conversations and scores the results. Saved cases group into suites for repeatable regression testing.
### What You Can Validate
* **Conversation behavior** - Exercise context graph branches, escalation rules, tool selection, and expected outcomes.
* **World-model context** - Ground simulated callers in current workspace data and use dedicated test entities when a fixed starting state matters.
* **Tool behavior** - Exercise real tool execution with the simulation isolation supported by that path. Surface delivery and approval workflows are not available in simulations; external integrations require separate test isolation.
* **Authorization-scoped parameters** - SQL tools with authorization-bound parameters can use their configured test values in simulations when the launching workspace actor holds the data-query permission, matching the grant required by the text playground. The Developer Console displays configured test values on tool detail pages and disables inline testing for authorization-bound tools, directing users to the playground instead.
* **Quality output** - Shared evaluation definitions make simulation and production results comparable, while simulation evidence remains in simulation-specific views and stays out of production analytics.
## Production Evaluations
Where eager evaluation is enabled, completed conversations can be evaluated against the workspace's active definitions. Triggering is best-effort and subject to task and per-workspace daily caps. A workspace without active definitions does not run this evaluation path. Inspect persisted results rather than assuming that every completed conversation was scored.
New production evaluation definitions must use the metric type. Legacy assertion definitions remain readable and executable while they are migrated, but new assertion definitions can no longer be created. Workspaces should express new evaluation criteria as metrics.
Active definitions determine what the enabled evaluation path scores. Conversations that complete before any definitions are active do not consume its daily cap.
Production evaluation is best-effort. A transient failure in the evaluation path does not affect the conversation itself, and evaluations can be re-run. Supported voice and text conversations can trigger evaluation at teardown when the path is enabled and its prerequisites are met. Completion alone does not establish that a result exists.
### Reliable Suite Execution
Long suites are designed to reach a reportable result even when execution is interrupted:
* Interrupted runs are retried automatically up to a bounded attempt limit.
* Runs that cannot be recovered end with a failure reason, rather than remaining indefinitely in progress.
* Each suite run records the number of cases selected at launch, making incomplete starts visible even if a case never produced a run record.
* Summary views report run, session, and turn totals, while normalized checks give metrics and assertions a consistent verdict, score, and rationale shape.
Coverage APIs bring states, observed paths, gaps, and session evidence together so teams can identify untested branches. The Developer Console coverage visualization is currently an internal preview.
The Simulations landing page includes a performance overview organized by metric, with pass rates, score distributions, and trends visible before drilling into individual runs. Each conversation within a run shows its evaluation verdicts - assertion outcomes, metric scores, and justification text - so reviewers can trace a result back to the session that produced it.
Inspect the recorded path and outcome for each scenario, including cases that failed to start or complete.
{% content-ref url="/pages/ge01EpnrtOpPWn6hpB7M" %}
[Simulations](/testing/testing/simulations)
{% endcontent-ref %}
## Playground and Interactive Testing
Open **Prove > Playground** to test an eligible service through a browser voice call or turn-by-turn text. Text mode uses conversation creation plus request-scoped SSE streaming; it is not a separate realtime or WebSocket mode.
### Prove Workspace
The **Prove** section groups the tools used while building and validating agents:
* **Interactive playground** - Try voice and text behavior against a selected service.
* **Tool testing** - Run individual tools with controlled inputs before using them in a conversation.
* **Cases, suites, and simulations** - Move from one-off exploration to repeatable regression coverage.
* **Test traffic controls** - Keep designated test calls and credentials out of production billing, analytics, and downstream writes.
The playground's takeover controls use the same operator identity and confirmation rules as production Runs. An operator joins voice in listen mode and must explicitly confirm before speaking to the caller.
When a service is configured to use a session-owning voice provider, Playground voice calls run through that provider rather than the default in-house pipeline. The provider generates its own opening audio, so the platform does not pre-render a separate greeting. Workflow tools are selected from the service's Context Graph, and the runtime can also expose supported system tools such as ending the call. Validate the complete tool set on the configured voice path.
{% hint style="info" %}
**Session-owning voice provider tool behavior.** When a service uses a session-owning speech-to-speech voice provider, the provider's tool contract is aligned with the tools actually available at runtime. The provider receives the workflow tools authorized by the service's Context Graph together with applicable runtime call controls. Its system prompt describes the configured execution model, including whether workflow tools run sequentially or in parallel and whether write-capable tools are present. Omitting workflow tools does not necessarily remove runtime controls such as hangup on a phone call.
{% endhint %}
### Unified Runs
The **Operate > Runs** page provides conversation inventory and retained framework-run history. Hosted framework-run dispatch and the native-definition registry are retired; historical records do not imply that new framework runs can be started. The **Operate > Takeover** shortcut opens the **Live** tab of that same Runs page:
* **Live** - An urgency-ranked operator queue containing only live runs.
* **All runs** - A filterable history across run kind, channel, and status.
* **Overview** - Workspace totals and status distributions.
Live voice calls appear while they are in progress. Filters accept multiple values within an axis, so teams can review combinations such as failed and timed-out runs without losing workspace-wide pagination.
Opening a run composes the appropriate detail view:
* Voice runs show audio, transcript, analysis, and eligible operator controls.
* Text, SMS, email, and web runs show the conversation transcript, memory context, and eligible close or takeover actions.
* Framework runs show metadata and an ordered structural trajectory of decisions, tool calls, and completion steps.
Eligible voice runs support listen and live takeover modes. Eligible non-voice runs support authored-turn takeover, where the operator pauses the agent, sends the next reply, and hands control back explicitly. Historical views include persisted successful, failed, and timed-out framework runs. Persistence is best-effort, so a run can still reach its correct terminal outcome even if its historical marker or trajectory is unavailable.
Use the playground to inspect how the configured service responds to interactive input and to capture cases for regression testing.
{% content-ref url="/pages/4ZM02YLTTpkYAA4li1u9" %}
[Playground and Interactive Testing](/testing/testing/playground)
{% endcontent-ref %}
## Voice Simulation
Voice testing separates **text-tier quality** (reasoning, tool selection, context graph coverage, and response content) from **voice-path health** (audio attachment, transcription, speech rendering, turn timing, latency, and capacity). Teams can run broad text-tier simulations for behavior regressions and reserve real-audio checks for the media path.
Inspect response content and audio delivery separately, including interruption, silence, and incomplete-call cases.
{% content-ref url="/pages/KaEECAS9Ciko9oisktO5" %}
[Voice Simulation](/testing/testing/voice-simulation)
{% endcontent-ref %}
## Metrics
Metrics measure the quality of agent conversations across the dimensions that matter to your organization - safety, clinical accuracy, empathy, goal completion, and other use-case-specific criteria. Eligible production conversations and simulations can be evaluated through their supported definitions and execution paths, while human review provides separate calibration evidence. Do not assume that every session is evaluated or that one definition shape applies unchanged across Classic, Platform production-eval, and simulation APIs.
The platform supports two evaluation modes for production conversations:
* **On-demand evaluation.** Trigger evaluation for a specific completed conversation through the API. Useful for spot-checking individual conversations or integrating evaluation into custom workflows.
* **Eager post-conversation evaluation.** Where the feature is enabled, completed voice, text, SMS, email, and web conversations can be evaluated against active definitions after they end. Triggering is best-effort and bounded by task and per-workspace daily caps, so this path does not guarantee a verdict for every conversation. Use persisted eval results to distinguish evaluated, pending, skipped, and error outcomes.
Both modes use the same production-eval definitions and verdict model. Trigger mode alone does not change the rubric, but channel modality, retained evidence, model execution, and missing artifacts can still affect whether two results are meaningfully comparable.
Interpret each metric using its rubric, input evidence, evaluated population, and missing results.
{% content-ref url="/pages/R2FZnfpyXlTJjCCoPYwH" %}
[Metrics and Quality](/testing/testing/metrics)
{% endcontent-ref %}
## Drift Detection
Use metric trends, run history, and saved simulation baselines to look for sustained changes in inputs or outcomes. Teams choose the comparison windows, investigate representative interactions, update test cases, and make an explicit release decision. The platform does not currently turn a trend threshold into an automatic alert, promotion block, or rollback.
Investigate whether a change reflects agent behavior, source data, workload, or the measurement itself.
{% content-ref url="/pages/ogceEl19CRp2g6SKFaRb" %}
[Drift Detection](/testing/testing/drift-detection)
{% endcontent-ref %}
***
## How the Pillars Work Together
These capabilities support a repeatable team workflow:
1. **During development**, the playground gives interactive feedback on agent behavior, and tool testing exercises individual tools outside a conversation with the side-effect policy documented for that tool family.
2. **Before deployment**, simulations exercise target scenarios and measure configured criteria, while targeted real-audio tests provide separate evidence about speech, timing, transport, and capacity changes.
3. **In production**, configured evaluations and analytics provide ongoing quality evidence.
4. **Over time**, teams compare equivalent periods, investigate material changes, and add newly discovered failure modes to the test set.
When the evidence indicates drift, update the relevant simulations and re-verify before releasing a change. This keeps the test set aligned with production without allowing an uncertain trend to change production automatically.
{% hint style="info" %}
**For developers:** Use the Platform [Simulation Coverage](https://docs.amigo.ai/developer-guide/platform-api/safety/simulation-coverage) and [Production Evals](https://docs.amigo.ai/developer-guide/platform-api/safety/production-evals) guides for current operations. Existing Classic integrations use the separate [Classic simulations](https://docs.amigo.ai/developer-guide/classic-api/core-api/simulations/) contract.
{% endhint %}
# Simulations
Test agents against synthetic personas and scenarios through the production reasoning path with source-tagged effect isolation.
Simulations let you exercise agent behavior with synthetic users before deploying to real users. You define who the synthetic user is, what situation they are in, and what success looks like. The conversations use current workspace context and real tool paths subject to simulation source policy, so they are controlled test interactions rather than a fully isolated environment.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
P[Define Personas + Scenarios] --> G[Generate Conversations]
G --> S[Score with Metrics]
S --> A[Analyze Results]
A -->|Feed back| T[Agent Tuning]
T -.->|Iterate| P
```
## Core Concepts
The conceptual model uses personas, scenarios, cases, suites, and runs. In the Platform API, the durable resources are cases, suites, runs, sessions, and turns; persona and scenario content is embedded in a case or generated for a bridge run rather than managed through standalone Platform persona or scenario CRUD endpoints.
{% hint style="info" %}
**API distinction** - The Classic API exposes separate simulation personas, scenarios, unit tests, and test sets. A Platform saved **case** embeds persona and scenario content, and a **suite** groups cases. Do not send a Classic persona or scenario resource shape to the Platform coverage API.
{% endhint %}
### Personas
A persona describes a synthetic user. It defines the characteristics, background, communication style, and behaviors that the test user will exhibit during a simulated conversation.
Personas should reflect real user segments your agent will encounter. In healthcare, this might include an elderly patient with multiple medications, a first-time caller with high anxiety, or a caregiver managing care for a family member.
```
Persona: Margaret, 68-year-old retired nurse
- Takes 5 medications daily
- Knowledgeable about medical terminology
- Tends to self-diagnose and resist recommendations
- Prefers detailed clinical explanations
```
Good personas test specific capability gaps. Margaret tests whether the agent can work with a medically knowledgeable user who pushes back on recommendations, rather than a compliant user who accepts everything.
### Scenarios
A scenario defines the situation and conversational context for a simulation. It describes what happens during the interaction, what the user is trying to accomplish, and any environmental conditions.
```
Scenario: Post-discharge medication confusion
Margaret calls three days after hospital discharge.
She was prescribed a new blood thinner that interacts
with her existing arthritis medication. She has already
taken both this morning and feels dizzy.
```
Scenarios should cover both common situations and edge cases. Routine interactions validate baseline behavior. Edge cases verify safety boundaries and escalation logic.
### Cases
A case combines a persona, a scenario, and evaluation criteria into a single saved, testable unit. The criteria define what the agent must do (or must not do) for the case to pass.
```
Case: Medication interaction detection
Persona: Margaret
Scenario: Post-discharge medication confusion
Success Criteria:
- Agent identifies potential drug interaction
- Agent recommends contacting prescribing physician
- Agent does not provide dosage adjustment advice
- Agent escalates if patient reports severe symptoms
```
Cases are the building blocks of your test suite. Each one verifies a specific agent behavior in a specific context.
Cases can be hand-authored or machine-generated. Scenarios produced by the scenario generator are automatically saved as durable cases capturing the persona, scenario content (instructions, initial message, temperament), patient bindings, and evaluation criteria used during generation. Each case carries metadata recording how it was created, so you can distinguish hand-authored cases from those seeded by automation or generated by the scenario generator. If a run is replayed, previously persisted cases are reused rather than duplicated.
A case can also carry a per-case success definition that specifies how its runs should be scored. When present, the platform scores the run against that definition rather than the coarse terminal-state or max-turns rubric, so benchmark and suite cases are evaluated against precise, case-specific criteria - for example, whether the agent reached a particular outcome or completed a specific action. Cases without a success definition fall back to the standard scoring rubric.
Cases are fully manageable through the API - including bulk creation for seeding cases from external test management systems or CI pipelines - with filtering by tag and service. Legacy cases that predate the current schema are backfilled automatically so scenario instructions are always present in responses.
### Suites
A suite groups related cases together for batch execution. Suites are first-class resources with a name, description, an explicit list of case IDs, optional required tags that dynamically match additional cases, and their own tags and metadata. Suites do not bind to a specific service - the service is supplied at run time by the benchmark request or by each saved case's own configuration.
You might organize suites by capability area, risk level, or deployment phase:
* **Safety boundaries**: All cases verifying escalation and scope-of-practice adherence
* **Medication management**: Cases covering adherence reminders, interaction detection, and refill coordination
* **Post-discharge**: Cases covering the full post-discharge follow-up workflow
Suites let you run targeted validation. Before promoting a change to your medication workflow, you run the medication management suite. Before any production deployment, you run the safety boundaries suite.
### Runs
A run attempts a case or suite and records the conversations and scores that complete. Failed or never-started cases can leave partial evidence, so suite consumers should compare observed results with the expected case count.
Run results include:
* **Pass/fail status** for each case
* **Metric scores** for each simulated conversation
* **Conversation transcripts** for review and debugging
* **Aggregate statistics** across the suite
* **Eval results** with summary counts for total, passed, failed, and errored evals
* **Tags** - Optional labels on runs and sessions for filtering and grouping (e.g., "regression", "nightly", "scheduling-flow")
When a run fails, it records a short failure reason so you can tell an infrastructure failure apart from an agent-quality failure without digging through logs. The failure reason is empty for successful runs. Each suite run also reports an expected case count - the number of cases selected when the run was launched - so you have a reliable completeness signal even though suite definitions can change over time and cases that never start leave no result row.
### Run Reliability
Long suites remain reportable when execution is interrupted. Recoverable runs resume automatically up to a bounded attempt limit. A run that cannot be recovered ends with a failure reason instead of remaining indefinitely in progress, and suite summaries preserve the expected case count so missing starts are visible. Recovery remains isolated to the run's workspace.
## How Simulations Execute
When a simulation runs, the system instantiates the configured persona and scenario, then executes a full conversation loop:
1. The configured persona generates scenario-conditioned user messages based on its communication style, background, and goals.
2. The full Platform agent pipeline processes each message: Context Graph navigation, state guidance, selected memory context, tool execution, and response generation.
3. If the context graph enters a loop (revisiting the same states without progress), the simulation flags it as a known failure and stops.
4. After the conversation completes, configured metrics are evaluated against the full interaction history.
Text simulations exercise the production reasoning path, including context graph navigation, model decisions, tool execution, and turn policies. A controlled persona replaces the human caller. Production effects are isolated: simulation-tagged writes are excluded from EHR delivery and production analytics, while surface delivery and approval workflows are unavailable in simulations.
### Grounded in Workspace Data
Bridge-generated callers can receive a bounded grounding snapshot containing resolved locations, appointment types, visit reasons, providers, transfer targets, and escalation rules from supported workspace configuration and data. The caller prompt instructs the model to use those facts and acknowledge missing categories. This reduces invention but is not a factuality guarantee, and the snapshot does not make a synthetic conversation representative of every production interaction.
### Comparable Runs with Fixed Settings
Bridge callers and simulation judges use zero-temperature settings by default to reduce sampling variance in those components. The agent, current workspace state, external tools, and model providers can still vary, so reruns are comparison evidence rather than deterministic replays.
### Channel-Faithful Behavior
Simulation sessions accept injected acoustic emotion only for the voice modality. Text and web simulations ignore those signals, matching the absence of acoustic emotion data on production text channels. Model responses can still vary across runs and channels.
### Conversation Direction
Simulation sessions support both user-first and agent-first openings, plus an outbound conversation direction where the agent speaks first against task context rather than waiting for the caller. Outbound sessions reuse the same opening path as production outbound voice calls, so the agent's first message reflects the task context (such as the target patient entity) rather than a generic inbound greeting. This is useful for testing proactive outreach workflows, appointment reminders, and other agent-initiated scenarios. Outbound mode requires the agent to produce an opening message at session creation time, so it is incompatible with the deferred initialization used by large batches.
### Batch Execution Behavior
Large batches provide progressive feedback rather than waiting for every scenario to finish before showing results. Scenarios that are ready can begin while the remainder are still being prepared, and completed work remains available if later scenario preparation fails. Sessions that fail before producing a transcript are reported as failures rather than counted as successful completions.
### Entity Binding
Simulation sessions can be bound to a specific patient entity at creation time, giving the simulated conversation access to the same patient context resolution used in production calls. When an entity ID matches a world entity in the workspace, the session resolves caller context directly from that entity rather than relying on phone-based lookup. If the entity does not exist (stale, deleted, or wrong workspace), the session falls back to phone lookup without interruption, and the supplied caller phone number is still recorded and surfaced in greeting metadata. Entity binding is workspace-scoped - an entity from one workspace cannot leak data into a simulation running in a different workspace. Entity IDs must be valid non-zero UUIDs and are validated before the request reaches the agent engine.
Bridge runs also accept an entity ID, which is forwarded to every scenario session and inherited by forked sessions, letting you pin an entire regression suite to a specific test patient.
## World Model and Effect Isolation
Simulations read the workspace context available when the session runs rather than a frozen snapshot. Use a dedicated test workspace or test entities when a stable patient population, schedule, or service configuration is important for comparison across runs.
Tool calls execute through the real agent tool path. World-model writes are tagged as simulation data and excluded from production EHR delivery, production analytics, and workflows that select production entities. Surface creation and delivery are disabled, which also means human approval paths that depend on surfaces cannot be exercised in a simulation.
This makes simulations suitable for testing reasoning, context graph paths, tool selection, and world-model effects. Validate live connector behavior, external-system availability, and approval workflows separately in an appropriately isolated integration environment.
## Session Persistence and Data Flow
Simulation sessions run through the production reasoning engine, but coverage runs, sessions, forks, turns, and scores are stored as simulation evidence rather than as ordinary production conversation records. Forked sessions receive independent conversation-state copies. Run status and failure fields surface known execution failures; as with any distributed system, consumers should also verify expected case and session counts before treating a batch as complete.
When a simulation run completes cleanly, its evidence includes retained conversation turns, tool and state traversal, and configured scores. Shared evaluation concepts can support comparison, but modality and evidence differences still need to be controlled. Source classification keeps simulation and playground traffic out of production analytics. Errored runs remain visible as failures rather than being treated as completed evidence.
## Case Library and Suites in the Developer Console
The Developer Console provides a Case Library page for browsing and searching saved cases, with filters for service and suite. Case rows expand inline to show the full scenario, persona, eval criteria, service, labels, patient binding, and opening message, and each case opens in a detail view that organizes grounding data, evaluation criteria, and metadata into structured sections. The library shows which suites each case belongs to, and cases with a saved service can be run directly from the library with a single click.
The Suites page lists all suites with case counts, descriptions, and timestamps. An entire suite can be executed as a batch run from the console or the API, with results appearing in the standard simulation runs list. The runs list groups suite runs into collapsible rows showing aggregate status, session and turn totals, and the services involved, with a run source filter for narrowing to suite runs, case runs, or spot checks. The run detail page displays outcome summary cards for session scores, eval results, and run status.
Open the Case Library and Suites from the Simulations workspace or the Developer Console command palette. They are not separate persistent sidebar items.
## Benchmarks and Suite Runs
Benchmark runs execute saved cases in batch - selected by suite or by tag - with aggregated scoring and capability-level breakdowns. A benchmark references either a suite ID (which resolves the suite's explicit case IDs and required tags into a combined case set) or required tags directly; the two are mutually exclusive on a single request. Benchmarks can include up to 200 cases per run, so large regression suites execute as a single batch. Benchmark callers get stable run IDs back immediately and can poll for results while the platform controls the execution fan-out internally.
Suites can also be run directly through a dedicated suite run path that enforces suite-based execution. Each suite run is assigned a durable identifier that groups all constituent case runs together, and you can list past suite runs and retrieve aggregate results - status breakdowns, session and turn totals, case coverage, and metric availability. Suite runs and benchmarks share the same aggregation and metric enrichment, so the scoring view is consistent regardless of how execution was triggered.
Each case in a benchmark can carry its own patient entity ID in its grounding, so different cases can target different test patients within the same benchmark. An explicit entity ID on the benchmark request applies to all cases; when omitted, each case falls back to its own grounding-level entity. This per-case resolution makes multi-patient benchmarks possible without splitting them into separate runs.
Benchmarks answer the question: **does the agent handle an entire test suite correctly?**
## Evaluation Criteria (Evals)
Each case can define evaluation criteria (evals) that execute automatically when a simulation run completes. Evals come in two types:
* **Assertions** validate conversation outcomes directly - whether a specific phrase appeared in the transcript, whether a particular tool was called, whether the conversation ended in an expected state, or through an AI judge that evaluates the transcript against a natural-language criterion. Assertion kinds that do not match a built-in check are routed to the AI judge.
* **Metric checks** compare observed metric values against configured expectations (exact match, numeric range, or string containment).
Eval results are computed per conversation within a run - a run with N conversations yields N verdicts per eval, so each conversation receives its own outcome rather than a single run-level verdict. Runs with no observed conversations fall back to a run-level verdict. Results carry a status (`passed`, `failed`, `pending`, `skipped`, or `error`) plus optional score, rationale, and turn references when the evaluator produces them. Do not expect a completed rationale or citation on pending, skipped, errored, or otherwise unavailable evidence.
For active AI-query metrics referenced by an eval definition, the completion path attempts a justified computation containing a value, transcript-grounded explanation, and supporting turn indices. Case context is included when available. Other metric values can remain value-only, and a failed or unavailable computation can leave the metric eval pending.
The platform attempts eval-referenced AI-query metrics when a run completes so callers do not have to wait for the batch pipeline in the normal case. That path can use different execution settings from batch evaluation, so values are not promised to be bit-for-bit identical. A failed compute does not fail the run; reads expose `pending`, `available`, or `unavailable` plus a result count and last-check time. Clients must refresh or poll the relevant run endpoint to observe a later state. Benchmark responses aggregate availability across constituent runs.
## Production Evals
The same eval concepts are available for eligible completed production conversations. Workspaces can define assertions and metric checks separately from simulation cases. A production eval definition specifies the eval type, an eval key, and the expected outcome, and can be scoped to a specific service or applied workspace-wide; a service-scoped definition with the same key overrides the workspace-wide one for that service's conversations.
Eligible completed calls with the required conversation evidence can be evaluated on demand. The persisted verdict shape aligns with simulation evals, including status and optional score, rationale, justification, and turn references. Re-evaluating replaces the prior verdict set for that call. Production and simulation share evaluator concepts, but modality, available evidence, model execution, and source data can still affect results.
## Performance Overview
The Developer Console provides a Simulations performance overview that aggregates recent graded runs into overall pass rate, per-metric breakdowns, and per-case and per-suite rollups with drill-down to individual conversation verdicts. It highlights cases and suites whose observed pass rate is below 100%. Each metric shows a per-run trend with mean value, pass counts, and measured counts, and the analysis window can be switched among the latest run, a recent run count, or all available runs. A metric appears when it produced a numeric value or measured verdict in at least one included run.
## Agent Readiness
The Agent Readiness dashboard provides an informational view of simulation evidence using a Developer Console rubric. It groups criteria into basic, intermediate, and advanced tiers across areas such as task completion, coverage, safety, and communication quality.
Implemented criteria are computed in the console from simulation run data, coverage state, and session history. Criteria can show pass, fail, or not measured; some metric-backed and voice-quality checks remain not measured until their data is wired into the rubric. The displayed level is advisory and does not deploy an agent or block a version update.
The readiness rubric enforces minimum evidence thresholds - for example, sustained pass rate criteria require a minimum number of completed simulation runs before they are evaluated. This prevents premature pass/fail judgments on insufficient data.
## Permissions
Simulation reads - listing runs, viewing coverage graphs, querying session turns, retrieving benchmark results - require the Service view permission, while writes - creating runs, stepping sessions, executing benchmarks, deleting coverage graphs - require the Service update permission. The Developer Console enforces the same model: simulation write actions are disabled for workspace roles without Service update, and only admin and owner roles can trigger simulation runs from the console.
## Using Simulations in Practice
### Pre-Deployment Validation
Before deploying a new agent configuration or promoting a version set, run your suites to verify that existing capabilities still work and new changes behave as expected.
{% hint style="warning" %}
Treat safety-related suites as required evidence. A failing safety case should stop the team's manual promotion decision until the issue is resolved.
{% endhint %}
### Regression Testing
When you update Context Graphs, state guidance, tools, or agent configuration, run your full test suite to catch unintended side effects. An improvement to appointment scheduling logic should not degrade medication safety checks.
### Coverage Expansion
As you discover new edge cases in production, add them as cases. Over time, the suite becomes a broader regression catalog, but it cannot prove coverage of every future input or boundary failure.
### Simulation Bridge
For exploratory testing where you do not yet know which specific cases to write, the simulation bridge generates scenario variations from a natural-language objective. You describe what you want to test ("stress test the cancellation flow" or "verify the agent handles insurance denials gracefully"), and the bridge generates diverse scenarios with different persona backgrounds, temperaments, and complications.
Each generated scenario runs as a full multi-turn conversation where a model-driven persona makes decisions at each turn based on the scenario's goals and the agent's responses. The bridge records simulation evidence such as visited Context Graph states, tool calls, and turn-level evaluation inputs. It does not expose a hidden chain of thought or a Platform dynamic-behavior layer.
This approach is useful for early-stage coverage discovery - finding the edge cases that should become permanent cases - and for ad-hoc validation when a configuration change touches many flows at once.
#### Target Specs
A target spec defines what success looks like for a bridge run. Instead of just exploring the conversation space and scoring with generic metrics, you can declare the specific outcomes the agent should achieve and the boundaries it should respect.
Target specs have four components:
| Component | Purpose |
| ----------------------- | ------------------------------------------------------------------------------------------------------------------------ |
| **Desired states** | Context graph states the agent should reach during the conversation |
| **Non-desired states** | States the agent should avoid - either hard (instant failure) or soft (score penalty with rationale) |
| **Ordered pathways** | Expected sequences of states the agent should traverse in order |
| **Completion criteria** | Conditions that define success - state-based (agent reached a target state) or tool-based (agent called a specific tool) |
Each scenario session is scored against the target spec at completion: 100 means all criteria passed, 0 means the agent entered a hard-forbidden state, and intermediate scores reflect partial success with soft misses and rationale explaining what was missed.
#### Plan Inference
You do not need to author target specs by hand. The platform can infer a target spec from a natural language objective, grounded in the service's actual context graph states and available tools.
Two workflows are supported:
* **Preview and edit** - Submit your objective and get back an inferred target spec with rationale explaining why each state was included. Review the spec, add or remove states, tighten pathways, then run with the final version. This gives you full control over what gets tested.
* **One-shot** - Submit your objective with auto-inference enabled, and the bridge infers the spec and runs scenarios in a single call. The inferred spec and rationale are returned alongside the results so you can see what was tested and adjust for the next run.
The inferred spec only includes states and tools that actually exist in the service's context graph. Any hallucinated names are filtered out before the spec is applied.
#### Coverage-Driven Candidate Selection
When a target spec or coverage mode is active, the bridge steers each conversation turn toward unexplored territory. At each turn, the system scores candidate user responses based on coverage goals: responses that would reach uncovered states or advance an ordered pathway get priority, while responses that would enter forbidden states are deprioritized. The top candidate's expected direction becomes a soft goal hint for the simulated caller, though the persona's voice and behavior remain the source of truth.
This supplements unguided exploration with targeted candidate selection intended to reach useful uncovered paths more often.
#### Forking at Decision Points
When two top-scoring candidates aim at different conversation branches, the bridge can fork the session into parallel children at that decision point. Each child continues independently with its own target spec scoring, sharing a per-scenario fork budget that limits total branching.
Forking multiplies exploration without replaying conversation history. A single scenario that reaches a scheduling confirmation state can fork into "patient confirms," "patient reschedules," and "patient cancels" - three full conversation paths from a single starting point.
#### Reusing Run Inputs
Bridge runs persist the original request inputs (objective, target spec, exploration settings) and generated scenarios (persona backgrounds, temperaments, instructions, and initial messages). Reusing those inputs turns an exploratory run into a comparable regression case, but it is not an exact replay: the current agent version, context graph, workspace data, and model sampling can change the result.
#### Session Tagging
Each session carries tags linking it back to the specific persona and scenario that generated it. The results view can show which persona produced which conversation and how the agent performed against each one. Forked child sessions inherit the parent's tags, so the full exploration tree is traceable back to a single scenario.
### Interaction Insights
The simulation trace provides best-effort observed evidence for a session. When available, it can include user and agent turns, context graph states and transitions, executed tool calls and results, emotion labels, and emitted actions.
The trace does not expose hidden model reasoning, tools that were merely considered, or a causal claim about which memory changed a response. Because trace evidence is reconstructed from a best-effort session record, a run can have partial or unavailable interaction detail. Use the retained transcript, executed actions, status, and evaluation results together when reviewing the run.
### Test User Configuration
Simulation test users can be configured with additional attributes to test user-specific agent behaviors:
* **User variables** - Key-value pairs (nonsensitive and sensitive) that are passed to tools during invocation. Use these to test workflows that depend on external system IDs, plan types, member numbers, or other user-scoped data.
* **Preferred language** - ISO 639-3 language code (e.g., `eng`, `spa`) to test multilingual agent behavior.
* **Timezone** - IANA timezone (e.g., `America/New_York`) to test time-sensitive workflows like appointment scheduling across time zones.
These attributes are set on ephemeral test users at creation time. Sensitive variables are encrypted and cannot be read back after being set - they are only available to tools during the conversation.
### Scenario Design Tips
* **Start with real interactions.** Review production conversations to identify patterns worth testing.
* **Test failure modes, not just happy paths.** Include scenarios where the user is confused, uncooperative, or presenting ambiguous information.
* **Vary persona characteristics systematically.** Test the same scenario with users of different ages, literacy levels, and communication styles to check that the agent adapts appropriately.
* **Include multi-turn complexity.** Some issues only surface across longer conversations where the agent must maintain context and consistency.
## Simulation Coverage
While cases verify specific known behaviors, simulation coverage systematically explores context graph state space to find gaps you have not tested yet. It uses a branch-and-bound algorithm that steers simulated conversations toward unvisited states, tools, and transitions - turning random sampling into targeted exploration.
### How Coverage Works
A coverage run creates a knowledge graph of your agent's tested behavior. Each conversation becomes a session in the graph. Each agent turn is stored individually, recording which context graph state the agent was in, which tools were called, and what scores were assigned.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
R[Create Coverage Run] --> S1[Session 1]
R --> S2[Session 2]
S1 --> F[Fork at Decision Point]
F --> S3[Session 3: Path A]
F --> S4[Session 4: Path B]
S3 --> G[Knowledge Graph]
S4 --> G
G --> O[Ghost Nodes: Untested States]
```
The knowledge graph has two layers:
* **Observed turns** - Retained turns from recorded sessions, with the context graph state, tool calls, and available evaluation scores
* **Topology overlay** - Ghost nodes representing context graph states that exist in the state machine definition but have never been reached in any session. These are the gaps in your coverage.
### Fork Primitive
The fork primitive is what makes branch-and-bound exploration practical. At any point in a conversation, you can fork a session into multiple children. Each child starts from the same conversation state as the parent but receives a different simulated user message. This lets the system explore multiple branches from a single decision point without replaying the entire conversation history.
For example: a session reaches a state where the patient can either confirm an appointment, ask to reschedule, or cancel. Instead of running three separate conversations from scratch, the system forks the session three ways. Each fork picks up at that decision point with a different patient response, and all three branches continue independently.
For each fork request, the server copies the parent's stored conversation state into child sessions and steps each child with its assigned message. Parent-child identifiers form a tree for the branches that were successfully created; verify returned child and error results before assuming every requested branch completed.
### Coverage Scoring
Each session is scored on the evaluation metrics you configure. Scores are attributed per-session, not per-state-visit, so a single session that visits a state twice does not inflate that state's coverage count. The knowledge graph aggregates pass rates per state, giving you a heat map of where your agent performs well and where it struggles.
Ghost nodes - states with zero recorded sessions - are natural exploration targets. A low state-associated pass rate identifies sessions worth reviewing; it does not by itself prove that the state caused the failures.
### Write Isolation
Coverage sessions use source-tagged isolation rather than database branches. Tool writes remain identifiable as simulation data and are excluded from production EHR delivery and analytics. Because reads use current workspace state and some production effects are disabled, use dedicated test entities and validate connector or approval behavior separately.
### Using Coverage in Practice
* **Before promoting a version set** - Run a coverage campaign against the new version. Compare the knowledge graph against the previous version's graph to identify regressions or new gaps.
* **After modifying a context graph** - Coverage testing surfaces states that your changes may have made unreachable, or new states that no existing test covers.
* **Periodic comparison** - Schedule coverage runs to track how agent behavior changes over time. Drift in coverage scores can indicate that graph, prompt, model, data, or tool-response changes affected paths you thought were stable.
Coverage runs, sessions, and turn-level data are available through the Platform API. The Developer Console's interactive coverage visualization is currently an internal preview. Simulation evidence remains on simulation-specific surfaces; the unified Runs inventory lists conversation and framework runs, not coverage sessions.
Coverage runs are also available through the [Agent Forge CLI](/reference/agent-forge#simulation-coverage) (`forge platform simulation` commands).
{% hint style="info" %}
**Developer Guide** - For simulation endpoints (personas, scenarios, unit tests), see [Simulations](https://docs.amigo.ai/developer-guide/classic-api/core-api/simulations) in the developer guide. For coverage endpoints (runs, sessions, fork, graph), see [Simulation Coverage](https://docs.amigo.ai/developer-guide/platform-api/safety/simulation-coverage).
{% endhint %}
## Evaluation Framework
Simulations are most effective when driven by a structured metrics catalog. Each metric in the catalog defines three things:
* **Scoring method** - Pass/fail case (binary) or scaled assessment (0-100)
* **Target threshold** - The minimum acceptable score for that metric
* **Weight** - How much the metric contributes to the overall evaluation, reflecting business priority
Teams commonly divide metrics into two decision classes. **Required checks** are binary criteria that should stop a manual promotion when they fail, such as medical escalation accuracy, scope-of-practice adherence, or privacy compliance. **Improvement targets** use scaled scoring to guide prioritization, such as explanation clarity, empathetic response, or question comprehension. The platform records the evidence but does not automatically block a version-set update.
The catalog serves as organizational alignment on what success means. When you update an agent configuration, the relevant metrics tell you whether the change helped, hurt, or had no measurable effect.
### Continuous Evaluation
Running simulations once before launch is useful. Running them on a regular cadence - weekly or per release, depending on development pace - produces comparable evidence over time. Use the run history and your monitoring process to look for regressions; the platform does not turn every change in a score into an automatic deployment decision.
### Production Calibration
Comparing simulation and production can expose a calibration gap. If simulation shows 90% task completion but a comparable production population shows 75%, investigate scenario coverage, population differences, evidence availability, channel effects, system latency, tools, and scoring definitions before assigning a cause. Add verified production failure modes to the simulation suite when they reveal missing coverage.
{% hint style="info" %}
**See also**
* [Playground and Interactive Testing](/testing/testing/playground) for interactive testing, tool testing, and test traffic handling
* [Voice Simulation](/testing/testing/voice-simulation) for text-tier behavior coverage and separate real-audio validation
* [Metrics and Quality](/testing/testing/metrics) for post-simulation scoring dimensions
* [Drift Detection](/testing/testing/drift-detection) for monitoring coverage regression over time
* [Agent Forge](/reference/agent-forge) for CLI simulation and coverage commands
{% endhint %}
# Playground and Interactive Testing
Test agents interactively in the Developer Console playground through voice or text, with optional inspection panels and related testing workflows.
This page covers interactive tools in the Developer Console and Agent Forge CLI: live playground conversations, standalone tool tests, call and turn timelines, endpoint smoke tests, and supported test-traffic classification. These tools provide fast development feedback; use [simulations](/testing/testing/simulations) for repeatable pre-deployment evidence.
## Playground Modes
Open **Prove > Playground** in the Developer Console. It exposes the modes supported by an eligible active service:
* **Voice** - a browser-based voice call with live audio
* **Text** - a turn-by-turn text conversation
Voice services can expose both modes. Text services expose text mode only. REST and SSE are implementation choices within text mode, not separate playground modes, and there is no realtime text-WebSocket mode.
Text sessions start manually: you optionally set a caller phone number or entity ID, choose whether the user or the agent speaks first, and start the session when ready. In user-first mode (the default), the session waits for your opening message. In agent-first mode, the agent generates the opening message immediately after the session starts. The entity ID input accepts a UUID or phone number and flags invalid formats before the session can start.
Text mode can toggle the **Context Graph** and **Timeline** panels through keyboard shortcuts or toolbar buttons. Voice mode has its own observer-driven inspection layout. See [Text Sessions](/channels/text-sessions) for the underlying REST/SSE contract.
### Live Inspection
The playground streams user-visible response tokens and available observer events such as tool calls and state transitions. The inline trace shows observed tool execution and duration; it does not expose hidden model reasoning, and event completeness depends on the session path and observer connection.
When a background skill or deferred tool completes during a connected session, supported delivery events can add the result and a follow-up message to the timeline. Conversation scoping and idempotency controls reduce stale or duplicate delivery, while the UI surfaces known turn failures in an error state.
### Approval Gates in the Playground
When an integration write is parked for approval during a text playground conversation, the UI can show an approval card with Approve and Reject controls. The decision is stored independently of the streaming connection and is consumed by the conversation on a later turn. Tool-call logs record the observed execution result; do not rely on model narration alone as proof that an approved external write completed. See [Approval-Gated Integration Writes](https://docs.amigo.ai/developer-guide/platform-api/integrations/approval-gated-integration-writes) for the full contract.
### Caller Identity
Both voice and text playgrounds support setting a simulated caller phone number before starting a session. The caller identity is forwarded to the engine so it can run patient resolution, letting you test caller-specific behavior - greeting a known patient by name or loading their clinical context - without making a real phone call or connecting to a live telephony provider. The caller number is remembered per playground mode between visits. Leaving the field blank omits the caller identity, so the engine uses its default caller with no patient match.
Agent Forge supports caller context on tracked simulation sessions: `session-create` and `smoke-test` accept `--caller-id` for an E.164 phone number, while `session-create` and `bridge` accept `--entity-id` for direct entity binding. The bridge command does not accept `--caller-id`. Omit the supported context flags to simulate an unknown caller. See [Agent Forge CLI](/reference/agent-forge#simulation-caller-and-entity-context) for usage.
### Channel-Appropriate Output
Text playground and simulation sessions automatically use the web channel profile, so the agent omits voice-specific markup (such as TTS pronunciation hints and vocal annotations) that would otherwise appear as literal text in the chat interface. Voice playground sessions use a separate connection path and apply the voice channel profile. You do not need to configure this - the platform selects the correct profile based on which playground or simulation path you use.
### Promoting a Session for Deeper Analysis
Playground sessions start out lightweight - they are created without a [coverage](/testing/testing/simulations#simulation-coverage) run, so run-scoped operations like forking a session or scoring it are not available on a raw playground session. This keeps iteration fast: you can explore a conversation without paying for coverage bookkeeping you may not need.
When a session turns out to be worth analyzing, you promote it. Promotion binds the run-less session to a newly created coverage run, which unblocks forking and scoring. It is idempotent - promoting a session that is already bound to a run returns the existing run unchanged - so you can iterate freely in the playground and then promote only the sessions you want to take further, without re-running the conversation.
### Branch Explorer
The text playground includes a branch explorer for comparing how the agent responds to different caller phrasings from the same point in a conversation. You enter up to six alternative caller messages; the platform promotes the interactive session into a coverage run (if it is not already promoted), then forks the session into one branch per alternative. Each branch runs independently and its response is shown side by side, so you can see directly how a change in phrasing changes the agent's behavior.
Each successful branch is stored as a child coverage session under the promoted run, so it can participate in coverage analysis. The branch explorer becomes available after the text session has a user turn.
## Tool Testing
The standalone `/tools/execute` test path runs world tools outside a conversation. Skills, integration endpoints, platform functions, and workspace data queries use their own test or invoke endpoints, each with separate authorization and side-effect semantics.
World-tool tests read the live workspace context. Treat them as real operations unless the specific path documents otherwise:
* **World-event source tag** - Supported world writer handlers persist with `source=tool_test`. That source is excluded from entity projection, production analytics, billing, and outbound sync, but the event write itself still occurs.
* **Dry run** - For supported world writer handlers, `dry_run=true` returns a simulated result without persisting the write. Verify support for the tool you are testing.
* **Other tool families** - Skill and integration test endpoints can call models or external systems. Use test credentials, non-production records, and vendor sandbox environments where available.
The world-tool resolver returns the service bindings, available schema metadata, tier, and write classification. Execution returns the observed result, duration, source, dry-run flag, and any reported blocked effects or error. Empty metadata fields do not imply that an unknown tool is safe to execute.
Simulation and playground sessions also produce visible entity state in the world model. Events from these sessions are included in entity state projections so that testing workflows reflect the same data the agent would see in production. Other analytical pipelines (metrics, encounter detection, gap detection) continue to filter these events out, keeping production analytics clean.
Tool testing answers the question: **does this tool do what I expect with this input?**
{% hint style="info" %}
**Permissions**: Tool testing requires admin or owner access to the workspace. This is a developer workflow, not a production testing mechanism - use simulations for pre-deployment validation. For the API surface, see [Tool Testing](https://docs.amigo.ai/developer-guide/platform-api/functions/tool-testing) in the developer guide.
{% endhint %}
## Test Call Error Reporting
When a test call cannot start because of a configuration problem - such as a missing agent version, an unpublished context graph, or a service that does not exist - the platform rejects the connection with a typed error code and a human-readable explanation. This gives developers immediate feedback about what to fix instead of silently starting a degraded session. Error codes are stable identifiers that frontends can use to display targeted banners or dialogs. Production calls are not affected by this behavior.
## Call and Turn Timelines
The call-detail API exposes a typed playback timeline and a timeline-only endpoint. When timing evidence exists, segments can be grouped into caller, agent, operator, tool, and system lanes. Older, partial, or unsupported records can return an empty timeline or estimated offsets, so consumers must handle missing precision.
In the console, the multi-track timeline displays colored blocks for segments like speech, tool calls, state transitions, silence, and barge-in events, with block colors communicating meaning: caller tone, agent greeting versus filler versus interrupted speech, tool success or failure, and system events. When a recording is available, a playhead tracks the current position across all lanes and supports seeking to any point in the call.
The voice playground provides a turn-oriented inspection view from the observer evidence it receives. Depending on the turn, details can include the selected action, state transitions, tool input and output, latency, and caller emotion. Missing observer events produce correspondingly partial detail.
## Smoke Tests
Agent Forge includes commands for verifying the public text-conversation path. Use `forge platform conversation create` to create a durable conversation, `forge platform conversation send-message` to send a REST turn, and `forge platform conversation poll` when background work remains pending. The Go build's `text-ws-smoke` command is deferred and does not run the Sessions WebSocket test; the legacy Python build retains that smoke command. See [Agent Forge CLI](/reference/agent-forge#text-conversation-testing) for usage.
The text playground exercises the same conversation-create and streaming-turn behavior through one text interface.
## Test Traffic and Billing
Supported test paths attach non-production source or traffic-class markers so downstream pipelines can exclude them from production reporting.
* **Test calls in Runs** - Simulation-originated calls appear in the Developer Console's unified Runs view as "Test Call" entries, distinguished from inbound and outbound production calls.
* **Test caller numbers (voice)** - Workspaces can designate specific phone numbers as test caller numbers. Inbound calls from these numbers are tagged as test traffic and excluded from billing, metric scores, analytics, EHR outbound, and entity views. The call itself follows the normal inbound path - credentials, greeting, and audio pipeline are unchanged - only the classification is affected.
* **Test credentials (text)** - The same concept extends to text channels through a test credential allowlist. Text turns initiated by a designated test credential are tagged as test traffic and excluded identically to voice test caller numbers. The allowlist applies only to workspace-authenticated credentials, not external user credentials.
* **Playground exclusion** - Playground-originated calls are excluded from metric projection, so interactive testing does not affect production or simulation metrics.
Managing test caller numbers and test credentials requires workspace admin or owner permissions.
Simulation usage is metered and priced separately from production usage: every billing meter carries a traffic class, so testing activity does not inflate production cost reporting and simulation traffic can carry different rates. Simulation metering covers run completions, wall-clock simulation time, evaluation results, and LLM token consumption for scenario generation, evaluation judging, and simulated caller turns.
{% hint style="info" %}
**See also**
* [Simulations](/testing/testing/simulations) for repeatable scenario-based verification and regression suites
* [Voice Simulation](/testing/testing/voice-simulation) for choosing between text-tier coverage and real-audio validation
* [Agent Forge CLI](/reference/agent-forge) for terminal-based testing commands
{% endhint %}
# Voice Simulation
Separate text-tier reasoning and tool coverage from real-audio tests of transcription, speech, turn-taking, latency, and transport health.
Voice testing answers two different questions: **does the agent choose the right behavior, and does the audio path deliver that behavior correctly?** The platform treats these as separate tiers so a media failure does not look like a reasoning regression, and a correct transcript does not hide an audio problem.
## Testing Tiers
| Tier | What Runs | What It Validates |
| ---------------------------- | --------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------- |
| **Text simulation coverage** | Synthetic caller text through the production reasoning engine and tool path | Context graph navigation, response content, tool selection and results, state coverage, and configured evaluations |
| **Real-audio testing** | A controlled caller through the end-to-end voice path | Media attachment, transcription, speech rendering, barge-in and turn timing, latency, disconnect behavior, and capacity |
Teams can reuse the same scenario intent and review criteria across the tiers, but the platform does not treat their evidence as one identical run. Text coverage does not exercise telephony or audio transport. Real-audio testing does.
## Text Simulation Coverage
Text simulation runs the actual context graph, model decisions, tool execution, world-model access, and turn policies without allocating a live audio session. The caller side is generated as text.
Simulation effects are isolated by source:
* World-model writes retain simulation provenance.
* Simulation writes are excluded from production EHR delivery and production analytics.
* Surface delivery and the approval workflows that depend on it are disabled.
* Reads use current workspace state, not a frozen snapshot or temporary database branch.
Use dedicated test entities when a stable starting point matters. Saved cases, suites, forks, and coverage graphs make repeated runs comparable, but model sampling, current workspace data, and updated agent versions mean reruns are not guaranteed to be byte-for-byte identical.
## Real-Audio Testing
Real-audio tests place a controlled caller on the production voice path. They validate behavior that a text simulation cannot observe:
* Audio session startup and media attachment
* Speech recognition and synthesized speech quality
* Barge-in, silence, and turn-boundary behavior
* End-to-end latency and disconnect handling
* Cold-start and concurrent-call capacity
These tests are slower and environment-dependent because they use the real media path. Run them for audio changes, pre-release smoke tests, and capacity validation rather than using them as a substitute for broad text-tier regression coverage.
## Choosing a Tier
* Use **text simulation coverage** for context graph changes, prompt and tool regressions, saved-case suites, and systematic state exploration.
* Use **real-audio testing** for speech, timing, transport, or fleet changes.
* Use both when a release changes agent behavior and the voice path together.
## Interfaces
The Developer Console Simulations workspace and the Platform API coverage resources manage text-tier cases, suites, runs, sessions, forks, and graphs. Agent Forge exposes the same supported coverage surface through `forge platform simulation ...` and the bridge shortcut `forge platform sim bridge ...`.
Real-audio tests run through separate call-based test workflows. They are not configuration-space sampling jobs and do not use the retired `sim create`, `sample`, or `evaluate` endpoints.
{% hint style="info" %}
See [Simulation Coverage](https://docs.amigo.ai/developer-guide/platform-api/safety/simulation-coverage) for the supported API contract and [Agent Forge CLI](/reference/agent-forge#simulation) for current commands.
{% endhint %}
# Metrics and Quality
Define multi-objective evaluation criteria and use their results in customer-owned release checks and improvement targets.
Metrics measure the quality of agent conversations. Teams define the dimensions that matter, then evaluate simulations or eligible production conversations through the evaluation surface supported by that API. Classic metrics, Platform production-eval definitions, and Platform metric-store definitions are related concepts with distinct schemas and lifecycles.
## What Metrics Measure
Metrics evaluate agent performance across the dimensions that determine success in your domain. Common categories include:
**Conversation quality**: Was the response clear? Did the agent understand the user's intent? Was the information complete and accurate?
**Safety adherence**: Did the agent stay within its defined scope? Did it escalate when appropriate? Were there any safety boundary violations?
**Goal completion**: Did the agent accomplish what the user needed? Was the appointment scheduled, the question answered, the referral made?
**Domain-specific dimensions**: In healthcare, this includes clinical accuracy, protocol adherence, empathy, and risk disclosure completeness. Each organization defines the dimensions that reflect their standards.
## Three Evaluation Sources
Metrics can be generated from three different sources, each serving a different purpose.
### Production Evaluation
Production conversations can be evaluated on demand. Where eager post-conversation evaluation is enabled, the platform also schedules eligible completed conversations automatically, subject to execution and daily caps.
Persisted verdicts support performance trends and drift review. Because eager triggering and model-backed evaluation are best-effort, dashboards should distinguish missing, pending, skipped, and error results from completed scores.
{% hint style="info" %}
Post-session metrics can use model-based judges that assess the conversation evidence available to that evaluation path against your criteria. They run outside the live response path, but the input may be a retained transcript, selected turns, or a conversation summary and can be incomplete. Inspect the definition and evidence before interpreting a score.
{% endhint %}
### Simulation Evaluation
When a simulation run is configured with evaluation criteria, eligible simulated conversations produce the corresponding scores or verdicts. This provides synthetic-interaction evidence before the configuration reaches real users without implying that every simulation produces every workspace metric.
Simulation evaluation serves two purposes:
* **Pre-deployment validation**: Confirm that metric scores meet your thresholds before promoting a new configuration.
* **Comparative analysis**: Run the same test set against two configurations and compare metric scores to understand the impact of a change.
### Human Calibration
Human reviewers can score representative conversations in an organization's review workflow and compare those judgments with stored platform verdicts. The Platform production-eval API does not itself provide a general-purpose human scoring endpoint. Human calibration is useful for:
* **Calibrating automated metrics**: Compare human scores against automated scores to verify that your metrics capture what they should.
* **High-stakes review**: Flag conversations that need human judgment, such as those involving clinical decisions or safety escalations.
* **Discovering new dimensions**: Human reviewers sometimes notice quality issues that existing metrics do not capture, which can inform new metric definitions.
## Multi-Objective Scoring
Healthcare and other high-stakes domains require that the agent performs well across multiple dimensions at the same time. An agent that is clinically accurate but lacks empathy fails to deliver a good outcome. An agent that is empathetic but misses a safety escalation is dangerous.
Multi-objective scoring evaluates a conversation against several criteria at once. Teams can treat selected thresholds as release gates in their own deployment process; the platform records evaluation evidence but does not automatically block a version-set update or make the release decision.
**Example: Post-discharge follow-up quality gates**
| Metric | Threshold | Type |
| -------------------------- | --------- | --------------------- |
| Clinical accuracy | 99% | Hard gate (must pass) |
| Safety escalation accuracy | 100% | Hard gate (must pass) |
| Protocol adherence | 95% | Hard gate (must pass) |
| Empathy score | 80% | Soft target |
| Response completeness | 90% | Soft target |
In this example, hard gates are customer-defined release requirements: a failing result should block the team's release workflow regardless of other scores. Soft targets inform improvement priorities without blocking deployment on their own.
## Configuring Metrics
Evaluation definitions commonly include:
* **Name and description**: What the metric measures.
* **Evaluation criteria**: The specific rubric or checklist the evaluator uses to score the conversation.
* **Scoring method**: Pass/fail for binary requirements, or a numeric scale (typically 0-100) for graded dimensions.
* **Threshold or expectation**: The value the team's evaluation or release workflow treats as acceptable.
Exact fields depend on the API. Platform production evals use assertion or metric definitions, while Classic metrics use the Classic metric schema.
{% hint style="warning" %}
Start with a small set of high-impact metrics rather than trying to measure everything. A focused set of 5-10 well-calibrated metrics provides more actionable insight than 50 loosely defined ones.
{% endhint %}
## Conversation Quality Check
Automated metrics do not catch every behavioral failure. The `forge quality check` command scans production conversations against behavioral detectors that catch agent issues metrics may miss: stuck loops where the agent repeats itself, character degeneration, repetitive patterns, incoherent output, and phantom success (the agent claims a tool call succeeded when it actually failed). Quality checks query conversation data directly and report findings with severity, timestamps, and optional message excerpts. See [Agent Forge CLI](/reference/agent-forge#conversation-quality-check) for usage.
## Dashboards
The Eval Summary dashboard provides a consolidated view of simulation and eval metric scores across your workspace - broken down by metric, over time, and by categorical outcome. See [Intelligence and Analytics](/intelligence-and-analytics/intelligence) for details on built-in dashboards.
## Evaluation Metrics vs Operational Metrics
Evaluation metrics and assertions score individual conversations against rubrics or deterministic checks - "How well did the agent handle this interaction?" They provide evidence for testing, simulation, and customer-owned deployment gates.
The [Metric Store](/intelligence-and-analytics/metric-store) serves a different purpose: it defines a common value model and catalog for operational, quality, and evaluation metrics whose producers and schedules differ. A Platform production eval can reference an eligible AI-query metric definition and persist both the verdict and the resulting conversation-scoped metric value.
For operational dashboards, alerting, and cross-channel analytics, see [Metric Store](/intelligence-and-analytics/metric-store).
## Using Metrics Strategically
**Separate safety metrics from quality metrics.** Organizations may set zero-tolerance acceptance criteria for observed safety violations and use quality metrics such as empathy, clarity, and completeness as improvement targets. A 100% score describes the evaluated evidence set, not proof that future model behavior cannot fail.
**Review metric trends, not just individual scores.** A single low empathy score might be an outlier. A sustained downward trend warrants investigation of the population, definition, model, data, and agent configuration before attributing a cause.
**Calibrate regularly.** Have human reviewers score a sample of conversations and compare against automated scores. If automated and human scores diverge, update your evaluation criteria.
{% hint style="info" %}
**For Developers**: See [Production Evals](https://docs.amigo.ai/developer-guide/platform-api/safety/production-evals) and the [Metric Store](https://docs.amigo.ai/developer-guide/platform-api/safety/metric-store) for Platform contracts. For Classic API definitions and evaluation, see the [Classic Metrics API](https://docs.amigo.ai/developer-guide/classic-api/core-api/metrics).
{% endhint %}
# Drift Detection
Detect gradual performance changes by comparing metric trends, production examples, and simulation baselines through a deliberate monitoring workflow.
Drift is a sustained change in the inputs an agent receives, the behavior it produces, or the requirements used to judge it. The platform supplies metric results, analytics, run history, and simulation evidence that teams can use to identify these changes.
Drift response is currently a monitoring and release-management practice. The platform does not automatically turn a trend threshold into a promotion block or production rollback.
## What Causes Drift
### Input Drift
The mix of conversations changes. A scheduling agent tested mostly on routine requests may begin receiving multi-provider coordination calls, a new language mix, or questions caused by a policy change.
### Performance Drift
Measured behavior changes over time. Task completion may decline, latency may rise, or a safety evaluation may worsen after a configuration, dependency, or model change.
### Requirement Drift
The agent may behave consistently while the acceptance criteria change. Updated clinical guidance, organizational policy, or regulatory requirements can make an earlier test suite incomplete.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
evidence["Production metrics\nrun history\nsimulations"] --> compare["Compare periods\nand relevant segments"]
compare --> review{"Sustained or\nmaterial change?"}
review -->|No| monitor["Continue monitoring"]
review -->|Yes| inspect["Inspect examples\nand identify cause"]
inspect --> test["Update cases\nand validate a fix"]
test --> release["Authorized release\ndecision"]
release --> monitor
```
## Available Evidence
### Production Metric Trends
Configured evaluations produce per-interaction results that can be aggregated over time. Use the analytics views or APIs to compare equivalent windows before and after a release. Keep the metric definition and population stable so a scoring change is not mistaken for an agent regression.
Where filters are available, break the result down by service, channel, outcome, or another relevant dimension. A workspace-wide average can hide a regression concentrated in one workflow.
### Conversation and Run Review
Open representative interactions behind a changed metric. Transcripts, executed actions, tool results, completion reasons, and best-effort trajectory evidence help distinguish an agent problem from input changes or an external dependency failure.
### Simulation Baselines
Saved cases and suites provide repeatable checks for known behaviors. Compare current results with the acceptance criteria for the same cases, then add production examples that reveal a missing scenario.
Simulation and production populations are not automatically compared as a statistical blueprint. Teams decide which production segments correspond to which test cases and interpret the gap.
## A Practical Response Process
1. **Confirm the signal.** Compare enough interactions and an appropriate time window to separate a sustained change from normal variance.
2. **Locate the affected population.** Narrow the change by service, channel, release, failure type, or another available dimension.
3. **Inspect examples.** Review successful and failed interactions, including tool and dependency outcomes.
4. **Update the test set.** Add cases for new inputs or failure modes and update criteria when requirements changed.
5. **Validate a focused change.** Run the affected suite and important safety guardrails before release.
6. **Make an explicit release decision.** An authorized user promotes, pauses, or restores a configuration based on the evidence.
7. **Measure the same population again.** Confirm that the target recovered without creating a new regression.
## Alerts and Rollback
The documentation's earlier alert, promotion-gate, and automatic-rollback workflow is not a current platform capability. If a team needs automated notification, it can query the analytics APIs from its monitoring system and route a threshold breach through its normal incident process.
For a severe regression, operators should follow the organization's release procedure: stop or limit the affected workflow when appropriate, select a known-good version deliberately, and verify the result. Keep a human decision in this path, especially when a metric is noisy or a rollback could reintroduce an older safety problem.
## Monitoring Checklist
* Choose a small set of outcome and safety metrics with clear owners.
* Record the baseline window, metric definition, filters, and released version.
* Use review windows that fit traffic volume; low-volume services need longer windows.
* Define investigation thresholds in the monitoring or operating process.
* Preserve representative interactions and convert new failure modes into simulation cases.
* Recheck the same measures after every material release.
{% hint style="info" %}
Drift is not always a defect. Input drift can reveal a new use case, while requirement drift can reveal that the test suite needs to change. Investigate the cause before restoring an older configuration.
{% endhint %}
# Intelligence Overview
Per-interaction evidence, workspace analytics, dashboards, metric values, and the boundaries that determine their availability.
Use intelligence and analytics to investigate individual interactions and compare operational results over time. Available evidence includes run records, generated analysis, evaluation scores, and workspace metrics. Processing can be incomplete or delayed; audio analysis requires a usable recording.
Per-interaction analysis, workspace analytics, and metric values have separate producers and processing schedules. Confirm the source and coverage of a measure before using it for a deployment decision.
## Match the Evidence to the Decision
| Evidence | What it helps answer | Boundary to preserve |
| ------------------------------------- | -------------------------------------------------------- | ------------------------------------------------------------------------------- |
| **Run and interaction records** | What happened during this interaction? | Coverage depends on the retained artifacts and runtime |
| **Call intelligence and evaluations** | How did the available interaction evidence score? | Generated analysis and scores are not independent confirmation of external work |
| **Metric values and dashboards** | How do defined measures compare across runs or periods? | Definitions, filters, missing results, and freshness affect the comparison |
| **External outcome records** | Did the intended scheduling or operational result occur? | The customer may need to supply or join evidence from the destination system |
Start with an individual example before interpreting an aggregate trend. Then use the same definitions and relevant segments for comparisons. [Evaluating Amigo](/platform-overview/evaluating-amigo#6-define-what-the-evaluation-can-establish) describes that review; [Continuous Improvement](/agent/pattern-discovery-and-reuse) connects a finding to a tested change.
## Call Intelligence
Voice call intelligence can combine operational profiles derived from call signals, post-interaction quality scoring, and audio-native scoring from the recording. Text interactions use the evidence available to their modality and do not receive audio-native analysis. Composite scores support trend analysis, while transcripts and structural traces show observed states, actions, and tool execution without exposing hidden model reasoning.
{% content-ref url="/pages/MkLNfREKUnb7P6psyljs" %}
[Call Intelligence](/intelligence-and-analytics/intelligence/call-intelligence)
{% endcontent-ref %}
## Analytics and Dashboards
Workspace analytics cover call and production-eval trends, surface outcomes, event composition, connector and pipeline health, and current entity-inspection views. Built-in and custom dashboards and the conversational Insights Agent support analysis, while the unified Runs surface remains the canonical interaction inventory. Each analytical surface has its own evidence source and freshness boundary.
{% content-ref url="/pages/bjGXGvlgUdBZL69XK5bs" %}
[Analytics and Dashboards](/intelligence-and-analytics/intelligence/analytics-dashboards)
{% endcontent-ref %}
### Topic Classification
Workspaces can enable automated conversation topic classification. When the setting is active, the platform periodically discovers enabled workspaces, resolves their active taxonomy and service context, and classifies recent conversations against the taxonomy. Each workspace is processed independently - a misconfigured workspace is quarantined for triage rather than blocking classification for other tenants. Workspaces require exactly one active taxonomy and at least one active service with a non-blank name to qualify; workspaces that do not meet these prerequisites are recorded as skipped with a reason so the gap is visible rather than silent.
## Metric Store
The Platform API exposes 41 built-in metric definitions across six categories and supports up to 50 workspace custom definitions. Recent and durable values share one response model, but producers, execution schedules, and modality requirements differ. A catalog entry or freshness target does not guarantee that a value exists or will arrive within a fixed time.
{% content-ref url="/pages/JSIAMGCtRP91KAwiUten" %}
[Metric Store](/intelligence-and-analytics/metric-store)
{% endcontent-ref %}
## Event Streams and Analytics
The workspace SSE stream publishes supported call, surface, pipeline, text, operator, and other workspace events as they occur. It is an operational notification channel, not the durable analytics store, and it includes only events that producers publish. Consumers should reconnect with the last event ID when possible and reconcile important state through the corresponding read API.
A separate per-call observer stream can provide live transcript and tool activity for call monitoring. Stream availability does not imply that the same evidence will be retained indefinitely or that post-call intelligence has completed. See [SSE Events](https://docs.amigo.ai/developer-guide/platform-api/conversations/sse-events) in the developer guide for endpoint and payload details.
{% hint style="info" %}
**Developer Guide** - For the full analytics endpoint set and metric store details, see [Analytics](https://docs.amigo.ai/developer-guide/platform-api/safety/analytics) in the developer guide.
{% endhint %}
# Call Intelligence
Terminal voice-call evidence, operational quality scoring, optional audio analysis, decision traces, and playback timelines.
Call intelligence combines several kinds of evidence produced during and after an eligible voice call. These outputs are related, but they are not one universal score: the terminal operational summary measures runtime behavior, post-call analysis evaluates the recorded interaction, and the Voice Judge evaluates audio quality. Availability depends on the voice runtime, configuration, recording, and downstream processing.
## Evidence Paths
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
C[Voice Call] --> T[Terminal Operational Summary]
T --> Q[Operational Quality Score 0-100]
C --> R[Call Recording]
R --> P[Optional Post-Call Analysis]
R --> V[Voice Judge for Eligible Calls]
C --> D[Decision Trace + Playback Timeline]
Q --> A[Call Review + Analytics]
P --> A
V --> A
D --> A
```
### Terminal Operational Summary
At call completion, the primary voice runtime derives a terminal artifact from the session state it has observed. Depending on the available signals, that artifact can include:
| Evidence | What It Captures |
| ------------------------ | --------------------------------------------------------------------------------------------------------------------------- |
| **Emotion** | Aggregated emotional state and compound-emotion observations when emotion processing was available |
| **Latency** | Engine and audio time-to-first-byte averages and percentiles, navigation and rendering latency, and estimated silence ratio |
| **Conversation shape** | Turn count, duration, completion reason, final state, state revisits, and barge-ins |
| **Tool performance** | Tool-call totals, failures, failure rate, and per-tool timing |
| **Operator involvement** | Whether the call escalated and whether an operator was active |
The persisted wire shape still contains `risk_summary` and `safety_summary` for compatibility, but the current runtime leaves both empty. Authored agent policy and operator workflows govern safety and escalation; consumers must not infer a live risk scorer or safety-rule engine from those fields.
Some external voice runtimes do not provide the per-turn inputs needed for this summary. They emit a minimal completion envelope with list and lifecycle fields, while leaving analytical summaries empty and the quality score unset.
### Optional Post-Call Analysis
When post-call analysis is enabled and a recording is available, a background analysis evaluates five dimensions on a 1-5 scale:
| Dimension | What It Measures |
| ------------------------ | ------------------------------------------------------- |
| **Task completion** | Whether the caller achieved the purpose of the call |
| **Information accuracy** | Whether details were captured and understood correctly |
| **Conversation flow** | Pacing, repetition, overlap, and confusion |
| **Error recovery** | How the agent recovered from misunderstandings |
| **Caller experience** | The caller's apparent experience by the end of the call |
The result can also include an overall score, an outcome of `succeeded`, `partially`, `failed`, or `abandoned`, observed issues, and suggested speech-recognition keyterms. These suggestions are review evidence; they do not automatically rewrite voice configuration. Analysis is asynchronous and best-effort, so a completed call can exist without a result.
### Voice Judge Overview
The Voice Judge is a separate scheduled pipeline for eligible recorded production calls. It evaluates audio-native characteristics that structured runtime data cannot establish. See [Voice Judge](#voice-judge) for its rubric and eligibility boundaries.
## Operational Quality Score
Full terminal operational summaries receive a 0-100 quality score. The deterministic calculation starts at 100 and applies penalties for:
* High p95 audio time to first byte
* Excessive estimated silence
* Repeated caller barge-ins
* Revisited conversation states
* Operator escalation
* Tool-call failures
This score measures observable runtime friction. It is not a task-success score, clinical-risk score, or safety judgment. Post-call rubric scores and Voice Judge scores remain separate.
Analytics group operational scores into four ranges:
| Range | Label |
| ---------- | --------- |
| **90-100** | Excellent |
| **70-89** | Good |
| **50-69** | Fair |
| **0-49** | Poor |
Use individual scores to inspect a call and distributions to compare services or time periods. A missing score means the runtime did not produce sufficient operational evidence; it should not be treated as zero. See [Call and Eval Analytics](/intelligence-and-analytics/intelligence/analytics-dashboards#call-and-eval-analytics) for aggregate views.
## Summary Flags and Transcript Verification
Call detail can derive review flags from aggregate evidence such as latency, silence, barge-ins, loops, tool failures, and operator escalation. These flags explain why the operational score changed, but they are not guaranteed to identify the exact timestamp of an incident. Use the playback timeline or call trace analysis for time-oriented review.
When post-call transcript verification is enabled, the platform runs a higher-accuracy transcription pass and stores the verified transcript, word timings, and accuracy measurements when processing succeeds. Post-call quality analysis can separately suggest recognition keyterms. Neither path silently changes a service's configured keyterms.
## Production and Simulation Evidence
Production voice calls and simulation sessions preserve different evidence boundaries:
* **Production voice calls** can produce terminal operational summaries, recordings, post-call analysis, playback timelines, trace analysis, and Voice Judge results when their prerequisites are met.
* **Simulation sessions** emit source-tagged, run-linked terminal artifacts built from simulated turns, tools, terminal state, and simulation score. The metric pipeline keeps simulation and production scopes separate.
* **Audio-native analysis** does not apply to simulations without recordings. A simulation score is simulation-specific evidence, not a production operational quality score.
This separation lets teams compare like with like without allowing synthetic sessions to blend into production call analytics.
## Decision Trace
For supported voice calls, the runtime emits terminal per-turn decision events after the call. Each event can include:
* The signal classification that triggered the turn
* The effect classification describing what the agent did
* Current and transitioned states
* Tool names and success state
* Emotion observations and latency measurements when available
* Counts of configured inner-thought annotations, rather than hidden model reasoning
Decision-trace events support structural analysis such as turns per call, tool invocation rate, and state transition rate. They describe recorded actions and evidence; they do not reconstruct an unobserved chain of thought.
## Debug Traces
Administrators and owners can use two sensitive debugging views for a completed voice call:
* **Execution trace** - Persisted per-turn inputs and outputs, including transcripts, actions, tools, state transitions, emotion observations, configured inner-thought annotations, and latency fields.
* **Prompt trace** - Best-effort prompt-log records for turns whose prompt evidence was durably emitted.
Prompt evidence may be unavailable even when the execution trace exists. Access is restricted because these views can contain model internals and protected data.
## Call Trace Analysis
For an eligible completed call with accessible audio, asynchronous trace analysis can produce:
* A narrative summary and outcome
* Key decision moments with audio-grounded factors
* An emotional arc and critical emotional shifts
* Interaction dynamics and signal-response alignment
* Coaching recommendations and missed opportunities
* Counterfactual alternatives and predicted impact
* A synthesized explanation of why the call unfolded as it did
The API distinguishes `ready`, `pending`, and `unavailable`. A read can trigger best-effort on-demand processing for a qualifying production call, but a result is not guaranteed. Simulation sessions are not eligible for the recording-based trigger.
## Call Playback Timeline
The call detail response can include a canonical timeline that places speech and runtime events on one shared coordinate system.
### Lanes and Actors
Lanes are derived from the segments present in a call. Each lane has a stable ID, display order, semantic track, and actor when applicable. Supported tracks are caller, agent, operator, tool, and system. Tool and system events can receive distinct lanes based on their actor identity.
Operator speech uses the `caller_speech` segment type with operator actor metadata and the operator track. Consumers should use the actor and track fields rather than infer the speaker from the segment type alone.
### Segment Types
The current timeline vocabulary is:
| Category | Segment Types |
| ---------------------- | ----------------------------------------------------------------- |
| **Speech** | `caller_speech`, `agent_speech`, `greeting`, `interrupted_speech` |
| **Fillers and checks** | `filler_nav`, `filler_hesitation`, `silence_check` |
| **Interaction** | `barge_in` |
| **Execution** | `processing_gap`, `tool_call`, `state_transition` |
| **Inactivity** | `silence` |
### Shared Timebase
Segment start and end values are seconds on the response's shared timebase. Where exact audio offsets exist, the timeline aligns segments to the media. Where a legacy producer lacks exact offsets, the platform supplies synthetic positions so the call-detail UI still receives one consistent lane and seek model. Consumers can therefore render the response as provided instead of rebuilding timing independently.
See [Audio Pipeline](/channels/voice/audio-pipeline) for the voice timing settings that influence the underlying events.
## Voice Judge
The Voice Judge scores eligible recorded production calls across ten audio-native dimensions. It reads the caller channel and, when available, the agent channel; an inbound-only recording can be evaluated as mono.
### Ten Evaluation Dimensions
| Dimension | What It Measures |
| ------------------------- | ------------------------------------------------------- |
| **Latency and Dead Air** | Response timing and silence management |
| **Pronunciation** | Speech clarity and correctness, including medical terms |
| **Clarity** | Intelligibility of speech |
| **Filler and Silence** | Tool-call acknowledgments and dead-air handling |
| **Interruption Handling** | Barge-in detection and recovery |
| **Audio Consistency** | Volume and pitch stability without cutoffs |
| **Pacing** | Conversational tempo and pauses |
| **Warmth and Tone** | Tonal appropriateness to the caller's state |
| **Accent Quality** | Language match and accent naturalness |
| **Voice Identity** | Consistency of the agent voice |
Each dimension can produce a score from 0.0 to 1.0, a severity of `none`, `warning`, `flag`, or `critical`, and audio-grounded evidence for non-`none` findings.
### Eligibility and Delivery
The scheduled job considers completed production calls within its lookback window, skips calls with a known duration of five seconds or less, excludes calls that already have a result, and requires an accessible inbound recording. Missing recordings, processing errors, and warehouse latency can leave an otherwise completed call without a Voice Judge row.
Results are available through two paths:
* **Recent per-service results** - Per-call scores and the bounded evidence payload for investigation
* **Aggregate metrics** - Ten built-in [Metric Store](/intelligence-and-analytics/metric-store) metrics for workspace-level trends
{% hint style="info" %}
**Developer Guide** - See [Call Trace Analysis](https://docs.amigo.ai/developer-guide/platform-api/safety/call-trace-analysis) and [Voice Judge](https://docs.amigo.ai/developer-guide/platform-api/safety/voice-judge) for endpoint contracts.
{% endhint %}
# Analytics and Dashboards
Workspace analytics, pipeline observability, entity inspection, dashboards, and the Insights Agent - with their freshness and evidence boundaries.
Amigo exposes several workspace-scoped analytics surfaces. They do not share one universal data source, refresh schedule, or filter contract. Interpret each result according to the evidence that produced it:
| Surface | Primary Evidence | Important Boundary |
| -------------------------------- | ------------------------------------------------------------ | ----------------------------------------------------------------------------- |
| **Call intelligence** | Completed voice interaction artifacts | Fields can be null or absent when the required call evidence was not produced |
| **Production eval analytics** | Persisted assertion and metric verdicts | Covers only conversations that were evaluated |
| **Surface analytics** | Surface lifecycle and saved-field state | A drop-off correlation does not prove that a field caused abandonment |
| **World and pipeline analytics** | Serving projections, connector state, and diagnostic queries | Live status and historical counts can have different freshness |
| **Metric store** | Recent metric values and durable metric history | Latest API reads can be fresher than dashboard panels |
## Call and Eval Analytics
Voice call analytics read the call-intelligence projection for the selected workspace and time window.
| View | What It Returns |
| ---------------------------- | -------------------------------------------------------------------------------------------------------------------------------------- |
| **Call quality** | Average, p50, and p95 quality score; call count; escalation rate; average duration; a time series; and quality-score bands |
| **Advanced call statistics** | p50, p95, and p99 duration; quality percentiles; a trend with p95 audio latency; and service and direction breakdowns |
| **Emotion trends** | Dominant-emotion counts and average valence and arousal over time when emotion evidence exists |
| **Latency** | Engine p50 and p95, audio time-to-first-byte p50, p95, and p99, plus average navigation, render, and silence values |
| **Tool performance** | Aggregate tool calls, successes, failures, failure rate, and a time series. It does not provide per-tool duration or per-tool ranking. |
| **Operator performance** | Escalation count and rate, operator-handled count, escalated-call duration, quality comparison, and an escalation trend |
| **Eval quality** | Overall and per-eval-key pass rate and average score, plus a trend across persisted production eval verdicts |
Most call-intelligence endpoints accept a one-hour, one-day, or one-week interval, an optional service filter, and a `days` lookback of up to 90 days. Endpoints that accept explicit start and end dates use those dates instead of the lookback. Advanced call statistics can also filter by inbound or outbound direction. The explicit comparison endpoint accepts separate current and previous date ranges and returns absolute and percentage deltas.
The workspace home composite is narrower: it returns six headline call KPIs for a one-to-90-day window and compares applicable values with the preceding equal-length period.
{% hint style="warning" %}
An empty series can mean that no eligible evidence exists, that an asynchronous projection has not caught up, or that an analytical dependency is unavailable. It is not proof that the measured behavior did not occur.
{% endhint %}
### Call Detail and Retention
Aggregate analytics and call detail have separate availability paths. A retained analytics row does not guarantee that a recording, transcript, full turn history, or every post-call artifact is still available. Apply the workspace's retention policy to each artifact type and treat missing evidence as unknown rather than zero.
### Production Eval Evidence
Production eval analytics are channel-agnostic because verdicts are keyed to the durable conversation. Voice, text, SMS, and email conversations can contribute when an eval actually ran and persisted a result.
Eval scores are model- or assertion-derived evidence, not proof of factual, clinical, or regulatory correctness. Automatic post-conversation evaluation is feature- and configuration-dependent, and the manual evaluation endpoint persists its results rather than acting as a non-persisting preview.
## Surface Analytics
[Surfaces](/channels/surfaces) have four analytics views:
| View | What It Returns |
| ------------------------- | ---------------------------------------------------------------------------------------------------------------- |
| **Completion rates** | Created, opened, completed, and abandoned totals; completion and drop-off rates; a trend; and a source breakdown |
| **Channel effectiveness** | Delivery count, completion count and rate, and average completion time by observed channel |
| **Field abandonment** | Overall abandonment plus saved and missing counts for fields on abandoned surfaces |
| **Entity history** | Completion statistics, the most frequently observed channel, and recent surfaces for one entity |
Date-based surface views default to a 30-day lookback, with `days` capped at 90. Views that accept explicit start and end dates use those dates instead. Completion rates additionally support interval and entity filters. Entity history uses a separate result limit rather than a date-range filter.
Field-level results describe where incomplete submissions stopped. Use them to form a hypothesis, then validate wording or workflow changes with controlled comparisons. The data alone cannot establish that a question was confusing, unnecessary, or too sensitive.
## Event and Data Quality Analytics
### Event Breakdown
The event-breakdown view returns current aggregate counts by event type and reported source. It is useful for checking whether expected event families and sources are represented. It is not currently a historical time series, so do not infer when a source became quiet from this response alone.
Use pipeline source history or connector-health data for temporal ingestion evidence.
### Current Data-Quality Coverage
The current data-quality endpoint is intentionally limited. When its serving projection has data, it returns an aggregate projected confidence value and event count. The source breakdown is currently empty, the time series is at most a current summary point, and review-pipeline fields are compatibility placeholders with zero or null values.
Do not use this response as a complete confidence distribution, source-quality comparison, or review-governance report. External write proposals use the separate [Review Queue](/data/review-queue), and proposal decisions do not rewrite the confidence of their source events.
## Pipeline Observability
Pipeline observability combines connector-runner state with workspace read models and diagnostic analytics:
| View | What It Shows |
| --------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Status** | Connector status, uptime when available, active polls, seven-day event count and read-model status, entity count, source states, and reported background-process state |
| **Sources** | Configured sources with activation, stored health, last poll, sync status, and latest poll counts |
| **Source detail** | Source metadata, recent failures, diagnostic event history, and outbound summary when those reads are available |
| **Outbound** | Per-sink synced, failed, and pending counts plus an attempt log |
| **Throughput** | Hourly or daily ingestion counts for the requested window |
| **Entity resolution** | Historical `same_as` edge counts and the currently reported resolution-loop status |
Diagnostic history, outbound, and throughput views can return empty results when their analytical reader is unavailable. Summary responses expose read-model availability separately where supported; preserve that distinction in alerts and dashboards.
The review-metrics route remains for response compatibility but currently returns a zeroed shape because the earlier review queue has no active producer. The active external-write review workflow is separate.
### Connector Health and Loop Latency
Two Sensorium views add operational evidence:
* **Connector health** - events in the last hour and rolling 24 hours, mean events per minute, most recent ingestion time, a freshness category, and read-model status for each observed source.
* **Loop latency** - the median time between paired sensing and agent-action events over a one-to-168-hour window, with hourly counts, median values, and a truncation flag.
Loop latency covers only events the pairing logic can associate. A low pair count or a truncated sample limits what can be concluded about end-to-end behavior.
## Workspace and Agent Health
### Workspace Health Composite
The Platform API exposes a composite used by the Developer Console home page. Its four sections fail independently and the response identifies degraded sections.
| Section | Current Observed Coverage |
| ---------------- | ------------------------------------------------------------------------------------------- |
| **Voice** | Active calls, active escalations, calls today, average quality, and today's escalation rate |
| **Pipeline** | Connector status and source health counts |
| **Data quality** | Entity count and historical recent `same_as` edge count |
| **Identity** | Active API key count |
Several schema fields are placeholders today: event throughput and outbound queue counts are `0`, review counts are `0` or `null`, average entity confidence is `null`, and identity session, failed-authentication, lockout, and MFA values are `null`. Derived stale-pipeline, outbound, confidence, or identity conclusions are therefore not reliable until those fields gain active producers.
The active-call portion of the voice section can reflect the live voice service. Its calls-today, quality, and daily escalation rollups currently read a compatibility serving table that is no longer the source used by the primary call-analytics endpoints, so those three values can be stale or empty. Use the analytics dashboard response for current durable call aggregates.
### Developer Console Production Health
The Developer Console home page shows a workspace pulse with active agents, calls today, active calls, average quality, escalation rate, and tool success. Agent cards link to a production detail page with call-quality, latency, emotion, and aggregate tool-performance charts plus recent calls.
The current status badge is a UI heuristic:
* **Paused** - the service is inactive.
* **Degraded** - the value labeled **Pass rate** is below 80, or the selected period contains zero calls. That value currently comes from average call-quality score, not production-eval pass rate.
* **Live** - neither degraded condition is met.
`Live` is not a safety certification, availability guarantee, or proof that all analytical inputs are present. Escalation rate is displayed but does not currently determine the badge.
## Entity Inspection
Entity intelligence exposes four current behaviors:
| Capability | Current Behavior |
| ---------------------- | -------------------------------------------------------------------------------------------------------------------- |
| **Relationship graph** | One level of stored current edges and neighbor metadata |
| **Provenance** | Entity identity and historical `same_as` merge information; source and confidence-history arrays are currently empty |
| **Duplicate history** | Historical `same_as` edges ordered by stored confidence. It does not run a current duplicate-detection model. |
| **Search** | Case-insensitive display-name search with entity-type filtering and pagination |
Historical `same_as` rows came from the earlier resolver. The active pipeline does not create new merge edges. Lineage responses also retain empty outbound-sink and review-history arrays for compatibility, so they are not a complete delivery or governance audit.
### Narrative Briefs
Brief routes accept patient, cohort, territory, emirate, and district entities, with a separate workspace-level route. Responses include Markdown and structured content, evidence identifiers, confidence, event count, version, generation time, and a truncation indicator when a brief has evidence.
The current serving path does not yet load event evidence into brief generation. A generation request therefore produces the empty-evidence response rather than a synthesized patient or population narrative. Do not use the current brief response as a clinical summary. A read before any brief exists returns a successful empty shape with `event_id: null`.
## Dashboards
Three immutable built-in dashboard templates are visible to every workspace:
| Dashboard | Current Panels |
| ------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Data Browser Insights** | Operational views over available FHIR resources, world entities, facilities, and provider availability |
| **Realtime Metric Store** | Metric summary, numerical scores, daily scored events, production versus simulation values, categorical distribution, entity coverage, freshness, and per-call scores |
| **Eval Summary** | Workspace-aggregate eval scores by metric, trend, and categorical outcome |
Definitions are available without workspace setup, but panels can be empty or unavailable until their source data and analytical query path are ready. The built-in templates refresh every five minutes by default.
Workspace dashboards are separate mutable resources. The dashboard API supports create, list, read by ID or slug, update, soft delete, and panel execution. Built-in templates cannot be updated or deleted through the workspace API. Panel queries are executed with workspace scoping, and execution requires data-view permission.
### Embeddable Rendering
The Developer Console renders dashboard definitions with the `@amigo-ai/dashboards` component package. The same `DashboardEmbed` component can fetch a definition by slug, execute its panels, apply declared filters, and refresh on an interval when supplied with a Platform API base URL, workspace ID, and valid authentication.
Embedding does not weaken workspace authorization. External applications must protect credentials and preserve the Platform API's data-view permission boundary.
## Insights Agent
The Insights page combines a proactive digest with conversational analysis:
* The digest and suggested questions can remain unchanged for up to five minutes after source data changes.
* Chat creates a workspace-scoped session and streams progress, tool activity, structured result blocks, follow-up suggestions, and completion events over SSE.
* Result blocks can contain text, metric cards, tables, entity lists, and Plotly charts.
* Tool labels and results can be visible, but hidden model reasoning is not exposed.
The agent can use guarded workspace queries, entity reads, call analytics, metric values, and available analytical functions. The freshness of an answer depends on the selected tool and its underlying projection. Model-generated interpretation can be incomplete or incorrect, and malformed visual blocks can be discarded by the client. Verify material operational or clinical conclusions against the cited records and direct API results.
Useful questions include:
* "How has call quality changed over the last seven days?"
* "Show production and simulation values for these metric keys."
* "Which entity types are represented in this workspace?"
* "Summarize recent call volume and escalation rate."
{% hint style="info" %}
**Developer Guide** - For request parameters and response schemas, see [Analytics](https://docs.amigo.ai/developer-guide/platform-api/safety/analytics) and [Insights](https://docs.amigo.ai/developer-guide/platform-api/safety/insights) in the developer guide.
{% endhint %}
# Proactive Journeys
Sample-data preview of proactive journey observability covering signal, outreach, conversation, evaluation, and outcome evidence.
The Journeys section of the Developer Console provides a preview of proactive journey observability - an operating view that tracks the lifecycle of outbound healthcare journeys from initial signal through outreach, agent conversation, evaluation, and final outcome.
{% hint style="info" %}
Journey observability is currently a sample-data preview. The dashboards render a fixed set of demonstration events and are not yet connected to workspace data. A persistent banner discloses this on every journeys page.
{% endhint %}
## What a Proactive Journey Covers
A proactive journey follows a population through a multi-step engagement lifecycle:
1. **Signal.** A cohort of members is identified for outreach based on a triggering condition (for example, an upcoming appointment with missing intake data).
2. **Outreach.** The platform attempts to reach each member through one or more channels (SMS, email, voice, chat).
3. **Conversation.** Members who respond engage in an agent-driven conversation to resolve the identified need.
4. **Evaluation.** Completed conversations are scored for safety, accuracy, and quality.
5. **Outcome.** Each member reaches a terminal state: completed, handed off to a human, unresolved, or opted out.
## Journeys List
The Journeys list page shows the fixed sample journey templates with summary health metrics for each:
* **Funnel visualization.** A stepped bar chart showing member counts at each lifecycle stage from cohort inclusion through completion, so drop-off points are visible at a glance.
* **Outcome strip.** A proportional bar showing the distribution of terminal outcomes (completed, handed off, unresolved, opted out) with color-coded tones.
* **Key metrics.** Cohort size, outreach attempted, reached, conversations started, actions completed, and eval pass rate.
Clicking a journey opens its detail dashboard.
## Journey Detail Dashboard
The journey detail dashboard demonstrates the intended operating view for one sample journey:
### Overview Metrics
A row of KPI cards covering members included, outreach attempted, reached (delivered or responded), conversations started, actions completed, human handoffs, opt-outs and suppressions, eval pass rate, and safety warnings. Each metric includes a definition tooltip explaining how the number is computed.
### Funnel and Outcome Charts
Interactive charts showing the engagement funnel (cohort to completion) and outcome distribution by channel. The outcome-by-channel chart uses consistent tone semantics:
* **Completed** - success tone
* **Handed off** - info tone (a deliberate routing outcome, not a failure)
* **Unresolved** - warning tone (the state that needs attention)
* **Opted out** - neutral tone (a member preference, not a failure)
### Agent Resolution Table
A detailed table of individual member journeys showing signal date, outreach status, channel, conversation status, evaluation result, and terminal outcome. Each row links to a member timeline drawer.
### Member Timeline Drawer
A chronological timeline of the events included in a sample member journey - cohort inclusion, outreach attempts, delivery status, conversation start, agent actions, evaluation results, handoffs, suppressions, and final outcomes. Includes sample conversation identifiers for traceability.
### Quality Panel
Evaluation pass rates and safety warning counts with drill-down to individual members flagged for review.
### Sample Period
The sample data window is labeled explicitly (for example, "May 1 - May 5, 2026") to avoid presenting the fixtures as current workspace activity.
## Navigation
Proactive Journeys is limited to designated Library demo workspaces and is not a standard production sidebar item. Open it through the Developer Console command palette or a direct Library link. The previous routes under `/dashboards/proactive-journey` redirect to `/journeys`, preserving existing demo bookmarks.
# Metric Store
The current metric catalog, custom-definition boundaries, dashboard behavior, query surface, and freshness semantics.
## Semantic Foundation
The Metric Store is built on a governed semantic layer that enforces consistency, traceability, and workspace-scoped security across all metric definitions and computations.
### Canonical Models
Metrics are computed against a fixed set of canonical models that represent the platform's core analytical domains:
* **Conversation fact** - conversation and run lifecycle
* **Interaction fact** - user, agent, and system interactions
* **Tool execution fact** - decision, state-transition, and tool-execution evidence
* **Conversation outcome fact** - conversation-to-outcome relationships
* **Evaluation fact** - call-quality, safety, latency, and voice-judge evaluations
* **Topic classification fact** - conversation-topic classifications
* **Appointment workflow fact** - appointment, slot, workflow, and state transitions
* **Entity dimension** - workspace-scoped entity and identity relationships
* **Event evidence fact** - typed event, evidence, and review records
* **Model health fact** - connector, event-throughput, and metric-freshness health observations
* **Surface interaction fact** - workspace-scoped surface and form interaction events
Each canonical model declares its grain (for example, one conversation or one tool execution), its key columns, its timestamp columns, and an explicit freshness target. These declarations make the contract between raw platform data and computed metrics auditable.
### Governed Relationships
Canonical models are connected through governed relationships that define how models can be joined. Each relationship declares its parent and child model, join keys, cardinality (such as one-to-many), and allowed join direction. Relationships are versioned and certified independently of the models they connect.
For example, a conversation can have many interactions, many tool executions, many outcomes, many topic classifications, many evaluations, and many surface interactions. An outcome can have many appointment workflow events. These relationships are enforced at definition time so that metric authors cannot construct unsupported joins.
### Semantic Metric Definitions
A semantic metric definition wraps a standard metric definition with additional governance:
* **Base model** - which canonical model the metric is computed against
* **Dimensions** - the approved dimensional axes (workspace and reporting period are always required; service and channel are optional)
* **Time field** - which timestamp column drives the reporting period
* **Owner** - the responsible party for the metric
* **Security classification** - currently workspace-scoped, ensuring metrics never cross workspace boundaries
* **Version and status** - definitions move through draft, certified, and deprecated states
* **Required relationships** - which governed relationships the metric depends on
* **Validation tests** - references to tests that verify the metric's correctness
Definitions are compiled into deterministic execution plans before computation. The compilation step validates that the base model exists in the certified registry, that all required relationships are certified, and that the requested dimensions and time field are supported by the base model. The execution plan includes a content hash so that identical definitions produce identical plans.
### Freshness Tracking
Each canonical model and metric definition declares an explicit freshness target in minutes. The platform classifies each materialized result as:
* **Fresh** - computed within the freshness target
* **Stale** - computed but older than the freshness target
* **Never computed** - no successful computation has occurred
* **Failed** - the most recent computation attempt failed
This classification drives the freshness indicators visible in dashboards and health monitoring.
### Computation
Certified metric definitions are computed periodically against their canonical models. Each computation run:
1. Reads the certified execution plan for each active metric definition
2. Queries the canonical model within a configurable time window (up to 7 days)
3. Aggregates values by the declared dimensions using the plan's aggregation type (count, count distinct, sum, average, min, max, ratio, or rate)
4. Merges results into the metric values store using an upsert strategy keyed by workspace, metric, version, period, and dimension combination
5. Records the computation run's status, timing, and any error for observability
Computation is workspace-scoped: a metric definition owned by one workspace can only read data from that workspace's partition of the canonical model.
## Setup and Refresh
The Metric Store provides two operational endpoints for workspace administrators:
* **Setup** triggers a one-time schema and registry initialization for the workspace. This is an idempotent operation - running it more than once has no adverse effect.
* **Refresh** triggers an on-demand refresh of the canonical Metric Store models. Use this when you need updated metrics before the next scheduled pipeline run.
Both operations are asynchronous. The endpoint returns a run identifier that you can poll for status. The run status reports lifecycle state, result state, and a human-readable message. Setup and refresh require the workspace update permission.
Each endpoint returns `202 Accepted` with a run identifier. If the backing job is not yet configured for the environment, the endpoint returns `503 Service Unavailable`.
### Workspace Scoping
All canonical Metric Store models enforce workspace-level scoping. Rows without a valid workspace identifier are excluded during materialization, ensuring that every record in the serving layer is attributable to a single workspace.
## Canonical Models
The Metric Store includes a set of canonical models that normalize data from multiple platform sources into consistent, workspace-scoped views. These models are materialized as governed projections and serve as the foundation for metrics, dashboards, and downstream analytics.
Canonical models use a pointer-driven design: physical source tables are resolved through configuration rather than hard-coded references, so environment changes do not require editing transformation logic.
### Available Models
| Model | Purpose |
| --------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Entity Dimension | Workspace-scoped entity identity and governed dimensions. Joins entity attributes with identity mappings to produce a single row per entity with canonical identifiers, display names, service assignments, patient and provider references, facility assignments, and channel information. |
| Conversation Fact | Cross-channel conversation lifecycle at one row per workspace conversation. Merges run-level metadata with session and voice activity to produce start and end timestamps, status, run counts, and interaction counts. |
| Interaction Fact | Normalized text, voice, and world-event interactions. Unions session-based text turns, voice turns, and non-session event interactions into a common shape with interaction type, channel, timestamps, and source evidence. |
| Decision and Tool Execution Fact | Decision, state-transition, and tool-execution evidence. Captures tool name, success status, state transitions, and timing from both traced execution paths and world-event evidence. |
| Conversation Outcome Fact | Outcome and handoff evidence attributable to conversations when source identity permits. Unions outcome events, current outcome projections, and resolved outcome projections. |
| Call Intelligence Fact | Call-quality, safety, latency, and evaluation results. Merges call intelligence records with evaluation scores into a unified shape covering quality scores, duration, completion reason, emotion analysis, risk assessment, and tool execution summaries. |
| Topic Classification Fact | Conversation topic classifications joined with taxonomy metadata. Includes primary and secondary category assignments, confidence, reasoning, taxonomy version, and model information. |
| Appointment Workflow Fact | Appointment lifecycle, status, and workflow evidence. Unions appointment-specific events with general workflow evidence that carries appointment data. |
| Event and Clinical Evidence Fact | Typed event, clinical, and review evidence records. Unions raw, current, and resolved event states with FHIR resource references, review status, and domain classification. |
| Data Source and Model Health Fact | Connector health, event throughput, and metric freshness observations. Provides a unified view of ingestion recency, event volume, and metric computation timestamps. |
| Metric Output | Existing metric values and freshness normalized for downstream consumers. Joins metric values with freshness metadata to expose computation timestamps, period boundaries, and value fields in a single row. |
Each model includes a canonicalization timestamp indicating when the projection was last materialized. Models that join multiple sources use full or left joins to preserve rows even when one source lacks a matching record.
### Design Principles
* **Environment-independent logic.** Source table references are resolved from configuration at runtime. The same transformation code runs across staging, production, and other catalog environments without modification.
* **Union-then-join structure.** Models that combine multiple source streams first union rows from the same grain, then join across grains. This keeps the transformation predictable and avoids fan-out.
* **Coalesce-based fallbacks.** When a preferred field may be null, models fall back to alternative fields using ordered preference. For example, display names prefer an explicit display name over a raw name, and timestamps prefer the most specific available timestamp.
* **Workspace scoping.** Every canonical model is keyed by workspace, ensuring tenant isolation in all downstream queries.
The metric store provides one value model for operational, quality, and evaluation metrics. Values carry a metric key, type, source class, scope identifiers, period, event count, optional confidence, unit, and computation time.
The active Platform API catalog contains 41 built-in definitions across six categories. A catalog entry describes a metric the platform knows how to represent; it does not guarantee that every workspace or interaction will produce a value for that key.
{% hint style="info" %}
Metric values distinguish **production** and **simulation** sources and **aggregate** and **entity** scopes. Simulations compute only the metrics selected by their evaluation configuration; they do not automatically produce all active workspace metrics.
{% endhint %}
## How Values Become Available
Metric values can arrive through different paths:
1. The platform loads active built-in definitions and supported workspace custom definitions.
2. Eligible call-intelligence, surface, world-event, voice-quality, production-eval, or simulation-eval evidence is evaluated or aggregated.
3. Recent per-interaction values can become available through a low-latency projection, while scheduled analytical processing produces aggregate and AI-evaluated history.
4. The metric API combines recent values with durable history. Dashboard panels query durable analytical views.
These paths can have different freshness. A definition update takes effect when the applicable execution path next processes eligible evidence. It does not promise atomic historical replacement, immediate recomputation, or backfill of earlier interactions.
## Developer Console
The Developer Console **Quality** page currently includes:
* The built-in **Realtime Metric Store** dashboard.
* A production-eval quality panel.
* Latest values and editable custom evaluation metrics.
* The 41 built-in definitions, with an active or inactive toggle.
The Console's custom-metric form creates conversation-summary `ai_query` definitions using the fast, balanced, or max model tier. The settings API exposes a broader definition schema than this form.
Built-in definitions are read-only in the Console except for activation. Through the API, accepted built-in override fields are limited to activation, freshness target, hourly or daily period granularity, and numerical valid-range bounds. Built-in keys, types, sources, and extraction behavior are platform-owned.
The settings response merges saved overrides into the built-in definitions, and the low-latency call projection reads the active workspace settings. The scheduled built-in aggregate pipeline remains code-defined, and the catalog endpoint returns the platform base catalog rather than saved built-in overrides. A toggle therefore does not delete history or guarantee that every scheduled aggregate stops being produced.
### Realtime Metric Store Dashboard
The `metrics-overview` template refreshes every five minutes by default and contains:
* **Metric store summary** - active metric count, numerical metric count, value points, scored events, average confidence, and latest computation.
* **Average metric scores** - numerical metric averages.
* **Daily scored events** - daily event volume, active metric count, and value points.
* **Production versus simulation scores** - numerical values grouped by source.
* **Categorical distribution** - event counts for categorical values.
* **Entity-level coverage** - distinct entities and value counts by metric.
* **Metric freshness** - last computation, latest covered period, value count, and observed minutes stale.
* **Per-call metric scores** - recent entity-scoped values with source and period.
Dashboard filters cover time window, source, aggregate or entity scope, and metric type. A panel can be empty when its source has not produced values or the analytical query path is unavailable.
## Built-In Catalog
The 41 built-ins are grouped as follows:
| Category | Count | Evidence |
| ------------------------ | ----: | ----------------------------------------- |
| Voice intelligence | 10 | Call-intelligence fields |
| Surface intelligence | 5 | Surface lifecycle evidence |
| Data quality | 3 | World-event fields |
| Cross-channel | 2 | Call outcome and surface lifecycle events |
| Standard quality | 11 | AI evaluation of conversation summaries |
| Voice quality evaluation | 10 | Audio-native Voice Judge results |
### Voice Intelligence
| Metric | Type | What It Measures |
| --------------------------- | ----------- | -------------------------------------------------------------------------------------------------------------------------------- |
| **Voice quality score** | Numerical | Average composite call-quality score from 0 to 100 |
| **Voice duration** | Numerical | Average call duration in seconds |
| **Voice escalation** | Numerical | Fraction of calls marked as escalated |
| **Voice completion reason** | Categorical | Counts by canonical terminal reason |
| **Voice risk level** | Categorical | Compatibility key. The current voice producer leaves the source field empty, so it does not provide a current risk distribution. |
| **Voice average TTFB** | Numerical | Average audio time-to-first-byte in milliseconds |
| **Voice tool failure rate** | Numerical | Average fraction of failed tool calls |
| **Voice barge-in count** | Numerical | Average caller interruptions per call |
| **Voice loop count** | Numerical | Average context-graph state revisits per call |
| **Voice silence ratio** | Numerical | Average fraction of call duration classified as silence |
These metrics use hourly periods and a near-realtime latency classification. They require a terminal call-intelligence artifact and the relevant source field. Missing source evidence produces no meaningful value; it should not be interpreted as zero.
### Surface Intelligence
| Metric | Type | What It Measures |
| ---------------------------- | ----------- | ---------------------------------------------------------- |
| **Surface completion rate** | Numerical | Submitted surfaces divided by created surfaces |
| **Surface open rate** | Numerical | Opened surfaces divided by delivered surfaces |
| **Surface abandonment rate** | Numerical | Opened surfaces not submitted, relative to opened surfaces |
| **Surface channel** | Categorical | Counts by observed delivery channel |
| **Surface time to complete** | Numerical | Average hours from creation to submission |
Surface metrics depend on the corresponding lifecycle events. Missing delivery or open events affect the available denominator and should be considered when comparing channels.
### Data Quality
| Metric | Type | What It Measures |
| --------------------------- | --------- | ---------------------------------------------------------- |
| **Average data confidence** | Numerical | Average confidence on eligible current world events |
| **Event volume** | Numerical | Count of eligible current world events |
| **Review approval rate** | Numerical | Compatibility definition for earlier event-review statuses |
The review-approval key has no active producer for the current external-write review workflow. Do not use it for present-day governance reporting. External write proposal decisions have a separate lifecycle.
### Cross-Channel
| Metric | Type | What It Measures |
| ------------------------- | --------- | -------------------------------------------------------------------------- |
| **Patient contact count** | Numerical | Eligible call-outcome and surface-delivery contacts |
| **Patient response rate** | Numerical | Eligible call outcomes and submitted surfaces relative to tracked contacts |
These definitions cover the event families named above. They are not a universal count of every message or contact channel.
### Standard Quality
Five definitions apply to every eligible service. Six outcome definitions apply only when the service carries the corresponding product-type tag.
| Metric | Type | Scope | What It Evaluates |
| ------------------------------ | --------------- | --------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Patient sentiment** | Categorical | All eligible services | The patient's apparent attitude toward the interaction: positive, neutral, or negative |
| **Conversational naturalness** | Numerical, 1-10 | All eligible services | Scriptedness, recovery, empathy, pacing, turn-taking, and related conversational qualities |
| **Conciseness** | Numerical, 1-10 | All eligible services | Whether responses were appropriately brief without penalizing necessary detail |
| **Information accuracy** | Boolean or null | All eligible services | Whether agent claims match tool responses. It does not verify that the tool data itself was correct. Null means there were no tool calls to compare. |
| **Safety** | Categorical | All eligible services | `no_event`, `handled`, `warning`, or `critical` according to the evaluation rubric |
| **Scheduling outcome** | Categorical | Scheduling | `escalated`, `resolved`, or `no_action` |
| **Outbound outcome** | Categorical | Outbound | `escalated`, `resolved`, `opted_out`, `no_action`, or `no_answer` |
| **Coaching outcome** | Categorical | Coaching | `escalated`, `resolved`, or `no_action` |
| **Intake outcome** | Categorical | Intake | `escalated`, `resolved`, or `no_action` |
| **Triage outcome** | Categorical | Triage | `escalated`, `resolved`, or `no_action` |
| **Support outcome** | Categorical | Support | `escalated`, `resolved`, or `no_action` |
Standard quality metrics use batch AI evaluation over eligible call-intelligence summaries. Their output is non-deterministic, can be incomplete, and does not replace authoritative record retrieval or human review.
### Voice Quality Evaluation
Ten daily metrics aggregate the [Voice Judge](/intelligence-and-analytics/intelligence/call-intelligence#voice-judge) dimensions: latency and dead air, pronunciation, clarity, filler and silence, interruption handling, audio consistency, pacing, warmth and tone, accent quality, and voice identity. Values range from `0.0` to `1.0`.
These metrics require a usable recording and a completed Voice Judge result. Recording or analysis failures can leave a call without these values.
## Custom Metrics
The settings API accepts up to 50 custom definitions per workspace. Custom keys cannot reuse built-in keys, and custom definitions cannot claim built-in status.
### Paved Console Workflow
The Console currently creates AI-query evaluation metrics against conversation summaries. Authors provide a name, rubric, result type, optional categories, and model tier. The transcript or conversation summary is supplied by the evaluation path.
This is a model-based judge, not a deterministic rule engine. Test new rubrics against representative conversations and calibrate them with human reviewers before using the results for deployment or safety decisions.
### API Extraction Modes
The definition schema contains five extraction modes, but their execution boundaries differ:
| Mode | Current Boundary |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **`static`** | Reads a configured JSON path from matching world events. The current custom static aggregate path is suited to numerical values. |
| **`ai_classify`** | Classifies selected event content into configured labels. Labels are required by the current execution path. |
| **`ai_extract`** | Extracts configured fields from event content. The current execution path requires labels. |
| **`ai_query`** | Runs a rubric against a call-intelligence summary or matching world-event data using an allowed managed tier or explicitly permitted custom model configuration. |
| **`sql_expr`** | Reserved for platform definitions. The settings API rejects it for custom metrics. |
The API accepts numerical, categorical, and boolean metric types. Not every type, aggregation, and extraction-mode combination has an active executor. Prefer the Console's AI-query workflow or a combination explicitly verified in the current API and pipeline before deploying a custom definition.
### Model Tiers
| Tier | Current Use |
| ------------ | ------------------------------------------------------------------------------------------------------ |
| **Free** | Platform-managed classification and extraction modes; it is not valid for `ai_query` |
| **Fast** | Managed AI-query tier for simpler evaluations |
| **Balanced** | Managed AI-query tier used by the built-in standard quality judges |
| **Max** | Managed AI-query tier for more complex evaluation |
| **Custom** | API-only custom model configuration when explicitly permitted; not exposed by the current Console form |
Tier names describe routing and intended complexity. They are not a latency, accuracy, or cost guarantee.
### Source and Channel Scoping
Custom definitions accept matching event types and a channel scope of `all`, `voice`, `text`, `surface`, `inbound`, or `outbound`. `ai_query` treats `call_intelligence` as a conversation-summary source and other supported configurations as world-event evaluation.
Current scheduled custom execution does not apply every channel-scope value consistently: the static custom path does not apply the field, AI event paths handle voice, text, and surface, and inbound or outbound scoping is not implemented across those paths. Use narrow event types as the reliable filter and verify the current executor before relying on channel scope. A broad wildcard can evaluate unrelated events, increase cost, and produce values that are difficult to interpret.
### No Generic Preview Endpoint
The Platform API does not currently expose a generic, non-persisting **evaluate metric** endpoint. The embedded [production-eval operation](https://docs.amigo.ai/developer-guide/platform-api/safety/production-evals#evaluating-a-call) runs the workspace's active eval definitions for one completed conversation and persists the verdicts. It is not an inline preview of an arbitrary metric definition.
## Processing and Freshness
### Latency Classification
| Tier | Intended Processing Class |
| ----------------- | ------------------------------------------------------------- |
| **Streaming** | A producer and projection capable of seconds-level processing |
| **Near realtime** | Triggered or low-latency processing measured in minutes |
| **Batch** | Scheduled processing, typically hourly or daily |
`latency_tier` is definition metadata and processing intent. It does not itself create a streaming producer, runtime alert, or contractual delivery time.
### Period Granularity
Definitions support hourly or daily periods. Built-in voice operational metrics use hourly periods. Standard quality and Voice Judge metrics use daily periods. Changing the setting affects future applicable processing; it does not guarantee an immediate rewrite of existing history.
### Freshness Target
`freshness_sla_minutes` accepts values from 5 minutes to 24 hours and defaults to 60 minutes. It is a configured staleness target, not an externally enforced SLA.
The Realtime Metric Store dashboard shows observed computation freshness from its analytical freshness view. There is no dedicated public metric-freshness endpoint in the current Platform API.
## Query Surface
The public metric routes provide four reads:
| Read | Current Behavior |
| ---------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **List metric values** | Latest values by default, or history with `latest_only=false`; supports source, scope, entity, service, run, session, date, limit, and offset filters |
| **Get one metric** | Values for a metric key with source, scope, entity, service, run, session, and date filters |
| **Metric trend** | Up to 365 days for one metric key with the same scope filters |
| **Metric catalog** | Active built-ins plus active custom definitions, including type, source, extraction mode, value granularity, period granularity, latency tier, model tier, unit, prompt presence, and built-in status |
`GET` and `PUT` on metric settings manage the complete definitions list. Reads require authenticated workspace access; updates require admin or owner permission. The list is replaced when supplied, while built-ins are merged back with only supported overrides.
A historical call route also returns recent per-call metric values for call detail. Use the unified Runs surface as the canonical interaction inventory, and use the general metric filters for run- and session-scoped analysis.
### Missing and Delayed Values
Preserve these distinctions in downstream reporting:
* A configured metric with no value can mean no eligible source evidence, pending processing, a failed evaluator, or an unavailable analytical dependency.
* Numerical `0`, boolean `false`, categorical values, and null are different outcomes.
* Recent API values can appear before the durable dashboard view catches up.
* Production and simulation values are separate source classes and should not be combined unless the analysis explicitly requests `all`.
* Per-entity values should not be treated as workspace aggregates without an explicit aggregation step.
## Production Evals and Metric Values
Production eval definitions and metric definitions are related but distinct. A production eval can reference an active AI-query metric and persist both an eval verdict and a metric value for the evaluated conversation. Assertion evals have their own verdict semantics.
Automatic eager evaluation is best-effort and feature-dependent. It can be skipped when disabled, when the conversation lacks a durable identifier, when capacity controls apply, or when an evaluator fails. Manual call evaluation persists results. Simulation runs evaluate only definitions captured and selected in the run configuration.
See [Metrics and Quality](/testing/testing/metrics) for simulation assertions, score interpretation, and deployment-gate guidance.
## Billing Meters Are Separate
Billing metering is a separate pipeline and API surface from the metric store. Its default lifecycle catalog currently includes:
| Meter | Unit | Current Evidence |
| ---------------------- | -------------- | --------------------------------------------------------------- |
| Voice minutes | minutes | Reported voice-call duration |
| Call count | calls | Voice-call events |
| LLM input tokens | tokens | Emitted model-usage records |
| LLM output tokens | tokens | Emitted model-usage records |
| SMS messages | messages | SMS message events |
| Call recording minutes | minutes | Reported recording duration |
| Completed calls | calls | Selected completed call-intelligence outcomes |
| Quality-weighted calls | quality points | Quality scores for those selected completed outcomes |
| Surface submissions | submissions | Submitted surface events |
| Message count | messages | Recorded agent engage-message events |
| Action count | actions | Reported tool counts on eligible voice and companion executions |
| Conversation count | conversations | Eligible call-session and companion-execution events |
Meter rows are partitioned by production or simulation source when the emitter supplies that classification. The metering emit API can also introduce authorized custom meter keys. Meter projection is asynchronous, so an accepted emission is not proof that a billing rollup or invoice already contains it.
{% hint style="info" %}
**Developer Guide** - For the current metric routes, settings schema, filters, and production-eval distinction, see the [Metric Store developer guide](https://docs.amigo.ai/developer-guide/platform-api/safety/metric-store).
{% endhint %}
# Cost to Serve
Workspace-level cost-to-serve visibility covering LLM inference and infrastructure, sourced from the monthly cost-allocation close.
The platform exposes workspace-level cost-to-serve data so Amigo staff can understand what it costs to operate each workspace. Two separate views cover distinct cost domains, each with its own accuracy characteristics.
## LLM Inference Cost
LLM inference cost uses recorded workspace token usage and the rate-card tier effective on each usage date. It is a calculated cost, whose completeness depends on emitted usage, cache counters, and pricing coverage. It does not establish the amount invoiced by a provider or owed by a customer.
Each model used by the workspace is reported individually with:
* Input, output, and cached token counts.
* Dollar cost, when the applicable rate-card entries and required usage counters are available.
* A pricing status flag. Usage that cannot be priced remains visible with token counts and a null cost. The response-level total excludes unpriced usage and flags that the total may understate actual spend.
Review unpriced usage before relying on the total for a cost comparison.
## Infrastructure Cost
Infrastructure cost represents the workspace's usage-weighted share of pooled compute and storage. Components include pipelines, model serving, warehouse, storage, and related resources.
Shared-resource figures depend on the allocation method and available usage weights. Review those assumptions separately from the token-metering and pricing coverage used for inference cost.
Each component reports:
* The infrastructure component category.
* How the cost was determined: a usage-weighted share of a pooled resource, or spend tagged directly to the workspace.
* The dollar amount for the month.
Components with no spend in a given month are omitted rather than shown as zero.
## Data Source and Availability
Both views are sourced from a monthly cost-allocation close that reconciles the full vendor bill to zero residual. Data is available after the close job completes, typically within a few days of month end. Only closed months can be queried.
Account-level overhead that cannot be attributed to any single workspace is excluded at the data layer and never appears in workspace-level results.
## Access Restrictions
Cost-to-serve data is restricted to Amigo staff. Workspace administrators - even those with full admin permissions - cannot access these endpoints. This is deliberate: the data represents Amigo's cost structure and margins, not the customer's bill or contracted price.
Authentication requires an Amigo identity credential. API-key-authenticated callers are rejected because API keys do not carry the identity information needed for staff verification.
## Relationship to Other Analytics
Cost-to-serve is separate from the workspace analytics and metric store surfaces. It is not available as an agent-reachable tool or through data access integrations. The data serves internal operational visibility, not customer-facing reporting.
For the separately restricted staff interface, see [Cost to Serve](https://docs.amigo.ai/developer-guide/platform-api/platform-api/cost-to-serve) in the Developer Guide. For customer-facing operational reporting, see [Analytics and Dashboards](/intelligence-and-analytics/intelligence/analytics-dashboards).
# Healthcare Overview
Healthcare workflow patterns showing how agents, data, channels, testing, and external integrations can be composed.
These guides apply Amigo's data, agent, channel, and operational capabilities to healthcare workflows. Each scenario identifies work that can be configured, the external systems it depends on, and the evidence needed to evaluate the result.
Voice, text, and messaging workflows can reuse compatible agent and Context Graph definitions and selected world-model context. Their runtimes, delivery rules, and operator controls differ. A workflow that combines a phone call, a form, and a reminder needs explicit routing and verification at each step. See [Reasoning Engine](/agent/reasoning-engine) for execution behavior and [Channels](/channels/conversations) for transport differences.
## Use a Scenario as a Design Exercise
For each scenario, identify the operational outcome, source data, allowed actions, confirmation evidence, and exception owner. Then map those needs to the platform components introduced in [Core Concepts](/platform-overview/core-concepts). The [end-to-end example](/platform-overview/how-it-works) shows the method for an appointment change.
Keep the workflow's business result separate from its conversation metrics. A recorded referral request, a delivered reminder, and a completed visit are different outcomes with different sources of evidence.
## Scenarios
Each guide walks through a healthcare workflow pattern. Some steps require customer-authored automation, configured external systems, or explicitly labeled sample-data previews; treat the guides as design patterns rather than proof that every capability is enabled in every workspace.
| Use Case | What It Covers | Primary Channel |
| ------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- | ---------------------- |
| [Patient Scheduling and Outreach](/use-cases/use-cases/scheduling-outreach) | Inbound scheduling, outbound appointment campaigns, insurance capture, gap closure | Voice + SMS |
| [Care Coordination](/use-cases/use-cases/care-coordination) | Multi-encounter follow-up, cross-session memory, personalized interactions, adherence tracking | Voice + SMS |
| [Clinical Verification](/use-cases/use-cases/clinical-verification) | Safety testing frameworks, simulation-based validation, metric design, human review processes | Testing + evaluation |
| [Population Health and Risk Management](/use-cases/use-cases/population-health) | Risk stratification, prediction, evidence-based outreach across clinical indications using clinical and sociodemographic data | Voice + SMS + Surfaces |
| [Healthcare Contact Center](/use-cases/use-cases/contact-center) | Conversational routing, quality evidence, call intelligence, operator workflows, and integration boundaries | Voice |
## Channel Selection
The guides target Platform API concepts. Channel support and external delivery still depend on workspace provisioning, service configuration, consent, and the selected runtime:
* **Scheduling, outreach, care coordination, contact center** - Phone and SMS workflows using the voice pipeline, world model, EHR connectors, and operator escalation.
* **Patient-facing chat, digital health coaching, in-app messaging** - Text sessions through the Platform API's text channel with the same memory system, context graphs, and world model integration.
* **Multi-channel deployments** - Compatible agent and Context Graph versions can be reused across supported channels, with channel-specific configuration and testing. [Agent Forge](/reference/agent-forge) manages the supported Platform configuration resources.
# Patient Scheduling and Outreach
End-to-end patient scheduling and outbound outreach workflow, from clinical data loading through interaction completion and policy-gated external updates.
This guide walks through a common healthcare workflow: an AI agent handles appointment scheduling and outbound patient outreach across voice and text channels, from data ingestion through interaction completion and configured external updates.
## The Workflow
A health system needs to contact patients who are due for follow-up appointments. Today, care coordinators manually review lists, make calls, navigate scheduling systems, and document outcomes. The process is time-consuming, and many patients never get contacted.
With Amigo, teams can automate selected parts of this workflow while keeping clinical standards, consent, external-system confirmation, and exception handling explicit.
## Step-by-Step Flow
### 1. Connector Runner Loads Patient Data
A configured connector can ingest supported patient data from an EHR or another source system. A separate query, trigger, or customer workflow identifies patients who are due for follow-up based on criteria such as time since last visit, care-plan milestones, or provider orders.
An example workflow may ingest or retrieve:
* Demographics and contact preferences
* Relevant clinical context (reason for follow-up, last visit summary)
* Scheduling constraints (provider availability, location preferences)
* Prior interaction history with the platform
Source records must carry a stable patient association or be reconciled through a supported customer workflow. The active pipeline does not create new cross-source `same_as` merges, so do not rely on automatic identity matching across unrelated systems.
### 2. Outbound Dispatch Initiates Contact
An explicit workflow can start an outbound SMS or iMessage conversation, place a direct voice call, or create a scheduled outbound voice task. Scheduled voice tasks support a business-hours window, timezone, priority, attempt limit, and retry backoff. The platform does not automatically choose a channel or fall back from an unanswered call to SMS or voicemail; configure those decisions in a Context Graph, trigger, or external workflow.
### 3. Agent Greets the Patient
When the patient answers a call or receives the first text message, the agent introduces itself and states the purpose of the interaction. If identity resolution and authorized context are available, the greeting can use that context without disclosing unverified identity information.
For example, the agent might say: "Hello, this is the follow-up team at City Medical Center. I am calling because Dr. Patel asked us to check in with you after your visit last week and help you get your next appointment scheduled."
The agent version, channel configuration, and authored guidance shape tone, pacing, and vocabulary. Do not infer communication needs from age alone; use explicit preferences, accessibility needs, and tested workflow guidance.
### 4. Agent Reads Context from the World Model
During the conversation, authorized tools can retrieve relevant projected information. Projection and tool latency vary, so the workflow must handle missing or stale context:
* **Appointment context**: What type of follow-up is needed, how soon, and with which provider
* **Patient history**: Prior no-shows, scheduling preferences, transportation barriers
* **Clinical notes**: Any instructions from the care team about urgency or special requirements
This context can support a more relevant conversation. If the patient says "I had trouble getting there last time," an authored workflow can consult current transportation options or record the new barrier rather than assume an earlier observation is still correct.
### 5. Agent Uses a Scheduling Integration
Once the patient agrees to schedule, an eligible scheduling tool can query current availability from the configured integration. The agent can present returned options and apply supported filters such as provider, location, appointment type, or time window. If no option satisfies the request, it should explain the returned alternatives or use the authored fallback rather than invent availability.
The workflow can incorporate scheduling constraints such as:
* Multiple providers or locations
* Insurance verification requirements
* Pre-appointment instructions (fasting, medication holds)
* Follow-up reminders and confirmation preferences
When the patient selects a slot, the agent requests the booking through the configured scheduling tool and confirms it only when the tool result supports that claim.
### 6. Outcomes and External Updates
During or after the interaction, supported tools can record structured outcome events in the world model. Depending on the tool and destination policy, eligible payloads can be delivered to a configured scheduling or clinical system. Outcome data may include:
* Interaction outcome (scheduled, declined, no answer, callback requested)
* Appointment details if scheduled
* Any patient concerns raised during the conversation
* Escalation notes if the patient reported symptoms or issues requiring clinical attention
Recording an outcome event does not itself prove that an external system accepted it. Connector delivery reports its own result, and care coordinators can use destination records or supported read-back evidence when confirmation matters.
## Handling Edge Cases
The agent and Context Graph should define boundaries for situations that require human involvement:
* **Patient reports new symptoms**: The workflow should prohibit unsupported clinical advice, record the concern when permitted, and use the authored care-team escalation path.
* **Patient requests a provider change**: The agent can offer available alternatives but escalates complex situations (such as insurance or referral issues) to a coordinator.
* **Patient expresses distress or confusion**: The agent adjusts its approach and, if needed, offers to connect the patient with a live staff member.
* **Language barriers**: The workflow uses the configured language capability and an authored fallback or transfer path when the interaction cannot be supported safely.
## What This Looks Like in Production
At scale, this pattern can increase routine outreach capacity when channel delivery, scheduling integrations, and exception handling perform as expected. Care coordinators can then focus on interactions that need complex coordination or clinical judgment, while retaining a fallback for automation failures.
Teams can define metrics over recorded outcomes, such as scheduling rates and escalation frequency. No-show comparison requires a reliable join to later appointment outcomes from the authoritative scheduling system. Use equivalent definitions and populations when comparing simulation and production, and investigate modality or evidence differences before drawing conclusions.
# Care Coordination
Multi-encounter care coordination with cross-session memory, world model data unification, and personalized patient interactions.
This guide covers how Amigo supports ongoing care coordination across multiple patient encounters. Unlike a single scheduling interaction, care coordination involves repeated touchpoints over weeks or months across voice and text channels, with the agent building context over time and personalizing each interaction.
## The Challenge
Patients with chronic conditions or complex care plans interact with the health system frequently. Each interaction generates information that should inform the next one. In practice, this context is often lost: different staff members handle different calls, notes are incomplete, and patients have to repeat themselves.
Effective care coordination requires continuity. The agent must remember what happened in prior conversations - whether they occurred over phone or text - track progress against care plan goals, and adapt its approach based on what has worked (or not worked) for each patient.
## Memory Across Encounters
Amigo's [memory system](/agent/memory) can turn completed conversation evidence into source-linked episodic observations and a consolidated user model for later sessions. Connected clinical records also contribute a separate deterministic clinical-state summary. Processing is asynchronous and generated memory is not guaranteed to capture every detail, so current clinical and scheduling facts still come from authoritative data tools.
**Context available across encounters:**
* Generated episodic observations can carry forward patient-reported barriers, preferences, and prior interaction context when memory processing succeeds.
* The bounded semantic user model can consolidate longer-lived goals, trajectories, and interaction preferences without becoming an authoritative clinical record.
* Connector-derived clinical state separately supplies current conditions, medications, and allergies with its own provenance.
* Scheduling, escalation, and care-team facts should come from current world-model records and authoritative tools rather than generated memory alone.
**How memory improves coordination:**
On a first call, the agent may follow a standard check-in flow. In later sessions, available memory can help it recognize that a patient prefers morning calls or wants concise explanations. Current medication and scheduling facts still come from connected records, and configured workflows decide timing and reminders.
Over longer time horizons, teams can analyze source-linked observations and explicit outcomes for patterns that are not visible in any single interaction. A suspected medication-adherence cycle, for example, should be validated against current records before it changes outreach or agent guidance.
## World Model Unifies Data Sources
The world model projects supported information from multiple systems into entity views that authorized agents and tools can access during a conversation.
| Data Source | What It Provides |
| ------------------- | ------------------------------------------------ |
| EHR | Diagnoses, medications, lab results, care plan |
| Voice conversations | Patient-reported symptoms, concerns, preferences |
| Manual entry | Care team notes, social work assessments |
| Scheduling system | Appointment history, upcoming visits |
| Connected devices | Vitals, weight trends, activity data |
When an authorized tool exposes a current fact, the workflow can avoid asking the patient to repeat it. For example, a configured device-data integration could expose a weight trend for an authored care-coordination step. Projection freshness and source authority still need to be checked before the agent treats the value as current.
This can expose conflicting information rather than hiding it. If the EHR shows a medication was discontinued but the patient mentions still taking it, the agent can preserve both sources and follow the authored escalation or verification workflow.
## Personalized Interactions
Each interaction is shaped by what the platform knows about the patient. Personalization happens across several dimensions:
**Communication style**: Some patients want detailed explanations. Others want brief, direct updates. When generated memory captures a supported preference, the agent can use it while remaining prepared for that preference to be incomplete or outdated.
**Timing and cadence**: Configured triggers and scheduling rules can use known preferences and prior outcomes. A team might move a patient who consistently misses afternoon calls to a morning outreach window.
**Content focus**: Authored state guidance and current tool results can prioritize topics relevant to the patient's situation. A medication change or care milestone should influence the conversation only when the workflow has current, authorized evidence for it.
**Barrier awareness**: Available patient-reported context can inform authored recommendations or referral options. Consequential facts should be verified when they may have changed.
## Operator Escalation
Not every situation is within the agent's scope. Authored context-graph instructions define when the agent should escalate to a human operator.
**When the agent escalates:**
* Patient reports new or worsening symptoms that require clinical assessment
* The patient's situation has changed significantly since the last care team update (new diagnosis, hospitalization, family crisis)
* The patient explicitly requests to speak with a nurse or provider
* The agent reaches an authored uncertainty or scope boundary
**How escalation works:**
Depending on the channel, retained evidence, and configured context, the selected run can give the operator information such as:
* Current conversation context and patient concern
* Relevant history from prior interactions
* Selected world-model or tool context made available to that operator workflow
* Reason for escalation
For voice, the operator can review available context before joining or taking over the live call. The handoff should not be treated as a guaranteed full clinical briefing; teams should keep authoritative records accessible and record the resolution through the configured workflow.
## What This Looks Like Over Time
In a care coordination deployment, the agent handles routine touchpoints (medication check-ins, appointment reminders, care plan reinforcement) while care managers focus on patients who need clinical judgment.
As supported interaction history accumulates, later calls can use available memory and current world-model context for continuity. Teams should measure whether that personalization improves explicit outcomes, such as adherence or missed appointments, rather than assume improvement from history alone.
{% hint style="info" %}
For details on how to verify clinical quality in care coordination workflows, see the [Clinical Verification](/use-cases/use-cases/clinical-verification) guide. For the memory system's layered architecture, see [Memory](/agent/memory).
{% endhint %}
# Clinical Verification
Build clinical-safety evidence with representative simulations, customer-owned release criteria, and qualified human review.
Before an AI agent interacts with patients, teams need evidence that its configured behavior is appropriate for the intended clinical scenarios and operating boundaries. This guide covers how to use Amigo's testing framework alongside organizational release criteria and qualified human review. No finite test set proves that a model will behave correctly on every future interaction.
{% hint style="warning" %}
Simulation scores and model-graded metrics are evidence, not clinical validation, regulatory approval, or a substitute for review by qualified clinical and compliance owners.
{% endhint %}
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
S["Simulate\n(clinical scenarios)"] --> G["Gate\n(safety metrics)"]
G --> R["Review\n(human judgment)"]
R --> D["Deploy\n(phased rollout)"]
D --> M["Monitor\n(metrics + drift)"]
M -->|New edge cases| S
```
## Why Clinical Verification Matters
Healthcare AI operates under constraints that most other domains do not have. A missed safety escalation can harm a patient. A scope-of-practice violation can create liability. A subtle bias in how the agent handles certain populations can produce inequitable care.
Generic testing is not sufficient. You need to test against your specific clinical workflows, patient populations, and safety standards. A model that scores well on general medical knowledge benchmarks may still fail to follow your organization's escalation protocols correctly.
## Simulation with Medical Scenarios
Build simulations that reflect the clinical situations your agent will encounter. Start with your highest-risk workflows and expand from there.
### Designing Clinical Personas
Clinical personas should represent the diversity of your patient population, including the patients who are hardest to serve well:
* **Complex medication regimens**: Patients on multiple medications where interaction detection is critical
* **Cognitive limitations**: Elderly patients or those with cognitive impairment who may provide unreliable information
* **Communication barriers**: Patients with limited health literacy, non-native speakers, or patients who minimize symptoms
* **High acuity**: Patients presenting with symptoms that require urgent escalation
Each persona exercises a specific capability. A persona with cognitive impairment can probe whether the agent notices confusion and follows the authored communication policy. A persona who downplays symptoms can exercise the organization's clarifying-question and escalation criteria.
### Building Clinical Scenarios
Pair personas with scenarios that test the boundaries of safe agent behavior:
* **Routine follow-up that reveals a problem**: A standard post-discharge check-in where the patient casually mentions a new symptom that requires escalation
* **Conflicting information**: The patient's self-report contradicts EHR data, and the agent must handle the discrepancy appropriately
* **Scope boundary**: The patient asks a question that falls outside the agent's defined scope of practice
* **Emotional distress**: The patient becomes upset, anxious, or frustrated during a clinical interaction
{% hint style="warning" %}
Do not only test happy paths. The scenarios that matter most for clinical safety are the ones where things go sideways: the patient who lies about taking their medication, the patient whose symptoms escalate mid-conversation, or the patient who insists on advice the agent should not give.
{% endhint %}
## Metric-Based Quality Gates
Define metrics that your release process treats as required checks. The platform records evaluation evidence, but it does not automatically block a version-set update or make the release decision.
### Safety Metrics (Hard Gates)
The values below are illustrative policy targets, not platform guarantees or claims that a finite evaluation set proves future behavior.
| Example Metric | Example Target | Notes |
| ---------------------------- | -------------- | ------------------------------------------------------------------- |
| Escalation accuracy | 100% | Agent correctly identifies situations requiring clinical escalation |
| Scope-of-practice adherence | 100% | No observed out-of-scope advice in the evaluated set |
| Privacy protocol compliance | 100% | No observed violation of the tested PHI-handling requirements |
| Medical information accuracy | 99.5%+ | Factual correctness of clinical information provided |
| Risk disclosure completeness | 99%+ | Agent discloses relevant risks when appropriate |
Set these thresholds with the clinical, compliance, and operational owners for the workflow. If a required check fails, keep the release out of production through your team's explicit review and promotion process.
### Quality Metrics (Improvement Targets)
| Example Metric | Example Target | Notes |
| --------------------- | -------------- | ------------------------------------------------------------ |
| Explanation clarity | 90%+ | Information presented in language appropriate to the patient |
| Empathy score | 85%+ | Agent demonstrates appropriate emotional support |
| Response completeness | 90%+ | Agent fully addresses the patient's question or concern |
| Goal completion | 85%+ | Agent accomplishes the intended purpose of the interaction |
Improvement targets guide prioritization rather than making the release decision. A configuration that meets the organization's required checks but falls slightly below an empathy target may still be appropriate to release while improvement work continues.
## Human Review Workflows
Automated metrics do not catch everything. Human review adds independent clinical judgment and context that a model-based evaluator may miss.
### When to Use Human Review
* **Initial deployment**: Have clinical staff review a meaningful sample of conversations before and during early production use.
* **After configuration changes**: Review conversations from the first few days after any update to agent instructions, Context Graphs, tools, or model configuration.
* **Selected conversations**: Use run filters, metric results, recordings, and transcripts to identify borderline or representative cases for human review.
* **Ongoing sampling**: Regularly review a random sample of production conversations to catch issues that metrics and drift detection may miss.
### Structuring Reviews
Provide reviewers with clear rubrics aligned to your metrics. Reviewers should assess:
* Did the agent stay within its scope of practice?
* Were escalation decisions appropriate?
* Was the clinical information accurate and complete?
* Was the communication appropriate for the patient's situation?
* Were there any missed opportunities or concerns?
Compare human review scores against automated metric scores. If they diverge, investigate the rubric, evidence, sampling, and reviewer calibration before changing the metric or release criteria.
## Putting It Together
Clinical verification is not a one-time event. It is an ongoing process that runs in parallel with deployment:
1. **Before deployment**: Run clinical simulation suites, compare results with your required criteria, complete initial human review, and make an explicit release decision.
2. **During early deployment**: Monitor metrics daily. Select representative and concerning conversations for review. Expand simulation coverage based on production patterns.
3. **In steady state**: Track metrics across cohorts. Detect drift. Update simulations when clinical workflows or guidelines change. Maintain ongoing human review sampling.
{% hint style="info" %}
For detailed guidance on phased deployment with quality gates at each stage, see [Simulations](/testing/testing/simulations). For the testing framework details, see [Testing and Evaluation](/testing/testing).
{% endhint %}
# Population Health
A configuration pattern for population outreach, plus the boundaries of the synthetic Sensorium population-health demo.
This guide describes how teams can compose ingestion, customer-defined risk logic, explicit outreach workflows, and agent conversations for population-health use cases. It closes with the Developer Console's Sensorium demo, which uses synthetic, hand-seeded or pipeline-generated sample data and is not connected to live patient or workspace metrics.
{% hint style="warning" %}
Risk scores, forecasts, intervention effects, and policy recommendations require customer validation and appropriate clinical governance. The Platform API does not turn a model output into a validated clinical decision or automatically enroll a population in outreach.
{% endhint %}
## The Challenge
Health systems sitting on large volumes of clinical and sociodemographic data face a common problem: the data exists, but it does not drive action. Risk models run in analytics platforms that are disconnected from patient communication. Stratification scores sit in dashboards that care coordinators check manually. Evidence-based guidelines live in PDFs and clinical protocols that staff apply inconsistently.
The gap is not data or knowledge. It is execution: turning a risk score into a patient conversation, turning a guideline into a recommendation delivered at the right moment, doing this across thousands of patients without scaling staff linearly.
Amigo provides data, function, trigger, outbound, and conversation primitives that a team can connect into this workflow. Eligibility, risk computation, consent, intervention policy, and outcome validation remain explicit configuration or customer-owned logic.
## Data Foundation
Population health starts with data. The platform needs a unified view of each patient that spans clinical records, sociodemographic context, and interaction history.
### Clinical Data Ingestion
The [connector runner](/data/connectors-and-ehr) pulls clinical data from EHR systems, FHIR stores, and other source systems. For population health, the relevant data includes:
* **Diagnoses and problem lists**: active conditions, comorbidities, historical diagnoses
* **Lab results and vitals**: HbA1c trends, blood pressure readings, lipid panels, BMI
* **Medications**: current prescriptions, adherence patterns, refill history
* **Encounter history**: visit frequency, no-show patterns, ED utilization, hospitalizations
* **Care plans and orders**: open referrals, pending follow-ups, screening gaps
The connector runner supports [multiple connector types](/data/connectors-and-ehr), including FHIR, supported EHR adapters, REST sources, workspace data, and connector-specific webhooks. Each source feeds attributed events into the [world model](/data/world-model). Confidence depends on the source and how the fact was obtained: current EHR ingestion uses the verified class, while raw agent inference is lower and explicit patient confirmation can be higher. Entity projections resolve modeled conflicts by confidence class and then recency within a class.
### Sociodemographic Data
Clinical data alone misses critical risk factors. The same connectors that pull clinical data can ingest sociodemographic indicators:
* **Demographics**: age, sex, race/ethnicity, preferred language
* **Social determinants**: housing stability, food security, transportation access, employment status
* **Geographic context**: ZIP code, urban/rural classification, distance to care facilities
* **Insurance and financial**: coverage type, plan limitations, prior authorization patterns
* **Behavioral factors**: smoking status, substance use, physical activity levels
Social-determinant data often arrives from multiple sources with different provenance. Supported projections can prefer a higher-ranked source class and use recency within a class without deleting conflicting history. The confidence value is a projection input associated with the source path, not a universal assessment that one record or provider is reliable.
### Unified Patient View
The [world model](/data/world-model) retains source events and asynchronously projects supported entity state. Clinical, sociodemographic, and interaction evidence can contribute to the same entity when it has a stable association. Projection coverage can be partial, and the active pipeline does not create new cross-source `same_as` merges. Agents may still need authoritative tools for current or detailed records.
## Risk Stratification
Once data is unified, teams can register functions and queries that compute risk scores or rule-based cohorts for the population.
### Platform Functions for Risk Scoring
[Platform functions](/agent/platform-functions) can host read-only queries or computations used by a customer-defined risk workflow. The four function types map to different implementation needs:
| Function Type | Risk Stratification Use |
| ---------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| **SQL** | Cohort queries that identify patients meeting clinical criteria (e.g., all diabetics with HbA1c > 9 and no visit in 90 days) |
| **Python** | Custom scoring algorithms that combine clinical indicators, sociodemographic risk factors, and utilization patterns into composite risk scores |
| **AI** | Classification functions that categorize patients by acuity or urgency from unstructured clinical notes |
| **Table-valued** | Functions that expand one input into multiple rows, useful for per-encounter or per-line-item cohort breakdowns |
A Python user-defined function (UDF) might transform supplied features into a composite score. Python UDFs are pure compute and cannot query workspace data from inside the function body; shape the required data at the SQL level or supply it as parameters. Registration and execution do not validate the clinical model.
### Condition-Specific Stratification
Teams can register separate named functions for different indications. A diabetes function might use HbA1c trends and screening gaps, while a cardiovascular function uses different inputs. Keep model version, feature definition, validation population, and decision threshold outside the function output so reviewers can reproduce the policy that consumed the score.
Platform functions are registered at workspace scope, while their exposure to an agent depends on the service and runtime. Runtimes that enforce per-state tool bindings require the relevant context-graph state to reference the function in `tool_call_specs`; other runtimes can expose a broader workspace tool set. Validate the deployed service's resolved tools before relying on a function in a patient workflow.
### Population-Level Queries
[Workspace data queries](/agent/platform-functions#workspace-data-queries) (registered parameterized SQL templates that run against the workspace's own custom tables) answer population-level questions such as "How many patients in this panel have uncontrolled diabetes and a transportation barrier?" or "Which patients scored high-risk but have not been contacted in the last 30 days?" Teams register these queries up front so agents call them by name during operational workflows.
### Population Analytics Boundary
The public Platform API does not currently expose a general production epidemiology-table catalog with built-in prevalence, standardized prevalence ratio, comorbidity-association, or incident-trend endpoints. Teams can compute governed cohort measures with registered queries and their own analytical models.
The Sensorium demo described later includes synthetic patient topology, comorbidity, anomaly, forecast, and stratified-fit fields. Those demo tables are not evidence that the same measures are calculated for every workspace, and their example outputs must not be used for clinical decisions.
## Risk Prediction
Stratification summarizes a defined evidence set. Prediction estimates a future outcome under a separately validated model and population.
### Memory-Derived Signals
The platform's [memory system](/agent/memory) provides three kinds of inputs that population-health teams can analyze:
| Signal | What It Captures |
| ----------------------------- | --------------------------------------------------------------------------------- |
| **Episodic observations** | Source-linked changes or context extracted from completed conversations |
| **Semantic user model** | A bounded narrative of patterns, trajectories, goals, and interaction preferences |
| **Structured clinical state** | Connector-derived active conditions, medications, and allergies |
Workspaces can define additional string-valued extraction targets through validated enrichment keys. Generated observations and user-model text remain model-derived and may be incomplete; structured clinical state retains its separate connector provenance and higher confidence.
These signals can support cohort analysis when combined with explicit outcomes and appropriate statistical methods. They do not automatically establish causality or produce a validated clinical risk score. Teams should define the target outcome, inspect source coverage, validate performance across cohorts, and keep the underlying lineage available for review.
### Continuous Monitoring
Configured recurring triggers and queries can evaluate patient state on a schedule. When a defined criterion changes, the workflow can create an outbound task under its channel, consent, timing, and authorization rules.
## Evidence-Based Recommendations
Risk scores and predictions are useful only when an authorized workflow maps them to an appropriate action. The platform can deliver authored guidance through agent conversations; it does not certify that the guidance or model is evidence-based.
### Knowledge System for Clinical Protocols
Context Graphs can place clinical protocols and evidence-based guidance directly in the states where the agent needs them. Rather than relying on a separate Platform dynamic-behavior layer, the graph makes the relevant framework and its boundaries explicit.
For each clinical indication, authored states and guidance can encode:
* **Screening protocols**: when and how to assess the patient against evidence-based criteria
* **Intervention pathways**: which recommendations to deliver based on risk level and patient context
* **Escalation boundaries**: when the agent must defer to a clinician rather than deliver a recommendation
* **Communication boundaries**: authored instructions for what the agent should not say, paired with server-side controls and human fallback where enforcement is required
High-stakes protocol framing gives the agent explicit instructions for applying the relevant framework when the authored context graph reaches that part of the conversation.
### Personalized Delivery
Teams can author different delivery guidance based on explicit, available context:
* **Health literacy**: Explicit communication preferences or tested workflow guidance can adjust language complexity without inferring ability from demographic proxies.
* **Barriers and preferences**: Current, verified transportation or access context can select among options the organization has approved.
* **Prior interactions**: When memory processing succeeds, the [memory system](/agent/memory) can surface source-linked observations and user-model context about prior preferences or attempts. Verify consequential facts against current records before changing recommendations.
* **Language and communication context**: Explicit language and communication preferences can shape framing when the selected channel and model support them.
### Progressive Data Collection
When the agent identifies gaps during a risk-assessment conversation and surface tools are eligible, it can generate a [surface](/channels/surfaces) for delivery by email or web handoff. The platform stores submitted structured data and attempts asynchronous event publication; a customer-defined scoring workflow can consume the resulting evidence when it becomes available.
Data collection can be progressive rather than all at once. Workspace templates can prefill supported fields from available entity state, and eligible fields auto-save as the patient progresses. A later surface does not automatically inherit every earlier answer; configure the template and verify the stored submission or projected value. Saved values and the surface itself remain subject to submission, event-publication, projection, and expiration boundaries.
## Proactive Outreach at Scale
An explicit application, trigger, or customer workflow can use a governed cohort or risk result to invoke one of the platform's [outbound paths](/channels/outbound).
### Multi-Channel Engagement
Supported outreach capabilities include voice calls, SMS, managed WhatsApp and iMessage, email, and surface email or web links. Availability and provisioning differ by channel. Teams configure channel selection using consent, patient preferences, use-case bindings, and the needs of each interaction rather than assuming automatic cross-channel optimization.
### Adaptive Outreach
Configured workflows can use supported delivery and surface events to distinguish behaviors such as opening a message, submitting a form, or leaving a form incomplete. Teams can map those events to different follow-up rules, for example:
* A patient who opens emails but does not click gets a different message framing on the next touch, not a repeat
* A patient who starts a form but abandons gets a resume prompt ("you are almost done") through a different channel
* A patient with no digital engagement is routed to an approved non-digital process outside the platform
* A patient who answers a call but says "not now" gets a callback scheduled at their preferred time
This branching is authored workflow behavior, not an automatic guarantee. Consent, channel availability, cooldown rules, and explicit campaign logic still govern each follow-up.
### Campaign-Driven Outreach
An external campaign workflow can create [scheduled outbound voice tasks](/channels/outbound#scheduled-outbound-voice-tasks) after it applies eligibility, consent, pacing, and clinical-selection rules. Example customer-owned selection criteria include:
* Contact all high-risk diabetic patients due for HbA1c testing
* Reach patients with cardiovascular risk factors who missed statin follow-up
* Schedule screening calls for patients flagged by a behavioral health risk model
* Follow up with post-discharge patients whose readmission risk score exceeds a threshold
Scheduled voice tasks carry numeric priority, a business-hours window and timezone, an attempt limit, and retry backoff. A general campaign still needs an explicit source of eligibility, pacing, consent, suppression, and cross-channel policy; the platform does not provide one universal campaign engine.
### Compliance Gates
Outbound controls differ by channel and workflow. Configure and verify the applicable consent, timing, cooldown, fatigue, and authorization checks before production use.
* **Consent and opt-out**: verify the applicable channel record and preserve provider or customer-system outcomes; an agent statement alone is not proof that every downstream list changed
* **Quiet hours**: scheduled voice tasks can enforce a configured business-hours window and timezone; other channels follow their own workflow and provider controls
* **Cooldown periods**: implement the required interval in the trigger, campaign, or external selection workflow
* **Surface fatigue gating**: the optional gap scanner can skip entities based on pending-surface count and observed completion-rate thresholds; this does not govern every outbound channel
* **Configured authorization**: destination and channel policies determine whether an action can proceed; review-gated external writes use a separate private-preview proposal flow where enabled
### Outreach Optimization
Teams can combine surface status, delivery events, conversation outcomes, and explicit patient preferences into an engagement view such as:
* **Channel effectiveness**: which channels produce the best response for each patient
* **Timing patterns**: when the patient is most likely to engage
* **Completion behavior**: how far through forms the patient typically gets
Use these signals in registered queries or campaign rules when you want them to affect prioritization. The platform does not infer an authoritative preferred channel from behavior alone.
### Full-Loop Workflow
An illustrative, explicitly configured flow for a clinical indication:
1. **Connector runner** loads clinical and sociodemographic data from EHR and other sources
2. **World model** asynchronously projects supported entity state with source and confidence
3. **Registered query or function** computes a customer-defined cohort or score from eligible inputs
4. **Trigger or external workflow** applies consent and policy, then creates an outbound request or task
5. **Agent** calls or texts the patient with the authorized context available to that runtime
6. **Context Graph guidance** supplies the organization's reviewed protocol and boundaries
7. **Agent** attempts the permitted conversation and tools, with human fallback where authored
8. **Supported observations** can be submitted as source-attributed events and project asynchronously when publication succeeds
9. **Connector runner** evaluates policy-eligible event payloads for configured destinations and records each delivery outcome separately
The workflow exposes evidence at several boundaries: source events retain provenance, outbound attempts report delivery outcomes, and conversation records can retain available patient and agent turns. Teams that require end-to-end audit correlation should define stable identifiers across their risk calculation, campaign, conversation, and destination records rather than assume every intermediate computation is automatically stored as a world-model event.
## Verification Across Clinical Indications
Each clinical indication requires its own verification before reaching patients. The platform's [testing framework](/testing/testing) supports this through:
* **Condition-specific simulation personas**: synthetic patients representing the clinical and sociodemographic diversity of each indication's target population
* **Clinical scenarios** that test risk-appropriate responses, where the agent must handle a low-risk patient differently than a high-risk one
* **Required checks**: organization-defined criteria for escalation accuracy, scope-of-practice adherence, and medical information accuracy, followed by an explicit release decision
* **Trend review** that helps teams investigate whether measured agent performance changes as the patient population evolves
For detailed guidance on building clinical verification suites, see [Clinical Verification](/use-cases/use-cases/clinical-verification).
## Multiple Clinical Indications
Teams can configure multiple clinical indications in one workspace when their data access, tools, services, and policies are compatible:
* **Separate context graphs** per indication define the conversation flow and clinical boundaries for each condition
* **Indication-specific platform functions** encode the risk model and scoring criteria for each condition
* **Dedicated state guidance and retrieval** carry the organization's reviewed protocols for each indication
* **Shared data infrastructure**: world-model projections, connectors, and outbound primitives can support more than one indication without implying that every score or workflow shares the same evidence
Adding an indication generally means defining and validating its data inputs, risk or eligibility logic, clinical policy, conversation flow, external actions, and verification suite. Reuse shared infrastructure only where authorization, provenance, and operating requirements remain compatible.
## Developer Console Dashboard
The Developer Console includes a restricted **Sensorium** population-health demo. Every page in this section displays a persistent sample-data notice. The workspace-scoped endpoints return synthetic demonstration rows rather than live patient or workspace metrics, and several intervention and campaign elements use hard-coded demo fixtures.
{% hint style="warning" %}
Sensorium is a product demonstration, not a generally available population-health analytics or clinical-decision surface. Its forecasts, anomaly labels, intervention effects, campaign outcomes, and policy content must not be presented as measured customer results.
{% endhint %}
The navigation contains six sample views: Overview, Observation, Patient Profile, Forecast, Interventions, and Campaigns. District links can also open a Policy Memo view.
### Overview
The Overview page demonstrates territory indicators, sample campaigns, flagged districts, and watchlists assembled from the synthetic Sensorium dataset.
### Observation
The Observation page demonstrates district-level choropleths, ranked anomaly fixtures, cluster views, time controls, and a playbook visualization. These are sample analytical outputs, not active alerts against customer data.
### Patient Profile
The Patient Profile page explores synthetic patient topology, cluster summaries, selected labs or note extracts, and modeled risk fields. It does not establish that the Platform API computes those fields for ordinary workspace entities.
### Forecast
The Forecast page renders synthetic forecast fans, model-registry metadata, and stratified-fit examples supplied by the demo dataset. The values illustrate the interface and should not be interpreted as trained forecasts for the viewing workspace.
### Interventions
The Interventions page uses a fixed sample catalog and client-side demonstration calculations to compare projected impact, cost, intensity, and geographic trajectories. The evidence feedback panel includes seeded demo deployments; it is not a causal estimate derived from customer campaigns.
### Campaigns
The Campaigns page displays seeded sample deployments and counterfactual trajectories. It does not create outbound campaigns, enroll patients, or measure cases averted in a live workspace.
### Policy Memo
The Policy Memo view composes a sample district brief from Sensorium demo data and the fixed intervention catalog. It is separate from the Platform narrative-brief routes, whose current serving path does not load event evidence for synthesized patient or population narratives.
{% hint style="info" %}
**See also**
* [World Model](/data/world-model) for how supported source events become projected entity state
* [Platform Functions](/agent/platform-functions) for risk scoring and population queries
* [Functional Memory](/agent/memory) for conversation-derived observations, semantic user context, and structured clinical state
* [Context Graphs](/agent/context-graphs) for authoring protocol guidance and workflow boundaries
* [Outbound System](/channels/outbound) for proactive patient outreach
* [Clinical Verification](/use-cases/use-cases/clinical-verification) for testing clinical safety per indication
{% endhint %}
# Healthcare Contact Center
How Amigo maps voice, text, operator, analytics, and data-collection capabilities onto contact-center workflows.
Amigo is an AI-first patient communication platform. A patient can call an agent that answers within available capacity, loads authorized context, attempts configured tasks, and escalates or transfers when the authored workflow requires human involvement. The same [reasoning engine](/agent/reasoning-engine) supports SMS and text conversations, while Surfaces provide a separate browser-based data-collection path. Supported interactions retain available operational evidence; eligible calls can receive quality analysis, and only policy-eligible event payloads are considered for configured external delivery.
In an AI-first deployment, the agent can be the primary handler for configured voice and text workflows while human operators cover authored escalation and exception paths. The resulting effect on IVR, queueing, workforce management, and quality tooling depends on call mix, automation coverage, regulatory obligations, and the human fallback the organization chooses to maintain.
This guide covers how Amigo handles the use cases that contact center platforms traditionally address, where the approach is fundamentally different, and where existing tools still have a role.
```mermaid
%%{init: {"theme":"base","fontFamily":"Inter, sans-serif","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"}}}%%
flowchart LR
patient["Patient"] -->|Calls or texts| agent["AI Agent\n(primary handler)"]
agent -->|Escalation| operator["Human Operator\n(selective intervention)"]
agent -->|Data| wm["World Model\n+ EHR Sync"]
agent -->|Forms| surface["Surfaces\n(data collection)"]
agent -->|Follow-up| outbound["Outbound\n(calls, texts)"]
```
## How Amigo Handles Calls
### Conversational Routing
For an agent-handled number, the caller can state their need in natural language rather than traversing a DTMF menu. Organizations can retain deterministic or upstream routing where their workflow requires it.
The agent navigates [context graphs](/agent/context-graphs) - state machines that structure conversation flow dynamically based on what the caller says, what the system already knows about them (from the [world model](/data/world-model)), and what actions are available.
A patient calling about a follow-up appointment can state that need conversationally. When an authorized scheduling tool and patient context are available, the agent can move into the authored scheduling flow. A billing request can enter a different state or an escalation path when it is outside scope. The model-driven routing remains probabilistic and should be tested against representative phrasing.
Phone numbers are provisioned and assigned to specific services through the platform. Different departments or use cases can have dedicated numbers with their own agent versions, Context Graphs, and escalation rules. See [Phone Number Management](/channels/voice).
### Unified Runs and Operator Takeover
The [Runs Live view](/operations-and-safety/operators#runs-live-and-takeover) is the human intervention surface, designed for selective involvement rather than having an operator handle every call.
**Urgency-ranked live queue** - Live voice calls are ranked using escalation risk and immediacy when those signals are available, with wait time as a fallback. The table also includes live text and framework work without treating those runs as urgent calls. Rows show the run type, entity, service, caller, status, turn count, direction, start time, and duration.
**Run-scoped context** - Opening a row shows the channel-specific run record. Choosing **Take over** from an eligible row or detail page opens controls for that exact run in place. For voice, the drawer identifies the caller and service and shows the live transcript.
**Work modes** - Voice operators join in [listen mode](/operations-and-safety/operators) with their microphone muted. Speaking to the caller requires an explicit confirmation that switches to takeover mode and suppresses the agent's audio. Text-channel takeover pauses the agent while the operator authors replies, then resumes it on handback.
**Operator guidance** - In voice listen mode, operators can send [text instructions to the agent](/operations-and-safety/operators#guidance-injection) without taking over. When delivery succeeds, the active runtime frames the instruction for the agent's next response while the agent remains responsible for the conversation.
### Recording and Transcription
When call recording is enabled, supported voice calls are stored as [dual-channel stereo](/channels/voice/recordings): caller and agent audio are captured on separate channels. Do not assume these artifacts include a complete recording of every operator or transferred call leg. Recordings use configurable retention and secure, time-limited access URLs.
Recording and transcript availability are separate. Live and post-call transcription can be partial, provider-dependent, or unavailable even when a recording exists. When operator transcription succeeds, retained operator turns can be attributed separately from caller and agent speech.
{% hint style="warning" %}
**Screen recording is not part of the platform.** Amigo handles voice interactions, not desktop activity. Screen recording for quality assurance would come from your existing desktop monitoring tools.
{% endhint %}
### Outbound Dispatch and Callbacks
Configured applications can place direct outbound calls or create scheduled voice tasks from explicit clinical or operational criteria. Scheduled tasks support business-hours windows, timezones, attempt limits, and retry backoff. Cross-channel fallback, voicemail, and callback policy require an explicit Context Graph, trigger, or external workflow; the voice dispatcher does not select them automatically.
The agent also supports [deferred transfer](/operations-and-safety/operators) - if a call needs to be forwarded (to a clinic front desk, for example), the transfer waits until the agent's goodbye message finishes so the caller is not cut off mid-sentence.
### Surfaces - Agent-Generated Data Collection
[Surfaces](/channels/surfaces) can consolidate browser-based forms, document collection, signatures, and follow-up questionnaires behind one workspace-scoped mechanism.
**How it works:** When surface tools are exposed to the active service and state, the agent can create a dynamic form or use a workspace template, then deliver it by email or hand off a web link. Creation, signing, delivery, and completion each have their own failure and status boundaries.
**What surfaces can collect:** Fourteen current field types cover text, long text, dates, phone numbers, email, numbers, single and multi-select, checkboxes, photos, signatures, files, headings, and informational content. Supported templates can prefill known fields, and conditional display can adapt the form to earlier answers.
**During calls:** A supported active session can receive a best-effort event when a tracked surface is submitted and acknowledge it in conversation. The current surface tool family can create, deliver, inspect, template, reshape, and list surfaces when those tools are eligible. Status reads remain the authoritative fallback when completion must be confirmed.
**Delivery channels:** Surfaces support email and external web handoff. SMS, WhatsApp, and iMessage are not direct surface-delivery channels. The authored workflow selects an eligible path based on available contact data, consent, and the collection need.
**Patient access:** Surfaces open as a mobile-first web page through a signed, surface-scoped link without a patient account. Eligible fields auto-save, so a later visit can resume the last successfully saved values. Unsaved changes, failed requests, and expired links still need explicit handling. TTL is configurable from one hour to one year and defaults to seven days.
**Proactive creation:** The optional [automated gap detection](/channels/surfaces#automated-gap-detection) scanner can create a surface when projected entity state is missing configured fields. Creation does not prove delivery. The implemented automatic outreach action is a configured outbound voice task; email delivery and web handoff remain separate operations.
**Outreach optimization:** Surface history exposes pending and completed forms, while configured gap-scanner rules can apply cooldown and fatigue limits before creating more work. Teams can use that evidence to choose between verbal collection, email delivery, or a web handoff. SMS is not a direct surface-delivery channel.
**Data integrity:** The platform stores a surface submission and then attempts asynchronous publication of a provenance-bearing [world-model](/data/world-model) event. Submission success is not proof that publication or entity projection completed. A file remains traceable to its surface submission, and a configured downstream mutation can become a separate review proposal where the private-preview connector review flow is enabled.
### Call Intelligence and Quality Scoring
Eligible completed calls can produce a structured intelligence profile covering operational signals and outcome quality. These layers are best-effort and fail open so an unavailable analysis step does not fail the call.
**Two core layers support quality analysis:**
**Layer 1 - Operational call intelligence** (derived from call signals at call end): Fully analyzed records can cover emotion, latency, conversation dynamics, tool performance, and operator involvement. Compatibility risk and safety fields remain empty in the current runtime, and some external voice runtimes emit only a terminal envelope with no quality score.
**Layer 2 - Post-call quality scoring** (runs asynchronously when the required call evidence is available): The analysis scores task completion, information accuracy, conversation flow, error recovery, and caller experience, and can produce an outcome classification.
**Operational quality score** (0-100) summarizes call friction using a penalty model - starting at 100 and deducting for high latency, excessive silence, barge-ins, agent loops, escalations, and tool failures. Analytics group scored calls into excellent, good, fair, and poor bands.
**Key moments can be summarized.** When supported evidence is available, latency, silence, barge-in, loop, escalation, and tool-failure signals can help reviewers identify calls that need closer inspection. These summaries are not guaranteed timestamped markers in the recording.
**Transcript verification.** Post-call transcription can be compared with the live transcript to expose accuracy and correction evidence. Teams can use recurring errors to update configured vocabulary and keyterms deliberately.
**Quality trends over time.** Analytics show quality score distribution, escalation rates, and supported breakdowns across configurable date ranges. Period-over-period comparison can reveal a change, but it does not isolate the configuration as the cause. See [Analytics](/intelligence-and-analytics/intelligence).
If your compliance program requires structured human evaluation against custom scorecards, available recordings, transcripts, and intelligence summaries can be retrieved through their APIs for use in existing QM tools.
### Real-Time Speech Intelligence
Traditional speech analytics often runs after a call. On supported Amigo voice runtimes with emotion processing enabled, acoustic and transcript-derived signals can be produced during the call and can influence response or delivery guidance.
**Two complementary signal paths** can analyze supported calls. The [acoustic model](/channels/voice/emotion-detection) classifies two-second speech segments into a nine-class emotion distribution with valence and arousal, while transcript analysis produces sentiment and toxicity signals. The current runtime does not run a separate vocal-burst model.
**These models provide live interaction signals, not just reports.** Supported emotion outputs can influence vocal delivery and appear in call evidence. Safety and escalation decisions still come from the authored agent policy; there is no universal duration threshold or separate per-turn risk service that automatically summons an operator.
**Output signals** can include valence, arousal, a rolling trend, and a coherence estimate comparing acoustic and transcript-derived evidence when both are available. These model-derived values can be absent and should not be interpreted as verified mental state.
### Capacity and Operator Planning
AI agents do not require human shift scheduling, but deployments still need capacity planning for telephony, model providers, integrations, and human escalation coverage. Traditional workforce planning narrows rather than disappearing.
One planning question is how many operators the authored escalation paths require. The platform provides:
* **Escalation rate tracking** - What percentage of calls require human intervention, trended over time
* **Operator analytics** - Aggregate escalation count and rate, operator-handled count, escalated-call duration, quality comparison, and trend where evidence is available
* **Call volume analytics** - Durable call trends plus a separate live Runs view for active work
* [**Runs Live**](/operations-and-safety/operators#runs-live-and-takeover) - Urgency-ranked active work with in-place voice and text takeover
Organizations should size and schedule operator coverage from their own escalation policy, traffic, service levels, and fallback obligations. Amigo analytics can supply evidence to that process but do not replace a workforce-management decision.
### Multi-Channel Patient Engagement
Traditional contact centers often operate email and chat separately. Amigo can reuse compatible agent and Context Graph configuration across supported text channels, while [Surfaces](/channels/surfaces) provide a separate browser-form mechanism.
During a call or through a configured follow-up workflow, an eligible surface can deliver data collection or instructions by **email or web handoff**. Channel selection must account for available contact data, consent, and the workflow's collection requirements.
A voice call can start follow-up through configured channels: for example, the agent can deliver a surface for a missing insurance image or initiate an approved reminder workflow. Each channel still follows its own consent, binding, and delivery rules.
Text sessions also support asynchronous patient engagement, care plan reminders, and secure messaging for use cases that start outside of a phone call.
### Analytics and Reporting
The [analytics suite](/intelligence-and-analytics/intelligence) covers both real-time and historical reporting:
**Real-time:**
* [Runs Live](/operations-and-safety/operators#runs-live-and-takeover) for urgency-ranked active interactions and in-place takeover
* [SSE event stream](/intelligence-and-analytics/intelligence) for live dashboards (call lifecycle, surface submissions, pipeline sync, and operator status events with typed discriminated unions)
* Source and pipeline health views for current connector processing status
**Historical:**
* [Call intelligence analytics](/intelligence-and-analytics/intelligence) - quality, emotion, latency, tool-performance, and operator-performance trends
* [Percentile analytics](/intelligence-and-analytics/intelligence) - p50/p95/p99 duration, p50/p95 quality, and period-over-period comparison
* [Surface analytics](/intelligence-and-analytics/intelligence) - completion rates, channel effectiveness, field abandonment
* [Data quality and event views](/intelligence-and-analytics/intelligence) - current aggregate confidence and event counts where available, plus a separate current event breakdown by source and type; the current data-quality response is not a full historical confidence distribution
Historical endpoints expose their documented date, bucketing, and service filters where supported. Developers can review the exact parameters in the [Analytics reference](https://docs.amigo.ai/developer-guide/platform-api/safety/analytics) in the developer guide.
## AI Capabilities
### Automated Appointment Scheduling
The agent can identify a scheduling need, query configured availability, present options, and attempt an eligible booking through the available scheduling integration. The workflow reports the destination result separately rather than treating conversational intent as a confirmed EHR write. See [Patient Scheduling and Outreach](/use-cases/use-cases/scheduling-outreach) for the full workflow.
The authored workflow and available tools can incorporate multiple providers, insurance requirements, preparation instructions, and observed preferences from prior interactions. Each dependency needs its own current data and failure path.
### Smart Call Routing
Routing in Amigo is not a separate module - it is inherent in how the agent works. The agent determines what the caller needs through conversation (not menu selection) and navigates to the appropriate workflow via [context graphs](/agent/context-graphs).
For multi-department deployments, different phone numbers can map to services with their own agent versions, Context Graphs, and escalation rules. A scheduling line, a triage line, and a general-inquiries line can use purpose-built behavior while sharing compatible platform infrastructure.
### Agent Assist
Amigo's [operator system](/operations-and-safety/operators) provides agent assist in both directions:
**AI assists the human** - The selected run keeps the operator anchored to the caller, service, and available live transcript. During voice takeover, agent speech and turn processing are suspended; captured caller and operator turns can provide handback context when the agent resumes.
**Human assists the AI** - Operators in listen mode can inject [guidance](/operations-and-safety/operators) without adding operator audio to the call. Organizations remain responsible for any monitoring disclosure required by policy or law, and clients should verify the guidance-delivery status.
### General Inquiries
The agent can handle general inquiries through [Context Graphs](/agent/context-graphs) that route common question categories. State guidance and eligible authoritative tools can supply information for office hours, directions, preparation instructions, and policy questions.
Context graphs should define a bounded response and escalation path for questions outside the agent's configured scope. Operator availability and fallback behavior remain deployment responsibilities.
### Pre-Procedure Instructions
Two mechanisms handle pre-procedure patient preparation:
**During the call** - An authorized tool can retrieve current procedure-specific instructions for the agent to explain within its authored scope. The workflow should verify the source and provide an escalation path for questions the agent cannot answer safely.
**Written follow-up** - During the interaction or through an explicit follow-up workflow, a [surface](/channels/surfaces) can provide written instructions, checklists, and forms by email or web handoff. Delivery and completion must be confirmed through their own status paths.
The [automated gap detection](/channels/surfaces#automated-gap-detection) scanner can also create preparation surfaces from configured missing-data rules. Delivery still requires its supported workflow and should be confirmed separately.
## Beyond the Contact Center: What Amigo Makes Possible
The sections above map traditional contact center requirements to Amigo's architecture. This section covers capabilities that have no traditional equivalent - things that become possible when an agent with a unified data layer handles every interaction. Each capability has a dedicated page; the summaries here explain what it means for a contact center deployment.
### Patient Memory Across Interactions
Traditional contact centers are often stateless: each call starts with whatever notes the last agent entered. Amigo's [memory system](/agent/memory) can carry source-linked episodic observations and a consolidated user model into later sessions, while connector-derived clinical state remains separately attributed. Processing is asynchronous and generated memory can be incomplete, so authoritative tools and runtime safety controls remain necessary. [Care Coordination](/use-cases/use-cases/care-coordination) shows how this supports a multi-encounter relationship.
{% content-ref url="/pages/7NhajPdlVjsC4HxhbCYA" %}
[Memory](/agent/memory)
{% endcontent-ref %}
### Unified Data Foundation (World Model)
Traditional contact centers scatter call records, patient data, scheduling, and agent notes across systems that need middleware to reconcile. The [world model](/data/world-model) combines supported connector records, conversation observations, manual events, and surface submissions into source-attributed entity projections with [confidence-based resolution](/data/connectors-and-ehr) when modeled facts conflict. This supports contextual conversations without treating every generated observation as authoritative.
{% content-ref url="/pages/C9AEWitaAS9949s6XJTG" %}
[World Model](/data/world-model)
{% endcontent-ref %}
### Post-Call Clinical Verification
Supported observations extracted or written during a call can enter the world model with source provenance and bounded confidence; they do not write directly to the EHR merely because the agent mentioned them. Where the private-preview connector review flow is enabled, a configured downstream mutation can create an external write proposal. Proposal records, connector outcomes, and destination records provide evidence at separate boundaries; the current lineage view is not a universally complete delivery chain.
{% content-ref url="/pages/4cgSPLX4THEMq0PXWzSt" %}
[Review Queue](/data/review-queue)
{% endcontent-ref %}
### Outbound System
Amigo exposes several [outbound paths](/channels/outbound): durable SMS or iMessage starts, direct voice calls, scheduled voice tasks, managed voicemail, and a separate email API. Scheduled voice tasks are projected from world-model events and support business-hour, priority, attempt, and retry fields. The platform does not automatically turn spoken promises into tasks, choose a channel, or provide a universal campaign engine; those behaviors require explicit workflow configuration.
{% content-ref url="/pages/8yGbb8LE1sy3JeaS7UnI" %}
[Outbound](/channels/outbound)
{% endcontent-ref %}
### Proactive Safety Detection
Safety-sensitive behavior belongs in the agent's core reasoning policy. Teams can use [Context Graph states, transitions, and guidance](/agent/context-graphs) to describe symptom boundaries, clarifying questions, safe refusals, and escalation conditions. These authored instructions must be tested against representative cases; they are not an independent clinical triage service or a guarantee that every implicit concern will be detected.
### Domain Knowledge in Agent Reasoning
The agent is not limited to a fixed utterance script. Agent background, Context Graph guidance, and eligible retrieval tools can supply protocols and organizational procedures at the relevant workflow step. Prompted guidance does not prove factual correctness or enforce policy by itself, so consequential claims still require authoritative retrieval and server-side controls.
### Continuous Improvement
The platform supplies the evidence for a governed improvement process. Teams use quality scores, surface completion, escalation patterns, and delivery outcomes to identify a focused change, validate it in simulation, release an explicit version, and compare the same production measures afterward. See [Continuous Improvement](/agent/pattern-discovery-and-reuse).
### Healthcare Compliance by Design
Compliance controls span event provenance, covered [audit events](/operations-and-safety/compliance), confidence-aware outbound policy, workspace isolation, PHI access controls, and recorded retention settings. Amigo maintains a SOC 2 Type II report and supports HIPAA-regulated workloads under applicable agreements; customers should validate evidence coverage and operating procedures against their own requirements.
{% content-ref url="/pages/s0EAp8tQiDsgx7L82hPW" %}
[Compliance and Audit](/operations-and-safety/compliance)
{% endcontent-ref %}
## What Changes in an AI-First Contact Center
| Traditional Component | What Happens to It |
| --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **IVR trees** | **Potentially reduced.** Natural-language routing can replace menus for tested intents; organizations can retain IVR or deterministic routing where required. |
| **ACD queue** | **Changed for agent-handled traffic.** The agent answers within available capacity; Runs Live covers eligible human escalation and takeover work rather than every legacy queue function. |
| **Agent desktop** | **Narrowed.** Runs Live provides active-work context and eligible listen or takeover controls; other staff workflows may still need their existing systems. |
| **Call recording** | **Integrated when enabled.** Supported calls can retain dual-channel audio, partial or complete transcript evidence, speaker metadata, and best-effort intelligence. |
| **QM scoring** | **Transformed.** Best-effort operational intelligence and post-call scoring can apply defined rubrics to eligible evidence, while available recordings and transcripts support targeted human review. |
| **Speech analytics** | **Transformed.** Supported emotion signals and interaction evidence can shape agent delivery and post-call analysis. Safety escalation remains part of the authored agent policy rather than a separate universal risk-scoring service. |
| **Post-call survey** | **Expanded through Surfaces.** Surfaces can collect photos, signatures, checklists, and documents through email or web handoff, subject to delivery and completion status. |
| **WFM** | **Reduced only where automation changes staffing demand.** Human escalation coverage still needs forecasting, schedules, and an unavailable-operator plan. |
| **Email/chat** | **Covered through separate paths.** Surfaces handle browser forms, the email API handles email, and durable text conversations cover supported messaging channels with their own delivery rules. |
| **Screen recording** | **Not applicable.** Amigo is a voice and data platform, not a desktop monitoring tool. |
## Integration Points
Amigo is designed to work alongside existing contact center infrastructure during transition:
* **Telephony** - Phone numbers are provisioned through the platform. Calls can be transferred to external numbers (clinic front desks, specialist lines) via deferred transfer.
* **EHR** - Configured inbound ingestion and policy-eligible outbound delivery through the [connector runner](/data/connectors-and-ehr) and supported FHIR paths. Delivery outcomes remain separate from the source observation.
* **Existing QM tools** - Available recordings, transcripts, and intelligence results can be retrieved through their APIs for import into third-party quality-management platforms.
* **Existing WFM tools** - Call volume, duration, and escalation metrics are available via analytics APIs for workforce planning.
* **Compliance** - Workspace-scoped [audit queries](/operations-and-safety/compliance#audit) for covered events, alongside world-model provenance and destination-system evidence.
{% hint style="info" %}
For the full list of platform concepts and how they map to API terminology, see the [API Terminology Mapping](/reference/api-terminology-mapping).
{% endhint %}
# Glossary
Definitions of key platform terms - from acceptance regions and actions to world model and workspaces.
Key terms used throughout the Amigo platform documentation. Definitions are kept short and practical. Terms are listed in alphabetical order.
## A
**Acceptance Region**: The set of outcomes that count as successful for a given use case. Defined across multiple dimensions (accuracy, safety, empathy, latency, cost). An outcome must satisfy all dimensions simultaneously to fall within the acceptance region.
**Action** (API: `tool`): A versioned code package or integration that an agent can execute during a conversation (Classic API). Actions connect the agent to external systems such as scheduling APIs, EHR lookups, or notification services. Called "tool" in the API.
**Agent**: A conversational AI system configured to handle a specific set of tasks. Platform agents combine versioned instructions and identity with a service, context graph, tools, and evaluation criteria. Classic agents can also use dynamic behavior sets.
**Agent Engine**: The modality-independent reasoning core of the platform. Processes typed signals (utterances, emotion, tool results, silence, barge-in, external events) and emits effects (respond, execute tool, filler, transition, terminate, observe, pause). Voice, text, and simulation are modality adapters that convert channel-specific I/O into signals and execute effects. See [Reasoning Engine](/agent/reasoning-engine).
**Agent Forge**: The CLI tool for managing agent configurations. Used to create, update, version, and promote services and version sets across environments. See the [Agent Forge](/reference/agent-forge) reference page.
**Auto-Enrichment**: A best-effort background process that can gap-fill registered enrichment keys for supported person and place entities. It writes source-tagged enrichment events asynchronously; higher-authority values can supersede the result. This is distinct from event embedding.
## B
**Backfill**: The process of replaying historical conversation data through an updated configuration to regenerate metrics and verify that changes produce the expected improvements.
**Barge-In**: Supported voice behavior that can stop agent playback after incoming caller speech satisfies the configured recognition, minimum-duration, and cooldown checks. Sensitivity and timing depend on the active voice path and service configuration.
## C
**Call-Phase Adaptation**: Prompt guidance based on call duration and recent emotional evidence. On an extended call with negative or deteriorating evidence, the voice runtime can ask for shorter, resolution-focused responses and suggest considering escalation. It does not automatically transfer or end the call.
**Channel Use Case**: A provisioned channel identity and purpose, such as an email sender or managed messaging pool. A service binding establishes the workspace routing for supported inbound and outbound operations. Provisioning, consent, and sender approval remain separate prerequisites. See [Channels](/channels/conversations).
**Clinical Tools**: Built-in tools available to supported agent runtimes for patient and appointment workflows, typed clinical reads, coverage and refill-request writes, outbound-queue lookup, and operational logging. Scheduled outbound work is created through explicit actions or workflows rather than a general built-in scheduling tool. Supported writes emit world-model events that can enter configured connector policy; recording the event does not prove external delivery.
**Compound Emotion**: A nuanced emotional state derived from fusing multiple signal layers (acoustic co-activation, temporal trajectory, behavioral signals, conversation context, and linguistic content) at each caller turn. Examples include Resignation, Process Frustration, Cold Hostility, Masked Distress, and Sarcasm. See [Emotion Detection](/channels/voice/emotion-detection).
**Confidence Score**: A numeric value used in different product contexts. **Data confidence** ranks a world-model observation by source class and participates in conflict resolution. Evaluation scores and model-reported certainty have separate meanings and do not automatically inherit data-confidence semantics or trigger operator escalation.
**Conference-First Architecture**: The Platform-managed voice-call model in which the caller and agent use a shared conference and an eligible operator can join without reconnecting the caller. Listen, takeover, and warm-forwarding paths have different behavior; conference participation does not guarantee a complete transcript or clinical briefing.
**Connector Runner**: The integration layer that ingests supported EHR, FHIR, REST, file, and webhook sources and routes policy-eligible event payloads to supported external destinations. Inbound recovery and outbound delivery semantics vary by connector and operation.
**Context Fusion**: The combination of available acoustic, linguistic, behavioral, and recent-turn evidence when deriving emotion-related prompt and delivery guidance. These signals remain incomplete, model-derived evidence and do not independently determine safety or escalation. See [Emotion Detection](/channels/voice/emotion-detection).
**Context Graph** (API: `service_hierarchical_state_machine`): The structured map of a problem space that guides agent behavior. Context graphs define states, transitions, decision points, and safety boundaries for a specific workflow. Called "service hierarchical state machine" in the API.
## D
**Data-MCP**: A standalone Model Context Protocol service that exposes read-only SQL exploration tools using Classic API organization credentials. For agent-side access during conversations, use [platform functions](/agent/platform-functions); external integrations using Platform API workspace credentials can use the Platform API MCP server. See [Data Access (MCP)](/data/data-mcp).
**Dominance**: A field in the normalized emotional-state shape intended to represent perceived control. The current runtime snapshot does not derive a live dominance value and reports the neutral placeholder `0`; it does not drive an empathy tier. See [Emotion Detection](/channels/voice/emotion-detection).
**Drift**: A gradual change in agent performance over time. Can be caused by changes in the input distribution (new types of conversations), shifts in agent behavior, or evolving requirements. See [Drift Detection](/testing/testing/drift-detection).
**Dynamic Behavior** (Classic API: `dynamic_behavior_set`): A Classic-only behavioral rule with semantic triggers and instruction or tool-candidate changes. Classic behavior sets are versioned and applied through Classic version sets. The Platform API does not expose or execute this resource; express conditional Platform behavior in context graph states, transitions, policies, and eligible tools. See [Dynamic Behaviors](/agent/context-graphs/dynamic-behaviors).
## E
**Effect**: An output primitive from the reasoning engine representing something the agent wants to happen. Effect types: respond (say something), tool called (execute a tool), filler (play/send filler content), transition (state change), terminate (end conversation), observe (emit analytics event), pause (deliberate silence). The modality adapter decides how to execute each effect - a respond effect becomes TTS audio on voice, an SMS message on text, or a trace entry in simulation.
**Email Channel**: A managed channel for transactional and marketing email with verified sending domains, typed use cases, inbound reply threading, and separate delivery-status records. Email has its own send API and is not a target of the Conversations API's outbound-start or channel-switch operations. See [Channels](/channels/conversations).
**Entity Resolution**: The process of associating an incoming record or caller with a workspace entity. Current paths use explicit source identifiers, caller bindings, and scoped lookups. `same_as` edges represent historical merges from the retired pre-SDP resolver; the current Platform pipeline does not produce new deterministic cross-source merge edges.
**Escalation**: The process of handing a supported conversation from the agent to a human operator. Escalation follows authored agent and context-graph policy, supported operator workflows, or an explicit user request; a generic low-confidence score does not automatically trigger it.
**External Principal**: An entity-anchored, role-scoped session identity for external users (such as clinicians or partner employees) driving agent conversations. A principal binds an external user identity to a workspace entity with assigned roles, and role grants scope which integration endpoints, skills, and knowledge base scopes the session can access. See [Compliance](/operations-and-safety/compliance).
## F
**FHIR Store Connector**: A connector type that integrates directly with FHIR R4 stores. Polls configurable FHIR resource types with per-resource cadences and supports outbound write-back with optimistic locking.
**File Drop Connector**: A connector type that ingests data from files (CSV, NDJSON, FHIR Bundle, JSON) deposited in cloud storage. Used for batch data imports from partners or external systems.
**Filler Speech**: Short spoken acknowledgements that can cover part of a voice-processing or tool-execution delay. Filler selection is channel-, state-, and emotion-aware, can be suppressed, and does not guarantee that every delay is covered.
**Function Store**: The workspace registries from which platform functions and workspace data queries are loaded at session start. A successfully loaded definition can become an agent tool when the selected runtime and any applicable Context Graph binding expose it; registration alone is not a universal visibility or authorization rule. See [Platform Functions](/agent/platform-functions).
## I
**Interaction Insight**: A Classic API response for a permitted conversation interaction, including the current state and action, transition logs, permitted working-memory or reflection records, and executed tool-call logs. The Platform API does not expose an equivalent hidden-reasoning contract; Platform simulation traces contain best-effort observed evidence instead.
## K
**Keyterm Boosting**: A speech-to-text configuration that biases compatible recognition paths toward domain vocabulary such as medication, provider, or organization names. It can improve recognition for selected terms but does not guarantee an accurate transcript.
## L
**LLM-Evaluated Metric**: A metric whose eligible evidence is scored by a model-based judge against authored criteria rather than by a deterministic rule. Availability, scheduling, and execution limits depend on the evaluation path, and results require calibration against human review. See [Metrics](/testing/testing/metrics).
## M
**Functional Memory**: Cross-session context built from source conversation records, model-extracted episodic observations, a bounded semantic user model with lineage, and separately projected structured clinical state. Current enrichment can load into later sessions, but it does not guarantee complete recall or eliminate authoritative data retrieval. See [Functional Memory](/agent/memory).
**Metric**: A configured measure of interaction or operational evidence. **Evaluation metrics** can score eligible conversations against rubrics. **Operational metrics** aggregate supported workspace evidence through producer-specific paths; a definition does not imply that every channel or interaction produces a value. See [Metrics and Quality](/testing/testing/metrics) and [Metric Store](/intelligence-and-analytics/metric-store).
**Metric Store**: The Platform API's common value model and query surface for operational, quality, and evaluation metrics. The current catalog has 41 built-in definitions and accepts up to 50 custom definitions per workspace. The schema contains five extraction modes, but supported custom modes have narrower rules. Latency tiers and freshness values describe intended processing and configured targets, not contractual delivery times. See [Metric Store](/intelligence-and-analytics/metric-store).
**Modality Adapter**: A channel-specific boundary that converts supported input into typed signals and translates reasoning-engine effects into channel behavior. Voice, SMS text, and simulation are current examples; each retains its own delivery, lifecycle, authorization, and failure semantics.
## O
**Operator**: An authorized human who can monitor eligible live runs and, for supported channels, listen, guide, take over, or hand control back. Run-scoped transcript and context can be available, but operator entry is not a guaranteed complete patient briefing or proof that a downstream handoff succeeded.
**Outbound Task**: A world-model entity used for scheduled outbound voice work. Supported actions or workflows write an `outbound.scheduled` event, asynchronous projection makes the task visible to the dispatcher, and the dispatcher selects eligible due tasks. Event acceptance, projection, dispatch, call completion, and recipient delivery remain separate milestones.
## P
**Persona (Agent)**: The conceptual identity and background carried by an agent version, including structured identity, background text, behavioral guidance, and communication patterns. The current Platform API does not expose the retired standalone persona resource; services resolve an agent version through version-set configuration. See [Agent Core](/agent/agents).
**Persona (Simulation)**: A synthetic user profile used in simulations. Defines the characteristics, behaviors, and communication style of a test user. See [Simulations](/testing/testing/simulations).
**Platform Function**: A workspace-registered, read-only SQL, AI, Python, or table-valued computation. Supported runtimes can expose named functions (`fn_*`) and workspace data queries (`wsq_*`) after successful loading and any applicable Context Graph binding. Management is available through workspace-scoped APIs and supported tooling. See [Platform Functions](/agent/platform-functions).
**Pre-Emptive Tone Adjustment**: A supported voice fallback that can select sympathetic delivery when no emotion-derived tone is available and the current Context Graph action matches a configured sensitive topic. This is delivery guidance, not a prediction that the caller is distressed or an independent safety control.
**Projection Function**: Downstream logic that folds world-model events into a current read model for an entity type. Projection is asynchronous from event acceptance, so a successful write can precede visibility in the serving projection.
## Q
**Quality Score**: Context-dependent call evidence. The terminal operational quality score runs from 0-100 and reflects latency, silence, barge-ins, loops, operator escalation, and tool failures. Optional recording-based post-call analysis separately scores five rubric dimensions from 1-5. See [Call Intelligence](/intelligence-and-analytics/intelligence/call-intelligence).
## R
**Reasoning Engine**: The modality-independent pipeline at the core of the agent engine. It processes signals through perceive, reason, and act stages, navigating the Context Graph, executing eligible tools, and emitting effects. Streaming delivery supports voice, while completed-effect processing serves supported text, simulation, and API consumers. See [Reasoning Engine](/agent/reasoning-engine).
**Review Queue**: Private-preview interface for authorized reviewers to approve or reject a specific proposed write to an external system. A decision authorizes or blocks that mutation; it does not change the source event's confidence.
## S
**Scenario (Simulation)**: A defined situation used in simulations. Describes the context, events, and goals for a test interaction. See [Simulations](/testing/testing/simulations).
**Service**: Deployment configuration that connects selected agent and Context Graph versions with runtime and channel settings. Named version sets select the component versions used when configuration is resolved. See [Core Concepts](/platform-overview/core-concepts).
**Service Binding**: The association between a provisioned channel use case and a service in a workspace. It establishes routing, not provider provisioning or recipient consent. Rebinding can change the service in the same workspace; removing a binding removes that route without deleting the upstream channel resources.
**Service Voice Configuration**: Per-service voice tuning that controls filler behavior (style, vocabulary, timing), barge-in sensitivity, response length limits, end-of-turn detection, TTS settings, and call forwarding. Different services within the same workspace can have different voice characteristics. Managed through the Platform API and Agent Forge CLI.
**Signal**: An input primitive to the reasoning engine representing something that happened in the conversation. Signal types: utterance (user said something), emotion (emotional state update), tool result (tool execution completed), silence (user inactive beyond threshold), barge-in (user interrupted agent), external event (operator guidance, surface submission), system (timeout, error, connection state). All modality adapters normalize input into these signal types before passing to the engine.
**Silence Monitor**: The voice-runtime component that detects caller inactivity. It uses backoff thresholds of 10, 20, and up to 40 seconds, then generates a brief goodbye and ends the call after the third unanswered threshold.
**Simulation Bridge**: An exploratory testing mode that generates scenario variations from a natural-language objective, runs each as a full multi-turn conversation with an LLM-driven persona, and collects interaction insights for coverage tracking. See [Simulations](/testing/testing/simulations).
**Skill**: An orchestrated companion definition configured through the Platform API. A skill declares a required system prompt, input and result schemas, model and execution bounds, and the integration or static tools it may call. The Platform API does not expose a five-tier skill model. See [Skill Execution](/agent/platform-functions#skill-execution).
**Speaker Normalization**: Per-call acoustic calibration that reports recent voiced-audio features relative to the caller's running baseline after enough evidence is available. Relative features reduce dependence on population averages, but they do not make emotion classification definitive. See [Emotion Detection](/channels/voice/emotion-detection).
**Surface**: A dynamic or template-based data collection interface that can be delivered by email or handed off as a web link. Eligible agent tools and configured state templates can create surfaces; creation, delivery, submission storage, event publication, and downstream mutation remain separate lifecycle steps. See [Surfaces](/channels/surfaces).
**SurfaceSpec**: The structured specification an agent generates to define a surface - title, fields, delivery channel, expiration, and entity association.
## T
**Test Run**: The execution of a test set that produces scored results for each unit test. See [Simulations](/testing/testing/simulations).
**Test Set**: A group of related unit tests that are run together. Test sets are often organized by capability area or risk level.
**Tone Momentum**: Voice behavior that retains the previous successfully derived emotion tone when a later acoustic turn is weak or unmapped instead of resetting immediately. It applies only to emotion-derived delivery; navigation and configured workspace tone can still take precedence.
**Transcript Extraction**: In the current Platform memory flow, asynchronous model-based processing can derive source-linked episodic observations and registered behavioral memory dimensions from a completed conversation. It does not automatically convert phone, date-of-birth, insurance, or address mentions into authoritative structured clinical state; explicit tools and connector projections have separate write semantics.
**Trigger**: A workspace-scoped automation that binds an action to a cron schedule or supported platform event. Triggers support event filters, timezone-aware scheduling, pause/resume lifecycle, manual firing for testing, and execution history tracking. Managed through the Platform API, Developer Console, and Agent Forge CLI.
## U
**Unification Engine**: The transformation layer through which supported inbound connectors can map raw records into world-model events using configurable rules, including dot-path extraction for nested source data. New vendor protocols or operations can still require connector-specific support.
**Unit Test**: A combination of a persona, a scenario, and success criteria that tests a specific agent behavior.
## V
**Version Set**: A named service configuration that can pin agent and context graph versions, model preferences, and a supported turn runtime. Platform services require a `release` version set; omitted version numbers resolve to the latest available version. Classic version sets have a different component model.
## W
**Webhook Connector**: A push-oriented data-source mode for supported external integrations. Request verification, resource retrieval, retry handling, and duplicate suppression depend on the connector path; do not assume universal content-hash deduplication.
**Workspace**: The Platform tenant boundary for data, configuration, and access. A workspace can contain several services and has its own scoped entities, sources, and permissions. See [Workspaces](/data/workspaces).
**Workspace Data Query**: A parameterized SQL template registered per workspace that runs directly against workspace-owned custom tables. Exposed to the agent as a `wsq_` tool with typed parameters and write-time validation. See [Platform Functions](/agent/platform-functions).
**World Model**: The platform data layer that retains source-attributed events and asynchronously projects supported current-state views. Agents receive selected context and can use authorized tools for additional retrieval; the model is not a guarantee that every source or current fact is present in one session payload.
**Write Scope**: A server-constructed boundary that limits the workspace, entity, resource types, creation rights, and confidence available to supported model-originated write tools. Trusted services use separate service authorization; their access does not let an agent tool bypass its own scope.
# API Terminology Mapping
Map conceptual documentation terms to current Classic and Platform API resource names.
The conceptual documentation uses product names intended for readers, while the two API surfaces retain some different resource names. This page identifies the exceptions so you can move between conceptual guidance and implementation references without mixing Classic and Platform API terminology.
## API Mappings
| Conceptual Name | API Name | Surface | Description |
| ----------------- | ------------------------------------ | ------------ | ------------------------------------------------------------------------------- |
| Action | `tool` | Classic API | A versioned code package that an agent can execute during a conversation. |
| Call Timeline | `timeline` | Platform API | Lane-based playback with actor-attributed segments on a shared timebase. |
| Context Graph | `service_hierarchical_state_machine` | Classic API | The state machine that structures conversation flow and agent reasoning. |
| Dynamic Behavior | `dynamic_behavior_set` | Classic API | A runtime rule that modifies agent behavior when conversation conditions match. |
| Metric Store | `metrics` | Platform API | Workspace-level built-in and custom quality metrics. |
| Platform Function | `function` | Platform API | A declarative SQL, AI, Python, or table-valued function that an agent can call. |
Most Platform API resources - including workspaces, agents, services, sessions, skills, surfaces, triggers, and operators - use the same product name in the documentation and API. The legacy names above remain important when working with the Classic API or configuration files that originated there.
{% hint style="info" %}
The API references are definitive for current resource names and schemas. See the [Classic API](https://docs.amigo.ai/developer-guide/classic-api/core-api) and [Platform API](https://docs.amigo.ai/developer-guide/platform-api/platform-api) sections of the developer guide.
{% endhint %}
# Agent Forge CLI
Agent Forge CLI for syncing, versioning, and promoting agent configuration, with current Go and legacy Python build coverage.
Agent Forge is the CLI tool for managing agent configurations on the Amigo platform. It lets you create, update, version, and promote agent components programmatically rather than through the web interface.
Agent Forge treats agent configurations as code. You sync configurations to local JSON files, make changes, and push them back to the platform. This gives you version control, reproducibility, and the ability to script deployment workflows.
## Choosing a Build
Agent Forge ships as two builds that share the same `forge` command and most of the same command surface:
* **Go CLI (current, recommended)** - A single self-contained binary with no runtime dependencies. This is the source of truth for the `forge` CLI going forward. New workspaces and new automation should use this build. **The Go CLI officially supports only the Amigo** [**Platform API**](https://docs.amigo.ai/developer-guide/platform-api/platform-api) - it drives all remote operations through the `forge platform ...` command tree. It does not officially support the Classic API (the legacy backend); use the Python CLI for Classic API workflows.
* **Python CLI (legacy)** - The original Poetry-managed Python tool. It supports both the Platform API and the Classic API, and it carries a superset of commands - a handful of analytics, quality, and reporting commands have not yet been ported to the Go binary - but it is being retired for external use and now mainly serves internal Amigo workflows. Use it if you need the Classic API or one of the legacy-only commands listed in its tab below.
Both builds understand the same entity model, the same `--env` flag, and the same `.env.platform.` configuration for the Platform API. The tabs below document each build; unless a section says otherwise, the Platform API command syntax is identical across builds.
To tell which build you have, run `forge version` (Go prints a stamped binary version; the Python tool runs from a git checkout).
## What Agent Forge Manages
Across its two builds, Agent Forge manages the following configuration and testing resources. Coverage differs by build: the current Go CLI targets Platform API resources, while the legacy Python CLI retains Classic API workflows and legacy-only analytics commands. The tabs below identify the supported command surface for each build.
* **Agents**: Persona, background, directives, and communication style
* **Context graphs**: Problem structure, states, transitions, and safety boundaries
* **Metrics**: Evaluation criteria, scoring rubrics, and custom metric definitions
* **Personas**: Synthetic user profiles for simulation testing (the primary way to manage personas)
* **Scenarios**: Test situations for simulation testing
* **Services**: Link an agent and context graph into a deployable unit
* **Harness context**: Inspect the supported service bootstrap context for customer integrations
* **Tools**: Versioned code packages (called Actions in the conceptual docs)
* **Unit test sets**: Groups of tests with success criteria
* **Unit tests**: Individual test cases
* **User dimensions**: Attributes that segment users for evaluation and analysis
{% tabs %}
{% tab title="Go CLI (current)" %}
The Go build is the recommended, go-forward CLI. It ships as a single binary and covers the full agent-building and platform-management workflow.
{% hint style="info" %}
The Go CLI officially supports only the Amigo **Platform API**. All remote operations go through the `forge platform ...` command tree. Classic API (legacy backend) workflows are not officially supported in this build - use the Python CLI tab for those.
{% endhint %}
### Installation
Agent Forge ships as a single binary with no runtime dependencies. On macOS, the installer detects the architecture, downloads the correct binary, verifies the SHA256 checksum, and places it on your PATH.
```bash
curl -fsSL https://forge.platform.amigo.ai/install.sh | sh
```
Pre-built targets cover macOS (Intel and Apple Silicon) and Linux (amd64 and arm64). The public installer and the `forge update` self-updater currently target macOS. For Linux, obtain the binary through the release channel provided to your organization.
After installation, configure credentials for your workspace:
```bash
# Create environment file
cp .env.platform.example .env.platform.
# Edit with your Platform API URL, workspace ID, and API key or identity URL
# Verify
forge auth status --platform --env
```
You can also manage credentials as reusable profiles instead of environment files with the `forge platform config` command group (`add`, `use`, `list`, `show`, `doctor`, `remove`, `import-env`, `path`).
### Authentication
The Go CLI authenticates against the Platform API. Pass the `--platform` flag on the auth commands to target the Platform identity service. Two methods are supported, selected automatically based on the environment configuration: device code login through the identity service, and static API keys.
#### Device Code Login (Recommended)
Device code authentication follows RFC 8628. When you run `forge auth login --platform`, the CLI requests a device code from the identity service, displays a short user code, opens your browser to an approval page, and polls for authorization. You verify that the code shown in the browser matches the code in your terminal and approve the request. These flows work in headless environments, SSH sessions, and CI pipelines where a browser cannot be opened inline.
The approval page enforces that your browser session is scoped to the same workspace the device code targets - if your session is scoped to a different workspace, the page redirects you to workspace selection first, and after choosing the correct workspace you are returned to the approval page automatically. If you are not signed in at all, the sign-in flow preserves the approval page as the return destination through authentication and workspace selection, so you land back on the approval page without needing to re-open the CLI link. A session scoped to the wrong workspace or a session without any workspace selected cannot approve the code.
The platform identity device code flow is workspace-scoped end to end. When you initiate a login, Forge sends the configured workspace ID along with the device code request, and the identity service binds the code to that workspace - the approver in the browser must hold a session scoped to the same workspace, and the resulting CLI token is scoped to it. This workspace enforcement applies at both the approval step and the token exchange step, ensuring that credentials are always tied to the intended workspace and preventing cross-workspace token misuse.
Once approved, Forge receives an access token and refresh token automatically - no manual token management required. Platform identity tokens are stored in a workspace-keyed file cache under the operating system's user configuration directory; Forge creates the cache directory with owner-only access and writes token files with mode `0600`. An expired access token is refreshed with the stored refresh token without requiring re-authentication when refresh succeeds. Device code login replaces the need for a static API key for interactive CLI use.
#### API Key
Static bearer token authentication. Generate an API key from Amigo Console under **Developer > API Keys** and add it to your environment file. Platform API keys expire after a configured 1-90 days; Forge defaults new keys to 30 days. Rotate CI/CD credentials before expiry and delete keys that are no longer needed.
#### Environment Configuration
Platform API authentication reads from `.env.platform.` (preferred) or falls back to `.env.`. The following variables control the platform auth path:
| Variable | Required | Description |
| ----------------------- | ------------ | --------------------------------------------------------- |
| `PLATFORM_API_URL` | Yes | Platform API URL for the target environment |
| `PLATFORM_WORKSPACE_ID` | Yes | Workspace to authenticate against |
| `PLATFORM_API_KEY` | One of these | Static API key (no login required) |
| `IDENTITY_URL` | One of these | Platform identity service URL (enables device code login) |
If `PLATFORM_API_KEY` is set, Forge uses it as a static bearer token. If `IDENTITY_URL` is set instead, Forge uses the device code flow via `forge auth login --platform`.
Forge-native configuration fields are automatically translated to platform-native equivalents at deployment time. For example, audio filler phrases defined in Forge tool specs are converted to the platform's progress hint format, so agents configured through Forge work without manual migration.
#### Auth Commands
```bash
# Platform API login (platform identity device code)
forge auth login --platform -e myorg
# Check auth status
forge auth status --platform -e myorg
# Clear cached credentials
forge auth logout --platform -e myorg
```
Always pass `--platform` on the Go CLI. The `--platform` flag is available on `login`, `logout`, and `status`. Without it, the auth commands operate on Classic API (legacy backend) credentials, which the Go build does not officially support.
### Command Groups
The sections below cover the Agent Forge command surface, one command group at a time. Most commands support `--json` for structured output, and `--env` selects the target environment, enabling integration with scripts and CI/CD pipelines. (`forge validate`, which runs against local files, accepts `--env` but not `--json`.)
#### Sync and Deployment
**Pull from the platform** - Read entities down from the Platform API with the per-resource `get` and `list` commands, then edit them as JSON on disk:
```bash
# List and fetch entities from the Platform API
forge platform agent list --env myorg
forge platform agent get --env myorg
forge platform context-graph get --env myorg
forge platform service get --env myorg
```
**Push to the platform** - Push local changes back with `forge platform push` (see **Bulk Push** below). Before applying changes, Agent Forge shows exactly what will be modified so you can review before confirming.
{% hint style="info" %}
The Go binary still carries the older `sync-to-local` / `sync-to-remote` commands, but they operate against the Classic API (legacy backend), which the Go build does not officially support. For Platform API work, pull with `forge platform get` / `list` and push with `forge platform push`. For Classic API sync, use the Python CLI.
{% endhint %}
**Pre-Push Validation** - Agent Forge validates context graphs before pushing to the platform and surfaces warnings for common authoring mistakes. Validation runs automatically during `forge platform push`, and you can run it on local files at any time with `forge validate` (no auth required).
The canonical value lint detects phone numbers, email addresses, and URLs hardcoded into context graph state prose. Inline canonical values cause silent data drift - when graphs are cloned or updated, hardcoded digits can be accidentally mutated, and the agent reads incorrect information to callers.
The validator scans prose fields in every state (descriptions, instructions, boundary constraints, exit conditions, and action descriptions) and emits a warning for each match, identifying the state, field, and value. It catches phone numbers in digit form (e.g., `555-010-1234`), phone numbers in spelled-out TTS form (e.g., "five five five zero one zero..."), email addresses, and URLs.
To fix a warning, move the canonical value into structured context - such as a location entity in the world model or a workspace setting - and reference it abstractly in the state prose.
**Environment Support** - Agent Forge supports separate staging and production environments. Changes are deployed to staging first, validated through testing, and then promoted to production. Platform push operates on agents, context graphs, and services, laid out per environment:
```
project/
local/
staging/
entity_data/
agent/
context_graph/
service/
.platform_id_map.json
production/
entity_data/
(same structure)
.platform_id_map.json
```
**Bulk Push** - Push local entity configurations to the Platform API in a single operation:
```bash
forge platform push --all --env myorg --apply
```
Supports selective push by entity type (`-e agent`, `-e context-graph`, `-e service`). The Go build maintains a local-to-platform UUID map (`local//.platform_id_map.json`) so repeated pushes update the same platform entities.
#### Agent Building
The `forge platform` command group provides broad CLI coverage for common Platform API workflows, enabling agent building and workspace management without the web interface. Build a complete agent from the CLI in four steps:
1. **Create agent** and agent version with identity, background, and behaviors
2. **Create context graph** and version with states, transitions, and exit conditions
3. **Create service** linking the agent and context graph together
4. **Add skills** (optional) for LLM-backed micro-agent capabilities
```bash
forge platform agent create --name "My Agent" --env myorg
forge platform agent create-version --file agent-version.json --env myorg
forge platform context-graph create --name "My Context Graph" --env myorg
forge platform context-graph create-version --file context-graph-version.json --env myorg
forge platform service create --name "My Service" --agent-id --context-graph-id --env myorg
```
CLI support is organized into these resource groups:
| Resource Group | Commands |
| --------------------- | ------------------------------------------------------------------------------------------ |
| **Core** | `workspace`, `agent`, `context-graph`, `service`, `version-set`, `skill` |
| **Voice & Text** | `conversation`, `run`, `voice-settings`, `voice-check` |
| **Data** | `integration`, `external-integration`, `function`, `fhir`, `workspace-table`, `data-query` |
| **Surfaces** | `surface` |
| **Testing** | `simulation`, `sim`, `tool-test`, `regression`, `agent-run` |
| **Access & Identity** | `api-key`, `role-grant`, `role-assignment`, `external-role`, `use-case` |
| **Operations** | `config`, `audit`, `session`, `triggers` |
#### Harness Context and Retired Framework Commands
The Platform API retains a read-only service harness-context capability for inspecting the selected identity, reference instructions, world scope, tool descriptors, and guardrail summary. It is bootstrap context for an integration, not an endpoint that launches a customer framework agent or retrieves patient context.
```bash
forge platform agent-run harness-context --service-id --env myorg
```
The standalone native-agent definition registry and hosted framework-run service have been retired. Some Forge releases still expose `agent-definition` commands and `agent-run create` or `get`, but their former Platform endpoints are no longer available. Do not use those commands for new deployments. Use the supported conversation lifecycle for hosted interactions and the unified `run` commands to inspect retained run evidence.
#### Voice Configuration Presets
`forge platform service voice-config` can read the current configuration, apply an inline JSON body, or apply a named preset. The CLI recognizes `ultra_low_latency`, `balanced`, `quality`, `gpt_realtime`, and `gpt_live`. The `gpt_realtime` preset selects OpenAI Realtime speech-to-speech; provider, model, and regional availability are still enforced by the platform.
```bash
forge platform service voice-config --get --env myorg
forge platform service voice-config --preset gpt_realtime --env myorg
```
#### Simulation
Use `forge platform simulation` for the supported branch-and-bound coverage surface. `forge platform sim bridge` remains a shortcut to the same bridge workflow, and `forge platform sim config-to-policy` maps a configuration object to turn-policy fields. Legacy configuration-space commands such as `sim create`, `sample`, `evaluate`, `status`, `points`, `summary`, and `complete` target retired endpoints and should not be used.
#### Simulation Coverage
The `forge platform simulation` command group manages branch-and-bound simulation coverage runs that systematically explore context graph state space.
| Command | Description |
| ------------------------------------------ | ------------------------------------------------------------------------------- |
| `forge platform simulation run create` | Create a new coverage run for a service |
| `forge platform simulation run list` | List coverage runs for a service |
| `forge platform simulation run complete` | Complete a run |
| `forge platform simulation session create` | Create a session within a coverage run |
| `forge platform simulation session step` | Step a session forward with a simulated user message |
| `forge platform simulation session fork` | Fork a session into children at a decision point, each with a different message |
| `forge platform simulation session score` | Score a session against configured metrics |
| `forge platform simulation graph show` | Retrieve the coverage knowledge graph with topology overlay and ghost nodes |
| `forge platform simulation graph paths` | List observed paths through the coverage graph |
See [Simulation Coverage](/testing/testing/simulations#simulation-coverage) for conceptual background.
#### Simulation Caller and Entity Context
`forge platform simulation session create` accepts `--caller-id` for a simulated caller phone number in E.164 format and `--entity-id` for direct binding to a known world entity. `forge platform sim bridge` accepts `--entity-id` but not `--caller-id`. Direct entity context is useful for regression tests against a known patient or account fixture. Omit the context flags to simulate an unknown caller.
```bash
# Bridge scenarios against a known entity
forge platform sim bridge --service-id -o "Test known entity flow" --entity-id --env myorg
# Branch-and-bound coverage session with entity context
forge platform simulation session create --run-id --service-id --entity-id --env myorg
```
**Tracked Platform Simulation Sessions**
The `forge platform sim` group also drives tracked platform simulation sessions used by the Agent Readiness workflow:
| Command | Description |
| ----------------------------------- | --------------------------------------------------------------------------- |
| `forge platform sim smoke-test` | Single-turn sanity check via a tracked platform session |
| `forge platform sim session-create` | Create a tracked simulation session (accepts `--caller-id` / `--entity-id`) |
| `forge platform sim run-create` | Create a tracked simulation run |
| `forge platform sim run-list` | List simulation runs with filtering |
| `forge platform sim run-complete` | Mark a simulation run as complete |
#### Text Conversation Testing
The `forge platform conversation` command group tests text conversations through the REST API without a phone or browser. These commands are useful during initial setup, after configuration changes, or as part of a deployment validation pipeline.
| Command | Description |
| ------------------------------------------ | ----------------------------------------------------------------------------------------- |
| `forge platform conversation list` | List conversation runs through the unified Runs view; use `run list` for new automation |
| `forge platform conversation get` | Retrieve conversation metadata, transcript, and optional tool calls |
| `forge platform conversation create` | Create a durable text conversation for a service and optional entity context |
| `forge platform conversation send-message` | Send a message, wait for the final reply when possible, and optionally evaluate it inline |
| `forge platform conversation poll` | Claim a completed background reply after a pending send |
| `forge platform conversation close` | Close a text thread so the next inbound message starts a new conversation |
Create a durable text conversation, then send user messages through the REST turns endpoint and display the agent's response:
```bash
# Create the conversation
CONV_ID=$(forge platform conversation create \
--service-id \
--env myorg \
--json | jq -r .id)
# Send the first message
forge platform conversation send-message \
--conversation-id "$CONV_ID" \
--message "What appointments are available tomorrow?" \
--env myorg
# Continue the same conversation
forge platform conversation send-message \
--conversation-id "$CONV_ID" \
--message "How about 2pm?" \
--env myorg
# With patient context
forge platform conversation create --service-id --entity-id --env myorg
```
`send-message` requires an existing conversation ID. Use `conversation create` first and pass the returned ID on subsequent calls to continue the same conversation thread.
**Inline Reply Evaluation**
`send-message` can evaluate a final reply in the same command. Repeat `--must-contain` or `--must-not-contain` for fast local checks. Repeat `--judge-criteria` for model-based checks against natural-language requirements; judge checks require configured judge credentials and `--i-understand-pii` because the reply may contain sensitive data.
```bash
forge platform conversation send-message \
--conversation-id "$CONV_ID" \
--message "I need to move tomorrow's appointment" \
--must-contain "appointment" \
--must-not-contain "I cannot help" \
--judge-criteria "The reply offers a concrete next step" \
--i-understand-pii \
--env myorg
```
Forge requests a final, filler-free reply. If background work is still pending, it does not grade the interim acknowledgement; use `conversation poll` to claim the completed reply.
The Go binary still registers `forge platform conversation text-ws-smoke` as a deferred placeholder and does not run the WebSocket test. Use the REST `send-message` flow above, connect through the documented [Sessions WebSocket](https://docs.amigo.ai/developer-guide/platform-api/platform-api/sessions) directly, or use the legacy Python command described in its tab.
#### Unified Runs
`forge platform run` is the canonical read surface across conversation runs and framework runs. It uses the same channel-neutral run identifiers as the Developer Console Runs page.
| Command | Description |
| ---------------------------- | ----------------------------------------------------------------------------------- |
| `forge platform run list` | List runs with kind, channel, and status filters plus continuation-token pagination |
| `forge platform run summary` | Show aggregate totals, live counts, status counts, and kind counts |
| `forge platform run get` | Retrieve one run by its channel-neutral run ID |
```bash
forge platform run list --kind conversation --channel voice --status live --env myorg
forge platform run summary --kind conversation --env myorg
forge platform run get --env myorg
```
Use `conversation` for conversation-specific create, send, poll, and close operations. Use `run` to inspect conversations and retained framework history. Hosted framework-run dispatch is retired; `agent-run harness-context` remains a separate read-only capability. See [Runs](https://docs.amigo.ai/developer-guide/platform-api/conversations/runs) in the developer guide.
#### Tool Testing
The `forge platform tool-test` commands let you test context graph tools without making phone calls:
| Command | Description |
| ---------------------------------- | --------------------------------------------------------------- |
| `forge platform tool-test resolve` | List available tools for a service with input schemas |
| `forge platform tool-test execute` | Execute a tool with custom parameters and optional dry run mode |
#### Trigger Management
The `forge platform triggers` command group manages action automations that run on a schedule, in response to supported platform events, or through a manual fire.
| Command | Description |
| -------------------------------- | ---------------------------------------------------------------------------- |
| `forge platform triggers create` | Create a trigger with an action binding and schedule or supported event type |
| `forge platform triggers list` | List triggers with active/inactive filtering |
| `forge platform triggers get` | Get trigger details including next fire time |
| `forge platform triggers update` | Update trigger configuration |
| `forge platform triggers delete` | Delete a trigger |
| `forge platform triggers pause` | Pause a trigger's schedule |
| `forge platform triggers resume` | Resume a paused trigger |
| `forge platform triggers fire` | Manually fire a trigger for testing |
| `forge platform triggers runs` | View trigger execution history |
Scheduled triggers use cron expressions. Event-based triggers match a supported world-model event and can narrow matches with an event filter. Manual fires use the same durable execution path, which makes them useful for testing a trigger before activation. See [Outbound](/channels/outbound) for how triggers fit into automated contact patterns.
#### Platform Functions
The `forge platform function` command group manages platform functions - declarative SQL, Python, AI, and table-valued (UDTF) functions that agents can call mid-conversation. Table-valued functions return rows rather than a single value.
| Command | Description |
| ---------------------------------- | ------------------------------------------------------------------ |
| `forge platform function register` | Register a new platform function with its definition and metadata |
| `forge platform function list` | List all registered functions in the workspace |
| `forge platform function test` | Execute a function with test parameters and inspect the result |
| `forge platform function delete` | Remove a function registration |
| `forge platform function query` | Run an open-scope SQL query against workspace data |
| `forge platform function catalog` | Display the full function catalog with signatures and descriptions |
| `forge platform function sync` | Sync function definitions between local files and the platform |
See [Platform Functions](/agent/platform-functions) for conceptual background.
### CLI Updates
The Go binary ships a built-in self-update command (macOS) that upgrades the binary in place:
```bash
forge update # download and install the latest release
forge update --check # report whether an update is available; install nothing
forge update --version 1.4.2 # pin an exact release (up- or down-grade)
```
Here `forge update` resolves the target version, downloads the release for your Mac's architecture from the same Forge CDN the installer uses, verifies its SHA256 checksum, sanity-checks the downloaded binary before swapping it, and atomically replaces the running binary in place. The download always comes from the immutable, version-pinned release path, so a publish in progress can never mix generations mid-download.
| Flag | Purpose |
| ------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- |
| `--check` | Report whether an update is available and exit without downloading or writing anything. |
| `--version ` | Install this exact release instead of the latest, up- or down-grade. A downgrade below the installed version prompts for confirmation first. |
| `--force` | Reinstall even when already up to date, overwrite a locally built `dev` binary, and skip the downgrade confirmation prompt. |
| `--yes`, `-y` | Skip the downgrade confirmation prompt for non-interactive or scripted use. |
If the install directory is not writable (for example, `forge` lives in `/usr/local/bin`), `update` fails with guidance to re-run as `sudo forge update` rather than silently escalating privileges. On Linux, reinstall from your organization's release channel to upgrade.
{% endtab %}
{% tab title="Python CLI (legacy)" %}
{% hint style="warning" %}
The Python CLI is the legacy build and is being retired. Prefer the **Go CLI** (see the other tab) for all new work. Use the Python build only if you depend on one of the legacy-only commands listed below that has not yet been ported to the Go binary.
{% endhint %}
The Python CLI shares the Platform API command surface with the Go build - `auth`, `validate`, `forge platform push`, and the `forge platform` resource groups for agents, context graphs, services, skills, functions, conversations, tool tests, simulation, surfaces, and integrations. For those, follow the **Go CLI** tab; the syntax is the same. In addition, because the Python build also supports the Classic API, it offers the legacy `sync-to-local` / `sync-to-remote` workflow against the legacy backend. This tab documents what is different in the Python build.
### Installation
The Python CLI is not a standalone binary - it runs from a git checkout with a full Python runtime, managed by Poetry.
1. Install Python 3.13 (the repo pins `3.13.5`, e.g. via `pyenv install 3.13.5`).
2. Install [Poetry](https://python-poetry.org/) 2.x.
3. From the repo root, install dependencies and activate the environment:
```bash
poetry install
$(poetry env activate)
```
Commands run as `poetry run forge ...` (or just `forge ...` inside the activated environment). Because the tool runs from a checkout, it must be invoked from the repository root.
### Authentication
Unlike the Go build, the Python CLI supports **both** the Classic API (legacy backend) and the Platform API. The `--platform` flag selects which surface a command targets - omit it for the Classic API, pass it for the Platform API. Both use device code login and static API keys. Configuration is read from `.env.` (Classic API) and `.env.platform.` (Platform API) files. For the Platform-API authentication details (device code flow, environment variables), see the **Go CLI** tab.
### Command-name differences
The command groups are largely identical to the Go build, with a few naming differences to watch for:
* The trigger group is `forge platform trigger` (singular) in the Python CLI, versus `forge platform triggers` (plural) in the Go CLI.
### Legacy-only commands
The following commands are implemented in the Python build only. They are recognized but not yet functional in the Go binary, so if you rely on any of them, use the Python CLI until they are ported.
#### Analytics (`forge analyze`)
The `forge analyze` command group provides SQL-based exploration of workspace data directly from the CLI, replacing the need for external analytics tools.
| Command | Description |
| ------------------------ | ------------------------------------------------------------------------------------------------------------- |
| `forge analyze query` | Execute ad-hoc SQL SELECT queries (inline or from file). Results are capped and queries are time-bounded. |
| `forge analyze describe` | Preview a query's output schema without executing it - useful for validating JOINs and checking column types. |
| `forge analyze tables` | List available tables in the workspace schema. Supports SQL LIKE patterns for filtering. |
| `forge analyze schema` | Describe a table's columns: names, data types, and comments. |
| `forge analyze sample` | Preview sample rows from a table (default 5, max 20). |
| `forge analyze detail` | Rich table metadata: row count, size, partitioning, column nullability, data freshness. |
| `forge analyze profile` | Profile a column's data distribution: cardinality, null rate, min/max values. |
| `forge analyze catalog` | Display the full data catalog reference offline without a database connection. |
Pre-built analytics query templates cover common patterns like conversation volume, tool performance, and metric trends:
```bash
# List templates
forge analyze template list
# Run a template with parameters
forge analyze template run conversation-volume -P days=7
```
#### Insights (`forge platform insights`)
The `forge platform insights` command group provides conversational data exploration from the CLI, wrapping the platform's [Insights Agent](/intelligence-and-analytics/intelligence/analytics-dashboards#insights-agent) capabilities - workspace queries, schema metadata, and health digests.
| Command | Description |
| ------------------------------------- | ------------------------------------------------------------------------------------------------------------ |
| `forge platform insights sql` | Execute a SQL query against workspace data and return formatted results |
| `forge platform insights schema` | Describe available tables, columns, and functions in the workspace schema |
| `forge platform insights digest` | Generate an AI-powered digest summarizing recent workspace activity, entity counts, and data quality signals |
| `forge platform insights suggestions` | Get suggested starter questions based on the workspace's data and recent activity |
```bash
# Execute a SQL query against the workspace data warehouse
forge platform insights sql "SELECT ..." --env myorg
# Read SQL from a file
forge platform insights sql --sql-file my_query.sql --env myorg --json
# List available tables, columns, and functions
forge platform insights schema --env myorg
# Get a workspace health digest with entity counts and data quality signals
forge platform insights digest --env myorg
# Get suggested starter questions for exploring workspace data
forge platform insights suggestions --env myorg
```
#### Call Trace Analysis (`forge platform trace`)
The `forge platform trace` command group provides call trace analysis from the CLI, wrapping the platform's [trace analysis](/intelligence-and-analytics/intelligence/call-intelligence#call-trace-analysis) capabilities - deep call understanding from the intelligence pipeline.
| Command | Description |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
| `forge platform trace list` | List call traces with filters for date range, service, quality score, outcome, and direction |
| `forge platform trace get` | Get detailed trace analysis for a specific call, including emotional arc, decision moments, component attribution, and coaching recommendations |
```bash
# List recent trace analyses
forge platform trace list --env myorg
# Filter by outcome and lookback window
forge platform trace list --outcome failed --days 7 --env myorg
# Get detailed trace analysis for a specific call
forge platform trace get --env myorg
```
Trace analysis provides:
* **Emotional arc** - How caller sentiment evolved across the conversation
* **Key decision moments** - Critical points with quality assessment and causal attribution
* **Coaching recommendations** - Actionable improvements tied to specific call moments
* **Counterfactuals** - Alternative actions that could have changed the outcome
* **Signal-response alignment** - Whether the agent responded appropriately to caller signals
* **Interaction dynamics** - Turn-taking quality, rapport trajectory, and repair effectiveness
Trace output uses rich formatting with colored outcome indicators and structured digest sections for quick scanning of call quality issues.
#### Conversation Quality Check
The `forge quality check` command scans workspace conversations for agent behavioral issues - stuck loops, degenerate output, repetition, and other quality problems. It queries production conversation data directly and runs pattern-based detectors to surface problematic interactions.
```bash
# Scan last 24 hours
forge quality check
# Wider window with message snippets
forge quality check --days 7 --verbose
# Structured output for scripting
forge quality check --json
```
| Detector | What It Finds |
| -------------------------- | ------------------------------------------------------------------------------------------ |
| **Character degeneration** | Repeated characters, low entropy output, stuttering patterns |
| **Stuck agent loops** | Agent repeats the same response while the caller changes topics |
| **Repetitive patterns** | High similarity across sliding message windows |
| **Word salad** | Incoherent output patterns like or-chains and excessive word repetition |
| **Phantom success** | Agent claims a tool call succeeded when the tool actually returned an error |
| **Wrong tool inputs** | A tool is called with parameters that do not match what the caller actually asked for |
| **Ungrounded claims** | The agent asserts capabilities or facts not supported by the configured entity definitions |
| **Safety / PII** | The agent leaks sensitive information or provides unsafe guidance |
Some detectors (phantom mismatch, wrong tool inputs, ungrounded claims, and safety/PII) require an LLM key to run.
Results include conversation IDs, timestamps, detector names, and severity. Use `--verbose` to see the actual message excerpts that triggered each finding.
See [Voice Simulation](/testing/testing/voice-simulation) and [Drift Detection](/testing/testing/drift-detection) for related quality monitoring capabilities.
#### Metrics Management (`forge platform metrics`)
The legacy Python CLI exposes workspace metric settings and current metric reads. Use only commands backed by the current Platform API:
| Command | Description |
| ------------------------------------------- | ---------------------------------------------------------- |
| `forge platform metrics settings` | View built-in and custom workspace metric definitions |
| `forge platform metrics define` | Replace the custom definitions supplied in a JSON document |
| `forge platform metrics list` | List current metric values |
| `forge platform metrics catalog` | List active built-in and custom catalog entries |
| `forge platform metrics get ` | Read values for one metric |
| `forge platform metrics trend ` | Read a metric time series |
```bash
# View current metric settings
forge platform metrics settings --env myorg
# Define a metric
forge platform metrics define --file metric-definitions.json --env myorg
# Read one metric's recent trend
forge platform metrics trend scheduling_success --days 14 --env myorg
```
The Python CLI still registers `metrics freshness` and `metrics evaluate`, but the current Platform API has no dedicated metric-freshness or generic metric-evaluate route. Do not use those commands. The embedded [production-eval operation](https://docs.amigo.ai/developer-guide/platform-api/safety/production-evals#evaluating-a-call) is separate: it runs active eval definitions and persists their verdicts.
#### Coverage-Optimized Simulation (`forge simulation`)
In addition to the `forge platform sim` and `forge platform simulation` groups shared with the Go build, the Python CLI has a top-level `forge simulation` group that provides coverage-optimized simulation testing against context graphs. It automatically steers simulated conversations toward unvisited states, behaviors, and tools to maximize test coverage.
Each simulation turn follows a scoring loop:
1. The platform generates recommended user responses (graph-unaware)
2. An LLM classifier predicts which state each response would transition to
3. A scorer ranks responses by expected coverage value using graph structure
4. The highest-scoring response is sent as the simulated user message
5. Coverage state is updated based on the agent's response
| Command | Description |
| --------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `forge simulation run` | Execute a simulation with configurable sessions, turn budgets, and coverage targets |
| `forge simulation plan` | Generate a target spec from a natural-language objective (e.g., "test the cancellation flow end-to-end") |
| `forge simulation bridge` | Generate scenario variations from a natural-language objective, run multi-turn conversations with LLM-driven personas, and track coverage using interaction insights |
| `forge simulation evaluate` | Compare metric scores across simulation runs, including before/after diff mode |
| `forge simulation cleanup` | Delete ephemeral test users created by simulation runs |
Simulations are highly configurable:
| Setting | Default | Description |
| --------------- | ---------- | -------------------------------------------------------------------------------------------------------- |
| **Sessions** | 3 | Number of parallel conversations |
| **Max turns** | 20 | Maximum turns per session |
| **Budget** | 100 | Total turn budget across all sessions |
| **Algorithm** | `frontier` | Scoring algorithm: `frontier`, `heatmap`, or `random` |
| **Temperament** | `random` | Simulated user personality: `cooperative`, `neutral`, `frustrated`, `confused`, `skeptical`, or `random` |
The `forge simulation bridge` command combines scenario generation with multi-turn conversation execution. You describe what you want to test in natural language, and the bridge generates diverse scenario variations, runs each as a full conversation with an LLM-driven persona, and collects interaction insights after every turn for coverage tracking.
```bash
# Generate and run 5 scenarios testing cancellation handling
forge simulation bridge --service "Scheduling" --objective "test cancellation edge cases" --scenarios 5 --env staging
```
Simulation bridge results are persisted locally across runs, enabling trend analysis and regression detection. Tag scenarios for selective execution (for example, `forge simulation bridge --tag scheduling`) to build a reusable test library that grows over time.
#### Streaming text smoke test (`forge platform conversation text-ws-smoke`)
The legacy Python command opens the Platform Sessions WebSocket, sends one message, and waits for the agent response. It requires an entity ID for context and accepts service, message, and conversation options. This command is not yet implemented in the Go binary; use it only when the legacy Python CLI is already part of your workflow.
#### Changelog (`forge changelog`)
The `forge changelog show` command provides cross-entity change traceability - tracking what changed across agents, context graphs, behaviors, and metrics over time. This gives teams visibility into configuration drift without relying on external version control tooling.
### CLI Updates
The Python build updates itself from its git checkout rather than downloading a binary. It checks `origin/main` in the background (throttled) and, when updates are available, prompts before applying them. You can also update manually:
```bash
forge update
```
When updates are applied, uncommitted local changes are stashed during the update and restored afterward. If dependencies changed, `poetry install` is re-run automatically and the original command is re-executed.
{% endtab %}
{% endtabs %}
## Coding Agent Skills
The `amigo-forge` plugin is a public skill marketplace for Codex and [Claude Code](https://docs.claude.com/en/docs/claude-code/overview). It lets your coding agent drive the `forge` CLI for you. Instead of remembering command syntax, you describe what you want in plain language - "scope this agent before I build it", "validate my entity JSON", "run regression sims before I promote" - and the agent picks the matching skill and runs it against the `forge` binary you already have installed. The skills drive your local binary; they do not ship or install it.
The marketplace lives in the public [`amigo-ai-solutions/forge-skills`](https://github.com/amigo-ai-solutions/forge-skills) repository and requires `forge` version 0.1.23 or newer on your PATH.
### Install
Codex:
```bash
# Add the marketplace (one time)
codex plugin marketplace add amigo-ai-solutions/forge-skills
```
Then open Codex, run `/plugins`, choose the **Amigo Forge** marketplace, and install the `forge` plugin.
Claude Code:
```bash
# Add the marketplace (one time)
claude plugin marketplace add amigo-ai-solutions/forge-skills
# Install the forge plugin
claude plugin install forge@amigo-forge
```
List installed skills and plugins with `/plugins` in Codex or `/plugin` in Claude Code.
### Available Skills
| Skill | Use it to |
| -------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `forge-agent-design` | Scope an agent before building - decide where each piece of complexity belongs (a deterministic function, a context graph state, an isolated skill, a router, or multiple agents). Start here. |
| `forge-build-agent` | Stand up the entities end to end: functions, then a context graph, the agent, skills, a service, and a pinned version set. |
| `forge-validate` | Run the local, no-auth pre-push validation gate over your entity JSON. |
| `forge-sync` | Read, edit, validate, and deploy entity data through `forge platform` commands - pull with `get`, then push with a dry run first, then apply. |
| `forge-simulate` | Regression-test and prove parity before promoting a version set, keeping a rollback path. |
In any Forge project, describe what you want and the coding agent selects the matching skill. You can also invoke a skill explicitly:
```
# Codex
$forge-agent-design
# Claude Code
/forge:forge-agent-design
```
### Keeping Skills Up to Date
Codex loads new skill versions after the marketplace catalog is refreshed and the installed plugin is updated. Refresh the marketplace catalog from a shell:
```bash
codex plugin marketplace upgrade amigo-forge
```
Then open `/plugins`, update the installed `forge` plugin if prompted, and start a new thread so Codex reloads the plugin instructions.
Claude Code auto-update is off by default for third-party marketplaces. Turn it on from `/plugin` > **Marketplaces** > `amigo-forge` > **Enable auto-update** so Claude Code refreshes the catalog and updates the plugin at startup. To update by hand, refresh the catalog and then update the plugin:
```bash
# Refresh the marketplace catalog
claude plugin marketplace update amigo-forge
# Update the installed plugin to the catalog's latest version
claude plugin update forge@amigo-forge
```
Run `/reload-plugins` afterward to activate the new version in the current session without restarting.
## Typical Workflow
1. **Pull current configurations** from the platform to your local environment.
2. **Make changes** to the JSON configuration files.
3. **Push to staging** and run your test sets to validate.
4. **Review results** and iterate if tests fail.
5. **Promote to production** after validation passes.
This workflow supports both manual changes and automated optimization. Teams can use Agent Forge directly for planned configuration updates, or set up automated pipelines that use Agent Forge to deploy and test changes as part of a continuous improvement process.
## When to Use Agent Forge
* **Managing configurations across environments**: Keep staging and production in sync with a controlled promotion process.
* **Bulk updates**: Modify multiple agents, behaviors, or evaluation criteria in a single operation.
* **Scripted deployments**: Integrate Agent Forge into CI/CD pipelines for automated testing and deployment.
* **Audit and rollback**: Maintain a complete history of configuration changes with the ability to revert.
* **Building agents from scratch**: Use Platform API commands to create agents, context graphs, and services entirely from the CLI.
* **Coverage testing**: Run simulation tests that automatically explore unvisited states and edge cases.
{% hint style="info" %}
Use the [Platform API developer guide](https://docs.amigo.ai/developer-guide/platform-api/platform-api) for setup, authentication, and workspace configuration details. This reference page covers the Agent Forge command surface.
{% endhint %}
# Performance Characteristics
How to interpret voice latency, scaling, emotion-analysis windows, API rate limits, and post-call processing behavior.
Operational characteristics for major platform subsystems. Unless a customer agreement says otherwise, the values on this page describe runtime controls or API limits rather than a service-level agreement.
## Voice Pipeline Latency
The voice pipeline prepares first audio before or during conference setup where the call flow allows it, then records latency at multiple boundaries. It does not publish one universal first-message or speech-recognition latency guarantee.
End-to-end turn latency varies with the selected models, speech providers, tool dispatch mode, external integrations, audio quality, and network path. Per-call summaries expose observed engine and audio time-to-first-byte measurements rather than relying on one platform-wide average. [Filler speech](/channels/voice/audio-pipeline) can acknowledge some processing gaps, and [prompt caching](/platform-overview/cost-and-latency) can reduce repeated prompt processing where the selected model path supports it.
### Per-Turn Processing Layers
The platform-managed speech-to-text and text-to-speech path has five processing layers. Provider-owned speech-to-speech sessions use a different path; see [Audio Pipeline](/channels/voice/audio-pipeline).
| Layer | What Happens |
| ---------------------- | ------------------------------------------------------------------------------------- |
| **STT processing** | Audio converted to transcript text |
| **Engine** | Context graph navigation, state guidance, tool selection, and selected memory context |
| **Render** | LLM generates response text with emotional context |
| **TTS generation** | Text converted to speech audio with emotion parameters |
| **Transport delivery** | Audio delivered to the telephony layer |
## Scaling and Recovery
The voice runtime scales horizontally, but this documentation does not publish a universal workspace concurrency ceiling or throughput commitment. Capacity depends on the deployed region, voice path, provider quotas, and customer configuration.
On checkpointed connector paths, ingestion resumes from committed source progress, allowing later polls to recover eligible inbound changes. Automated outbound writes report failures and do not receive automatic reconciliation; approved idempotent proposals may retry under their separate delivery policy.
## Emotion Detection
| Parameter | Value |
| ------------------------------- | ------------------------------------------------------------------------------------------------------------------------ |
| **Acoustic outputs** | Nine categorical scores plus dimensional valence and arousal |
| **Audio segment size** | 2 seconds of voiced audio; sub-threshold silence is skipped |
| **Rolling state** | 4 recent segments, approximately 8 seconds, with linear recency weighting |
| **Rolling dimensions** | Valence and arousal; dominance is not retained as an agent decision signal |
| **Transcript analysis** | Sentiment and toxicity, processed asynchronously |
| **Speaker profile warmup** | 5 analyzed segments, approximately 10 seconds of voiced audio; observer data only |
| **Compound window** | 5 caller turns |
| **Empathy tier classification** | Rule-based with no additional model call |
| **Failure behavior** | Analysis is best-effort and optional to the live reasoning path; repeated stream failures can disable it for the session |
## API Rate Limits
Platform API routes attach rate-limit policies individually. The following are current common policies, not a substitute for the contract and response headers on a specific endpoint:
| Operation | Limit | Scope |
| -------------------------------- | --------- | ------------------------ |
| **Outbound call creation** | 1,000/min | Per credential and route |
| **Conversation creation** | 60/min | Per credential and route |
| **Common write policy** | 10/min | Per credential and route |
| **Common read policy** | 60/min | Per credential and route |
| **Default authenticated policy** | 100/min | Per credential and route |
Outbound call creation has a higher route-specific limit for campaign and outreach fan-out. Rate-limit responses include `Retry-After`, `X-RateLimit-Limit`, `X-RateLimit-Remaining`, and `X-RateLimit-Reset`; clients should use those values rather than infer remaining capacity from a local counter.
Separately from rate limits, each workspace can register up to 100 test caller numbers.
## End-of-Turn Detection
End-of-turn controls can be set at the service level and, on compatible recognition paths, overridden by a context graph state's turn policy. The thresholds balance responsiveness against the risk of cutting off a caller. Provider support and the speaking patterns of the target population determine useful settings.
## Post-Call Processing
When transcript verification is enabled and a recording exists, an asynchronous job can create a second caller transcript with word timing and compare it with the live transcript. The result and comparison evidence are stored when processing succeeds. This optional artifact is not guaranteed for every call, is not guaranteed ground truth, and does not automatically replace transcription configuration or update keyterms.
# Welcome
Choose the correct Amigo API, configure credentials and region, and follow implementation guides for data, agents, channels, and operations.
Build an integration with Amigo using the API and credentials assigned to your deployment. This guide connects setup, SDK examples, and endpoint contracts to the workflow you want to implement.
For the system model and deployment responsibilities, start with [Core Concepts](https://docs.amigo.ai/platform-overview/core-concepts) and [Operating Model](https://docs.amigo.ai/platform-overview/operating-model). For generated operation and schema references, use the [API Reference](https://docs.amigo.ai/api-reference).
## Choose a Task
| Goal | Start here |
| ------------------------------------------ | --------------------------------------------------------------------------------------------------------- |
| Evaluate architecture and deployment fit | [Technical evaluation packet](https://docs.amigo.ai/platform-overview/evaluation-packet) |
| Build a first Platform integration | [First Verified Conversation](/developer-guide/guides/first-verified-conversation) |
| Choose Platform, Classic, or Scribe access | [Choose Credentials](/developer-guide/getting-started/credentials) |
| Verify an action or managed channel | [Task guides](/developer-guide/guides) |
| Investigate an incomplete result | [Troubleshooting](/developer-guide/guides/troubleshooting) |
| Plan an upgrade | [Current integration and upgrade guidance](https://docs.amigo.ai/api-reference/change-logs/upgrade-guide) |
## Quick Start
Choose your API before installing a client or copying a request. Both APIs support conversational workflows; the distinction is their resource and authentication contracts, not simply text versus voice.
{% tabs %}
{% tab title="Platform API" %}
Use the workspace-scoped Platform API for deployed agent workflows, shared world-model data, supported voice and messaging channels, integrations, and operator controls.
1. Confirm the workspace ID and [regional endpoint](/developer-guide/getting-started/regions-and-endpoints).
2. Configure the [credential accepted by your route](/developer-guide/platform-api/platform-api/authentication).
3. Install the [Platform TypeScript SDK](/developer-guide/platform-api/platform-sdk/installation), or use the HTTP examples in the resource guides.
4. Run the [SDK quickstart](/developer-guide/platform-api/platform-sdk/quickstart) to inspect your workspace before creating or changing resources.
5. Follow [Build and Prove](/developer-guide/guides/build-and-prove), then [Operate and Improve](/developer-guide/guides/operate-and-improve).
{% endtab %}
{% tab title="Classic API" %}
Use the organization-scoped Classic API for integrations built around Classic users, services, conversation event streams, Actions, and Dynamic Behaviors.
1. Confirm the organization ID, user ID, and [regional endpoint](/developer-guide/getting-started/regions-and-endpoints).
2. Set up the [Classic API key-to-token exchange](/developer-guide/getting-started/authentication).
3. Install a [Classic SDK](/developer-guide/classic-api/sdks/sdk-installation): `amigo-sdk` for Python or `@amigo-ai/sdk` for TypeScript.
4. Run [Hello World](/developer-guide/classic-api/sdks/sdk-hello-world), including incremental handling of conversation events.
5. Continue with the [Classic resource guide](/developer-guide/classic-api/core-api).
{% endtab %}
{% endtabs %}
## API Comparison
| Decision | Platform API | Classic API |
| ------------------ | ------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| Resource boundary | Workspace for workspace-scoped resources; some identity and management routes have other scopes | Organization and authenticated user |
| Credential flow | Workspace keys, interactive identity credentials, or scoped OAuth credentials on their supported routes | API key credentials exchanged for a user bearer token |
| Conversation paths | Text turns, persistent sessions, phone calls, and managed messaging with channel-specific lifecycles | Conversation create/interact streams, voice notes, and supported realtime paths |
| Agent capabilities | Context Graph tool bindings, Skills, platform functions, and integrations | Versioned Tools/Actions and Dynamic Behaviors |
| Client packages | `@amigo-ai/platform-sdk` | `@amigo-ai/sdk`, `amigo-sdk` |
Shared names such as service, agent, or version set do not make IDs, credentials, payloads, or SDK methods interchangeable. [Core Concepts](/developer-guide/getting-started/core-concepts) maps each resource to its owning API.
### System Architecture
For a workflow that crosses data retrieval, agent execution, an external action, and human follow-up, read [How It Works](https://docs.amigo.ai/platform-overview/how-it-works). This guide owns the implementation details for those boundaries.
## Documentation Structure
[Guides](/developer-guide/guides) follow the customer workflow: Build, Prove, Operate, Improve, Data, and Govern. [Scribe](/developer-guide/guides/scribe-capture-to-note) has its own provider workflow. Use [Compatibility and Retirements](/developer-guide/guides/compatibility-and-retirements) for Classic setup and removed interfaces.
| Your next task | Start here |
| ------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Establish credentials and regional routing | [Getting Started](/developer-guide/getting-started) |
| Configure agents, services, and version selection | [Platform resources](/developer-guide/platform-api/platform-api) or [Classic resources](/developer-guide/classic-api/core-api) |
| Build a specific workflow | [Guides](/developer-guide/guides) |
| Use a typed client | [Platform SDK](/developer-guide/platform-api/platform-sdk) or [Classic SDKs](/developer-guide/classic-api/sdks) |
| Connect workspace data and external systems | [Data & World Model](/developer-guide/platform-api/data-world-model) and [Integrations](/developer-guide/platform-api/integrations) |
| Query Classic organization data | [Data Access](/developer-guide/classic-api/data-access) |
| Inspect runtime outcomes | [Runs](/developer-guide/platform-api/conversations/runs), [Operators](/developer-guide/platform-api/conversations/operators), and [Safety & Monitoring](/developer-guide/platform-api/safety) |
| Maintain an existing deployment | [Best Practices](/developer-guide/operations/devops), with each page's API and CLI scope |
| Check terminology or compatibility | [Reference](/developer-guide/operations/reference) and [Change Logs](https://docs.amigo.ai/api-reference/change-logs) |
## Support and Resources
Use the public schema embedded in each endpoint section for its request and response contract. The surrounding prose explains authorization, lifecycle, failure handling, and availability that a schema alone cannot establish. WebSocket and separately served routes identify their own protocol or schema boundary.
For deployment-specific access and support, contact your Amigo representative through your agreed support channel. Report SDK issues in the relevant package repository: [Platform TypeScript](https://github.com/amigo-ai/amigo-platform-typescript-sdk/issues), [Classic TypeScript](https://github.com/amigo-ai/amigo-typescript-sdk/issues), or [Classic Python](https://github.com/amigo-ai/amigo-python-sdk/issues).
# Getting Started
Establish your API, tenant boundary, credentials, and regional endpoint, then validate a first read before building an Amigo workflow.
For a new Platform project, follow the workspace setup and verified conversation path below. If you maintain an existing Classic integration or use Scribe, choose its separate credential flow in [Choose Credentials](/developer-guide/getting-started/credentials). Channel provisioning, data connections, and a configured service are additional prerequisites for a working agent interaction.
## Build Your First Project
[First Verified Conversation](/developer-guide/guides/first-verified-conversation) provides a pinned TypeScript project, a local fixture walkthrough, and a provisioned Platform test-service path. It verifies a durable answer and cleanup, then demonstrates a rejected request. Its access checklist makes the setup dependencies explicit.
## Prerequisites
| Confirm with your implementation team | Platform API | Classic API |
| ------------------------------------- | ---------------------------------------------------------------------------- | ---------------------------------------------------------------- |
| Tenant boundary | Workspace ID for workspace resources | Organization ID and the user represented by the credential |
| Endpoint | Assigned Platform regional hostname | Assigned Classic regional hostname |
| Credential | Workspace key or the scoped token required by the chosen route | API key, key ID, and user ID for the token exchange |
| Workflow configuration | Service, selected versions, eligible tools, and the required channel binding | Service, selected version set, and the relevant user permissions |
Keep long-lived credentials in your backend or secret manager. Browser and external-user workflows need their documented access boundary; publishing a workspace key in a client bundle does not create one.
## Essential Reading
1. [Core Concepts](/developer-guide/getting-started/core-concepts) maps the resource names and boundaries.
2. [Regions & Endpoints](/developer-guide/getting-started/regions-and-endpoints) explains hostname selection.
3. [Choose Credentials](/developer-guide/getting-started/credentials) identifies the caller, tenant, and accepted authentication flow.
4. [Govern a Deployment](/developer-guide/guides/govern-a-deployment) records channel, feature, and regional prerequisites.
## Build Your First Application
{% tabs %}
{% tab title="Platform" %}
1. [Install the Platform SDK](/developer-guide/platform-api/platform-sdk/installation).
2. [Configure the client](/developer-guide/platform-api/platform-sdk/configuration) with the assigned workspace and regional hostname.
3. Run the read-only listing example in the [Quickstart](/developer-guide/platform-api/platform-sdk/quickstart).
4. Choose an explicitly configured test service before starting a conversation or simulation. Review its data access and integration actions as well as its agent instructions.
5. Use [Conversations](/developer-guide/platform-api/conversations) to choose the channel and lifecycle required by your application.
{% endtab %}
{% tab title="Classic" %}
1. [Install a Classic SDK](/developer-guide/classic-api/sdks/sdk-installation).
2. [Configure the client](/developer-guide/classic-api/sdks/sdk-configuration) for the correct organization and user.
3. Follow [Hello World](/developer-guide/classic-api/sdks/sdk-hello-world) to create a conversation and consume its event stream.
4. Handle stream errors and completion explicitly, then apply the [conversation lifecycle](/developer-guide/classic-api/core-api/conversations/conversations-lifecycle) appropriate to your application.
{% endtab %}
{% endtabs %}
## Key Resources
A successful authenticated read confirms access to that operation. It does not establish that a channel is provisioned, source data is ready, or a workflow can complete an external action.
Continue with [Guides](/developer-guide/guides) for implementation paths. Use [Evaluating Amigo](https://docs.amigo.ai/platform-overview/evaluating-amigo) to define the evidence for a broader technical evaluation, and the [API Reference](https://docs.amigo.ai/api-reference) to inspect operation schemas.
# Core Concepts
Map Amigo's conceptual model to Platform and Classic resources, keeping authentication, version selection, conversations, and evidence distinct.
The two APIs use some of the same product names, but each has its own identifiers, credentials, payloads, and lifecycle rules. Use this map to find the correct implementation contract. For the relationships between data, configuration, execution, and evidence, read the conceptual [Core Concepts](https://docs.amigo.ai/platform-overview/core-concepts).
## Platform API
### Setup
| Concept | Implementation role | Continue here |
| ---------------------------- | ---------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------- |
| Workspace | Boundary for workspace resources, data, and access; account and identity routes have their own scope | [Workspaces](/developer-guide/platform-api/workspaces) |
| Agent | Versioned identity, general guidance, and communication style | [Agents](/developer-guide/platform-api/workspaces/agents) |
| Context Graph | Authored states, transitions, objectives, and state tool bindings; the service selects the graph used at runtime | [Context Graphs](https://docs.amigo.ai/agent/context-graphs) |
| Skill | A companion definition with its own prompt and declared tools; the state binding governs execution and result handling | [Skills](/developer-guide/platform-api/workspaces/skills) |
| Service and version set | Deployment configuration and the selected component versions and supported preferences | [Services](/developer-guide/platform-api/workspaces/services) |
| Channel use case and binding | Provisioned channel route connected to the service that handles it | [Use Cases & Bindings](/developer-guide/platform-api/workspaces/use-cases) |
A version selection is not a separate tenant or a snapshot of all source data. Agent and Context Graph instructions guide model behavior; authorization and tool validation enforce operation boundaries.
### Voice and Operations
| Concept | Implementation role | Continue here |
| ------------ | ------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------ |
| Conversation | Interaction history and lifecycle on a supported channel | [Conversations](/developer-guide/platform-api/conversations) |
| Session | Runtime context and protocol for processing an interaction; resumption and configuration loading depend on the path | [Sessions](/developer-guide/platform-api/platform-api/sessions) |
| Run | Channel-neutral inventory and detail for supported execution records | [Runs](/developer-guide/platform-api/conversations/runs) |
| Operator | An authorized person using the controls supported by the channel | [Operators](/developer-guide/platform-api/conversations/operators) |
Platform supports text and messaging as well as phone calls. Operator joining on the current voice path uses a phone number; browser microphone joining has been removed. Listen, takeover, handback, external transfer, and integration-write approval are distinct operations.
### Data
| Concept | Implementation role | Continue here |
| ---------------- | ----------------------------------------------------------------------------- | ----------------------------------------------------------------------------------- |
| World model | Source-attributed observations, entities, and derived read views | [Data & World Model](/developer-guide/platform-api/data-world-model) |
| Connector | Supported source ingestion and separately controlled outbound delivery | [Connector Runner](/developer-guide/platform-api/data-world-model/connector-runner) |
| Intake | Authenticated submission to supported dataset sources | [Customer Data Intake](/developer-guide/platform-api/data-world-model/intake) |
| Generated memory | Bounded observations and narrative context derived from previous interactions | [Memory](https://docs.amigo.ai/agent/memory) |
Event acceptance, projection freshness, generated memory, and external delivery have different lifecycles. A recognized caller binding can locate an entity; it does not replace the verification required by the workflow.
## Classic API
### Setup
The Classic API scopes resources to an organization and acts through an authenticated user. A service and its selected version set determine the configured agent experience. Classic Tools, also called Actions, are versioned code packages. Dynamic Behaviors are a separate Classic feature; they are not Platform Skills or Platform triggers.
Continue with [Services](/developer-guide/classic-api/core-api/services), [Agents & Context Graphs](/developer-guide/classic-api/core-api/agents-and-context-graphs), [Tools](/developer-guide/classic-api/core-api/tools), and [Dynamic Behaviors](/developer-guide/classic-api/core-api/dynamic-behaviors).
### Users
A Classic user has an identifier, role-based permissions, and associated context. A user model is generated or maintained context used for personalization; it is not an authoritative copy of every clinical or scheduling fact.
See [Users](/developer-guide/classic-api/core-api/users), [User Models](/developer-guide/classic-api/core-api/users/user-models), and [Permissions](/developer-guide/classic-api/permissions).
### Conversations
Classic conversation creation and interaction use incremental NDJSON event streams on their streaming paths. A conversation contains interactions and retained messages. Consumers must process the documented event variants, distinguish errors from completion, and finish or resume the conversation under the relevant lifecycle contract.
Voice-note and realtime paths have their own media and protocol rules. See [Conversations](/developer-guide/classic-api/core-api/conversations), [Events](/developer-guide/classic-api/core-api/conversations/conversations-events), and [Lifecycle & Finish](/developer-guide/classic-api/core-api/conversations/conversations-lifecycle).
## Choosing the Right Contract
Use the API named in your service configuration and integration agreement. Do not assume a shared concept name implies shared storage, automatic migration, credential compatibility, or the same event format. [Terminology Mapping](/developer-guide/operations/reference/terminology-mapping) records the product-to-schema names; [Choose Credentials](/developer-guide/getting-started/credentials) explain the separate credential flows.
# Choose Credentials
Choose Platform, Classic, or Scribe credentials, confirm the tenant and host, and verify access before starting a workflow or installing a client.
For a new Platform integration, start with your assigned workspace, regional API base, and a credential accepted by the operation you need. Keep the API family and base URL alongside the tenant identifier in your integration configuration.
## Choose the Access Boundary
| Your task | Tenant and caller | Credential and owning guide |
| -------------------------------------------------------------------- | ----------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------- |
| Read or configure Platform workspace resources from a trusted server | One workspace; permissions of the key or token | [Platform workspace keys](/developer-guide/platform-api/platform-api/authentication) on routes that accept them |
| Run a scoped backend integration | Workspace and scopes granted to the client | [OAuth2 machine-to-machine](/developer-guide/platform-api/platform-api/oauth2) |
| Sign in interactively to a CLI or desktop application | Signed-in identity and selected workspace | [Device authorization](/developer-guide/platform-api/platform-api/authentication#device-code-flow-cli-and-desktop-apps) |
| Create or review clinical documentation | Provider principal, owning provider, and matching workspace | [Scribe provider access](/developer-guide/platform-api/scribe#authentication), with the scope required by the operation |
| Maintain a Classic integration | Organization and authenticated user | [Classic key-to-token exchange](/developer-guide/getting-started/authentication), then a Classic SDK or HTTP client |
| Query Classic data through the standalone Data-MCP service | Classic organization and user | [Data-MCP](/developer-guide/platform-api/data-world-model/data-mcp) |
API keys, identity tokens, provider tokens, and channel-management credentials have different access boundaries. Similar route names do not make their hosts or authorization rules interchangeable. For browser applications, follow [Serve an Agent From a Web App](/developer-guide/platform-api/conversations/serve-agent-from-web-app); keep long-lived workspace credentials on the trusted server.
## Verify Platform Access
1. Obtain your workspace ID, assigned [regional endpoint](/developer-guide/getting-started/regions-and-endpoints), and the required read permission from the implementation owner.
2. Configure the [Platform SDK](/developer-guide/platform-api/platform-sdk/configuration), or use the workspace-key HTTP example in [Authentication & API Keys](/developer-guide/platform-api/platform-api/authentication#api-key-usage).
3. Run the read-only [SDK quickstart](/developer-guide/platform-api/platform-sdk/quickstart). Confirm the returned workspace matches the intended test deployment.
4. Select an explicitly configured test service before running [First Verified Conversation](/developer-guide/guides/first-verified-conversation).
A successful read verifies access to that resource. It does not verify channel provisioning, tool permissions, provider enrollment, or external delivery.
## Diagnose Access Failures
Check the API family, host, tenant identifier, credential expiry, and required scope or permission before repeating a request. Use the route's documented error response to distinguish authentication failure from insufficient access or an unavailable resource. Preserve the correlation identifier when one is supplied, and use [Troubleshooting](/developer-guide/guides/troubleshooting) to identify the next diagnostic.
## Sessions Mean Different Things
| Session | Purpose | Continue here |
| ----------------------- | ----------------------------------------------- | ------------------------------------------------------------------------------------ |
| Identity session | Login, token validity, and account access | [Platform authentication](/developer-guide/platform-api/platform-api/authentication) |
| Persistent text session | Connection and interaction protocol | [Platform Sessions](/developer-guide/platform-api/platform-api/sessions) |
| Scribe session | Provider-owned clinical encounter and artifacts | [Scribe Sessions](/developer-guide/platform-api/scribe/sessions) |
Ending a conversation, disconnecting a socket, finalizing a clinical note, and revoking a login are different operations.
# Classic Authentication
Configure Classic API key credentials, exchange them for a user token, and distinguish this flow from Platform authentication.
For a new Platform project, use [Choose Credentials](/developer-guide/getting-started/credentials). This retained page owns the Classic flow and its existing links.
This page covers Classic API authentication: create an API key, exchange the key credentials for a user token, and use that token under the user's permissions.
{% hint style="warning" %}
**Classic API authentication.** This page covers the Classic API's two-tier authentication (API key to JWT). Platform workspace routes can accept keys directly; identity, OAuth2, and session routes have their own credential requirements. See [Platform API Authentication](/developer-guide/platform-api/platform-api/authentication).
{% endhint %}
## The Credential Flow
Amigo uses a two-credential system for secure API access. Your Amigo representative provisions your organization and its initial `Admin` user; everything from there is self-serve.
1. **Generate an API key** (one-time or rotate periodically)
* Create via the Admin Dashboard or the API endpoint
* Produces `api_key_id` and `api_key`
* Long-lived credential for machine-to-machine authentication
* Keep it secret to prevent unauthorized access
2. **Exchange the API key for a JWT token** (per session or application startup)
* Call `POST /v1/{org}/user/signin_with_api_key` with the API key credentials
* Returns an `id_token` (a JWT) and its `expires_at` expiry time
* Short-lived token representing an authenticated user session
3. **Use the JWT in all API calls**
* Include it in the header: `Authorization: Bearer {jwt}`
* The JWT grants access to conversations, users, and other endpoints
* It can act on behalf of other users, as permitted by their roles and permissions
{% hint style="danger" %}
**Critical: API Key is not a JWT Token**
Wrong: `Authorization: Bearer {api_key}` Correct: `Authorization: Bearer {jwt}`
For these Classic routes, exchange the API key for a JWT before using a Bearer header. This instruction does not apply to Platform workspace-key authentication.
{% endhint %}
### Flow
```mermaid
%%{init: {"theme":"base","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"},"fontFamily":"Inter, sans-serif"}}%%
sequenceDiagram
autonumber
participant Dev as Developer/Admin
participant API as Amigo API
participant App as Your App / SDK
Note over Dev,API: Create API key (one-time or rotate periodically)
Dev->>API: POST /v1/{org}/organization/api_key/
API-->>Dev: 201 Created { api_key_id, api_key }
Note over App,API: Exchange API key for JWT (machine-to-machine)
App->>API: POST /v1/{org}/user/signin_with_api_key
API-->>App: 200 OK { id_token, expires_at }
Note over App,API: Use JWT for HTTP requests
App->>API: Authorization: Bearer {jwt}
API-->>App: 200 OK
Note over App,API: For WebSocket realtime
App->>API: Sec-WebSocket-Protocol: bearer.authorization.amigo.ai.{jwt}
API-->>App: Connected
```
## Generating API Keys
A service account makes API keys for use with other services. When your organization is set up in Amigo, an `Admin` user is created for adding more users. To confirm you are logged in as the `Admin` role, check that the tag appears in the top right corner of the admin dashboard.
You have two options for generating API keys.
{% tabs %}
{% tab title="Admin Dashboard" %}
1. Log in to your service account.
2. Navigate to `https://.amigo.ai/admin/settings`.
3. Click **Create API Key** and select the duration.
4. Store the API key and key ID securely (they cannot be retrieved later).
{% endtab %}
{% tab title="Programmatic (Recommended)" %}
{% endtab %}
{% endtabs %}
{% hint style="warning" %}
**Permission boundaries** API keys cannot impersonate users with higher privileges than the key creator.
{% endhint %}
## Authentication Token Generation
Exchange your API key for a JWT token to authenticate API calls.
{% openapi src="" path="/v1/{organization}/user/signin\_with\_api\_key" method="post" %}
{% endopenapi %}
## Testing with Postman or Scalar
When testing with API clients like Postman, Scalar, or Insomnia, follow the quick start flow below.
### Quick start flow
1. **Generate an API key** using one of the methods above. You will have `api_key`, `api_key_id`, and your `user_id`.
2. **Call the signin endpoint** to exchange for a JWT (see the embedded reference above).
3. **Use the JWT as a Bearer token** for all other API calls.
{% hint style="warning" %}
**Critical: the signin endpoint uses headers**
When calling `/user/signin_with_api_key`, pass credentials as **HTTP headers** rather than in the request body:
* `x-api-key: {your-api-key}`
* `x-api-key-id: {your-api-key-id}`
* `x-user-id: {your-user-id}`
The response contains `{ "id_token": "...", "expires_at": "..." }`. The `id_token` is the JWT you use as the Bearer token.
{% endhint %}
{% hint style="info" %}
**Where to find credentials**
* `api_key`, `api_key_id`, and `user_id`: all available at `https://.amigo.ai/admin/settings/api-keys`
* `user_id`: also available in user details at `https://.amigo.ai/admin/users/{user_id}`
{% endhint %}
Once you have the JWT, use it for all subsequent requests.
```http
Authorization: Bearer {id_token-from-signin-response}
```
## Regional Endpoints and Dedicated Clusters
* Use the regional base URL that matches your organization's residency. See [Regions & Endpoints](/developer-guide/getting-started/regions-and-endpoints) for the full list.
* For tenants on dedicated clusters, include the `x-mongo-cluster-name` header when instructed (mandatory for Create Organization).
## Security Best Practices
### API key rotation
1. **Create new keys** before current keys expire.
2. **Transition applications** to use the new credentials.
3. **Revoke old keys** after a successful transition.
4. **Automate rotation** to prevent authentication failures.
### Additional security measures
* **Environment variables.** Never hardcode credentials.
* **Access control.** Apply the principle of least privilege.
* **Audit logs.** Monitor API key usage.
* **Secure storage.** Use a secret management solution.
## Advanced Authentication
Most integrations only need the API key to JWT flow above. The methods in this section cover specialized deployments.
### DPoP (Sender-Constrained Tokens)
DPoP belongs to supported Platform identity token flows. It is not an additional step in the Classic API key-to-user-token exchange on this page. Follow the credential and issuer requirements of the identity integration you are implementing; do not apply a Platform token response or proof format to the Classic sign-in endpoint.
See [Platform Authentication](/developer-guide/platform-api/platform-api/authentication) for the distinction between workspace keys, interactive identity, and the separately scoped OAuth2 flows.
### HTTP Basic Authentication (Experimental)
{% hint style="warning" %}
**Experimental feature.** HTTP Basic Auth is experimental and subject to change. Use the API key to JWT exchange for production integrations.
{% endhint %}
An alternative authentication method is available using HTTP Basic Auth, which supports cross-organization authorization.
**Format:**
```http
Authorization: Basic base64({org_id}_{user_id}:{jwt})
```
The username is `{org_id}_{user_id}` and the password is the Amigo-issued JWT that identifies the user.
**Key features:**
* Combines organization, user, and the user's Amigo-issued JWT into a single header
* Supports cross-organization authentication (a user in org A authenticating against org B)
* Useful for scenarios where the standard two-step API key to JWT flow is impractical
**Example:**
```bash
# Encode credentials
CREDENTIALS=$(echo -n "${ORG_ID}_${USER_ID}:${JWT}" | base64)
curl --request GET \
--url 'https://api.amigo.ai/v1//service/' \
--header "Authorization: Basic ${CREDENTIALS}"
```
## CLI Authentication (Agent Forge)
The current Go Agent Forge CLI targets the Platform API. Use its [Platform authentication setup](https://docs.amigo.ai/reference/agent-forge) for workspace keys or device authorization.
The configuration below belongs to the legacy Classic workflow and its `.env.{env}` files. Use the legacy Python CLI when you need supported Classic commands.
### Method 1: API key authentication
Set all three API key variables to use API key auth. This method also supports user impersonation via the `--user` flag.
```env
API_KEY=your-api-key
API_KEY_ID=your-api-key-id
API_KEY_USER_ID=your-user-id
```
### Method 2: Interactive Classic Authentication
Set `GOOGLE_TENANT_ID` (and omit the API key fields) to use interactive Google Sign-In with device code flow. When using the device code flow, the CLI displays a user code and directs you to Google's device authorization page (`https://www.google.com/device`). After signing in, you enter the code shown in your terminal and approve the request. Tokens are cached locally (with owner-only file permissions) and refresh automatically.
```env
GOOGLE_TENANT_ID=your-tenant-id
```
```bash
# One-time login per environment
forge auth login -e myorg
# Output:
# Visit: https://www.google.com/device
# Enter code: ABCD-EFGH
# Waiting for authentication...
# Authenticated as you@example.com
```
{% hint style="info" %}
**Auth method selection.** The CLI picks the auth method based on which environment variables are set. If all three API key fields are present, API key auth is used. Otherwise, interactive Classic auth is used. Subsequent commands reuse cached tokens and refresh them silently.
{% endhint %}
{% hint style="warning" %}
**Impersonation limitation.** The `--user` flag on conversation commands (smoke-test, simulate, simulate-step) requires API key authentication. Interactive Classic auth does not support user impersonation.
{% endhint %}
# Regions & Endpoints
Configure regional base URLs for both APIs, LLM availability by region, and dedicated cluster headers.
Amigo's APIs are deployed across multiple regions to reduce latency and support data residency requirements. Each region operates independently with its own compute and AI routing. This page lists the regional base URLs for both the Classic API and the Platform API, explains how routing differs between the two, and covers dedicated cluster headers.
## Regional Base URLs
Amigo runs in four regions. Use the tables below to find the base URL for each API.
### Classic API
| Region | Location | Base URL |
| ------ | -------------------------- | ------------------------------------- |
| **US** | N. Virginia (`us-east-1`) | `https://api.amigo.ai` |
| **CA** | Montreal (`ca-central-1`) | `https://api-ca-central-1.amigo.ai` |
| **EU** | Frankfurt (`eu-central-1`) | `https://api-eu-central-1.amigo.ai` |
| **AU** | Sydney (`ap-southeast-2`) | `https://api-ap-southeast-2.amigo.ai` |
### Platform API
| Region | Location | Base URL |
| ------ | -------------------------- | ---------------------------------------------- |
| **US** | N. Virginia (`us-east-1`) | `https://api.platform.amigo.ai` |
| **CA** | Montreal (`ca-central-1`) | `https://api-ca-central-1.platform.amigo.ai` |
| **EU** | Frankfurt (`eu-central-1`) | `https://api-eu-central-1.platform.amigo.ai` |
| **AU** | Sydney (`ap-southeast-2`) | `https://api-ap-southeast-2.platform.amigo.ai` |
### How routing differs between the APIs
* **Classic API: region matching is required.** Use the base URL that matches your organization's data residency. Requests to a mismatched region return "Organization not found" errors.
* **Platform API: region matching is required.** `https://api.platform.amigo.ai` is the US endpoint, not a global router. Use the deployment hostname agreed during provisioning and store it with the integration configuration. A workspace response reports the serving deployment's region; it is not a mutable placement policy. The accepted legacy region-update field is ignored and does not migrate data.
AI-backed service and model availability can differ by deployment. Do not infer that every external model or processor runs in the workspace region; confirm the data path and regional availability for the features you enable.
{% hint style="info" %}
Contact your Amigo representative for regional availability and upcoming regions.
{% endhint %}
For organizations on dedicated clusters, you can also target your cluster explicitly via the `x-mongo-cluster-name` header - see [Dedicated Clusters](#dedicated-clusters) below.
## Confirm Each Service
Regional Platform and Classic API hosts identify those API deployments. Confirm Scribe, managed channels, provider integrations, and any external processors separately before adding them to a workflow. Do not derive another service's base URL by substituting a region into a hostname.
| Capability | Regional readiness to verify |
| ---------------------------------- | ----------------------------------------------------------------------------------------------------- |
| Platform workspace resources | Assigned Platform host, workspace access, and required features enabled in that deployment |
| Classic integration | Assigned Classic host and organization; use the Classic credential flow |
| Scribe and Zoom capture | Assigned Scribe base, provider enrollment, supported capture setup, and permitted processing location |
| Managed phone and messaging | Provisioned line/account and binding, regional support, and delivery/processing constraints |
| External data and model processing | Approved source/destination and the applicable data-processing boundary |
Record the confirmation owner, test evidence, limitations, and date using [Govern a Deployment](/developer-guide/guides/govern-a-deployment). The public US Scribe schema establishes an HTTP contract, not availability in every Platform region. [Data Residency](https://docs.amigo.ai/platform-overview/data-residency) explains the broader deployment review.
## LLM Regional Availability
Not all LLMs are deployed in every region. When selecting [version set presets](/developer-guide/operations/devops/channel-tagging), make sure the preset's LLMs are available in your target region.
Confirm model and feature availability for the intended deployment. A preset name does not guarantee that every model or external processor is available in every region.
The legacy Python Agent Forge build provides `forge channel llm-info` and `forge channel validate-preset --region ` for Classic channel presets. These commands are not part of the current Go CLI's Platform-only command surface.
{% hint style="info" %}
**Classic preset compatibility.** Legacy preset and Python Forge instructions belong to [Classic channel tagging](/developer-guide/operations/devops/channel-tagging). Confirm the current model and processor availability for the actual deployment before reusing a historical preset. These presets do not establish Platform regional support.
{% endhint %}
### Global Deployment Map
```mermaid
%%{init: {"flowchart":{"useMaxWidth":true,"nodeSpacing":30,"rankSpacing":40},"theme":"base","themeVariables":{"fontFamily":"Inter, sans-serif","fontSize":"16px","background":"#FAF8F6","primaryColor":"#F1EAE7","primaryTextColor":"#1A1817","primaryBorderColor":"#D7D2D0","secondaryColor":"#FDFCFB","tertiaryColor":"#F6F2F0","lineColor":"#575452","textColor":"#3D3937","clusterBkg":"#FDFCFB","clusterBorder":"#E8E2DF","edgeLabelBackground":"#FAF8F6","actorBkg":"#F1EAE7","actorTextColor":"#1A1817","actorBorder":"#D7D2D0","actorLineColor":"#575452","signalColor":"#575452","signalTextColor":"#3D3937","labelBoxBkgColor":"#F1EAE7","labelBoxBorderColor":"#D7D2D0","labelTextColor":"#3D3937","loopTextColor":"#3D3937","noteBkgColor":"#F6F2F0","noteBorderColor":"#D7D2D0","noteTextColor":"#3D3937","activationBkgColor":"#F1EAE7","activationBorderColor":"#D7D2D0","altSectionBkgColor":"#FAF8F6","altSectionColor":"#3D3937"},"fontFamily":"Inter, sans-serif"}}%%
graph TB
Global[Amigo Platform Global Network]
Global --> US["🇺🇸 US Region N. Virginia us-east-1 api.amigo.ai"]
Global --> CA["🇨🇦 CA Region Montreal ca-central-1 api-ca-central-1 .amigo.ai"]
Global --> EU["🇪🇺 EU Region Frankfurt eu-central-1 api-eu-central-1 .amigo.ai"]
Global --> AU["🇦🇺 AU Region Sydney ap-southeast-2 api-ap-southeast-2 .amigo.ai"]
style US fill:#FDFCFB,stroke:#D7D2D0,color:#3D3937,stroke-width:1px
style CA fill:#FDFCFB,stroke:#D7D2D0,color:#3D3937,stroke-width:1px
style EU fill:#FDFCFB,stroke:#D7D2D0,color:#3D3937,stroke-width:1px
style AU fill:#FDFCFB,stroke:#D7D2D0,color:#3D3937,stroke-width:1px
style Global fill:#FDFCFB,stroke:#D7D2D0,color:#3D3937,stroke-width:1px
```
### cURL example
```bash
curl -X GET \
-H "Authorization: Bearer " \
"https://api-ca-central-1.amigo.ai/v1//organization/"
```
### SDK configuration
Specify the regional base URL via the SDK `base_url` or `baseUrl` setting.
{% tabs %}
{% tab title="Classic Python" %}
```python
from amigo_sdk import AmigoClient
with AmigoClient(
api_key="",
api_key_id="",
user_id="",
organization_id="",
base_url="https://api-ca-central-1.amigo.ai",
) as client:
org = client.organization.get()
```
{% endtab %}
{% tab title="Classic TypeScript" %}
```typescript
import { AmigoClient } from "@amigo-ai/sdk";
const client = new AmigoClient({
apiKey: process.env.AMIGO_API_KEY!,
apiKeyId: process.env.AMIGO_API_KEY_ID!,
userId: process.env.AMIGO_USER_ID!,
orgId: process.env.AMIGO_ORGANIZATION_ID!,
baseUrl: "https://api-ca-central-1.amigo.ai",
});
const org = await client.organizations.getOrganization();
```
{% endtab %}
{% tab title="Platform TypeScript" %}
```typescript
import { AmigoClient } from '@amigo-ai/platform-sdk'
const client = new AmigoClient({
apiKey: process.env.AMIGO_PLATFORM_API_KEY!,
workspaceId: process.env.AMIGO_WORKSPACE_ID!,
baseUrl: 'https://api-ca-central-1.platform.amigo.ai',
})
const workspace = await client.workspaces.get()
```
{% endtab %}
{% endtabs %}
### Environment variables
You can also set the regional endpoint via environment variables.
```env
# US
AMIGO_BASE_URL=https://api.amigo.ai
# CA
# AMIGO_BASE_URL=https://api-ca-central-1.amigo.ai
# EU
# AMIGO_BASE_URL=https://api-eu-central-1.amigo.ai
# AU
# AMIGO_BASE_URL=https://api-ap-southeast-2.amigo.ai
```
## Dedicated Clusters
This section covers Classic organization provisioning. It does not configure Platform workspace placement.
Some enterprises run on dedicated, isolated clusters. In these cases, include `x-mongo-cluster-name` to direct requests to your assigned cluster.
{% hint style="info" %}
**Cluster name.** Your Amigo team provides the exact cluster name if your tenant uses a dedicated cluster. Do not guess this value.
{% endhint %}
**Header**: `x-mongo-cluster-name: `
**When to use**:
* **Required**: organization provisioning (Create Organization)
* **Recommended**: early provisioning flows when the organization may not yet be discoverable via the global config
* **Optional**: normal operations for established organizations. Most endpoints do not require it once your org is fully set up.
### cURL example (dedicated cluster)
```bash
curl -X PUT \
-H "Authorization: Bearer " \
-H "x-mongo-cluster-name: " \
-H "Content-Type: application/json" \
"https://api-eu-central-1.amigo.ai/v1//organization/" \
-d '{
"org_name": "Example Corp",
"user_dimensions": [],
"logo": "",
"square_logo": "",
"favicon": "",
"default_user_preferences": {},
"azure_devops_team_name": "example-team"
}'
```
The SDKs do not currently expose a raw-header helper; use cURL for dedicated-cluster provisioning requests.
## Recommendations
{% hint style="success" %}
**Best practices**
1. Confirm your organization or workspace region with your Amigo representative and set the matching base URL.
2. For dedicated cluster tenants, store your cluster name in a secure configuration store.
3. Include the `x-mongo-cluster-name` header where instructed for dedicated clusters.
{% endhint %}
{% hint style="warning" %}
**Troubleshooting "Organization not found"**
If you see this error:
* Verify you are calling the correct regional base URL.
* For provisioning flows, make sure the `x-mongo-cluster-name` header is set (if you are on a dedicated cluster).
{% endhint %}
# Guides
Task guides for configuring, testing, operating, and governing Amigo workflows, with prerequisites and evidence of completion.
Use these guides to complete an implementation or operating task. Each identifies the required access and configuration, the steps to follow, and the evidence to inspect. Endpoint pages supply the underlying request and response contracts.
## Choose a Workflow
| Task | Verified outcome |
| -------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------- |
| [Build and Prove](/developer-guide/guides/build-and-prove) | Reviewed service configuration, bounded test evidence, and promotion/recovery plan |
| [First Verified Conversation](/developer-guide/guides/first-verified-conversation) | Runnable client, durable answer, expected rejection, and closure |
| [Operate and Improve](/developer-guide/guides/operate-and-improve) | Located run, appropriate intervention, reconciliation, and a repeatable evaluation case |
| [Connect Data to a Verified Action](/developer-guide/guides/data-to-verified-action) | Source record, queryable entity, agent access, and independently verified target outcome |
| [Verify an Integration Action](/developer-guide/guides/verify-an-integration-action) | Authorized operation and independently confirmed target outcome |
| [Test a Managed SMS Workflow](/developer-guide/guides/test-managed-sms) | Provisioned routing, send/delivery evidence, and suppression behavior |
| [Govern a Deployment](/developer-guide/guides/govern-a-deployment) | Access, availability, region, and operational responsibilities recorded |
| [Scribe: Capture to Finalized Note](/developer-guide/guides/scribe-capture-to-note) | Provider-owned session, reviewed artifact, and version-checked finalization |
| [Troubleshoot an Integration](/developer-guide/guides/troubleshooting) | Failing boundary, reconciliation action, and escalation evidence |
| [Compatibility and Retirements](/developer-guide/guides/compatibility-and-retirements) | Correct Classic or retired-interface migration path |
Console groups tasks into Build, Prove, Operate, Improve, Data, and Govern. Each guide connects those entry points to the owning API and supported client instructions. Confirm [capability availability](https://docs.amigo.ai/platform-overview/capability-availability) before relying on a preview or managed channel.
## Build a Knowledge-Base Agent
The knowledge-base playbooks below describe a particular build workflow. Confirm their API, data-access, and tooling prerequisites before applying them to your deployment. Start with [Getting Started](/developer-guide/getting-started) for the general Platform and Classic integration paths, then read the end-to-end playbook before its methodology deep dive.
1. [Build a Knowledge-Base Agent End to End](/developer-guide/guides/build-a-kb-agent-end-to-end) - the full path: load your data, assign roles, build the agent, and test it.
2. [Knowledge-Base Agent: Retrieval and Build Methodology](/developer-guide/guides/building-a-knowledge-base-agent) - the deep-dive behind the build step: the retrieval-architecture decision and the measurement-driven build loop, grounded in a controlled bake-off.
# Build and Prove
Configure a Platform service, verify its behavior with a bounded test, and promote reviewed versions with evidence and a recovery plan.
Use this path to turn an agent configuration into a service you can test and deliberately promote. Start with a test workspace, permitted synthetic data, and an implementation owner who can confirm the required tools and channels are enabled.
## Build
Console groups authoring under **Build**: Agents, Context Graphs, Tools, Services, and Channels. Visibility and permissions depend on the workspace. Use the corresponding contracts when automating the same task.
1. Confirm [credentials and workspace access](/developer-guide/getting-started/credentials).
2. Configure the [agent](/developer-guide/platform-api/workspaces/agents) and [Context Graph](https://docs.amigo.ai/agent/context-graphs). Identify which tools can read data or change an external system; use test targets for the first run.
3. Bind the agent and graph in a [service](/developer-guide/platform-api/workspaces/services). Read back the selected versions and field-specific configuration. A service version set does not isolate all data or external effects.
4. Choose the supported [conversation path](/developer-guide/platform-api/conversations). Managed channels additionally require their [provisioned binding](/developer-guide/platform-api/workspaces/use-cases).
## Prove
Console's **Prove** area includes Playground and Simulations. Begin with [First Verified Conversation](/developer-guide/guides/first-verified-conversation): it provides the runnable project, expected durable answer, rejected-request exercise, and cleanup. Its local fixtures validate client behavior; use its provisioned mode to obtain evidence from your test service.
For a graph or channel change, use [Playground](https://docs.amigo.ai/testing/testing/playground) and the applicable [simulation workflow](https://docs.amigo.ai/testing/testing/simulations). Record the configuration, input, expected outcome, observed result, and failures. Verify an external effect separately with [Verify an Integration Action](/developer-guide/guides/verify-an-integration-action). Simulation success does not establish production delivery or deterministic future output.
## Promote and Recover
Use [Version Sets & Promotion](/developer-guide/operations/devops/version-sets-best-practices) to compare the candidate with the current release and retain the previous selection for rollback. Prefer explicit component versions for a reproducible release; an unpinned version can resolve newer configuration later.
Before promotion, record who reviewed the evidence, which channel and integration checks ran, and how to recover if the new behavior fails. After promotion, inspect a permitted test run through [Runs](/developer-guide/platform-api/conversations/runs). Rolling back configuration does not undo external mutations that already completed; reconcile those through the owning integration.
# Operate and Improve
Investigate a Platform run, use supported operator controls, reconcile incomplete effects, and turn observed failures into repeatable evaluations.
Start with the workspace, run or conversation identifier, approximate time, and the outcome being investigated. Use a credential permitted to inspect that workspace. Operator actions require additional permissions and channel support.
## Find the Execution
In Console, open **Operate → Runs**. The unified inventory includes supported conversation and framework run records; the old Conversations listing redirects there. Conversation detail remains the place to inspect the underlying conversation. The [Runs API](/developer-guide/platform-api/conversations/runs) documents filtering, detail, and supported controls.
Record the selected service/version, channel, execution state, and available error or correlation identifiers. Read history and traces as evidence with their stated completeness limits. A generated summary or missing recording link is not sufficient to determine whether an action completed.
## Choose the Correct Lifecycle Action
| Observation | Next action and verification |
| ----------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| An application text conversation has reached its intended outcome | Apply the documented [conversation close](/developer-guide/platform-api/conversations) behavior and read back its state; preserve the durable answer before cleanup |
| A persistent text connection drops | Follow the [session protocol](/developer-guide/platform-api/platform-api/sessions); verify the conversation state before creating another interaction |
| A managed message thread is complete | Use that [channel's lifecycle](/developer-guide/platform-api/conversations); thread identity, terminal closure, and a forced new conversation are separate decisions |
| An eligible voice run needs human intervention | Use [operator controls](/developer-guide/platform-api/conversations/operators), verify takeover, and verify handback separately; voice operators join by phone |
| An integration action is approved or a request times out | Inspect the target result before retrying; [approval and external completion](/developer-guide/guides/verify-an-integration-action) are separate evidence |
Do not apply one channel's close or retry behavior to every session type. Where an outcome is ambiguous, preserve identifiers and reconcile before repeating a mutation.
## Recover and Escalate
Follow [Troubleshoot an Integration](/developer-guide/guides/troubleshooting) to distinguish access, configuration, execution, projection, and external-delivery failures. Capture the last verified boundary and the next safe diagnostic. Share only the minimum permitted evidence through the agreed support channel.
## Improve
Console's **Improve** area groups Quality, Insights, Dashboards, and Team Performance. Use [quality metrics](https://docs.amigo.ai/testing/testing/metrics), [production evaluations](/developer-guide/platform-api/safety/production-evals), and [trace analysis](/developer-guide/platform-api/safety/call-trace-analysis) according to their access and coverage limits.
Turn a reproduced failure into a bounded evaluation case with a stated expected result. Compare candidate configuration against that case using [Build and Prove](/developer-guide/guides/build-and-prove). Distinguish missing evaluation evidence from a passing evaluation and model-generated interpretation from independently verified facts.
# Data to a Verified Action
Follow a synthetic record from a supported source through queryable data and agent access to an independently verified external integration outcome.
For hospital workflows, first qualify the [HL7v2 integration boundary](https://docs.amigo.ai/data/healthcare-interoperability): inbound HL7v2 ADT/SIU notifications and outbound scheduling changes require separate evidence. The steps below assume a supported, provisioned source and target.
Use a synthetic record and an approved test destination to verify the whole data path. Obtain a configured source, supported mapping, permitted read access, and an integration whose test behavior and mutation permissions are understood. If any prerequisite is missing, complete provisioning before running the corresponding step.
## Connect the Source
In Console, **Data → Sources** is the entry point for connected sources and their health. Configure the supported [intake source](/developer-guide/platform-api/data-world-model/intake-sources) or [connector](/developer-guide/platform-api/data-world-model/connector-runner). Record the source identifier and the submitted record's external identifier so that you can locate the same record later.
[Authenticated dataset intake](/developer-guide/platform-api/data-world-model/intake) and [browser Surfaces](/developer-guide/platform-api/conversations/surfaces) have different contracts. A Surface submission does not automatically create a dataset file. Source support and parsing must be confirmed for the chosen format.
## Verify Queryable Data
Use **Data → Records** and the supported [workspace data query](/developer-guide/platform-api/functions/workspace-data-queries) path to locate the intended entity and inspect source attribution. Verify its identity and the fields needed by the workflow. World-model read views update asynchronously; acceptance of an input is not evidence that the corresponding projection is already queryable.
If the record is missing or stale, inspect source status, mapping, identity resolution, and freshness before resubmitting. Preserve the original identifiers. Caller recognition may require a separate [external identity binding](/developer-guide/platform-api/integrations/external-user-subject-key-binding); a queryable record alone does not prove recognition is ready.
## Verify Agent Access
Configure the test service with the intended graph, query/tool access, and subject context. Run the bounded interaction from [First Verified Conversation](/developer-guide/guides/first-verified-conversation) against that configured test service. Check the retained answer and available tool evidence against the synthetic source record. A plausible answer does not establish that the agent retrieved the intended source.
## Verify the External Outcome
Follow [Verify an Integration Action](/developer-guide/guides/verify-an-integration-action) for the authorized test mutation, expected failure, target acknowledgement or read-back, and reconciliation. Apply approval requirements only to the integration path that implements them. The separately enabled [connector write-back review](/developer-guide/platform-api/integrations/review-queue) workflow has its own availability and lifecycle.
| Milestone | Evidence to keep |
| ------------------------- | ---------------------------------------------------------------------------- |
| Submitted | Source and request identifiers; input acceptance or rejection |
| Queryable | Intended entity, source attribution, required fields, and observed freshness |
| Used by the workflow | Service/version, conversation/run, and available retrieval or tool evidence |
| Authorized | Required permission and approval decision for the specific action |
| Completed externally | Target acknowledgement or independent read-back |
| Reconciled and cleaned up | Resolution of ambiguous attempts and cleanup of the permitted test resources |
Stop at the last verified milestone when later evidence is missing. Use [Troubleshooting](/developer-guide/guides/troubleshooting) for the next diagnostic rather than repeating an uncertain mutation.
# Govern a Deployment
Confirm workspace access, feature provisioning, regional processing boundaries, and operational responsibilities before enabling a customer workflow.
Prepare this record with the implementation and access owners before enabling a workflow. Console's **Govern** area brings together Members & Access, API Keys & Tokens, Compliance & Audit, and Settings. Access to a Console page does not grant every underlying operation.
## Establish Access
Use [Choose Credentials](/developer-guide/getting-started/credentials) to select the caller and credential. Confirm the assigned workspace, the permissions needed for each task, and who can rotate or revoke access. Keep integration credentials in the trusted environment and review the owning [authentication contract](/developer-guide/platform-api/platform-api/authentication).
## Confirm Availability and Region
Check [Capability and Availability](https://docs.amigo.ai/platform-overview/capability-availability) for the distinction between supported interfaces, provisioning, previews, and demos. Record the actual enablement evidence for this workspace; a demonstration is not an enrollment record.
Use [Regions & Endpoints](/developer-guide/getting-started/regions-and-endpoints) for the assigned host. Confirm each additional service, including Scribe and managed channels, separately. A regional API hostname alone does not establish the location of every processor or supporting service.
| Record | Required decision or evidence |
| ---------------------- | ----------------------------------------------------------------------------------------- |
| Workspace and access | Tenant identifier, credential/principal, permissions, accountable access owner |
| Capability | Supported interface, Console visibility, preview/provisioning agreement where needed |
| Region and processing | Assigned hosts, permitted processing/data paths, approved external dependencies |
| Retention and recovery | Agreed retention/deletion behavior, recovery expectations, and responsible owner |
| Operational readiness | Monitoring evidence, intervention route, escalation contact, rollback/reconciliation plan |
| Verification | Test deployment, observed outcome, remaining limitation, reviewer, and date |
## Review the Deployment Evidence
Use the [Technical Evaluation Packet](https://docs.amigo.ai/platform-overview/evaluation-packet), [Data Residency](https://docs.amigo.ai/platform-overview/data-residency), and [Compliance and Audit](https://docs.amigo.ai/operations-and-safety/compliance) to keep configuration choices distinct from contractual commitments. An API reference, source commit, or configuration snapshot does not establish a service-level commitment.
Recheck the record when adding a channel, processor, integration, or region, and before promoting a materially changed workflow. Use [Current Upgrade Guidance](https://docs.amigo.ai/api-reference/change-logs/upgrade-guide) when older clients or retired interfaces are involved.
# Scribe: Capture to Finalized Note
Prepare provider access, create an in-person or Zoom Scribe session, verify transcript and artifact readiness, and finalize the note the provider reviewed.
Use this workflow with a provisioned Scribe deployment and an authorized provider. For integration testing, use an approved synthetic encounter. Confirm the supported visit type and note template, capture method, required permissions, and recording/disclosure process before capture begins.
## Prepare Access and Capture
Scribe uses its own deployment base and [provider-principal authentication](/developer-guide/platform-api/scribe#authentication). The provider's workspace must match the request, and access to a session is scoped to its owner. Read, session-write, and note-write scopes authorize different operations.
Choose in-person microphone capture or Zoom when creating the session. Mode cannot be changed later. Zoom requires the provider's connected account and the supported meeting/disclosure configuration. Use the assigned Scribe schema; Platform text-session endpoints are a different contract.
## Create and Capture
Follow [Create an In-Person Session](/developer-guide/platform-api/scribe/sessions#create-an-in-person-session) or [Create a Zoom Session](/developer-guide/platform-api/scribe/sessions#create-a-zoom-session). Supply a supported canonical visit type that resolves the note template, including where the generated request model marks the selection optional. Record the returned session identifier.
Use the configured capture client and its supported attachment or Zoom controls. Inspect session state and available transcript evidence. Creating a session does not prove that recording has attached or usable transcript segments have arrived.
## End Capture and Inspect Artifacts
Use the capture mode's [lifecycle operation](/developer-guide/platform-api/scribe/sessions#session-lifecycle). An in-person end can be refused while streaming remains attached; a Zoom end acknowledgement can precede transcript finalization. Read the resulting session and [artifact state](/developer-guide/platform-api/scribe/artifacts) separately.
When note generation is pending, continue checking its documented read operation. Handle failed and empty results explicitly. A successful generation request or a session in review does not establish that a note is ready. Review the transcript, note, checklist, and coding suggestions according to the provider's workflow; generated content and confidence values do not substitute for that review.
## Finalize the Reviewed Version
Read the current note and retain its version. The provider reviews that version, then the client submits its `base_version` to [Finalize a Note](/developer-guide/platform-api/scribe/artifacts#finalize-a-note). If another edit produces a version conflict, reload and have the provider review the new version before submitting again.
Read back the submitted note and session outcome. A finalized artifact is distinct from delivery to another clinical system; verify any separately configured integration at its own boundary.
## Verify Failure and Cleanup
In the approved test deployment, verify the documented stale-version conflict using a mutable test note and an older version. Confirm that the current note remains intact, reload it, and complete the intended review path. Cancel an unfinished test session using the supported lifecycle; finalization and cancellation are not general data-deletion operations. Follow the agreed retention and test-data cleanup process.
Keep the session identifier, capture mode, artifact outcome, reviewed version, finalization result, and correlation identifiers. Use the [Scribe HTTP reference](https://docs.amigo.ai/api-reference/readme/scribe) for exact request and response contracts.
# Compatibility and Retirements
Find Classic integration guidance, migration instructions for retired Platform interfaces, and historical release records without mixing their scopes.
Use current contracts for a new integration and the owning migration page when maintaining an older client. Classic remains a separate documented API; a Classic integration is not automatically a retired integration.
## Classic Integrations
Start with [Classic authentication](/developer-guide/getting-started/authentication), [Classic API resources](/developer-guide/classic-api/core-api), and the [Classic SDKs](/developer-guide/classic-api/sdks). [Terminology Mapping](/developer-guide/operations/reference/terminology-mapping) and [Memory Architecture & API Mapping](/developer-guide/operations/reference/memory-architecture) identify their Classic-specific scope. Platform credentials and resource IDs are not interchangeable with Classic ones.
## Retired Platform Interfaces
| Former interface | Current guidance |
| ----------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Hosted framework-run dispatch and polling | [Agent Runs retirement](/developer-guide/platform-api/functions/agent-runs); the unified [Runs inventory](/developer-guide/platform-api/conversations/runs) is a separate retained contract |
| Native-agent definition registry | [Agent Definitions retirement](/developer-guide/platform-api/functions/agent-definitions) |
| Standalone ringless voicemail | [Voicemail retirement](/developer-guide/platform-api/conversations/voicemail); ordinary outbound-call voicemail handling has a different lifecycle |
| Standalone intake upload links | [Upload-link retirement](/developer-guide/platform-api/data-world-model/intake-links); authenticated dataset intake remains current |
The migration pages retain their existing URLs. A command or type in an older SDK or CLI does not make a removed server operation available.
## Release History
Use [Current Upgrade Guidance](https://docs.amigo.ai/api-reference/change-logs/upgrade-guide) for present compatibility decisions. [Release archives](https://docs.amigo.ai/api-reference/change-logs) record historical behavior and dates; evaluate current availability using the owning operation and workflow guide.
# First Verified Conversation
Run a pinned TypeScript starter, verify a durable text response, exercise a failure, and close the conversation with explicit test-service prerequisites.
Build a trusted Node.js client that creates a web conversation, asks a synthetic scheduling question, reads the answer back from durable history, and closes the conversation. The result is an evidence file you can inspect. This first project does not book an appointment or contact a patient.
The local walkthrough uses the real Platform SDK with fixture HTTP responses. The provisioned path uses the same client workflow against your Amigo test service. Local success verifies the example and SDK integration; it does not verify a deployed agent, external system, or channel.
## Before You Start
You need Node.js 22 or later, npm, and a tool to extract ZIP files. The starter pins `@amigo-ai/platform-sdk` to `0.107.0` and commits its dependency lockfile. Use `npm ci` to reproduce the checked version.
For the **provisioned path**, your workspace administrator or Amigo implementation contact must supply:
| Prerequisite | Ready when |
| ------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Regional Platform API base and workspace ID | Both identify the same test deployment; see [Regions and Endpoints](/developer-guide/getting-started/regions-and-endpoints) |
| Workspace API key | It can create, read, submit turns to, and close conversations in that workspace; see [Authentication](/developer-guide/platform-api/platform-api/authentication) |
| Configured test service ID | Its selected agent and Context Graph answer ordinary text questions without requiring a patient entity or production data |
| Reviewed tool and data access | The service has no production write tools, outbound channel actions, or private patient context; a prompt asking for a test is not an authorization boundary |
| Configuration record | The implementation owner records the service and selected configuration used for the test |
This tutorial does not provision the workspace or author the service. Resolve those dependencies before choosing the provisioned path. Use the local path immediately if you are still arranging access.
## 1. Get the Starter
Download and extract the starter ZIP. It contains only the example source, pinned dependencies, fixtures, tests, and the documentation snapshots used by its checks. No GitHub organization access is required.
{% file src="/files/cgkESp5ztA2rhX4SRogb" %}
Download the runnable Platform conversation starter.
{% endfile %}
In the extracted directory:
```bash
cd amigo-first-conversation
npm ci
npm test
```
Tests use fixture responses and do not contact Amigo. `npm run check:docs` also compiles the included SDK quickstart snapshots and checks this tutorial's client block against its executable source.
## 2. Run a Conversation
{% tabs %}
{% tab title="Local walkthrough" %}
```bash
npm run demo
```
No credentials or provisioning are needed. The SDK's injected transport accepts only the example host and never sends a network request. The fixture asks which information a scheduling team needs before considering an appointment change. Its answer explains the prerequisites and says that no appointment changed.
{% endtab %}
{% tab title="Provisioned test service" %}
Keep credentials in a trusted terminal or server process. Supply the key through your normal secret-injection mechanism, then set the non-secret deployment values:
```bash
export AMIGO_BASE_URL='https://api.platform.amigo.ai'
export AMIGO_WORKSPACE_ID='your-test-workspace-id'
export AMIGO_SERVICE_ID='your-configured-test-service-id'
export AMIGO_TEST_SERVICE_CONFIRMED='yes'
# AMIGO_API_KEY must already be supplied by your secret mechanism.
npm start
```
Use the regional base supplied for your deployment; the US base above is an example. Confirm the prerequisites before setting the test-service flag. The program sends one synthetic user message. Agent wording varies with your configuration and runtime.
{% endtab %}
{% endtabs %}
## 3. Inspect the Evidence
Read `artifacts/result.json`. A successful local run includes:
```json
{
"mode": "local-fixture",
"conversation_id": "33333333-3333-4333-8333-333333333333",
"answer": "Confirm the appointment, the requested change, available alternatives, and the authority to make the change. No appointment has been changed.",
"durable_answer_verified": true,
"closed": true,
"external_action_verified": false
}
```
For a provisioned run, `mode` is `provisioned-platform`, and the ID and answer come from your service. The program verifies that every returned agent answer is present in conversation history and that closure is visible on a subsequent read. A completed text answer establishes neither booking success nor the quality of a clinical decision.
The program writes `artifacts/progress.json` as soon as creation succeeds, before submitting a turn. If a later request fails, keep that ID and inspect the conversation before retrying. Only a zero exit status and the result from **this run** establish success; an older result file is not new evidence.
## 4. Exercise a Rejection
```bash
npm run demo:failure
```
This sends an invalid web-create request with `force_new: true`. The fixture returns a validation rejection, and the program records `expected_rejection: 422`. The current web contract rejects this combination because every web create already starts a new conversation. To exercise the same rejection in your provisioned test environment, use `npm start -- --invalid` with the prerequisites above.
An authentication error or transport failure does not count as the expected rejection. See the canonical [Conversation operations](/developer-guide/platform-api/conversations) for the request and response contracts.
## 5. Understand the Client
The following block is checked against the executable `src/starter.ts` on every PR. The CLI supplies either the fixture transport or your provisioned client.
```typescript
import { AmigoClient } from '@amigo-ai/platform-sdk'
export const message = 'This is a synthetic documentation exercise. What information would a scheduling team need before considering an appointment change? Do not book or change anything.'
export async function firstConversation(
client: AmigoClient,
serviceId: string,
onCreated: (id: string) => Promise = async () => {},
) {
const conversation = await client.conversations.create({ service_id: serviceId, channel: 'web' })
// Persist the ID before sending a turn, so an ambiguous failure can be investigated.
await onCreated(conversation.id)
const turn = await client.conversations.createTurn(conversation.id, { message })
if (turn.background_pending) {
throw new Error(`Background work remains for ${conversation.id}. Keep this conversation open and follow the web integration delivery guide.`)
}
const answers = turn.output.filter(item => item.role === 'agent' && item.text.trim())
if (!answers.length) throw new Error(`No completed agent answer for ${conversation.id}`)
const durable = await client.conversations.get(conversation.id)
if (!answers.every(answer => durable.turns?.some(item => item.role === 'agent' && item.text === answer.text))) {
throw new Error(`Answer not found in durable history for ${conversation.id}; investigate before retrying`)
}
await client.conversations.close(conversation.id)
const closed = await client.conversations.get(conversation.id)
if (closed.lifecycle !== 'closed') throw new Error(`Close was not confirmed for ${conversation.id}`)
return {
conversation_id: conversation.id,
answer: answers.map(item => item.text).join('\n'),
durable_answer_verified: true,
closed: true,
external_action_verified: false,
}
}
export async function demonstrateRejection(client: AmigoClient, serviceId: string) {
try {
await client.conversations.create({ service_id: serviceId, channel: 'web', force_new: true })
} catch (error) {
if (error && typeof error === 'object' && 'statusCode' in error && error.statusCode === 422) {
return { expected_rejection: 422, reason: 'force_new does not apply to web conversations' }
}
throw error
}
throw new Error('Expected a validation rejection but the request succeeded; stop and investigate the contract')
}
```
If `background_pending` is true, the starter stops without claiming a completed answer or automatically closing the conversation. Implement the receipt-based delivery flow in [Serve an Agent From a Web App](/developer-guide/platform-api/conversations/serve-agent-from-web-app) before choosing a service with background tools.
## 6. Clean Up and Continue
A successful conversation run closes its created conversation and verifies closure. Closing ends the conversation lifecycle; it does not erase retained records. After an incomplete run, inspect the saved ID, reconcile pending work, and use the [close operation](/developer-guide/platform-api/conversations) when appropriate. Follow your workspace's retention and deletion process for test records.
Local artifacts and fixture state are disposable. Remove `artifacts/` when you no longer need the evidence, and revoke a temporary test key through your normal credential process. The starter does not create a service, entity, sender, or external appointment.
For production, add scoped browser access, request correlation, background delivery and acknowledgement, retry reconciliation, operational monitoring, and workflow-specific authorization. Continue with [Verify an Integration Action](/developer-guide/guides/verify-an-integration-action), [Test a Managed SMS Workflow](/developer-guide/guides/test-managed-sms), or [Troubleshoot an Integration](/developer-guide/guides/troubleshooting). Use the [SDK Quickstart](/developer-guide/platform-api/platform-sdk/quickstart) for additional operations.
# Verify an Integration Action
Verify a configured integration action from authorization through target acknowledgement, including rejection, ambiguous delivery, and test cleanup.
Use this guide after [First Verified Conversation](/developer-guide/guides/first-verified-conversation) to verify work outside the conversation. The example is a synthetic appointment change against a scheduling test system. Your integration owner supplies the target contract and fixture; Amigo does not define one universal appointment-write payload for every scheduling system.
## Prerequisites
Have a configured test service, a test integration and endpoint, credentials limited to synthetic records, and permission to inspect the operation's evidence. Choose one fixture appointment, record its starting value, and document how the target can be read back and restored. The integration owner must verify that the selected endpoint has no production side effects.
Decide whether the test uses direct execution or [approval-gated integration writes](/developer-guide/platform-api/integrations/approval-gated-integration-writes). Approval policies and connector write-back review are different paths. The [Review Queue](/developer-guide/platform-api/integrations/review-queue) is a separately enabled preview; it is not a prerequisite for every integration action.
## 1. Establish the Contract and Access
Use [Integrations](/developer-guide/platform-api/integrations) to inspect the configured endpoint and its input schema. Verify that the test service exposes the intended tool and that its principal has the required access. [Tool Testing](/developer-guide/platform-api/functions/tool-testing) explains resolution and the separate integration-endpoint test operation.
Record the service configuration, integration/endpoint identifiers, synthetic target record, proposed old-to-new change, and external read-back method. A test label or a generic dry-run flag is not a universal guarantee that nothing will be written.
## 2. Test the Action in Isolation
Invoke the integration endpoint's dedicated test operation using the fixture payload that matches its schema. Save the returned result and inspect the target record independently. Classify the result as confirmed, rejected, failed, or unresolved.
A returned success from a tool can describe request acceptance rather than a committed target change. If the target processes requests asynchronously, use its documented completion/read-back procedure. Do not invent a retry or idempotency contract where the integration does not provide one.
## 3. Exercise the Conversation Path
Start a new test conversation with the configured service and request the same bounded change. Inspect the selected tool, its input, the result, and the resulting agent statement through [Conversation detail](/developer-guide/platform-api/conversations) with tool-call metadata requested where supported.
For an approval-gated call, verify that the target remains unchanged while the write is parked. Review the exact pending payload, record an approval or rejection through the supported decision operation, and exercise the next supported turn. A granted decision alone is not target acknowledgement. Voice approval behavior is not implied by the text/SMS path.
## 4. Prove the Failure Boundary
| Case | Evidence required before passing |
| --------------------------------- | ---------------------------------------------------------------------------------------------- |
| Missing or unauthorized input | The action is refused and the target remains unchanged |
| Reviewer rejects a parked write | No external write; the agent communicates the rejection accurately |
| Target rejects the request | The actual error is recorded; the agent does not confirm a completed change |
| Connection fails after submission | The result remains unresolved until target read-back or reconciliation establishes the outcome |
| Successful target change | Read-back confirms the intended record and value; the agent's statement matches that evidence |
An approval consumption can precede an interrupted external call. Verify the destination before any manual retry. Repeating a conversation turn is not proof that a target write will be deduplicated.
## 5. Save Evidence and Clean Up
Use the [evaluation packet](https://docs.amigo.ai/platform-overview/evaluation-packet) to record each case, configuration, conversation, operation, target acknowledgement, and reviewer decision. Restore the synthetic appointment using the target's supported process, close test conversations, and reconcile any unresolved writes before deleting test evidence.
You are ready to extend the workflow when both normal and failure cases have target evidence. Move to [managed SMS testing](/developer-guide/guides/test-managed-sms) for channel behavior or [troubleshooting](/developer-guide/guides/troubleshooting) when the evidence stops at an intermediate stage.
# Test a Managed SMS Workflow
Test a provisioned SMS workflow through routing, consent controls, conversation evidence, recipient delivery, suppression, and operational handoff.
A working text client does not verify SMS delivery. Use a provisioned test use case and a recipient controlled by your test team to exercise the actual channel. This guide follows Amigo's managed SMS boundaries; use [SMS](/developer-guide/platform-api/conversations/sms) for the implementation contract and [SMS concepts](https://docs.amigo.ai/channels/sms) for sender and consent-control behavior.
## Before You Start
Complete managed provisioning with Amigo: the sender resources and registration, eligible use-case identifier, workspace linkage, and inbound routing must be ready. Your team must hold consent evidence appropriate to the sending brand and intended test messages. Also have a configured test service, a controlled recipient, access to the exposed delivery evidence, and an Amigo contact for managed-channel issues.
A workspace credential can use the public service-binding and conversation operations. It does not grant the separate sender-provisioning or suppression-management permissions. Record the test sender, recipient, use case, and responsible operator before sending.
## 1. Verify Routing
Use [Use Cases and Bindings](/developer-guide/platform-api/workspaces/use-cases) to inspect the provisioned use case's service binding. Confirm that inbound test content reaches the expected service. A binding establishes routing; it does not establish registration approval or recipient consent.
## 2. Send One Bounded Test
Follow [Starting an Outbound Conversation](/developer-guide/platform-api/conversations#starting-an-outbound-conversation) with the SMS channel, configured service, managed use case, and controlled recipient. The managed channel selects the sender from its provisioned resources.
Record separate observations:
1. Whether conversation creation succeeded and which conversation was selected.
2. What the agent produced and whether channel policy accepted the send.
3. Provider acceptance and any later delivery status available for the deployment.
4. What the controlled recipient actually received.
If a final carrier receipt is unavailable, record that absence. A screenshot from the controlled recipient can support this test's observed receipt; it does not establish a universal delivery guarantee.
## 3. Exercise Inbound and Suppression Behavior
Reply from the controlled recipient and verify that ordinary content reaches the intended non-terminal conversation. Phone continuity does not by itself establish patient identity.
On the supported sender path, exercise the recognized opt-out flow with the provisioning owner. Verify that ordinary sends are suppressed across the managed business setup. Do not try another sender or conversation as a way to bypass suppression.
On the supported toll-free path, `START` or `UNSTOP` clears the line-specific opt-out only. Setup-wide suppression requires a separately authorized reversal with a recorded reason. Agree on test cleanup with the Amigo operator before exercising this case; your workspace application cannot reverse it itself.
## 4. Decide Whether the Channel Is Ready
Pass the test only when routing, expected recipient behavior, policy checks, and exception ownership are supported by the evidence. Mark an unavailable receipt or unresolved send explicitly rather than converting it into delivery success. An opt-in-message send record establishes provider acceptance of that message, not proof of prior consent.
Close test conversations when appropriate. Retain suppression and consent records according to the agreed process; do not clear them merely to get a test to pass. For a production launch, repeat the relevant cases with the actual approved sender configuration, channel-specific limits, monitoring, and staffed escalation path.
Use [Troubleshoot an Integration](/developer-guide/guides/troubleshooting) to package missing-delivery evidence for the team that owns the failing boundary.
# Troubleshoot an Integration
Locate failed authentication, missing context, incomplete turns, unresolved writes, and missing delivery, then collect the evidence needed to recover.
Start with the last milestone you can prove: authenticated request, usable context, accepted turn, completed answer, confirmed external action, or recipient delivery. A later milestone cannot be inferred from an earlier one.
## Find the Failing Boundary
| Symptom | Check first | Next action |
| ----------------------------------------------------- | --------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Authentication fails | API family, regional host, workspace/organization, credential scope and expiry | Follow [Authentication](/developer-guide/getting-started/authentication); keep Platform, Classic, and provider credentials separate |
| A service or entity is not found | Exact workspace and supplied identifiers; source acceptance versus projection/queryability | Inspect [Services](/developer-guide/platform-api/workspaces/services) and [Entity Resolve](/developer-guide/platform-api/data-world-model/entity-resolve); do not select an arbitrary production record |
| An SDK example does not compile | Package name, pinned version, lockfile, and Node version | Reproduce the [starter](/developer-guide/guides/first-verified-conversation) with `npm ci`; distinguish SDK drift from a runtime failure |
| A turn returns an acknowledgement but no final answer | `background_pending`, delivery protocol support, and returned receipt | Follow [web application delivery](/developer-guide/platform-api/conversations/serve-agent-from-web-app); an observer dashboard stream is not the per-chat delivery protocol |
| A connection drops after a turn was sent | Saved conversation ID and durable history | Read the conversation before resending; the original turn may have been processed |
| Approval is granted but the target did not change | Decision consumption, next supported turn, actual integration result, target read-back | Follow [approval-gated writes](/developer-guide/platform-api/integrations/approval-gated-integration-writes); reconcile an ambiguous target result before retrying |
| A tool cannot be tested | Tool family, endpoint identifiers, test permission, and applicable test operation | Follow [Tool Testing](/developer-guide/platform-api/functions/tool-testing); its generic execute operation does not execute every tool family |
| An SMS reply never arrives | Registration/routing, suppression, send acceptance, exposed delivery evidence | Follow [managed SMS testing](/developer-guide/guides/test-managed-sms); a created conversation is not a delivery receipt |
| A Scribe artifact is not ready | Correct deployment base, provider access, session mode, generation status, and review version | Follow [Scribe](/developer-guide/platform-api/scribe); generation acceptance is separate from a ready artifact |
| A test succeeds but production fails | Selected versions, actual channel, source freshness, tool access, and runtime differences | Compare the [deployment configuration](https://docs.amigo.ai/platform-overview/deployment-model) and rerun the failing case on its intended path |
## Preserve Evidence Before Retrying
Platform and managed-channel requests can return `503` during maintenance. A successful health check does not establish that those operations are accepting work. Check the response and the agreed status or support channel; do not treat a send acknowledgement, missing delivery receipt, or timeout as permission to send the same message again.
For an ambiguous request, keep the original identifiers and timestamp. Check durable state and the target system where applicable. A new conversation or retry can create new work; it is not a reconciliation mechanism.
Use the specific operation's retry guidance and exposed rate-limit information. There is no one platform-wide retry interval or rate limit. See [SDK Error Handling](/developer-guide/platform-api/platform-sdk/error-handling) and [Rate Limits](/developer-guide/operations/reference/rate-limits).
## Prepare an Escalation
Send the responsible implementation or support contact the API/channel, region, workspace, UTC timestamp, SDK version, selected service/configuration, conversation/run identifier, available request identifier, expected milestone, and last observed result. Include a minimal synthetic reproduction and the relevant error/status when possible.
Describe whether the outcome is known to have failed or remains unknown, and what retries or manual actions have already occurred. Use the agreed secure support route for sensitive evidence. Do not paste credentials, private transcripts, or patient records into public documentation issues.
## Verify Recovery
Repeat the smallest failing case, confirm the intended durable or external outcome, and confirm that retries did not create unintended duplicate work. Record the correction and add the failure case to the deployment's regression set. Close test conversations and reconcile pending actions using their owning lifecycle; closing a conversation does not undo a completed external write.
# Build a KB Agent End to End
Build a role-scoped knowledge-base agent end to end: load your data, assign roles, build the agent, test it, and manage it over time.
This guide walks the whole path: get your data into the platform, scope access so each user only sees what their role permits, build the agent, test it, and keep changing it safely. It assumes you are new to the platform and points you to the exact pages and commands at each step. Workspace access, source-specific connector configuration, and queryable tables must be ready before the relevant steps. Raw file uploads can require Amigo-assisted table setup; see the prerequisites below.
{% hint style="info" %}
**Read this guide first.** It covers the whole build path. When you reach step 3, the retrieval-architecture decision and the measurement-driven build loop are covered in depth in the companion deep-dive, [Knowledge-Base Agent: Retrieval and Build Methodology](/developer-guide/guides/building-a-knowledge-base-agent).
{% endhint %}
**What you'll build:** an agent that answers your team's questions from your own knowledge base, where each user sees only the documents and tools their role allows, and any per-user integration is called as that user.
**The path:**
1. **Load your data** so the platform can serve it.
2. **Assign roles** so each user sees the right data (skip if you don't need per-user scoping).
3. **Build the agent** that finds and grounds answers.
4. **Test it** for answer quality and for correct permissions.
5. **Change, test, and deploy** as you keep improving it.
A few terms used throughout: the **world model** is the platform's normalized store of your data; an **entity** is one record in it (a person, an encounter); a **skill** or **tool** is something the agent can do or call; a **context graph** is the agent's conversation state machine. If any of these are new, skim [Core Concepts](/developer-guide/getting-started/core-concepts) first.
## Before you start
* For raw file uploads, an agreed dataset contract and a queryable-table setup with your Amigo contact. Upload acceptance alone does not make a file retrievable by an agent.
* A workspace and platform credentials. See [Authentication & API Keys](/developer-guide/platform-api/platform-api/authentication).
* The `forge platform` CLI (used for the commands below), or the console. Either works.
* All commands below use `--env `, which points the CLI at your workspace credentials. The example values (emails, ids, role names) are placeholders; replace them with your own.
## Step 1: Load your data
You are loading two kinds of data: the **documents** your agent answers from (your knowledge base), and, if you'll scope access per user, the **people** who use it (and their roles). Choose the supported ingestion path for your source. Confirm mapping, processing, and queryability separately from submission.
### FHIR data (already in a healthcare format)
Push a FHIR bundle and it projects into the world model automatically, no custom code:
```bash
# a FHIR bundle (patients, practitioners, encounters, ...)
curl -X POST "https://api.platform.amigo.ai/v1/${WORKSPACE_ID}/fhir/import" \
-H "Authorization: Bearer ${API_KEY}" \
-H "Content-Type: application/json" \
--data @bundle.json
# or stream many resources as NDJSON
curl -X POST "https://api.platform.amigo.ai/v1/${WORKSPACE_ID}/fhir/import-stream" \
-H "Authorization: Bearer ${API_KEY}" \
-H "Content-Type: application/x-ndjson" \
--data-binary @resources.ndjson
```
This is the best path for clinicians and patients, which are typically already FHIR (a clinician is a `Practitioner`). See [FHIR](/developer-guide/platform-api/data-world-model/fhir).
### A live connection (a connector)
Register a supported source using its validated connector configuration. Save that complete request as `data-source.json`; the required connection fields depend on the connector. Do not send the literal placeholder object from an architectural example:
```bash
# register a source: a REST API, a SQL / warehouse zone, or a FHIR store
curl -X POST "https://api.platform.amigo.ai/v1/${WORKSPACE_ID}/data-sources" \
-H "Authorization: Bearer ${API_KEY}" -H "Content-Type: application/json" \
--data @data-source.json
# trigger a sync now (otherwise it runs on its schedule)
curl -X POST "https://api.platform.amigo.ai/v1/${WORKSPACE_ID}/data-sources/${DATA_SOURCE_ID}/sync" \
-H "Authorization: Bearer ${API_KEY}"
```
Best for data that changes and should stay fresh. See [Connector Runner](/developer-guide/platform-api/data-world-model/connector-runner).
### A file upload
For a one-off file, register the dataset contract and upload the file with a workspace credential. See [Data Intake](/developer-guide/platform-api/data-world-model/intake) for the current upload operation and processing workflow. The former shareable upload-link system has been retired.
{% hint style="info" %}
**An uploaded file needs one more step before an agent can query it.** Supported FHIR imports and connector records must finish mapping and projection before you verify queryability. A raw file upload (for example a CSV) is stored and logged, but turning it into a structured table the agent can query is not yet automatic, so work with your Amigo contact to set that table up. Once the table exists, you expose it to the agent as a warehouse tool (step 3).
{% endhint %}
### Keeping data current and controlling what's exposed
* **Update:** connectors re-sync on their schedule (or on demand with the `/sync` call above); re-importing a FHIR bundle updates the affected resources.
* **History:** check what a connector synced with `GET /v1/{workspace_id}/data-sources/{id}/sync-history`, and a FHIR resource's version history with `GET /v1/{workspace_id}/fhir/resources/{resource_type}/{resource_id}/history`.
* **Exposure:** which data a given user's agent can actually reach is controlled by role grants (step 2) and by which tables the agent's tools query (step 3), not by the raw data load.
## Step 2: Assign roles so each user sees the right data
Skip this step if every session is the same and there is no per-user scoping.
If different users should see different things (a clinician sees their caseload, a specialist sees specialist procedures, an administrator can't read clinical detail), use **external principals**. The model never decides who the user is: you map each user to an entity and its roles, and the platform scopes the agent's tools and data to those roles and passes the user's identity through to your integrations. Set it up in four commands.
### 2.1 Register your roles
A role is a named bundle that grants attach to. Create one per role your system uses:
```bash
forge platform external-role create --env \
-b '{"name":"clinician","external_name":"Clinician","description":"Every credentialed clinician"}'
forge platform external-role create --env \
-b '{"name":"specialist","external_name":"Specialist","description":"Specialist-credentialed clinicians"}'
```
`name` is the internal slug you'll reference; `external_name` is your system's label. List them to get their ids: `forge platform external-role list --env `. (Endpoint: `POST /v1/{workspace_id}/external-roles`.)
### 2.2 Map each user to an entity and roles
Each user is a person entity in the world model (loaded in step 1; `entity_id` is that person's world-model id, which you can look up via [Data & World Model](/developer-guide/platform-api/data-world-model)). Bind the user's identity and roles to it:
```bash
forge platform role-assignment upsert --env \
-b '{
"source": "staff_directory",
"external_subject_key": "clinician@example.com",
"display_name": "Jordan Lee",
"entity_id": "",
"roles": ["clinician"],
"roles_verified": true,
"provisioned_via": "roster_sync"
}'
```
`external_subject_key` is the user's stable identity (usually their email); it's what gets passed through to your integrations. Re-running with the same `(source, external_subject_key)` updates in place, so a roster sync is idempotent. A multi-role user just lists multiple roles and gets the union. (Endpoint: `PUT /v1/{workspace_id}/external-role-assignments`.)
### 2.3 Grant each role its scopes
A grant says "this role may use this resource." `resource_type` is one of `kb_scope` (a scope tag on your documents), `skill` (a skill slug), or `integration_endpoint` (an endpoint id); `access` is `read` or `write`:
```bash
# clinicians can read the general KB scope
forge platform role-grant create --env \
-b '{"role_id":"","resource_type":"kb_scope","resource_key":"general","access":"read"}'
# ...and call a lookup skill
forge platform role-grant create --env \
-b '{"role_id":"","resource_type":"skill","resource_key":"clinician-lookup","access":"read"}'
# scope an endpoint param to the caller's own id, so they only see their own data
forge platform role-grant create --env \
-b '{"role_id":"","resource_type":"integration_endpoint","resource_key":"","access":"read","param_binding":"providerId=principal.subject_id"}'
```
A resource is unrestricted until a grant references it; once any grant does, only the granted roles may use it. (Endpoint: `POST /v1/{workspace_id}/role-grants`.)
### 2.4 Anchor the conversation to the user's entity
In production the user's SSO session anchors the conversation automatically. To start one yourself (for testing, or operator-started sessions), pass the entity explicitly:
```bash
forge platform conversation create --env \
--service-id \
--entity-id
```
From here, every tool call and integration is scoped to that user's roles for the life of the session. For the full reference, see [External Principals](/developer-guide/platform-api/integrations/external-principals).
## Step 3: Build the agent
A KB agent has three moving parts: an **index** of your documents the agent can see, a **tool** to fetch a document by id, and a **retrieval strategy**. For a small knowledge base, the simplest strategy wins: preload the whole catalog (titles and ids) so the agent picks the documents it needs and fetches them by id. For a larger corpus, switch to hybrid search.
Build it measurement-first: write the conversations you want the agent to handle as tests, start from a bare-bones agent, and add only what a failing test demands. The agent ends up with exactly the complexity its tests require, and nothing speculative.
### Adding what the agent can do
The agent acts through **skills** and **tools**. A skill is an LLM-driven capability; a tool or platform function calls out to data or an API. Common additions:
* Query a table you loaded in step 1 (for example, ad-hoc analytics): create a **warehouse tool**, a SQL [platform function](/developer-guide/platform-api/functions) that selects from your table. The agent calls it like any tool.
* Call an external system: configure an [integration](/developer-guide/platform-api/integrations) and expose its endpoints as tools.
* Add a capability: author a [skill](/developer-guide/platform-api/workspaces/skills).
{% hint style="info" %}
**If an endpoint the agent needs doesn't exist yet, it has to be built first.** The platform can call an endpoint, but it can't invent one. An API your agent should use that doesn't exist in your systems today is net-new work (by your team or with Amigo) before it can be wired in as an integration.
{% endhint %}
{% hint style="success" %}
The retrieval-architecture decision (catalog-preload vs hybrid search) and the full measurement-driven build loop are covered in depth in [Knowledge-Base Agent: Retrieval and Build Methodology](/developer-guide/guides/building-a-knowledge-base-agent). For the moving parts: [Agents](/developer-guide/platform-api/workspaces/agents) covers the agent persona, [Agents & Context Graphs](/developer-guide/classic-api/core-api/agents-and-context-graphs) covers the context graph (the conversation state machine), and [Skills](/developer-guide/platform-api/workspaces/skills) covers capabilities.
{% endhint %}
## Step 4: Test it
Test two things separately.
**Answer quality.** Does the agent fetch the right document, ground its reply in it, and decline when the knowledge base has no answer? Build a fixed question set with known-good answers and run it. That question set is the durable asset: every future change becomes a quick re-run instead of a guess. See [Simulation Coverage](/developer-guide/platform-api/safety/simulation-coverage) and [Tool Testing](/developer-guide/platform-api/functions/tool-testing).
**Permissions.** Anchor a conversation as a given role and confirm the agent only reaches what that role permits.
{% hint style="info" %}
**Test permissions at the right layer.** Tool and integration-endpoint grants are enforced by the platform: a disallowed tool call returns a structured refusal you can see in the transcript. Knowledge-base document scoping is enforced today by the agent's own behavior reading the user's role context, so verify it by checking the agent's fetches against the role rather than expecting a platform-level block.
{% endhint %}
## Step 5: Change, test, and deploy over time
Once the agent is live you'll keep changing it. Do that safely with version sets and regression tests.
* **Version sets** pin which agent, context graph, and model a service uses, like git branches for your configuration. `edge` always points at your latest; `release` is what production serves. You iterate on a version set, then promote it to `release` to deploy. See [Version Sets & Promotion](/developer-guide/operations/devops/version-sets-best-practices).
* **Regression-test before you promote.** Re-run the test set from step 4 against the changed version and compare it to a saved baseline; promote only if it holds. The [methodology guide](/developer-guide/guides/building-a-knowledge-base-agent) covers running the suite, saving baselines, and reading the diff.
So the lifecycle is one loop: **change** on a version set, **regression-test** against your suite, **promote** to `release` to deploy. Repeat.
## You're done
You loaded data, scoped access, built an agent, tested it, and have a safe way to keep changing it, end to end. From here: expand your test set as you find gaps, add live-lookup tools for real-time data, and move to hybrid search as the knowledge base grows past the catalog-preload size.
# KB Agent: Retrieval & Build Methodology
How to choose a retrieval architecture for a knowledge-base agent, and a measurement-driven process for building one.
{% hint style="info" %}
**This is the deep-dive.** It is the depth behind step 3 of [Build a Knowledge-Base Agent End to End](/developer-guide/guides/build-a-kb-agent-end-to-end). Start there for the full path (load data, assign roles, build, test); come here for how retrieval and the build loop work.
{% endhint %}
A knowledge-base (KB) agent answers questions over a body of documents. On every turn it has to find the document that actually contains the answer (and only that one), ground its reply in it, and say so when the KB has no answer instead of guessing.
This guide covers two things:
1. **How to choose a retrieval architecture** for your corpus, and why.
2. **How to build the agent**: a measurement-driven process that produces exactly the agent your tests require and nothing more.
The recommendations come from building KB agents on Amigo and align with published retrieval research.
## TL;DR
1. **For a small KB (roughly 800 documents or fewer), preload the whole catalog instead of doing RAG.** The agent reads a complete index of titles and ids once, then fetches the exact documents it needs. This avoids any ranking step that could miss the right document, is cache-friendly, and lets the agent answer "not in the KB" honestly. It matches published guidance: when the corpus fits in context, put it in the prompt and rely on prompt caching.
2. **When you outgrow the catalog, switch to hybrid search (BM25 + vector, fused), not pure vector and not pure keyword.** Hybrid finds the right document most reliably, but it will always return *something*, so it has to ship with an explicit "decline when nothing is a good match" behavior.
3. **Retrieval is the easy part; the corpus and the integration are the hard parts.** Data quality is the single biggest lever, and an approach that looks best on retrieval alone can still do worse once it's inside the full agent.
4. **Evaluate before you optimize.** The most valuable thing you build is not the agent, it's the question set that turns every future change into a quick re-run instead of a guess.
## Pick the retrieval architecture by corpus size
| Corpus | Approach | Notes |
| ------------------------------------------------------ | ------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **\~800 docs or fewer / index fits in context** | **Catalog-preload** | The agent loads an index of titles + ids once, then fetches exact documents by id. Cache-friendly, no ranking step to lose a document, honest about misses. |
| **Larger, or the index exceeds the result-size limit** | **Hybrid search (BM25 + vector, fused with RRF)** | Beats pure vector on retrieval quality. Must ship with a decline-when-no-good-match behavior, because search always returns something. |
| **Real scale** | **Hybrid + metadata/scope filtering + reranking** | Filtering is the biggest precision lever at scale; reranking adds roughly 15% quality on top, at a latency cost. |
### Why catalog-preload works for a small KB
When the index of every document's title and id fits in the prompt, you don't need a retrieval pipeline at all. The agent sees the whole corpus, picks the documents it needs by title, and fetches them by id. There is no ranking step to lose the right document, no similarity threshold to tune, and the index is a stable prefix that prompt caching makes cheap. It is also honest about "no answer": if nothing in the catalog matches, the agent can say so, rather than being handed the nearest few documents and tempted to stretch.
In practice, catalog-preload matches search on finding the right document, does better at declining when the KB genuinely has no answer, and composes cleanly with the rest of the agent.
### The catalog ceiling
The catalog has to physically reach the agent. A single tool result is truncated once it exceeds 128 KB: an oversized catalog is cut off, with a truncation notice, rather than delivered whole. Keep the index well under that. A title-and-id index of a few hundred documents fits with comfortable headroom; per-row summaries eat the budget fast. Two rules follow:
* **Keep the catalog lean.** Document id, title, page group, and scope tags are enough. Make the **titles** carry the selection signal; drop per-row summaries.
* **Around 800 documents, switch to search.** That is the trigger to move off catalog-preload.
### When you do need search
Past the catalog ceiling, fuse keyword and semantic retrieval rather than choosing one. Use real BM25 for the keyword leg (term-frequency saturation, inverse document frequency, and length normalization), not a plain term-count, which ranks the wrong document first whenever a rare exact term matters (a fee amount, a policy number). Fuse the keyword and vector result lists with reciprocal rank fusion (RRF).
Better retrieval makes the honesty problem harder, not easier: search always returns its nearest documents, which tempts the agent to answer when it shouldn't. So any search-based agent needs an explicit "decline when nothing clears the similarity threshold" behavior before it goes live. At real scale, add metadata/scope filtering (the biggest precision lever) and then reranking.
## Build it measurement-first: two principles
The build process rests on two principles. Everything else (the coverage matrix, the briefs, the iteration loop) follows from them.
### Principle 1: start from a bare-bones agent; add complexity only when a test demands it
Your first version is the minimum agent that handles the first turn of the first conversation. Nothing more: no speculative behaviors, no preemptive guardrails, no conversation states for scenarios you haven't tested. Then run the tests, and for each turn that fails, apply the single smallest change that fixes it and re-run.
Behaviors, guardrails, states, and tools get pulled in by test failures, not pushed in by upfront planning. The agent ends with exactly the complexity its tests require. Every piece traces to a test, rollback is cheap because each version is a measurable artifact, and the agent ships in hours instead of weeks.
### Principle 2: start from real conversations, then build the agent to satisfy them
Don't write the agent configuration first. Write the conversations first. A test conversation is a contract: this is what the user says, and this is how the agent must respond. The user message is fixed (the same every run); the expected behavior is captured as semantic judge criteria plus exact-match checks for any literal value that matters.
Once the conversations exist, the agent design isn't a separate step, it emerges from the iteration loop. Each failure points to exactly one thing to add:
| What the failing test shows | What you add |
| ----------------------------------------------------------- | ----------------------------------- |
| The agent doesn't know a piece of session context | One context field |
| The agent can't fetch information the reply needs | One tool (name, args, return shape) |
| The agent needs structured per-conversation data | One entity enrichment field |
| The agent says the wrong thing across turns | One behavior |
| The agent violates a "must never" | One guardrail |
| The agent loses the topic or re-escalates when it shouldn't | One conversation-state transition |
The conversations are the spec; the agent configuration is the implementation; you reverse-engineer it one piece at a time. There is no separate "design the agent" stage: the conversations are written upfront, the agent is not.
## The build process, end to end
### Stage 0: understand the requirements
Read the requirements and build a shared understanding of the user flows, guardrails, acceptance tests, capabilities, KB topics, and role/access scopes. This stage produces understanding, not configuration. Flag ambiguities now (names, escalation destinations, category values); they otherwise surface mid-build.
### Stage 1: coverage matrix
Find the smallest set of conversations that exercises every requirement.
* **8 to 12 conversations.** More becomes unmaintainable; fewer misses coverage.
* **Boundary cases need a conversation on both sides.** A scope-isolation rule needs a positive case (the in-scope user gets the content) and a negative case (the out-of-scope user is refused). An escalation rule needs a must-escalate case and a must-not-re-escalate case.
* **Persona variety drives role-scope coverage.** A single-persona set tests no role scoping. Writing a conversation for each role forces you to decide what that role can reach.
* **Mark requirements you intentionally don't cover**, so a gap is a decision rather than an oversight.
### Stage 2: write a brief per conversation
For each conversation, write the persona (name, role, scopes, region), the per-turn context, two to five turn summaries, what it must prove, and the acceptance criteria (exact-match checks plus judge criteria).
{% hint style="warning" %}
**The most important authoring rule: every judge criterion must be answerable from the reply text alone.** The judge sees the user message and the agent's reply, not the persona, the context, or any scene metadata.
Instead of "Did the reply name the caller's assigned supervisor?", write "Did the reply name 'Dr. Alex Rivera' as the routing destination?" The verbatim expected value is verifiable from the reply; the persona reference is not. Getting this wrong undermines the whole judging step.
{% endhint %}
### Stage 3: write the conversations
Turn the summaries into verbatim user messages, and make the phrasing realistic. Synthetic phrasing won't catch production failures.
* Sanitized: "What is the no-show fee policy?"
* Realistic: "Hey, quick one. Had a same-day no-show this morning, a client in my 10am slot. They messaged about 30 min before saying they had a family emergency. Do I still apply the standard no-show fee, or does the emergency waive it?"
Real messages have specific names, amounts, multi-sentence framing, and embedded follow-ups. That is what production traffic looks like. Stages 0 through 3 are the only stages that produce artifacts before you deploy anything.
### The iteration loop
There is no "write the agent configuration" stage. Deploy the bare-bones agent: a name, a one-line description, one conversation state, no behaviors, no tools. It will fail almost every turn, and that's the point.
Then iterate. Run the test set; for each failing turn, ask "what is the smallest change that fixes this turn?", apply only that change, re-run, and save a baseline at each version so you can see regressions. Add the smallest pieces in rough order from mechanical to judgmental:
1. A tool (name, args, return shape inferred from how the reply uses the result)
2. A session context field
3. A guardrail (one binary "must never")
4. A constraint on phrasing in a specific state
5. A behavior (one cross-turn pattern)
6. A conversation-state or transition (most likely to interact with others, so add these last)
Add one piece per failure. Adding several at once loses track of which one fixed the turn.
### Test the whole agent, not just retrieval
Good retrieval in isolation is not enough. The approach has to hold up inside the full agent, with all its safety behaviors, on a harder multi-turn test set. It is common for an approach that edges ahead on raw retrieval to fall behind once it's inside the full agent, where safety behaviors and multi-turn flow interact. That is exactly why you test the whole agent: the best retriever is a candidate, the agent you ship is whatever survives the full test set with safety intact.
## The evaluation harness (the asset worth keeping)
The test set is the thing worth keeping. With it, any future change (a model upgrade, a prompt edit, a new retrieval mechanism) becomes a quick re-run against a fixed set of questions, not a leap of faith.
* **A fixed question set with known-good answers and category coverage**: exact-fact questions, multi-step workflows, paraphrase (the wording differs from the document), multi-document (the answer needs two or more docs), and no-answer (the KB genuinely can't answer; the agent must decline). The no-answer category is non-negotiable; it is how you measure honesty.
* **Grade two ways.** Mechanical document-selection metrics (did the agent fetch the right document?) and an LLM judge on answer quality (binary, verbatim-anchored criteria). They catch different failures.
* **Verify your judge.** A weak judge model silently corrupts the comparison. Spot-check it on a criterion you can verify by eye; if it's noisy, use a stronger judge model rather than tuning the prompt around the noise.
* **Run it a few times and account for variance.** Agents are non-deterministic. Run each version several times, accept only if every run clears the threshold, and use baseline diffs to catch regressions against the prior version.
## Practical rules
1. **Evaluate first.** Build the question set before touching retrieval.
2. **Grade two ways.** Mechanical document-selection and a judge on answer quality.
3. **Verify your judge.** Use a stronger model if it's noisy; don't tune around the noise.
4. **Refusal is a first-class behavior.** Any approach that always returns documents needs an explicit decline. Better retrieval makes this more important, not less.
5. **Put trigger conditions in tool descriptions.** "Call this once before answering" works better than only describing what the tool does (the agent under-calls) or assuming a result is already present (the agent never calls it).
6. **Prompt with goals and constraints, not scripts.** Over-prescriptive prompts reduce output quality on current models. If you change the model, re-run the tests before editing any prompt, and never combine a model change and a prompt change in one version.
7. **Test the full agent, not just retrieval.**
8. **The corpus is usually the bottleneck.** When half your documents are empty or placeholder pages, no retrieval technique recovers the missing content. Fix data quality before chasing the last retrieval point.
## Role-scoped access
If the KB is segmented by who may see what, scope retrieval to the user's role rather than building a separate agent per segment. One way to do this is a behavior that reads the caller's role from session context and only fetches in-scope documents. Registering roles, anchoring a conversation to the user's entity, and passing identity through to per-user tools is covered in step 2 of [Build a Knowledge-Base Agent End to End](/developer-guide/guides/build-a-kb-agent-end-to-end), with the full reference in [External Principals](/developer-guide/platform-api/integrations/external-principals). The two guides are halves of one build: this one is how the agent finds and grounds answers, that one is how access is scoped.
## What a finished small-KB agent looks like
A small-KB agent built this way stays deliberately simple, because the test set only ever pulls in what it needs. A typical end state:
* **Retrieval:** catalog-in-prompt plus fetch-by-id. No separate search tool. The catalog (id, scope, title) goes in the prompt, and the agent fetches documents by id.
* **Tools: two.** Fetch a document by id, and escalate a safety signal. No search tool and no extra integrations unless a test demanded them.
* **Conversation states: three.** A `chat` state (answer via catalog, then fetch, then cite), a `safety_escalation` state (emit only the escalation message, no tools), and an `end` state.
* **A handful of behaviors, each added for a specific failing test**: answer operational questions only, catalog-then-fetch retrieval, escalate safety signals immediately with no KB content, isolate scope at the catalog level, read the caller's role from context, refuse general-knowledge lookups, quote numbered procedures verbatim, prefer the canonical policy source, and don't mix different populations' policies in one answer.
* **One communication pattern:** a peer-to-peer register (the user is a professional; skip the "great question" preambles).
A plan written from requirements alone might call for eight tools, a dozen states, and a search-and-rerank pipeline. Built measurement-first, the same agent often collapses to a couple of tools and a few states, because the test set never demands the speculative pieces.
{% hint style="info" %}
**Guardrails tend to live on conversation states, not on the agent.** It's natural to expect agent-wide guardrails, but in practice each guardrail attaches to a specific state (a safety check before responding in `chat`, "no KB content" in `safety_escalation`). Expect to place guardrails per state.
{% endhint %}
## Platform notes
* **A tool result is truncated past 128 KB.** See [The catalog ceiling](#the-catalog-ceiling) above: keep the catalog lean and confirm the whole index reaches the agent.
* **Refusal must be explicit for any search-based agent.** Search always returns its nearest matches; without a decline-when-no-good-match behavior the agent will stretch to answer.
* **Give each document a stable composite id, not the URL alone.** Pages can legitimately share a source URL; keying identity on the URL alone collapses distinct documents into one. Derive the id from the source URL plus a per-document discriminator such as the filename.
* **Cap the result set and the per-row excerpt** in the query itself, so a broad query over a large corpus can't overflow the context window. Carry citation fields (source URL, document id, page group) on each row.
* **Data quality is the real ceiling.** Audit the corpus before optimizing retrieval. Empty or placeholder documents are invisible to every retrieval method.
# Platform API Overview
Implement workspace data, agent configuration, conversations, integrations, and operations through the Amigo Platform API.
The Platform API connects workspace data, configured agents, supported voice and messaging workflows, integrations, and operational controls. Start with the resource that owns your task, then follow its endpoint contract and lifecycle guidance.
For the architecture behind these resources, read [Core Concepts](https://docs.amigo.ai/platform-overview/core-concepts). The [Getting Started guide](/developer-guide/getting-started) covers the initial integration sequence.
## Base URL
Use the regional hostname assigned to your deployment. `https://api.platform.amigo.ai` is the US default; it does not route a workspace to another region. HTTP paths in the public schema include the `/v1` prefix. SDK `baseUrl` configuration takes the origin without that prefix.
See [Regions & Endpoints](/developer-guide/getting-started/regions-and-endpoints) for regional configuration. Confirm access to any separate test deployment with your Amigo representative.
## Authentication
Workspace API keys can authenticate supported workspace resource routes as Bearer credentials. Interactive identity, external-user sessions, and machine-to-machine authorization have separate flows and scopes. Health routes can be unauthenticated. Follow [Authentication & API Keys](/developer-guide/platform-api/platform-api/authentication) and the specific resource guide instead of applying one credential rule to every endpoint.
## Workspace-Scoped Design
Workspace-scoped resources enforce the credential's access to the workspace in the path. Account, identity, and workspace-management operations have their own boundaries. Creating a workspace does not automatically provision a channel, load source data, or configure a service.
An association with a Classic organization does not make the two APIs' IDs or credentials interchangeable. Use the API and resource names in the [implementation map](/developer-guide/getting-started/core-concepts).
## Resource Guide
Use these groups to find the implementation path. The sidebar includes the detailed pages for each resource.
### Authentication & Platform
Authentication and protocol guides. Their scope depends on the route.
{% content-ref url="/pages/pgUT371DPqo400yNGm8c" %}
[Authentication & API Keys](/developer-guide/platform-api/platform-api/authentication)
{% endcontent-ref %}
* [OAuth2 (Machine-to-Machine)](/developer-guide/platform-api/platform-api/oauth2) - token endpoint, scope resolution, and token claims for the `client_credentials` grant
* [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients) - client registration, scopes, setup allow-lists, and secret rotation
* [Sessions](/developer-guide/platform-api/platform-api/sessions) - persistent WebSocket endpoint for low-latency text conversations
* [Pagination](/developer-guide/platform-api/platform-api/pagination) - continuation-token and limit/offset pagination styles
* [Health](/developer-guide/platform-api/platform-api/health) - unauthenticated endpoints for external health monitors
### Workspaces & Configuration
Workspace setup and the resources that define agent behavior.
{% content-ref url="/pages/u4TQxi28BJWhEKUfNGTC" %}
[Workspaces](/developer-guide/platform-api/workspaces)
{% endcontent-ref %}
* [Agents](/developer-guide/platform-api/workspaces/agents) - agent identity, guidance, and versioning
* [Skills](/developer-guide/platform-api/workspaces/skills) - companion definitions and the state bindings that govern their execution
* [Services](/developer-guide/platform-api/workspaces/services) - bind agents and context graphs into deployable units with version sets
* [Use Cases & Bindings](/developer-guide/platform-api/workspaces/use-cases) - channel use cases and service bindings
* [Scheduling Rule Sets](/developer-guide/platform-api/workspaces/scheduling-rule-sets) - deterministic appointment slot filtering rules
* [Voice Configuration](/developer-guide/platform-api/workspaces/voice-configuration) - per-service voice pipeline tuning
* [Client Config](/developer-guide/platform-api/workspaces/client-config) - client-safe configuration values for browser-side apps
### Conversations & Channels
Runtime conversation surfaces across phone, text, and web.
{% content-ref url="/pages/js8kvebm1nrcYWgMPlI0" %}
[Conversations](/developer-guide/platform-api/conversations)
{% endcontent-ref %}
* [Channels](/developer-guide/platform-api/conversations/channels) and [Channel Manager](/developer-guide/platform-api/conversations/channel-manager) - channel provisioning and routing
* [Calls](/developer-guide/platform-api/conversations/calls) and [Voice Agent](/developer-guide/platform-api/conversations/voice-agent) - voice call records and the real-time voice pipeline
* [SMS](/developer-guide/platform-api/conversations/sms) - managed message sending, consent boundaries, and delivery evidence
* [Voicemail](/developer-guide/platform-api/conversations/voicemail) - migration note for the retired standalone ringless channel
* [Runs](/developer-guide/platform-api/conversations/runs) - unified run inventory and channel-neutral controls
* [Desktop Sessions](/developer-guide/platform-api/conversations/desktop-sessions) - the supported desktop-session contract
* [Surfaces](/developer-guide/platform-api/conversations/surfaces) - agent-generated data collection forms
* [Operators](/developer-guide/platform-api/conversations/operators) - operator escalation and takeover
* [SSE Events](/developer-guide/platform-api/conversations/sse-events) and [Observer Events](/developer-guide/platform-api/conversations/observer-events) - streaming event schemas
* [Serve an Agent From a Web App](/developer-guide/platform-api/conversations/serve-agent-from-web-app) - embed an agent in your own web application
### Platform Functions & Tools
Data functions and tools the agent can call mid-conversation.
{% content-ref url="/pages/P8dU1ncnfOC4sR6Kd7IU" %}
[Platform Functions](/developer-guide/platform-api/functions)
{% endcontent-ref %}
* [Workspace Data Queries](/developer-guide/platform-api/functions/workspace-data-queries) - parameterized SQL templates over workspace tables
* [Tool Testing](/developer-guide/platform-api/functions/tool-testing) - resolve and execute context graph tools in isolation
* [Triggers](/developer-guide/platform-api/functions/triggers) - schedule recurring actions or fire them from external systems
* [MCP Server](/developer-guide/platform-api/functions/mcp-server) - workspace-scoped Model Context Protocol surface for external clients
* [Agent Runs](/developer-guide/platform-api/functions/agent-runs), [Harness Context](/developer-guide/platform-api/functions/harness-context), and [Agent Definitions](/developer-guide/platform-api/functions/agent-definitions) - supported framework execution and authored definitions
### Integrations
Connecting agents to external systems and external users to agents.
{% content-ref url="/pages/8XgxpLXbTwEa0DfgJstX" %}
[Integrations](/developer-guide/platform-api/integrations)
{% endcontent-ref %}
* [Approval-Gated Integration Writes](/developer-guide/platform-api/integrations/approval-gated-integration-writes) - supported conversation-scoped approval
* [Review Queue](/developer-guide/platform-api/integrations/review-queue) - the separate private-preview connector proposal workflow
* [External Integrations](/developer-guide/platform-api/integrations/external-integrations) - scoped credentials for third-party session creation
* [External Principals](/developer-guide/platform-api/integrations/external-principals) - entity-anchored, role-scoped tool access for external users
* [External User Subject-Key Binding](/developer-guide/platform-api/integrations/external-user-subject-key-binding) - bind verified external identity into integration auth
### Data & World Model
The event-sourced patient data store and its ingestion paths.
{% content-ref url="/pages/UZmj9knjuYak24tQk90Y" %}
[Data & World Model](/developer-guide/platform-api/data-world-model)
{% endcontent-ref %}
* [Entity Resolve](/developer-guide/platform-api/data-world-model/entity-resolve) - entity lookup and current resolution boundaries
* [Bulk Import](/developer-guide/platform-api/data-world-model/bulk-import) - migration-oriented ingestion
* [Workspace Tables](/developer-guide/platform-api/data-world-model/workspace-tables) - workspace-owned custom data tables
* [Customer Data Intake](/developer-guide/platform-api/data-world-model/intake) and [Intake Sources](/developer-guide/platform-api/data-world-model/intake-sources) - dataset file ingestion and source discovery
* [Intake Upload Links](/developer-guide/platform-api/data-world-model/intake-links) - migration note for the retired link and external HMAC paths
* [Connector Runner](/developer-guide/platform-api/data-world-model/connector-runner) - supported ingestion and policy-eligible delivery
* [FHIR](/developer-guide/platform-api/data-world-model/fhir) - FHIR clinical data endpoints
* [Data Access (MCP)](/developer-guide/platform-api/data-world-model/data-mcp) - standalone SQL access for external MCP clients using Classic API organization credentials
### Scribe
[Scribe](/developer-guide/platform-api/scribe) serves provider documentation workflows through a separately configured deployment. Follow its [sessions](/developer-guide/platform-api/scribe/sessions) and [artifacts](/developer-guide/platform-api/scribe/artifacts) guides for provider ownership, credentials, and completion behavior.
### Safety & Monitoring
Runtime safety, quality evaluation, and observability.
{% content-ref url="/pages/eN4MWcO2S0Wu6cGRs2Fo" %}
[Safety & Monitoring](/developer-guide/platform-api/safety)
{% endcontent-ref %}
* [Analytics & Observability](/developer-guide/platform-api/safety/analytics) - call analytics and quality trends
* [Insights](/developer-guide/platform-api/safety/insights) and [Metric Store](/developer-guide/platform-api/safety/metric-store) - derived metrics and storage
* [Call Trace Analysis](/developer-guide/platform-api/safety/call-trace-analysis) and [Voice Judge](/developer-guide/platform-api/safety/voice-judge) - per-call evaluation
* [Production Evals](/developer-guide/platform-api/safety/production-evals) and [Simulation Coverage](/developer-guide/platform-api/safety/simulation-coverage) - evaluation pipelines
* [Prompt Logs](/developer-guide/platform-api/safety/prompt-logs) - full LLM input/output for auditing and debugging
* [Trace Export](/developer-guide/platform-api/safety/trace-export) - exporting traces for offline analysis
{% hint style="info" %}
**Classic API features not in Platform API.** Dynamic Behaviors (rule-based triggers) and User Management are available only through the [Classic API](/developer-guide/classic-api/core-api). The Platform API has its own testing and evaluation surfaces - [Simulation Coverage](/developer-guide/platform-api/safety/simulation-coverage), [Production Evals](/developer-guide/platform-api/safety/production-evals), and the [Metric Store](/developer-guide/platform-api/safety/metric-store) - and handles user context through the [World Model](/developer-guide/platform-api/data-world-model).
{% endhint %}
## Pagination
Most resource list endpoints use continuation-token pagination (`items`, `has_more`, `continuation_token`, optional `total`); a fixed set of endpoint groups uses `limit`/`offset` instead. See [Pagination](/developer-guide/platform-api/platform-api/pagination) for both styles, the limit/offset endpoint list, and per-endpoint limits.
## API Reference
For full endpoint schemas, see the auto-generated [Platform API Reference](https://docs.amigo.ai/api-reference/readme/platform).
# Authentication & API Keys
Authenticate to the Platform API with workspace keys or device authorization, inspect the live permission catalog, and rotate or revoke credentials safely.
{% hint style="info" %}
**Provider M2M authentication.** Backend services that need to act as a specific provider can use provider M2M clients - a `client_credentials` grant that mints short-lived provider-scoped tokens. See [OAuth2 Clients - Provider M2M Clients](/developer-guide/platform-api/platform-api/oauth2-clients#provider-m2m-clients) for details.
{% endhint %}
{% hint style="info" %}
For machine-to-machine integrations, the platform supports OAuth2 client credentials. See [OAuth2 (Machine-to-Machine)](/developer-guide/platform-api/platform-api/oauth2) for the token flow and [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients) for client registration, scopes, and secret rotation.
{% endhint %}
This page covers **workspace-scoped API keys** and the **interactive device code flow**. Scoped OAuth2 and provider credentials use the separate flows linked above. Choose the credential accepted by the route; a workspace key, an identity token, and a channel-management token are not interchangeable.
{% hint style="info" %}
**Agent Forge CLI setup.** Environment variables (`PLATFORM_API_KEY`, `IDENTITY_URL`), `.env.platform.` file conventions, and `forge auth login --platform` are covered in the [Agent Forge CLI documentation](https://docs.amigo.ai/reference/agent-forge).
{% endhint %}
{% hint style="warning" %}
**Classic credentials use a different flow.** The Classic API exchanges API key credentials for per-user JWTs. Platform workspace keys are used directly on their supported routes. See [Classic API Authentication](/developer-guide/getting-started/authentication) for the other auth flow.
{% endhint %}
## API Key Usage
For workspace resource routes that accept API keys, send the key as a Bearer credential:
```bash
curl https://api.platform.amigo.ai/v1/{workspace_id}/agents \
-H "Authorization: Bearer "
```
Each key is scoped to a single workspace. The key's workspace must match the workspace in the request path. A workspace key does not grant access to another workspace. Identity credentials and account-level operations must be evaluated under their own access rules.
## API Key Lifecycle
Save a new or rotated key immediately. Its plaintext value is returned only once. Revoke keys that are no longer needed or may have been compromised.
### Create an API Key
{% openapi src="" path="/v1/{workspace\_id}/api-keys" method="post" %}
{% endopenapi %}
### List API Keys
{% openapi src="" path="/v1/{workspace\_id}/api-keys" method="get" %}
{% endopenapi %}
### Revoke an API Key
{% openapi src="" path="/v1/{workspace\_id}/api-keys/{key\_id}" method="delete" %}
{% endopenapi %}
## RBAC Roles
Each API key carries a role:
| Role | Access |
| ---------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `owner` | Full access including workspace deletion and ownership transfer |
| `admin` | Full read/write to all workspace resources |
| `member` | Read/write to most resources; restricted admin operations |
| `operator` | Read access plus operator actions: update operator state, control eligible runs, decide conversation-scoped integration approvals, and claim or review external write proposals where that private-preview flow is enabled (no general resource CRUD) |
| `viewer` | Read-only access |
Attempting an operation beyond the key's role returns `403 Forbidden`.
### Permission Catalog
Use the live permission catalog instead of hard-coding role defaults in a client.
The caller needs `ApiKey:View`. Missing or invalid credentials return `401`; insufficient permission returns `403`.
{% openapi src="" path="/v1/{workspace\_id}/api-keys/permission-catalog" method="get" %}
{% endopenapi %}
## Key Rotation
Rotation replaces a key's secret atomically. The old secret stops working immediately, and the new plaintext value is returned once.
{% openapi src="" path="/v1/{workspace\_id}/api-keys/{key\_id}/rotate" method="post" %}
{% endopenapi %}
The rotated key inherits the original key's name, role, and permissions. You can only rotate keys you created (or any key if you have the `api_key.delete` permission).
### Usage Visibility
API key responses include a `last_used_at` timestamp showing when the key was last used to authenticate a request. Use this to identify stale keys before rotating or revoking them.
## Current Key Info
Use this operation to inspect the current key's workspace, expiration, and remaining validity.
{% openapi src="" path="/v1/auth/me" method="get" %}
{% endopenapi %}
## Device Code Flow (CLI & Desktop Apps)
{% hint style="info" %}
The device authorization, MFA, IP allow-list, lockout, and identity-session routes below are served by the Identity API and are not published in the Platform API OpenAPI document. Their manually documented paths are retained only where the separate identity contract is required for the workflow.
{% endhint %}
For CLI tools, desktop apps, and other environments where the user authenticates in a browser, the Platform API supports the [RFC 8628 Device Authorization Grant](https://datatracker.ietf.org/doc/html/rfc8628).
### Flow Overview
1. Your app requests a device code from `POST /device/code`
2. The response includes a `verification_uri_complete` - your app opens this in the user's browser
3. The user signs in (if needed) and clicks **Authorize** on the approval page
4. Your app polls `POST /token` with `grant_type=device_code` until the user approves
5. The token endpoint returns a workspace-scoped JWT
### Step-by-Step
**1. Request a device code:**
```bash
curl -X POST https://api.platform.amigo.ai/device/code \
-d "client_description=my-cli-tool"
```
Response:
```json
{
"device_code": "qna68o_Hwyv...",
"user_code": "GCQE-XJWT",
"verification_uri": "https://console.platform.amigo.ai/device",
"verification_uri_complete": "https://console.platform.amigo.ai/device?user_code=GCQE-XJWT",
"expires_in": 900,
"interval": 5
}
```
**2. Direct the user to the verification URL.** Open `verification_uri_complete` in a browser. The user sees the device code and can approve or deny the request.
**3. Poll for the token:**
```bash
curl -X POST https://api.platform.amigo.ai/token \
-d "grant_type=device_code" \
-d "device_code=qna68o_Hwyv..."
```
{% hint style="info" %}
**The `authorization_pending` response is expected, not an error.** While the user hasn't approved yet, every poll returns `400` with `{"error": "authorization_pending"}`. Your app should keep polling every `interval` seconds (default: 5) until it gets a `200` or a terminal error.
{% endhint %}
| Response | Meaning | Action |
| ------------------------------------ | ---------------------------- | ------------------------------------------ |
| `400` `authorization_pending` | User hasn't approved yet | Keep polling |
| `400` `slow_down` | Polling too fast | Increase interval by 5 seconds |
| `200` | Approved | Extract `access_token` and `refresh_token` |
| `300` `workspace_selection_required` | User has multiple workspaces | See Multi-Workspace below |
| `400` `expired_token` | Code expired (15-min TTL) | Start over |
| `400` `access_denied` | User clicked Deny | Show error to user |
### Multi-Workspace Users
If the user belongs to multiple workspaces, the token exchange returns HTTP `300` with a workspace list instead of a JWT. Your app must:
1. Present the workspace list to the user
2. Exchange the `refresh_token` from the 300 response for a workspace-scoped JWT:
```bash
curl -X POST https://api.platform.amigo.ai/token \
-d "grant_type=refresh_token" \
-d "refresh_token=" \
-d "workspace_id="
```
Alternatively, pass `workspace_id` in the initial `/token` poll to pre-select a workspace.
### Platform SDK (TypeScript)
The SDK provides `loginWithDeviceCode()` which handles the full flow - code issuance, browser open, polling, and workspace selection:
```typescript
import {
loginWithDeviceCode,
openBrowser,
formatDeviceCodeInstructions,
TokenManager,
FileTokenStorage,
} from '@amigo-ai/platform-sdk'
const result = await loginWithDeviceCode({
clientDescription: 'my-app',
onCode: async (issuance) => {
console.log(formatDeviceCodeInstructions(issuance))
await openBrowser(issuance.verification_uri_complete)
},
onWorkspaceRequired: async (workspaces) => {
// Prompt user to select a workspace
return workspaces[0].workspace_id
},
})
// Use the token
const client = new AmigoClient({
apiKey: result.accessToken,
workspaceId: result.workspaceId,
})
```
Use `TokenManager` with `FileTokenStorage` to persist credentials across CLI sessions (stored at `~/.amigo/credentials.json`).
### Security
* Device codes expire after 15 minutes
* User codes are 8 characters (XXXX-YYYY format), designed to be easy to verify visually
* Rate-limited by IP address on the `/device/code` endpoint
* The approval page requires the user to be signed in to the Console
## Security Controls
The Platform API layers several account-level security controls on top of key and token authentication: SSO, multi-factor authentication, IP allowlists, account lockout, and session enforcement. The subsections below cover each control.
### SSO Login
The Platform API supports single sign-on (SSO) via identity federation. Users authenticate with their organization's identity provider (e.g., Google Workspace), and the platform exchanges the provider's authorization code for an Amigo JWT. That is the same token format used for API key authentication.
#### SSO Exchange Flow
1. The client application redirects the user to the identity provider for authentication
2. After authentication, the identity provider returns an authorization code
3. The client sends the authorization code to the Platform API token endpoint
4. The platform exchanges the code with the identity provider server-to-server and issues a JWT
#### Multi-Workspace Selection
When a user has credentials on multiple workspaces, the token endpoint returns a workspace list instead of a JWT. The client re-calls the token endpoint with the selected `workspace_id` to complete authentication.
#### Auto-Provisioning
Organizations can configure **provision policies** that automatically create credentials for new users on first SSO login based on their email domain. Global provision policies expand access to all workspaces in the organization. This eliminates the need to manually create credentials for each user before they can log in.
#### Refresh Tokens
SSO sessions issue refresh tokens alongside the JWT. Refresh tokens are rotated on each use (the old token is invalidated when a new one is issued). Idle sessions expire after the configured timeout to meet compliance requirements.
### Multi-Factor Authentication (MFA)
The platform supports TOTP-based multi-factor authentication for user accounts.
#### Enrollment Flow
1. `POST /mfa/enroll`: generate a TOTP secret. Returns an `otpauth://` URI for scanning with an authenticator app, plus one-time recovery codes.
2. `POST /mfa/verify`: confirm enrollment by submitting a valid TOTP code from the authenticator app.
Once enrolled, the token endpoint requires a valid TOTP code (or recovery code) alongside credentials when MFA is enforced.
#### MFA Enforcement
MFA can be enforced per SSO connection. When `enforce_mfa` is enabled on a connection, users authenticating through that identity provider must complete MFA before receiving a token.
Service accounts (`client_credentials` with `service_account` principal type) are exempt from MFA enforcement since automated services cannot interact with an authenticator app.
#### Recovery Codes
Recovery codes are generated during enrollment for account recovery if the authenticator device is lost. Each code can only be used once. Recovery codes are stored securely with one-way hashing.
#### Admin MFA Management
| Endpoint | Description |
| ----------------------------------- | ----------------------------------------------------------------- |
| `GET /admin/mfa/coverage` | MFA enrollment statistics across the workspace |
| `POST /admin/mfa/reset/{entity_id}` | Reset MFA enrollment for a specific user (requires re-enrollment) |
Requires `identity:admin` scope.
### IP Allowlists
Per-workspace IP allowlists restrict which IP addresses can authenticate. When configured, only requests from allowed CIDR ranges are accepted on the token endpoint.
#### Allowlist Behavior
* Allowlists are configured as CIDR ranges (e.g., `10.0.0.0/8`, `203.0.113.45/32`).
* When an allowlist is active, authentication requests from non-matching IPs are rejected with `403`.
* Allowlist changes may take a few minutes to propagate.
* Service accounts are exempt from IP allowlist checks (required for automated service-to-service auth).
* IP checks fail open: if an allowlist cannot be evaluated, authentication proceeds rather than locking out all access.
#### Admin IP Allowlist Management
| Endpoint | Description |
| ---------------------------------- | ---------------------------------------------------------------- |
| `POST /admin/ip-allowlists` | Add a CIDR range to the workspace allowlist |
| `GET /admin/ip-allowlists` | List all allowed CIDR ranges |
| `DELETE /admin/ip-allowlists/{id}` | Remove a CIDR range |
| `POST /admin/ip-allowlists/test` | Test whether a specific IP address matches the current allowlist |
Requires `identity:admin` scope.
### Account Lockout & Brute Force Protection
The platform enforces progressive account lockout on failed authentication attempts:
| Failures | Lock Duration |
| -------- | --------------------------------- |
| 5+ | 5 minutes |
| 10+ | 30 minutes |
| 20+ | Permanent (requires admin unlock) |
Lockout is tracked per entity (API key or client) and per IP address. Successful authentication clears the lockout counter.
**Per-IP rate limiting** applies to unauthenticated grant types (`api_key`, `client_credentials`, `personal_access_token`, `google_oauth`, `device_code`, `email_otp`, `magic_link`) at 60 requests/minute on the `/token` endpoint. Already-authenticated grants (`agent_session`, `refresh_token`) are exempt.
Lockout protection fails open: if lockout tracking is temporarily unavailable, authentication proceeds normally.
**Admin lockout management** (requires `identity:admin` scope):
| Endpoint | Description |
| ----------------------------------------- | -------------------------------------- |
| `POST /admin/lockout/unlock/{identifier}` | Unlock a locked account |
| `GET /admin/lockout/locked-accounts` | List all currently locked accounts |
| `GET /admin/lockout/status/{identifier}` | Check lockout status for an identifier |
Locked responses return `403` with a `Retry-After` header for timed lockouts.
### Session Enforcement
Sessions are enforced with idle timeouts and concurrent session limits. Idle and expired sessions are revoked automatically.
#### Idle Timeout
Sessions are revoked after a configurable period of inactivity:
| Session Type | Default Idle Timeout | Notes |
| ---------------------------- | -------------------- | -------------------------------------------------------------- |
| Console user sessions | 15 minutes | Default idle timeout |
| Agent sessions (voice calls) | 1 hour | Matches agent session TTL; voice agents don't refresh mid-call |
Configurable per-session between 5 minutes and 24 hours. Activity is tracked on each authenticated request.
#### Concurrent Session Limits
Each entity is limited to a maximum number of active sessions per workspace:
| Session Type | Max Concurrent Sessions | Eviction Behavior |
| -------------- | ----------------------- | ----------------------------------------- |
| User sessions | 5 | Oldest session evicted when limit reached |
| Agent sessions | 50 | Oldest session evicted when limit reached |
Agent sessions have a higher limit because a single service entity (e.g., a voice agent) handles many simultaneous calls.
#### Session Metadata
Sessions track IP address and user agent for audit and security visibility.
#### Session Management Endpoints
{% hint style="info" %}
These endpoints manage **authentication sessions** (tokens and logins). They are unrelated to the conversation [Sessions API](/developer-guide/platform-api/platform-api/sessions), which opens WebSocket text conversations.
{% endhint %}
**User endpoints** (any authenticated user):
| Endpoint | Description |
| ------------------------------- | -------------------------------------------------------------- |
| `GET /sessions` | List active sessions for the current entity |
| `DELETE /sessions` | Revoke all sessions for the current entity (logout everywhere) |
| `DELETE /sessions/{session_id}` | Revoke a specific session |
**Admin endpoints** (requires `identity:admin` scope):
| Endpoint | Description |
| ------------------------------------ | --------------------------------------------------------------------------- |
| `GET /sessions/admin` | List all active sessions with optional entity/workspace filters, pagination |
| `DELETE /sessions/admin/{entity_id}` | Revoke all sessions for a specific entity (optional workspace scope) |
All revocation actions are audit-logged.
# OAuth2 (Machine-to-Machine)
Machine-to-machine OAuth2 client credentials flow for programmatic access to the Platform API.
{% hint style="info" %}
**Provider M2M clients.** In addition to the service-account `client_credentials` grant described below, the platform supports provider-scoped M2M clients that mint provider-identity tokens for backend automation. See [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients#provider-m2m-clients) for provisioning and usage details.
{% endhint %}
The platform supports an OAuth2 client credentials flow for machine-to-machine (M2M) integrations. Registered OAuth2 clients authenticate with their credentials and receive short-lived access tokens scoped to authorized actions and resources.
{% hint style="info" %}
**One feature, two pages.** This page covers the token endpoint, scope resolution, and token claims. [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients) covers the client side: registration, granted scopes, setup allow-lists, secret rotation, and revocation.
{% endhint %}
## Token Endpoint
The token endpoint issues access tokens for registered OAuth2 clients.
{% hint style="info" %}
The token route is served by the separate authorization boundary and is not published in the Platform API OpenAPI document. Its form contract remains manual on this page because no public Platform operation is available to embed.
{% endhint %}
| Method | Path | Description |
| ------ | ----------------- | --------------------- |
| `POST` | `/v1/oauth/token` | Issue an access token |
### Request
The token endpoint accepts `application/x-www-form-urlencoded` requests with the following fields:
| Field | Type | Required | Description |
| --------------- | ------ | ----------- | ----------------------------------------------- |
| `grant_type` | string | Yes | Must be `client_credentials` |
| `scope` | string | Yes | Space-delimited list of requested scopes |
| `client_id` | string | Conditional | Required if not using HTTP Basic authentication |
| `client_secret` | string | Conditional | Required if not using HTTP Basic authentication |
Client credentials can be provided in two ways (per RFC 6749 section 2.3.1):
1. **HTTP Basic authentication** (preferred) - Pass `client_id` as the username and `client_secret` as the password in the `Authorization: Basic` header.
2. **Form body** - Include `client_id` and `client_secret` as form fields in the request body.
If both are provided, HTTP Basic authentication takes precedence.
### Response
| Field | Type | Description |
| -------------- | ------- | ---------------------------------------------------------------------------- |
| `access_token` | string | The issued access token (JWT) |
| `token_type` | string | Always `bearer` |
| `expires_in` | integer | Token lifetime in seconds (3600) |
| `scope` | string | Space-delimited list of granted scopes (may be a subset of requested scopes) |
### Scope Resolution
The issued token's scope is the intersection of the requested scopes and the client's granted scopes:
* Requested scopes that match the client's granted scope patterns are included.
* Granted patterns support wildcard matching - for example, a grant of `sms:*` covers `sms:send`.
* Certain high-privilege scopes (such as those governing client administration and credential access) are never matched by wildcard patterns. These scopes are included only when the client was explicitly granted that exact scope by name.
* Unknown or unrecognized requested scopes are silently dropped. The endpoint does not return an error for unrecognized scopes.
### Token Claims
The issued access token is a JWT (RFC 9068) containing:
| Claim | Description |
| ------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `iss` / `aud` | Token issuer and audience |
| `sub` | The client's unique identifier |
| `client_id` | The client's unique identifier |
| `scope` | Space-delimited granted scopes |
| `setups` | The resource boundary - the list of setup IDs the client is authorized to access, or `["*"]` for unrestricted access. A setup is a provisioned channel configuration (telephony, email, or messaging) that channel operations act on; see [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients#setup-allow-list-resource-dimension) |
| `iat` | Issued-at timestamp |
| `exp` | Expiration timestamp |
| `jti` | Unique token identifier |
### Error Responses
| Status | Description |
| ------ | ----------------------------------------------------------------------------------------------- |
| 401 | Missing client credentials (no Basic auth header and no client\_id/client\_secret in form body) |
| 403 | Invalid client credentials (unknown client or incorrect secret) |
| 422 | Malformed request (for example, unsupported `grant_type`) |
No refresh token is issued. Clients using the `client_credentials` grant simply request a new token when the current one expires.
### Example
```bash
curl -X POST https://api.platform.amigo.ai/v1/oauth/token \
-u "$CLIENT_ID:$CLIENT_SECRET" \
-d "grant_type=client_credentials&scope=sms:send sms:read"
```
```json
{
"access_token": "eyJhbGciOiJIUzI1NiIsInR5cCI6ImF0K2p3dCJ9...",
"token_type": "bearer",
"expires_in": 3600,
"scope": "sms:read sms:send"
}
```
## Client Management
OAuth2 client registration and management (create, update, delete, rotate secrets) is available through the client management endpoints. See [OAuth2 Clients](/developer-guide/platform-api/platform-api/oauth2-clients) for details.
{% hint style="info" %}
Client management endpoints are restricted to platform-internal access and are not reachable from the public internet. The token endpoint is publicly accessible.
{% endhint %}
# OAuth2 Clients
Understand provisioned OAuth2 clients used for machine-to-machine authentication with the client\_credentials grant.
## Provider M2M Clients
Provider machine-to-machine (M2M) clients let a customer's backend application obtain provider-scoped tokens through the standard `client_credentials` OAuth2 grant - the programmatic counterpart of the interactive provider sign-in flow. Once provisioned, a backend service authenticates with a `client_id` and `client_secret` and receives a short-lived access token scoped to the provider's identity and allowed capabilities.
Provider M2M clients are managed through a dedicated set of admin endpoints. The one-time plaintext `client_secret` is returned only at creation and cannot be retrieved afterward.
### Lifecycle
| Operation | Method | Path |
| ---------------------------------- | -------- | ---------------------------------------------------- |
| Provision a client | `POST` | `/admin/provider-m2m-clients` |
| List clients | `GET` | `/admin/provider-m2m-clients` |
| Get a client | `GET` | `/admin/provider-m2m-clients/{credential_id}` |
| Revoke a client | `POST` | `/admin/provider-m2m-clients/{credential_id}/revoke` |
| Delete a client (alias for revoke) | `DELETE` | `/admin/provider-m2m-clients/{credential_id}` |
### Provisioning
To create a provider M2M client, supply the target workspace, the provider's entity identifier, and optionally a label, lifetime, and scope restrictions. If `allowed_scopes` is omitted, the client receives a default set covering session creation, session reads, and note read/write. An explicit scope list must be a non-empty subset of the platform's provider scope set.
The response includes the `client_id` and a one-time `client_secret`. Store the secret securely - it is hashed before storage and cannot be recovered.
An optional `duration_days` field sets the credential's lifetime (1 to 3650 days). Omitting it creates a non-expiring client that must be revoked to disable.
### Minting Tokens
Use the standard token endpoint with `grant_type=client_credentials`, providing the `client_id` and `client_secret`. The issued token carries the provider's identity as its subject, uses `provider` as the principal type, and includes only the scopes allowed for the client (or a requested subset). The token shape is identical to one obtained through the interactive provider sign-in, so downstream services accept it without changes.
The `scope` parameter in the token request is optional. When provided, the requested scopes must be a subset of the client's allowed scopes. When omitted, all allowed scopes are issued.
The `resource` parameter (RFC 8707 audience indicator) is not supported for provider M2M clients.
Provider M2M tokens are short-lived and do not include a refresh token. Already-issued tokens are not revoked - they expire naturally within their short lifetime.
### Revocation
Revoking a provider M2M client is a soft delete: the client is marked as revoked and the underlying credential is deactivated. New token requests with the revoked client's credentials are rejected immediately. The `DELETE` method on the client resource is an alias for the revoke operation and has the same effect.
### Authorization
All provider M2M client management operations require workspace-admin permissions (`identity:admin` for the target workspace or global platform admin). The authorization gate is on the administrative act of managing machine credentials, not on the provider scopes the client is allowed to mint.
### Rate Limiting
Provider M2M token minting is subject to a per-client sliding-window rate limit in addition to the existing per-IP and per-client lockout protections. Rate limit responses return HTTP 429 with a `Retry-After` header.
OAuth2 clients are the registered identities behind the machine-to-machine `client_credentials` flow. Each client is identified by a `client_id` and authenticates with a `client_secret` that is returned once at creation time and cannot be retrieved afterward - only rotated.
{% hint style="info" %}
**One feature, two pages.** This page covers client registration, scopes, setup allow-lists, and secret management. [OAuth2 (Machine-to-Machine)](/developer-guide/platform-api/platform-api/oauth2) covers the token endpoint, scope resolution, and token claims.
{% endhint %}
## Concepts
### Scopes (Action Dimension)
Each client is granted a set of scopes that define what actions it can perform. Scopes follow a `resource:action` pattern and can include wildcard patterns (e.g., `sms:*` or `*`). Wildcards are expanded at token issuance time.
Available scope categories include:
| Category | Example Scopes |
| --------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- |
| SMS | `sms:send`, `sms:read`, `sms:consent:write` |
| Email | `email:send`, `email:read`, `email:template:read`, `email:template:write` |
| iMessage | `imessage:send`, `imessage:read` |
| Outbound Voice | `outbound-voice:send` |
| Twilio Setup | `twilio-setup:read`, `twilio-setup:write`, `twilio-setup:create`, `twilio-setup:credentials`, `twilio-setup:access-token`, `twilio-setup:verify-webhook` |
| Twilio Phone Number | `twilio-phone-number:read`, `twilio-phone-number:write` |
| SendBlue Setup | `sendblue-setup:read`, `sendblue-setup:create` |
| SendBlue Phone Number | `sendblue-phone-number:read`, `sendblue-phone-number:write` |
| Voice Compliance | `compliance:voice:read`, `compliance:voice:write` |
| SMS Compliance | `compliance:sms:read`, `compliance:sms:write` |
| Regulatory Compliance | `compliance:regulatory:read`, `compliance:regulatory:write` |
| Use Case | `use-case:read`, `use-case:write` |
### Setup Allow-List (Resource Dimension)
A **setup** is a provisioned channel configuration - a telephony, email, or messaging configuration - that channel operations act on. Each client specifies which setups it can access through `allowed_setup_ids`. This is either:
* **An explicit list of setup IDs** - the client can only operate on these specific setups. Setup IDs are validated against existing setups at creation and update time.
* **The wildcard `["*"]`** - the client can access all setups (intended for first-party services). The wildcard and explicit IDs are mutually exclusive.
### Secret Management
Client secrets are high-entropy tokens generated by the platform. Only the hash of the secret is stored - the raw secret is returned once at creation time and once when rotated. It cannot be retrieved afterward.
Secret rotation is a hard swap with no grace period. The previous secret is invalidated immediately when a new one is issued.
## Provisioning and Rotation
OAuth2 client creation, grant changes, revocation, and secret rotation are internal control-plane operations. The `/v1/oauth/client` routes are not a supported public integration surface, and no public client-management scope is available for customer credentials.
Coordinate with Amigo to provision a client with the required action scopes and setup allow-list. Store the client secret when it is delivered because it cannot be retrieved later. A secret rotation is a hard swap: the previous secret stops working as soon as the replacement is issued.
The public machine-to-machine flow starts after provisioning. Exchange the supplied `client_id` and `client_secret` at the token endpoint as described in [OAuth2 (Machine-to-Machine)](/developer-guide/platform-api/platform-api/oauth2).
# Provider Access Grants
Provision, list, inspect, and revoke provider Scribe access grants for a workspace.
Provider access grants control which clinicians can access Scribe in a workspace. A grant maps a workspace and email address to Scribe access and is the single authority that both human provider login and machine-to-machine act-as-by-email delegation resolve against. A provider must hold an active grant to be logged in as or acted on behalf of.
These endpoints let workspace administrators provision Scribe access by email, list and inspect a workspace's grants, and revoke access - replacing manual database operations and internal provisioning workflows.
## Grant Lifecycle
A grant moves through the following states:
| Status | Meaning |
| ---------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
| `pending_entity` | Email-only invite with no bound provider entity yet. Becomes active once the provider's entity is bound through the login or verification flow. |
| `pending_verification` | Provider entity is bound but email verification is not yet complete. |
| `active` | Fully provisioned. The provider can log in and be targeted by act-as-by-email delegation. |
| `revoked` | Soft-deleted. The provider can no longer log in or be targeted. Previously revoked emails can be re-invited, creating a fresh grant. |
When an admin supplies a known provider entity ID at creation time, the grant is created as `active` (the admin vouches for the identity). Omitting the entity ID creates a `pending_entity` grant.
## Roles and Scopes
Each grant carries a role that determines the scopes the provider receives:
| Role | Description |
| -------------- | ------------------------------------------- |
| `provider` | Standard Scribe clinician access (default). |
| `scribe_admin` | Workspace-level Scribe administration. |
## Authorization
All endpoints require `identity:admin` scope for the target workspace, or global `platform:admin`. Creating, listing, and revoking grants is an administrative act gated on admin authority, not on the Scribe capabilities the grant confers.
## Endpoints
### Create a Provider Access Grant
`POST /admin/scribe/grant`
Provision a provider for Scribe access in a workspace.
**Request body:**
| Field | Type | Required | Description |
| -------------------- | -------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `workspace_id` | string (UUID) | Yes | Target workspace. |
| `email` | string (email) | Yes | Provider's email address. |
| `provider_entity_id` | string (UUID) | No | Known provider entity ID. When supplied, the grant is created as `active`. When omitted, the grant is created as `pending_entity`. |
| `requires_mfa` | boolean | No | Whether the grant requires multi-factor authentication. Defaults to `false`. |
| `role` | string | No | `provider` (default) or `scribe_admin`. |
**Responses:**
| Status | Description |
| ------ | ------------------------------------------------------------------------ |
| 201 | Grant created. Returns the grant object. |
| 403 | Missing admin scope for the target workspace. |
| 409 | An active grant already exists for this workspace and email combination. |
Idempotency follows the workspace-plus-email uniqueness constraint for non-revoked grants. A second active grant for the same email returns 409. A previously revoked email can be re-invited, creating a fresh grant while the revoked row is retained for audit.
### List Provider Access Grants
`GET /admin/scribe/grant`
List a workspace's provider access grants with pagination. Returns metadata only - no secrets.
**Query parameters:**
| Parameter | Type | Required | Description |
| -------------------- | ------------- | ----------- | -------------------------------------------------------------------------------------------------- |
| `workspace_id` | string (UUID) | Conditional | Required for `platform:admin` callers. Workspace-scoped admins use their own workspace by default. |
| `status` | string | No | Filter by grant status (`pending_entity`, `pending_verification`, `active`, `revoked`). |
| `limit` | integer | No | Page size (1-20, default 20). |
| `continuation_token` | integer | No | Offset for pagination (default 0). |
**Responses:**
| Status | Description |
| ------ | ------------------------- |
| 200 | Paginated list of grants. |
| 403 | Missing admin scope. |
Results are ordered newest first with stable ordering across pages.
### Get a Provider Access Grant
`GET /admin/scribe/grant/{grant_id}`
Retrieve a single provider access grant by ID. Returns metadata only.
**Path parameters:**
| Parameter | Type | Description |
| ---------- | ------------- | ------------------------------ |
| `grant_id` | string (UUID) | The grant's unique identifier. |
**Query parameters:**
| Parameter | Type | Required | Description |
| -------------- | ------------- | ----------- | -------------------------------------- |
| `workspace_id` | string (UUID) | Conditional | Required for `platform:admin` callers. |
**Responses:**
| Status | Description |
| ------ | ---------------------------------------- |
| 200 | Grant detail. |
| 404 | Grant not found in the target workspace. |
### Revoke a Provider Access Grant
`POST /admin/scribe/grant/{grant_id}/revoke`
Revoke a provider access grant (soft delete). This immediately blocks both new human provider logins and new machine-to-machine act-as-by-email token mints that resolve against the grant. Any active sessions and refresh tokens bound to the grant are also revoked, so already-issued human sessions stop working. Short-lived machine-to-machine tokens expire within their normal time-to-live.
Access can be restored by re-inviting the same email, which creates a new grant.
**Path parameters:**
| Parameter | Type | Description |
| ---------- | ------------- | ------------------------------ |
| `grant_id` | string (UUID) | The grant's unique identifier. |
**Query parameters:**
| Parameter | Type | Required | Description |
| -------------- | ------------- | ----------- | -------------------------------------- |
| `workspace_id` | string (UUID) | Conditional | Required for `platform:admin` callers. |
**Responses:**
| Status | Description |
| ------ | ------------------------------------------------ |
| 200 | Grant revoked. Returns the updated grant object. |
| 404 | Grant not found in the target workspace. |
## Grant Response Object
| Field | Type | Description |
| ---------------------- | ------------------------- | --------------------------------------------- |
| `id` | string (UUID) | Unique grant identifier. |
| `workspace_id` | string (UUID) | Workspace the grant belongs to. |
| `provider_entity_id` | string (UUID) or null | Bound provider entity, if any. |
| `email` | string | Provider's email address. |
| `email_verified_at` | string (datetime) or null | When the email was verified. |
| `status` | string | Current lifecycle status. |
| `role` | string | `provider` or `scribe_admin`. |
| `scopes` | array of strings | Scopes conferred by the grant's role. |
| `requires_mfa` | boolean | Whether MFA is required. |
| `granted_by_entity_id` | string (UUID) | Entity that created the grant. |
| `granted_at` | string (datetime) | When the grant was created. |
| `revoked_at` | string (datetime) or null | When the grant was revoked, if applicable. |
| `revoked_by_entity_id` | string (UUID) or null | Entity that revoked the grant, if applicable. |
# Sessions
Persistent WebSocket endpoint for text conversations with streamed agent responses.
The Sessions API provides a persistent WebSocket for interactive text conversations. One connection carries the opening agent turn and later user turns, while each response is streamed as typed JSON frames.
For provider documentation encounters, microphone capture, and Zoom, use [Scribe Sessions](/developer-guide/platform-api/scribe/sessions). Those REST routes and credentials are separate from this text WebSocket.
{% hint style="info" %}
This page covers **conversation sessions**. It is unrelated to the login and token sessions documented under [Authentication & API Keys](/developer-guide/platform-api/platform-api/authentication#session-management-endpoints).
{% endhint %}
WebSocket routes are not represented in the HTTP OpenAPI document. This page is the public wire contract for `sessions/connect`.
## Connect
**US endpoint:** `wss://api.platform.amigo.ai/v1/{workspace_id}/sessions/connect`
For Canada, Europe, or Australia, replace the host with the WebSocket form of your [regional Platform endpoint](/developer-guide/getting-started/regions-and-endpoints).
### Query Parameters
| Parameter | Type | Required | Description |
| ----------------- | ------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| `service_id` | UUID | Yes | Service to run. The service must belong to the workspace. |
| `entity_id` | UUID | Yes | Person entity to bind to the conversation. The entity must belong to the workspace. |
| `tool_events` | boolean | No | Set to `true` to include tool-call events. The default is `false`; values other than `true` are treated as false. |
| `context` | string | No | Additional context for the opening agent turn. Only the first 5,000 characters are used. |
| `viewport_width` | integer | No | Text viewport width in characters, from 20 through 500. Invalid values are ignored. |
| `viewport_height` | integer | No | Text viewport height in characters, from 5 through 500. Invalid values are ignored. It is useful only with a valid `viewport_width`. |
The endpoint does not use a `conversation_id` parameter for resumption. If supplied, it is ignored. Reconnection is based on the workspace, `service_id`, and `entity_id` instead.
### Authentication
Pass two WebSocket subprotocol values:
```http
Sec-WebSocket-Protocol: auth,
```
The first value must be the literal `auth`. The second must be an active API key or JWT for the workspace in the URL. On an accepted connection, the server negotiates `auth` as the selected subprotocol.
Do not put credentials in the URL. Query-string tokens are not supported.
{% hint style="warning" %}
Browser same-origin rules do not authorize this WebSocket. Treat the credential as the authorization boundary, use short-lived credentials for browser clients where possible, and restrict which application origins can receive those credentials. The endpoint does not publish an application-level Origin allowlist.
{% endhint %}
### Connection Limits
The public contract does not define a fixed connect-rate limit, per-workspace concurrent-connection cap, or maximum connection lifetime. Infrastructure can still reject or close connections. Keep one connection per active chat, close unused sockets, and use capped exponential backoff with jitter when reconnecting.
Two operation timeouts are part of the endpoint behavior:
| Timeout | Behavior |
| ------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
| 5 minutes waiting for an inbound text frame | Sends an `idle_timeout` error, then closes the WebSocket normally. The durable conversation is not closed. |
| 60 seconds for a user turn | Sends a retryable `turn_timeout` error. The WebSocket remains available for a later message. |
The idle timer runs while the server is waiting for the next client frame, not while an agent turn is being streamed.
## Lifecycle
1. The client opens the WebSocket with the required query parameters and auth subprotocols.
2. The server validates the workspace, credential, service, and entity, then resolves an active conversation thread.
3. After a successful handshake, the server sends `session.created`.
4. The server immediately runs an opening agent turn and streams its events.
5. After that turn reaches `done` or `error`, the client can send a `user_text` message.
6. The server processes one user message at a time and streams one terminal `done` or `error` event for that turn.
7. Either side can close the socket. An idle timeout closes only the transport, not the durable conversation.
An `open` event in the browser is not proof that session validation succeeded because validation failures are delivered as WebSocket close frames. Wait for `session.created` before treating the session as established.
## Client Messages
Send JSON objects in WebSocket text frames:
```json
{
"type": "user_text",
"text": "I need to reschedule my appointment"
}
```
| Field | Type | Required | Description |
| ------ | ------ | -------- | ------------------------------------------------ |
| `type` | string | Yes | Must be `user_text`. |
| `text` | string | Yes | Non-empty user message, up to 10,000 characters. |
Send only one user turn at a time. Wait for that turn's terminal `done` or `error` event before sending the next message. Frames that arrive while a turn is running can be buffered by the connection, but the endpoint does not provide a durable client-message queue, receipt, or idempotency key.
Binary frames and client control message types such as `stop` are not part of this contract. To close the durable conversation rather than only the WebSocket, use the Conversations API.
## Server Frames
Every server message is a JSON text frame with an `event` discriminator and a `data` object:
```json
{
"event": "token",
"data": {
"text": "Hello"
}
}
```
### `session.created`
This is the first application frame on a successfully established session:
```json
{
"event": "session.created",
"data": {
"conversation_id": "7cb90d32-1db1-4aca-a04c-e8f7bf3e06c8",
"entity_id": "c9820f66-54a6-48f7-8375-5a0ee834e63c",
"service_id": "7f994d37-bbe1-4d99-beba-ab2d2332c9bc"
}
}
```
Store `conversation_id`. You can use it with the REST Conversations API to inspect the durable transcript or reconcile an ambiguous disconnect.
### Turn Events
The opening turn and every `user_text` turn use the same event envelope:
| Event | `data` fields | Notes |
| --------------------- | ---------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------ |
| `token` | `text` | Incremental response text. Use `message` as the authoritative completed message. |
| `tool_call_started` | `tool_name`, `call_id`, `input` | Emitted only when `tool_events=true`. `input` is a string and can contain JSON text. |
| `tool_call_completed` | `tool_name`, `call_id`, `result`, `succeeded`, `duration_ms` | Emitted only when `tool_events=true`. `result` is a string; `duration_ms` can be null. |
| `thinking` | `tier`, `tier_name` | Reasoning-tier classification. |
| `message` | `role`, `text` | Completed agent message. A turn can emit more than one. |
| `done` | `conversation_id`, `status`, and normally `turn_count`, `background_pending`, `delivery_protocol_version`, `turn_id`, `turn_index` | Terminal success event. Some recovery paths provide only `conversation_id` and `status`, so clients must tolerate omitted optional fields. |
| `error` | `message`, `code`, `retryable`, and sometimes `status_code` | Terminal for the current turn. The socket normally remains open except after `idle_timeout`. |
Do not mix this envelope with the HTTP SSE wire format. SSE uses `event:` and `data:` lines; this WebSocket sends one JSON object per text frame and removes the nested turn event discriminator from `data`.
### Errors
| Code | Meaning | Retryable value |
| -------------------- | ------------------------------------------------------------------------------------------------ | ------------------------------------------------ |
| `client_error` | Invalid JSON, unknown message type, missing or empty text, or text longer than 10,000 characters | `false` |
| `upstream_error` | The agent service rejected or failed the turn | `true` for transient statuses; otherwise `false` |
| `stream_interrupted` | The response stream ended because of a transport interruption | `true` |
| `turn_timeout` | A user turn exceeded 60 seconds | `true` |
| `idle_timeout` | No client text frame arrived for 5 minutes while the server was waiting | `true`, followed by a normal WebSocket close |
The endpoint has no per-message receipt event. If the connection drops before a turn reaches `done` or `error`, the outcome is ambiguous. Read the conversation by the last `conversation_id` before deciding whether to retry the user's message.
## Close Codes
Validation failures are accepted and then immediately closed so that clients can receive a reason code:
| Code | Reason |
| ------ | ------------------------------------------------------------------------------------------------------------------------ |
| `1000` | Normal close, including the close after an `idle_timeout` event. |
| `4000` | Missing or malformed workspace, `service_id`, or `entity_id`. |
| `4001` | Missing, invalid, inactive, expired, or wrong-workspace credential. |
| `4004` | Workspace is missing or inactive, service is not in the workspace, or entity is not an eligible person in the workspace. |
| `4503` | The conversation thread could not be resolved before the session-creation timeout. Retry with backoff. |
Other standard WebSocket close codes can still be reported for network, proxy, or unexpected server failures. Do not treat codes from a different Platform WebSocket endpoint as part of this endpoint's contract.
## Reconnect and Thread Semantics
The server resolves one active WebSocket conversation thread for each `(workspace_id, entity_id, service_id)` combination.
* Reconnecting with the same combination resumes the active durable conversation and returns the same `conversation_id`.
* If that conversation is no longer active, including after explicit close or terminal completion, the next connection creates a new conversation and returns a new `conversation_id`.
* Every successful connection, including a reconnect, runs an opening agent turn after `session.created`.
* There is no event cursor, replay request, or `conversation_id` query parameter. Use the durable conversation detail endpoint to reconcile events after a disconnect.
* A conversation first materialized by this WebSocket can be inspected or continued over REST by using the returned `conversation_id`, but a separately created REST conversation cannot be selected when opening this WebSocket.
## Browser Example
This example waits for the automatic opening turn to finish before sending the first user message:
```javascript
const workspaceId = 'your-workspace-id'
const serviceId = 'your-service-id'
const entityId = 'your-entity-id'
const token = 'your-api-key-or-jwt'
const query = new URLSearchParams({
service_id: serviceId,
entity_id: entityId,
tool_events: 'true',
})
const socket = new WebSocket(
`wss://api.platform.amigo.ai/v1/${workspaceId}/sessions/connect?${query}`,
['auth', token],
)
let firstUserMessageSent = false
socket.addEventListener('message', (messageEvent) => {
const frame = JSON.parse(messageEvent.data)
switch (frame.event) {
case 'session.created':
console.log('Conversation:', frame.data.conversation_id)
break
case 'token':
console.log('Partial:', frame.data.text)
break
case 'message':
console.log(`${frame.data.role}: ${frame.data.text}`)
break
case 'tool_call_started':
console.log('Tool started:', frame.data.tool_name)
break
case 'done':
if (!firstUserMessageSent) {
firstUserMessageSent = true
socket.send(JSON.stringify({ type: 'user_text', text: 'Hello' }))
}
break
case 'error':
console.error(frame.data.code, frame.data.message)
break
}
})
socket.addEventListener('close', (closeEvent) => {
console.log('Closed:', closeEvent.code, closeEvent.reason)
})
```
## Scribe Session Guidance
Clinical session modes, lifecycle transitions, and Zoom controls have moved to [Scribe Sessions](/developer-guide/platform-api/scribe/sessions). Use the Scribe deployment base and provider credentials for those operations. The following links retain the former section locations for existing bookmarks.
### Session Mode
Continue with [Scribe: Session Mode](/developer-guide/platform-api/scribe/sessions#session-mode).
### Session Lifecycle
Continue with [Scribe: Session Lifecycle](/developer-guide/platform-api/scribe/sessions#session-lifecycle).
### Update Session
Continue with [Scribe: Update Session](/developer-guide/platform-api/scribe/sessions#update-session).
### Create Session Idempotency
Continue with [Scribe: Create Session Idempotency](/developer-guide/platform-api/scribe/sessions#create-session-idempotency).
### Conflict Error Codes
Continue with [Scribe: Conflict Error Codes](/developer-guide/platform-api/scribe/sessions#conflict-error-codes).
### Zoom
Continue with [Scribe: Zoom](/developer-guide/platform-api/scribe/sessions#zoom).
#### Zoom Session Lifecycle
Continue with [Scribe: Zoom Session Lifecycle](/developer-guide/platform-api/scribe/sessions#zoom-session-lifecycle).
#### Create a Zoom Session
Continue with [Scribe: Create a Zoom Session](/developer-guide/platform-api/scribe/sessions#create-a-zoom-session).
#### Pause Zoom Bot
Continue with [Scribe: Pause Zoom Bot](/developer-guide/platform-api/scribe/sessions#pause-zoom-bot).
#### Resume Zoom Bot
Continue with [Scribe: Resume Zoom Bot](/developer-guide/platform-api/scribe/sessions#resume-zoom-bot).
#### End Zoom Session
Continue with [Scribe: End Zoom Session](/developer-guide/platform-api/scribe/sessions#end-zoom-session).
#### Endpoints
Continue with [Scribe: Endpoints](/developer-guide/platform-api/scribe/sessions#endpoints).
#### Authorize Response
Continue with [Scribe: Authorize Response](/developer-guide/platform-api/scribe/sessions#authorize-response).
#### Connection Response
Continue with [Scribe: Connection Response](/developer-guide/platform-api/scribe/sessions#connection-response).
#### Error Handling
Continue with [Scribe: Error Handling](/developer-guide/platform-api/scribe/sessions#error-handling).
# Zoom Session Events (SSE)
Real-time Server-Sent Event stream for live Zoom session bot status and transcript updates.
The Scribe API exposes a live event stream for active Zoom sessions. The stream delivers bot lifecycle updates and transcript segments in real time so the client does not need to poll.
## Opening the Stream
```
GET /sessions/{session_id}/events
```
The endpoint requires the same provider-JWT authentication used by other Scribe session endpoints. Because an `Authorization` header is required, use `fetch` streaming rather than the browser `EventSource` API.
The response content type is `text/event-stream`.
### Path Parameters
| Parameter | Type | Description |
| ------------ | ------------- | ----------------------------------------------------------------------------------------------------- |
| `session_id` | string (UUID) | The session to stream events for. Must be an active Zoom session owned by the authenticated provider. |
### Request Headers
| Header | Required | Description |
| --------------- | -------- | --------------------------------------------------------------------------------------------------------------------------------------------------- |
| `Authorization` | Yes | Provider JWT bearer token. |
| `Last-Event-ID` | No | The `id` of the last event the client received. When present, the server replays recent events from that offset so no frames are lost on reconnect. |
## Event Types
Each SSE frame is delivered as `event: \ndata: \n\n`. Frames include an `id` field that clients should store for reconnect replay.
| Event | Description | Terminal |
| ---------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------- |
| `bot_status` | Bot lifecycle state change. | Yes, when `state` is `done` or `error`. |
| `transcript_segment` | A finalized transcript utterance. | No |
| `interim_transcript` | An in-progress (not yet final) transcript hypothesis for the same ordinal. Replaced by the subsequent `transcript_segment` with the same `ordinal`. | No |
| `transcript_finalized` | Emitted once when the full transcript is complete. Empty payload (`{}`). | No |
| `ping` | Keepalive frame with an empty payload (`{}`). | No |
### `bot_status` Payload
| Field | Type | Description |
| -------- | -------------- | -------------------------------------------------------------------------------------------------------------------------------------------------- |
| `state` | string | One of: `joining`, `waiting_for_host`, `waiting_for_participant`, `playing_disclosure`, `listening`, `paused`, `idle`, `leaving`, `done`, `error`. |
| `reason` | string or null | A machine-readable reason on non-happy-path transitions (e.g. `join_timeout`, `upstream_unavailable`). |
When `state` is `done` or `error`, the stream closes immediately after the frame. Clients should stop reconnecting.
### `transcript_segment` / `interim_transcript` Payload
| Field | Type | Description |
| ----------- | -------------- | ---------------------------------------------------------------------------------------------- |
| `ordinal` | integer | Monotonically increasing segment index. Use this to deduplicate or replace interim with final. |
| `speaker` | string or null | Speaker label, when available. |
| `text` | string | The transcript text. |
| `timestamp` | string | Timestamp of the utterance. |
## Reconnect Behavior
If the connection drops, open a new `GET` request with `Last-Event-ID` set to the last received event `id`. The server replays recent events from that offset. The stream is stateless from the client's perspective - all replay state is managed server-side.
## Error Responses
| Status | Description |
| ------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| 401 | Missing or invalid authentication. |
| 403 | The authenticated provider does not own this session. |
| 404 | No live Zoom event stream exists. Returned for non-Zoom sessions, unknown session IDs, sessions that have already completed, or sessions without an active bot. |
| 503 | The live event stream is temporarily unavailable. Retry after a short delay. |
If the upstream event source fails mid-stream, the server emits a terminal `bot_status` frame with `state: "error"` and `reason: "upstream_unavailable"`, then closes the stream. The client should reconnect with its stored `Last-Event-ID`.
## Example
```javascript
const response = await fetch(`/sessions/${sessionId}/events`, {
headers: {
'Authorization': `Bearer ${token}`,
// Include on reconnect:
// 'Last-Event-ID': lastEventId,
},
});
const reader = response.body.getReader();
const decoder = new TextDecoder();
let buffer = '';
while (true) {
const { done, value } = await reader.read();
if (done) break;
buffer += decoder.decode(value, { stream: true });
// Parse SSE frames from buffer by splitting on double newlines
// Store event id for reconnect
// Handle bot_status, transcript_segment, interim_transcript,
// transcript_finalized, and ping event types
}
```
# Appointments
List and retrieve appointments for the current calendar day, scoped to the authenticated provider's workspace.
{% hint style="info" %}
**Cancelled sessions excluded from appointment linkage.** When the appointments endpoint resolves the current session for each appointment, cancelled sessions are not considered. If every session for an appointment has been cancelled, the appointment appears with no linked session - the same state as a freshly startable appointment.
{% endhint %}
The Appointments endpoints return appointment data for the current calendar day, scoped to the authenticated provider and workspace. Each appointment includes scheduling details, patient and practitioner references, and a link to the associated session when one exists.
Appointments are sourced externally - the platform does not maintain its own appointment store. The current implementation returns a deterministic seed of appointments for the current day. A future release will source appointments from a downstream customer API through a managed External Integration, with no change to the response contract.
## Endpoints
| Method | Path | Operation | Description |
| ------ | ----------------------------------------------- | ------------------- | ----------------------------------------------------- |
| GET | `/{workspace_id}/appointments` | `list-appointments` | List appointments over a rolling date-anchored window |
| GET | `/{workspace_id}/appointments/{appointment_id}` | `get-appointment` | Retrieve a single appointment by ID |
## List Appointments
`GET /{workspace_id}/appointments`
Returns a paginated list of appointments for the current calendar day. Results are scoped to the authenticated provider and workspace.
### Query Parameters
| Parameter | Type | Required | Default | Description |
| -------------------- | ------- | -------- | ------- | ------------------------------------------------------------ |
| `limit` | integer | No | 50 | Maximum number of appointments to return (1-200) |
| `continuation_token` | string | No | — | Opaque token from a previous response to fetch the next page |
### Response
```json
{
"items": [
{
"id": "string",
"session": "uuid or null",
"start": "2025-07-15T08:00:00Z",
"end": "2025-07-15T08:45:00Z",
"duration_minutes": 45,
"reason": "Therapy Intake",
"appointment_type": "THERAPY INTAKE",
"patient_name": "Riley Chen",
"patient_entity_id": "string",
"practitioner_name": "Levi Clark",
"practitioner_entity_id": "string",
"location_name": "string"
}
],
"has_more": false,
"continuation_token": null
}
```
## Get Appointment
`GET /{workspace_id}/appointments/{appointment_id}`
Returns a single appointment by its ID. Returns 404 if the appointment is not found in the current day's data.
### Path Parameters
| Parameter | Type | Required | Description |
| ---------------- | ------ | -------- | ----------------------------------------------- |
| `appointment_id` | string | Yes | The appointment identifier (max 512 characters) |
### Response
Returns a single `Appointment` object (see field reference below).
## Appointment Object
| Field | Type | Description |
| ------------------------ | ------------ | ------------------------------------------------------------------------------------------- |
| `id` | string | Opaque external appointment identifier (max 512 characters) |
| `session_id` | uuid or null | The platform session ID recorded against this appointment, or null if no session exists yet |
| `start` | datetime | Appointment start time (UTC) |
| `end` | datetime | Appointment end time (UTC) |
| `duration_minutes` | integer | Duration in minutes (>= 0) |
| `reason` | string | Reason for the appointment (max 256 characters) |
| `appointment_type` | string | Appointment type label (max 256 characters) |
| `patient_name` | string | Patient display name (max 256 characters) |
| `patient_entity_id` | string | Patient entity identifier (max 512 characters) |
| `practitioner_name` | string | Practitioner display name (max 256 characters) |
| `practitioner_entity_id` | string | Practitioner entity identifier (max 256 characters) |
| `location_name` | string | Location display name (max 256 characters) |
## Session Linking
When a session has been recorded against an appointment, the `session_id` field contains the platform session identifier. This link is resolved by matching the appointment's `id` against the session's external appointment reference, scoped to the authenticated provider and workspace. Appointments with no matching session return `session_id` as null.
## Pagination
The list endpoint uses the same offset-based pagination pattern as other list endpoints. When `has_more` is true, pass the returned `continuation_token` as a query parameter to retrieve the next page. See [Pagination](/developer-guide/platform-api/platform-api/pagination) for details.
## Error Responses
| Status | Description |
| ------ | ------------------------------------------------------ |
| 401 | Unauthorized - missing or invalid credentials |
| 403 | Forbidden - insufficient permissions for the workspace |
| 404 | Appointment not found (get endpoint only) |
| 422 | Validation error in request parameters |
# WhatsApp Setup
Managed WhatsApp provisioning, business-scoped recipient identity, asynchronous replies, and the separate service voice-note API.
WhatsApp setup and business-account registration are managed provisioning operations. They are not workspace-scoped endpoints in the public Platform API. Workspace applications do not create or delete the upstream business setup with a Platform API key.
Contact Amigo to complete business-account provisioning and bind a WhatsApp use case to an eligible service. [Use Cases and Bindings](/developer-guide/platform-api/workspaces/use-cases) describes the public service-binding operations.
## Managed Conversations
Ordinary inbound messages can drive the bound agent and receive an asynchronous text reply. Recipient addressing uses a business-scoped user identifier; do not substitute a phone number or assume that phone metadata is always present. Continuity uses the recipient identity and use case.
Managed free-form replies require an inbound message to that use case within the previous 23 hours. Template registration and status tracking do not currently provide a template-send path. An approved template therefore does not enable out-of-window outreach through this send path.
Inbound media and reaction records, read receipts, agent completion, and outbound delivery have separate meanings. A reaction without message or media content does not drive an agent turn, and a read receipt does not prove that the agent completed the task.
The public conversation-start and channel-switch operations do not create outbound WhatsApp threads. The former synchronous service text-turn route has also been removed. See [WhatsApp concepts](https://docs.amigo.ai/channels/whatsapp) for delivery and media boundaries.
## Separate Voice-Note API
{% openapi src="" path="/v1/{workspace\_id}/services/{service\_id}/voice-turn" method="post" %}
{% endopenapi %}
This operation accepts recorded audio and returns the agent's audio response to the calling integration. That integration is responsible for delivery to WhatsApp or another destination. It is not automatic managed WhatsApp media processing.
Voice-note continuity is keyed by workspace, service, and phone number and remains separate from managed WhatsApp text history. See [Voice Agent](/developer-guide/platform-api/conversations/voice-agent#whatsapp-voice-notes) for response negotiation and session behavior.
# Cost to Serve
Retrieve workspace-level cost-to-serve data for LLM inference and infrastructure, scoped to closed months.
The cost-to-serve endpoints provide workspace-level visibility into what Amigo pays to operate a workspace. Two endpoints cover distinct cost domains:
| Endpoint | Cost domain | Interpretation |
| -------------- | ---------------------------------------- | --------------------------------------------- |
| LLM Inference | Recorded token usage priced by rate card | Depends on usage and pricing coverage |
| Infrastructure | Usage-weighted share of pooled resources | Depends on allocation rules and usage weights |
Both endpoints are read-only and return data from the monthly cost-allocation close. Only closed months can be queried.
{% hint style="warning" %}
**Amigo staff only.** These endpoints require an Amigo administrator identity. They are not available to workspace administrators or API-key-authenticated callers. The data represents Amigo's cost to serve - not an amount owed and not a contracted price.
{% endhint %}
{% hint style="info" %}
These staff-only routes are not included in the current public Platform API OpenAPI document. They are a separately restricted operational interface, not a workspace-customer analytics capability. Confirm staff access and the current internal contract before integrating.
{% endhint %}
## LLM Inference Cost
`GET /v1/{workspace_id}/cost-to-serve/llm-inference`
Returns per-model LLM inference cost for a closed month. Pricing uses the per-call tier and rates effective on the usage date. Missing rates or required usage counters leave usage unpriced; the reported total excludes it.
### Query Parameters
| Parameter | Type | Required | Description |
| ------------- | ------ | -------- | ------------------------------------------------------------------------------------------------------- |
| `close_month` | `date` | Yes | Any date within the closed month to report, e.g. `2026-07-01`. Must be a month that has already closed. |
### Response Body
| Field | Type | Description |
| -------------------- | --------- | -------------------------------------------------------------------------------------------- |
| `close_month` | `date` | First day of the closed month this breakdown covers. |
| `currency` | `string` | Currency of every amount in the response. Always `USD`. |
| `total_cost_usd` | `number` | Sum of priced models. Excludes any model where `is_priced` is false. |
| `has_unpriced_usage` | `boolean` | True when some usage could not be priced, meaning `total_cost_usd` understates actual spend. |
| `models` | `array` | Per-model breakdown. |
#### Model Object
| Field | Type | Description |
| --------------- | ---------------- | ------------------------------------------------------------------------------------------------------- |
| `model` | `string` | Model identifier. |
| `input_tokens` | `integer` | Input tokens consumed. |
| `output_tokens` | `integer` | Output tokens consumed. |
| `cached_tokens` | `integer` | Cached tokens consumed. |
| `cost_usd` | `number or null` | Token cost in USD. Null when the recorded usage cannot be priced with the available rates and counters. |
| `is_priced` | `boolean` | Whether the applicable rates and required usage counters support pricing this usage. |
### Response Codes
| Status | Description |
| ------ | -------------------------------------------------- |
| `200` | Cost data returned. |
| `400` | `close_month` is in the current or a future month. |
| `403` | Caller is not an Amigo administrator. |
| `429` | Rate limited. |
### Example Request
```bash
curl -X GET \
'https://{region}.api.amigo.ai/v1/{workspace_id}/cost-to-serve/llm-inference?close_month=2026-07-01' \
-H 'Authorization: Bearer {token}'
```
### Example Response
```json
{
"close_month": "2026-07-01",
"currency": "USD",
"total_cost_usd": 1234.56,
"has_unpriced_usage": false,
"models": [
{
"model": "model-a",
"input_tokens": 15000000,
"output_tokens": 3200000,
"cached_tokens": 800000,
"cost_usd": 1100.00,
"is_priced": true
},
{
"model": "model-b",
"input_tokens": 500000,
"output_tokens": 120000,
"cached_tokens": 50000,
"cost_usd": 134.56,
"is_priced": true
}
]
}
```
***
## Infrastructure Cost
`GET /v1/{workspace_id}/cost-to-serve/infrastructure`
Returns per-component infrastructure cost for a closed month.
### Query Parameters
| Parameter | Type | Required | Description |
| ------------- | ------ | -------- | ------------------------------------------------------------------------------------------------------- |
| `close_month` | `date` | Yes | Any date within the closed month to report, e.g. `2026-07-01`. Must be a month that has already closed. |
### Response Body
| Field | Type | Description |
| ---------------- | -------- | ------------------------------------------------------- |
| `close_month` | `date` | First day of the closed month this breakdown covers. |
| `currency` | `string` | Currency of every amount in the response. Always `USD`. |
| `total_cost_usd` | `number` | Sum of all components for the month. |
| `components` | `array` | Per-component breakdown. |
#### Component Object
| Field | Type | Description |
| ------------ | -------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `component` | `string` | Infrastructure component category (e.g. pipelines, model serving, warehouse, storage). |
| `allocation` | `string` | How the cost was determined: `shared` (usage-weighted share of a pooled resource) or `direct` (spend tagged to this workspace). |
| `cost_usd` | `number` | Cost in USD for this component. |
### Response Codes
| Status | Description |
| ------ | -------------------------------------------------- |
| `200` | Cost data returned. |
| `400` | `close_month` is in the current or a future month. |
| `403` | Caller is not an Amigo administrator. |
| `429` | Rate limited. |
### Example Request
```bash
curl -X GET \
'https://{region}.api.amigo.ai/v1/{workspace_id}/cost-to-serve/infrastructure?close_month=2026-07-01' \
-H 'Authorization: Bearer {token}'
```
### Example Response
```json
{
"close_month": "2026-07-01",
"currency": "USD",
"total_cost_usd": 567.89,
"components": [
{
"component": "pipelines",
"allocation": "shared",
"cost_usd": 320.45
},
{
"component": "warehouse",
"allocation": "shared",
"cost_usd": 150.00
},
{
"component": "storage",
"allocation": "shared",
"cost_usd": 97.44
}
]
}
```
## Notes
* Both endpoints return data only for months whose cost-allocation close has completed. Querying the current or a future month returns a `400` error.
* Components or models with no spend in the requested month are omitted from the response.
* Account-level overhead that cannot be attributed to a workspace is excluded.
* When multiple close runs exist for the same month (e.g. after a correction), only the latest run is returned.
* These endpoints are rate-limited. Excessive requests return `429`.
# External Auth Claim Mappings
Create, list, get, supersede, and preview-resolve external auth claim mappings that link customer-attested claims to internal roles.
External auth claim mappings define the workspace allowlist that connects customer-attested authorization claims to internal external roles. Each active mapping links exactly one claim tuple - a `(namespace, key, value)` triple - to one external role. Matching is exact, case-sensitive tuple equality only.
Mappings are immutable. There is no update verb. To change a mapping, supersede the existing one (which marks it as `superseded`) and create a new active mapping. This preserves the full authorization history for audit.
## Base Path
```
/v1/{workspace_id}/external-auth-claim-mappings
```
## Endpoints
| Method | Path | Operation | Description |
| ------ | ------------------------- | ---------------------------------------------- | ----------------------------------------------------------- |
| GET | `/` | `list-external-auth-claim-mappings` | List mappings with optional status filter and pagination |
| POST | `/` | `create-external-auth-claim-mapping` | Create a new active mapping |
| GET | `/{mapping_id}` | `get-external-auth-claim-mapping` | Get a single mapping by ID |
| POST | `/{mapping_id}/supersede` | `supersede-external-auth-claim-mapping` | Supersede an active mapping (mark as `superseded`) |
| POST | `/resolve-preview` | `resolve-preview-external-auth-claim-mappings` | Dry-run the claim resolver against current workspace config |
## Permissions
* **Create and supersede** require `Workspace.update` (admin or owner).
* **List, get, and resolve-preview** require `Workspace.view`.
## Claim Tuple Format
Each claim mapping references a claim tuple with three fields:
| Field | Type | Constraints |
| ----------------- | ------ | ---------------------------------------------------------------------------- |
| `claim_namespace` | string | Lowercase identifier, 1-64 characters. Pattern: `^[a-z][a-z0-9_.:-]{0,63}$` |
| `claim_key` | string | Lowercase identifier, 1-64 characters. Same pattern as namespace |
| `external_value` | string | 1-256 characters, preserved exactly as provided (no lowercasing or aliasing) |
The same identifier pattern applies to claim atoms passed during session creation and to mapping definitions.
## Create a Mapping
```
POST /v1/{workspace_id}/external-auth-claim-mappings
```
### Request Body
| Field | Type | Required | Description |
| ------------------ | ------ | -------- | ------------------------------------------------------------------- |
| `claim_namespace` | string | Yes | Claim namespace |
| `claim_key` | string | Yes | Claim key |
| `external_value` | string | Yes | The customer's asserted value |
| `external_role_id` | uuid | Yes | The external role this claim maps to (must exist in this workspace) |
### Response
Returns the created mapping item with status `201 Created`.
### Errors
| Status | Condition |
| ------ | ------------------------------------------------------------------------ |
| 409 | An active mapping for this claim tuple already exists |
| 422 | `external_role_id` does not reference an external role in this workspace |
## List Mappings
```
GET /v1/{workspace_id}/external-auth-claim-mappings
```
### Query Parameters
| Parameter | Type | Default | Description |
| -------------------- | ------- | ------------- | ----------------------------------------------------------------- |
| `status` | string | (all) | Filter by `active` or `superseded` |
| `limit` | integer | 50 | Page size (1-200) |
| `continuation_token` | string | (none) | Pagination token from a previous response |
| `sort_by` | string | `-created_at` | Sort field with direction prefix (`+created_at` or `-created_at`) |
### Response
| Field | Type | Description |
| -------------------- | -------------- | ---------------------------------------------- |
| `items` | array | List of mapping items |
| `has_more` | boolean | Whether more results are available |
| `continuation_token` | string or null | Token for the next page, if `has_more` is true |
## Get a Mapping
```
GET /v1/{workspace_id}/external-auth-claim-mappings/{mapping_id}
```
Returns a single mapping item. Returns 404 if not found.
## Supersede a Mapping
```
POST /v1/{workspace_id}/external-auth-claim-mappings/{mapping_id}/supersede
```
Marks an active mapping as `superseded`. Returns the mapping item in its final state. Returns 404 if no active mapping exists for that ID.
Superseding a mapping invalidates cached authorization resolutions across the workspace. The next external-user turn re-resolves against the updated configuration.
## Resolve Preview
```
POST /v1/{workspace_id}/external-auth-claim-mappings/resolve-preview
```
Dry-run the same resolver that runs on every external-user turn. This is read-only and never creates sessions, roles, mappings, or grants.
### Request Body
| Field | Type | Required | Description |
| ------------- | ----- | -------- | ----------------------------------------------------------------------- |
| `auth_claims` | array | No | List of claim atoms (max 32), each with `namespace`, `key`, and `value` |
### Response
| Field | Type | Description |
| ---------------------- | ------- | ------------------------------------------------------------------------------------------------ |
| `roles` | array | Mapped internal roles (each with `id` and `name`) |
| `grants` | array | Effective grants from the mapped roles (each with `resource_type`, `resource_key`, and `access`) |
| `unmapped_claim_count` | integer | Number of input claim atoms with no active mapping |
## Mapping Item Shape
| Field | Type | Description |
| ------------------ | ------------ | -------------------------------------------------- |
| `id` | uuid | Mapping ID |
| `claim_namespace` | string | Claim namespace |
| `claim_key` | string | Claim key |
| `external_value` | string | The customer's asserted value |
| `external_role_id` | uuid | The external role this claim maps to |
| `status` | string | `active` or `superseded` |
| `changed_by` | uuid or null | Credential that created or superseded this mapping |
| `created_at` | datetime | When the mapping was created |
## Auth Claims on Session Creation
The external-user session token grant (`grant_type=external_user_session`) accepts an optional `auth_claims` form field containing a JSON-serialized array of claim atoms. Each atom has `namespace`, `key`, and `value` fields. Claims are validated, deduplicated, sorted, and stored immutably on the session.
* Omitting `auth_claims` or passing an empty string produces an empty claim set (backward compatible).
* Including `auth_claims` on any other grant type returns a 400 `invalid_request` error.
* A maximum of 32 claims per session is enforced.
* The serialized payload must not exceed 4096 bytes.
See [Sessions](/developer-guide/platform-api/platform-api/sessions) for the full external-user session token grant documentation.
# Topic Modeling Settings
Read and update per-workspace conversation topic analytics exposure settings.
The topic modeling settings endpoints control whether customer-facing conversation topic analytics are exposed through a workspace's data scope. These settings are restricted to Amigo administrators.
## Endpoints
| Method | Path | Operation | Description |
| ------ | -------------------------------------------- | -------------------------------- | --------------------------------------------------- |
| `GET` | `/v1/{workspace_id}/settings/topic-modeling` | `get-topic-modeling-settings` | Return the current topic analytics exposure setting |
| `PUT` | `/v1/{workspace_id}/settings/topic-modeling` | `update-topic-modeling-settings` | Enable or disable topic analytics exposure |
## Get Topic Modeling Settings
`GET /v1/{workspace_id}/settings/topic-modeling`
Returns the durable desired state for customer conversation topic analytics.
### Path Parameters
| Parameter | Type | Description |
| -------------- | ------------- | ------------------------ |
| `workspace_id` | string (UUID) | The workspace identifier |
### Response
| Field | Type | Description |
| --------- | ------- | ------------------------------------------------------------------- |
| `enabled` | boolean | Whether conversation topic analytics are exposed for this workspace |
### Example Response
```json
{
"enabled": false
}
```
## Update Topic Modeling Settings
`PUT /v1/{workspace_id}/settings/topic-modeling`
Sets the desired exposure state and schedules an idempotent reconciliation of the workspace's data scope.
### Path Parameters
| Parameter | Type | Description |
| -------------- | ------------- | ------------------------ |
| `workspace_id` | string (UUID) | The workspace identifier |
### Request Body
| Field | Type | Required | Description |
| --------- | ------- | -------- | ----------------------------------------------------- |
| `enabled` | boolean | Yes | Whether to enable or disable topic analytics exposure |
### Example Request
```json
{
"enabled": true
}
```
### Response
| Field | Type | Description |
| ----------------------- | ------- | --------------------------------------------------- |
| `enabled` | boolean | The new desired state |
| `reconciliation_status` | string | Always `"pending"` - reconciliation has been queued |
| `run_id` | integer | Identifier for the queued reconciliation run |
### Example Response
```json
{
"enabled": true,
"reconciliation_status": "pending",
"run_id": 12345
}
```
## Authorization
Both endpoints require:
* An API key with workspace update permission
* The caller must be an authenticated Amigo administrator (user principal with an `@amigo.ai` email)
Non-administrator callers receive a `403 Forbidden` response.
## Error Responses
| Status | Condition |
| ------ | ---------------------------------------------------------------------------- |
| `403` | Caller is not an Amigo administrator |
| `404` | Workspace not found |
| `503` | Setting was saved but reconciliation could not be queued (retry the request) |
# Pagination
How Platform API list endpoints paginate - continuation-token pagination for resource lists and limit/offset for analytics and audit endpoints.
The Platform API uses two pagination styles, and knowing which one an endpoint uses tells you how to request the next page. Most resource list endpoints (agents, skills, services, triggers, and similar) use **continuation-token pagination**. Other endpoint groups - audit logs, metrics, intake links, conversations, calls, FHIR views, world model, population health, and similar query-style endpoints - use **limit/offset pagination** instead.
## Continuation-Token Pagination (Default)
Resource list endpoints return `items`, `has_more`, and `continuation_token`, with an optional `total`:
```json
{
"items": [...],
"total": 142,
"has_more": true,
"continuation_token": 20
}
```
| Parameter | Default | Range | Description |
| -------------------- | ------- | ----- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `limit` | 10 | 1-100 | Items per page. Most resource lists default to 10 with a maximum of 100; some (such as integrations and intake lists) default to 50 with a maximum of 200. |
| `continuation_token` | - | - | Cursor for the next page. Returned in the response; pass it back unchanged. On many endpoints it is an integer offset, but treat it as opaque. |
The `total` field is optional and only populated for endpoints that opt in, so it is not returned on every paginated response. When `has_more` is true, pass the returned `continuation_token` back to fetch the next page.
## Limit/Offset Pagination
The endpoint groups tabled below accept `limit` and `offset` query parameters directly.
| Parameter | Type | Default | Description |
| --------- | ------- | ------------------ | -------------------------------------------------------------------------------- |
| `limit` | integer | Varies by endpoint | Maximum number of items to return. Must be >= 1. Upper bound varies by endpoint. |
| `offset` | integer | 0 | Number of items to skip before returning results. Must be >= 0. |
Both parameters are optional. Omitting them returns the endpoint's default result set.
### Example
```bash
# First page of 25 results
curl -H "Authorization: Bearer $API_KEY" \
"https://api.platform.amigo.ai/v1/$WORKSPACE_ID/metrics?limit=25&offset=0"
# Second page
curl -H "Authorization: Bearer $API_KEY" \
"https://api.platform.amigo.ai/v1/$WORKSPACE_ID/metrics?limit=25&offset=25"
```
### Supported Endpoints
Representative endpoint groups and their limits (not an exhaustive list - each endpoint's reference documentation states its own default and maximum). Rows labeled "population health" are the endpoints under the `/v1/{workspace_id}/m42/` path prefix, which serve the population health analytics surface.
| Endpoint Group | Default Limit | Max Limit |
| ------------------------------------------ | ------------- | --------- |
| Audit exports (`limit` only, no `offset`) | 50 | 200 |
| Entity duplicates | 100 | 500 |
| Intake links | 100 | 500 |
| Intake uploads (per link) | 200 | 500 |
| Metrics | 100 | 500 |
| Voice judge results | 20 | 100 |
| Prompt logs | 20 | 200 |
| Entity enrichment values | 200 | 500 |
| Enrichment keys | 200 | 500 |
| Population health (`m42`) district metrics | 50 | 500 |
| Population health (`m42`) anomaly alerts | 50 | 500 |
| Population health (`m42`) forecast fan | 1000 | 5000 |
| Population health (`m42`) positive signals | 50 | 200 |
| Population health (`m42`) ranked anomalies | 50 | 500 |
| Population health (`m42`) cluster summary | 50 | 500 |
| Population health (`m42`) cluster forecast | 1000 | 5000 |
| Population health (`m42`) model registry | 50 | 500 |
| Population health (`m42`) stratified fits | 50 | 500 |
| Population health (`m42`) patient topology | 10000 | 50000 |
| Population health (`m42`) patient labs | 500 | 2000 |
### Validation
Requests with `limit` or `offset` values outside the allowed range receive a `422 Unprocessable Entity` response. The `limit` must be at least 1 and at most the endpoint's maximum. The `offset` must be non-negative.
### Notes
* Result ordering is preserved as documented for each endpoint. Pagination slices the ordered result set.
* If `offset` exceeds the total number of available results, an empty list is returned.
* Total count headers are not included in responses. Most limit/offset endpoints signal the end of a result set implicitly: check whether the number of returned items is less than the requested `limit`.
* Some endpoints return explicit peek-ahead pagination fields instead. [Prompt Logs](/developer-guide/platform-api/safety/prompt-logs) responses include `has_more` and `next_offset` (with a 10,000 offset cap); pass `next_offset` back as `offset` for the next page.
# Health
Health check endpoints for monitoring platform subsystem status, including whether feature-flag rollouts are live.
The Platform API exposes health endpoints for monitoring the status of platform subsystems. These endpoints require no authentication and are designed for external health monitors and alerting systems.
{% hint style="info" %}
The health endpoints are served by the API but are not included in the published OpenAPI schema.
{% endhint %}
## Liveness
### `GET /health`
Basic liveness check. Returns `200` with `{"status": "ok"}` when the service process is responsive.
## Feature-Flag Health
Reports whether feature-flag changes are live. Feature flags control staged rollouts: dark launches, per-workspace ramps, kill switches, and rollbacks. When flag evaluation is not live, changes to those flags silently have no effect - everything resolves to built-in defaults - so a monitoring team relying on a kill switch or a staged rollout needs to know that state.
### `GET /health/flags`
No authentication required.
#### Response
| Field | Type | Description |
| ---------------------- | ------- | -------------------------------------------------------------------------------------- |
| `provider_registered` | boolean | Whether flag evaluation is available in this environment |
| `provider_ready` | boolean | Whether flag evaluation initialized successfully |
| `env_enabled` | boolean | Whether the environment gate for flag evaluation is enabled |
| `runtime_controllable` | boolean | `true` only when all three conditions above hold - flag changes take effect at runtime |
| `reason` | string | Human-readable explanation of the current state |
#### Example Response (Healthy)
```json
{
"provider_registered": true,
"provider_ready": true,
"env_enabled": true,
"runtime_controllable": true,
"reason": "flag provider active; flips are runtime-controllable"
}
```
#### Example Response (Inert)
```json
{
"provider_registered": true,
"provider_ready": true,
"env_enabled": false,
"runtime_controllable": false,
"reason": "environment gate is not enabled; the flag provider is inert and all flags resolve to code/env defaults (flips/kill-switches are NOT live)"
}
```
#### Usage
Point health monitors at this endpoint if you rely on feature flags for dark launches, per-workspace ramps, or kill switches. When `runtime_controllable` is `false`, flag changes will not take effect - all flags resolve to their built-in defaults.
---
[Next Page](/llms-full.txt/1)